At a glance
Better validation loss does not reliably imply better robot control. OCBench reproduces four puzzles in behavioral cloning: continued improvement after overfitting, gains from partially open-loop action chunks, benefits from very large policies, and sensitivity to feature scaling despite abundant data.
Its 28 manipulation tasks use controllable, GPU-accelerated scripts designed to resemble human trajectories. This enables experiments with fresh synthetic data and isolated design changes. The paper tests competing explanations rather than fully resolving the mysteries; synthetic evidence remains a complement to real-world experiments.
1 Introduction
BC underlies modern robot policies, but reported behavior often conflicts with supervised-learning intuition: overfitting can help, single-step feedback policies can fail, and adding observation history can hurt Mandlekar et al. (2021) Allshire et al. (2026) Zhao et al. (2023) de Haan et al. (2019). Human data and robot experiments are expensive and hard to control; conventional synthetic trajectories do not consistently reproduce these effects.
OCBench designs narrow, temporally correlated, non-Markovian trajectories with diverse strategies. MJWarp implementations of both simulation and scripted policies collect up to 200,000 environment steps per second on one H100 GPU. Efficient fresh-data generation helps separate limited-dataset effects from failures that persist with streaming data.
2 Related work
The study emphasizes flow BC, a common action-generation objective in large robot systems Black et al. (2025b) NVIDIA et al. (2025) Physical Intelligence et al. (2026), while comparing deterministic regression and autoregressive action tokens. Earlier analyses examine distribution shift, action chunking, and history conditioning, often using tens to hundreds of fixed human demonstrations Ross et al. (2011) Lazzati et al. (2026) Zeng et al. (2026) Sobol Mark et al. (2026). Such data limits can confound whether a problem persists at scale.
MimicGen generates new trajectories by adapting segments from about ten human demonstrations per task Mandlekar et al. (2023). OCBench instead uses fully scripted motion with controls for speed, mistakes, coverage, and strategy. Compared with OGBench and other synthetic benchmarks, its scripts are designed to reproduce human-demonstration phenomena while permitting fast controlled experiments Park et al. (2025a).
3 Motivation
The four mysteries: performance can rise while validation loss worsens; executing action chunks can outperform replanning every step without inference delay; cloning human behavior can require much larger models than conventional synthetic behavior; and feature choices can matter despite abundant data.
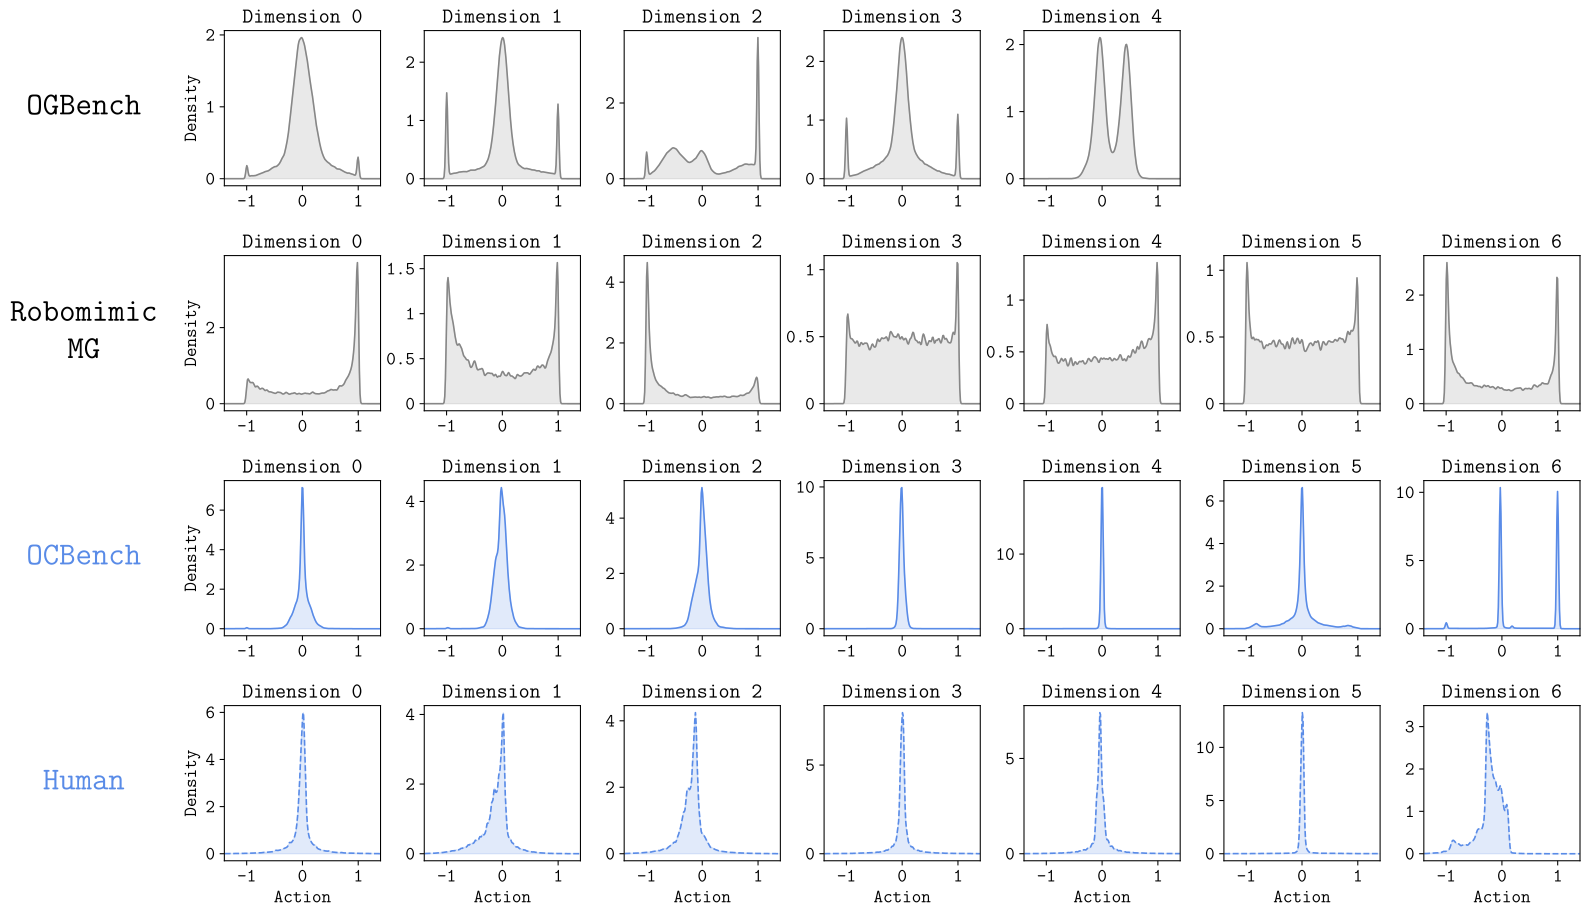
Here, “open-loop” always means partially open-loop execution of a predicted chunk, followed by a new observation and plan. The authors hypothesize that older synthetic datasets underrepresent human trajectories’ temporal correlation, multimodality, and narrow support. Gaussian-noise augmentation or saturated actions can yield statistics unlike human demonstrations; Figure 1 compares these distributions.
4 OCBench: A controllable robotic manipulation benchmark
OCBench combines controllable demonstration generation with efficient MuJoCo simulation to study BC under repeatable interventions. Both tasks and scripted policies have CPU and MJWarp implementations.
4.1 Scripted policies and datasets
The scripts target three proposed properties of human demonstrations: narrow trajectory distributions, non-Markovian temporal correlation, and semantic diversity. Randomized control points define phases such as grasping, lifting, and transport; piecewise Hermite splines with Catmull–Rom tangent matching provide continuous first derivatives.
Randomization changes waypoints, grasp angles, contact points, speeds, gripper orientation, curvature, and high-level strategies. Scripts sometimes make mistakes and recover. These choices reproduce several BC phenomena and yield action histograms closer to human data; they do not establish that all human behavior has been captured.
4.2 Tasks
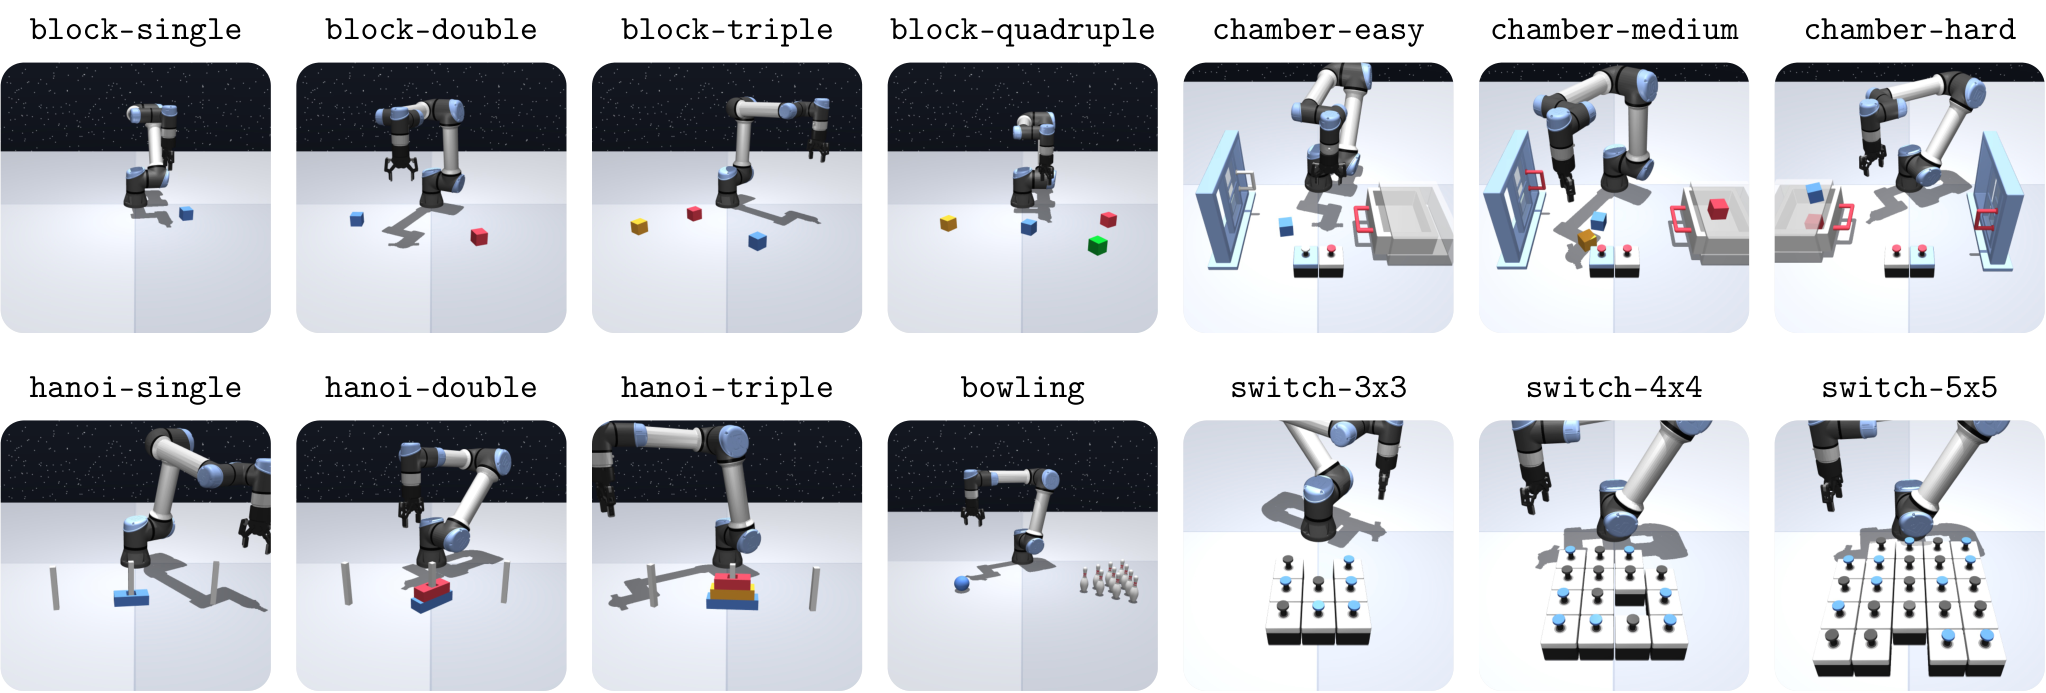
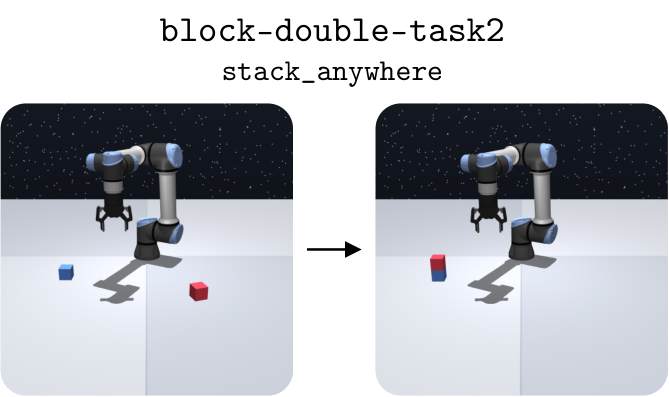
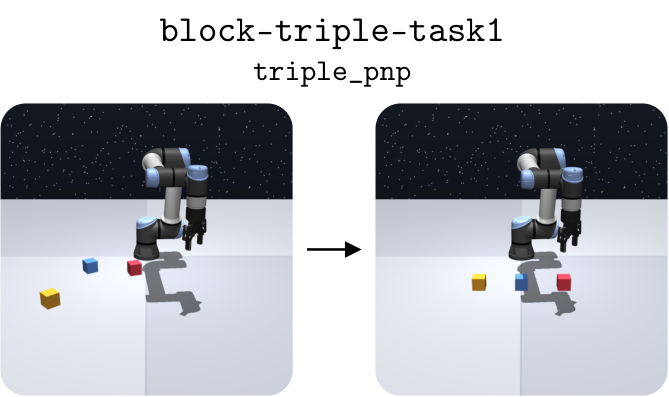
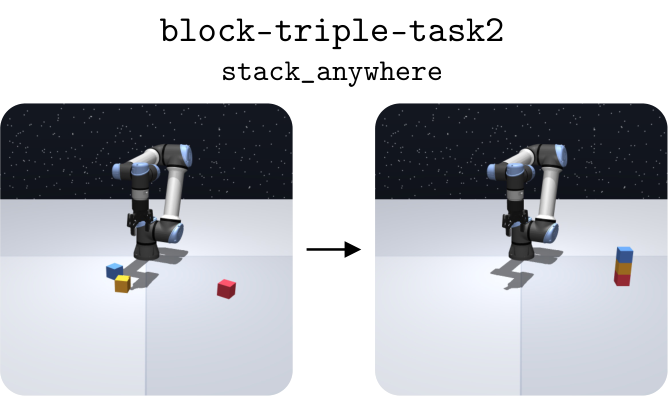
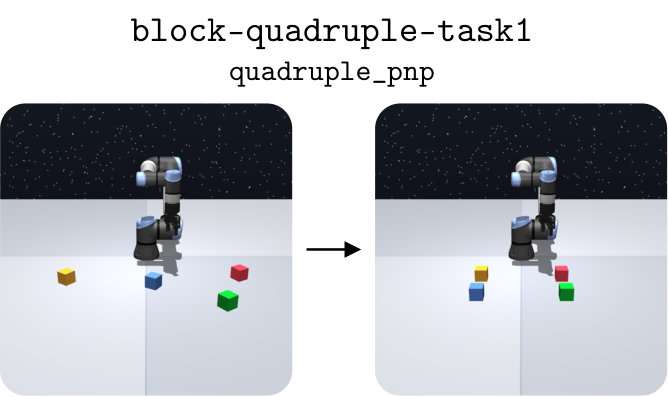
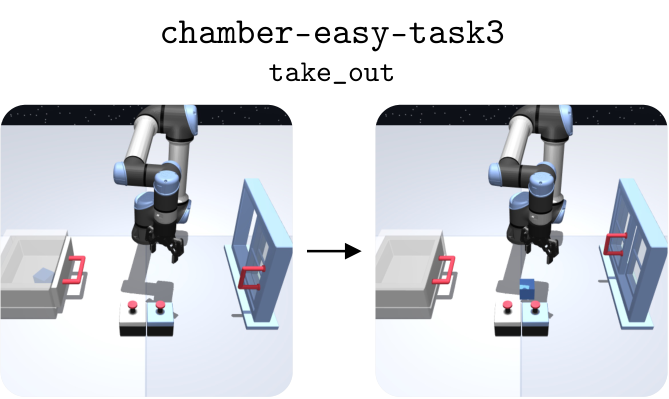
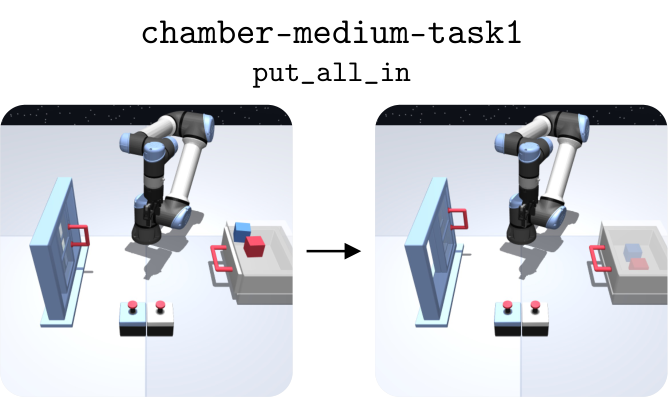
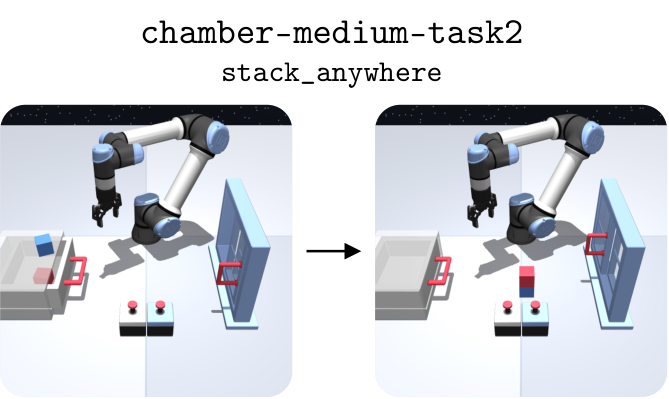
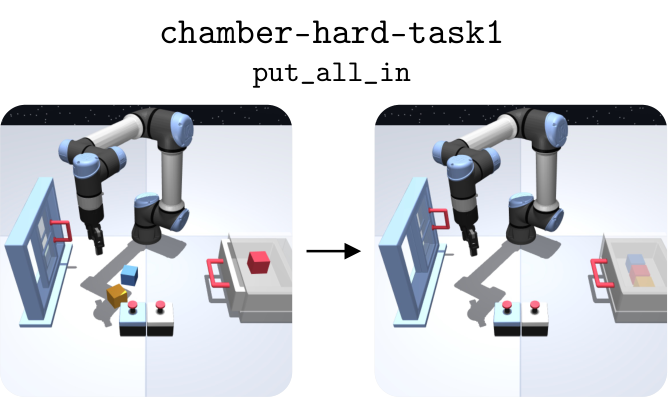
28 tasks span block, chamber, switch, hanoi, and bowling. Standard environments run at 50 Hz with seven-dimensional relative joint-position actions. Experiments mainly use state observations, though multi-view image versions are available.
CPU and MJWarp versions implement the same intended dynamics and generation logic but are not numerically identical. Lite variants, available except for bowling, run at 10 Hz with roughly twice-as-fast demonstrations and simpler motion, enabling smaller models and quicker iteration.
5 Studying behavioral cloning in OCBench
Flow BC learns a distribution over length-k action chunks conditioned on the current state Black et al. (2025b) Lipman et al. (2023) Albergo & Vanden-Eijnden (2023) Liu et al. (2023b). By default, evaluation executes the whole sampled chunk before replanning. Experiments generally average two random seeds with 95% confidence intervals; exceptions are identified in the relevant results.
The experiments demonstrate how to investigate the mysteries, rather than claiming definitive explanations. “Streaming” means periodically replacing training data with freshly generated episodes; the implementation refreshes 25,000 episodes every 100,000 training steps.
5.1 Mystery 1: Overfitting is not necessarily bad
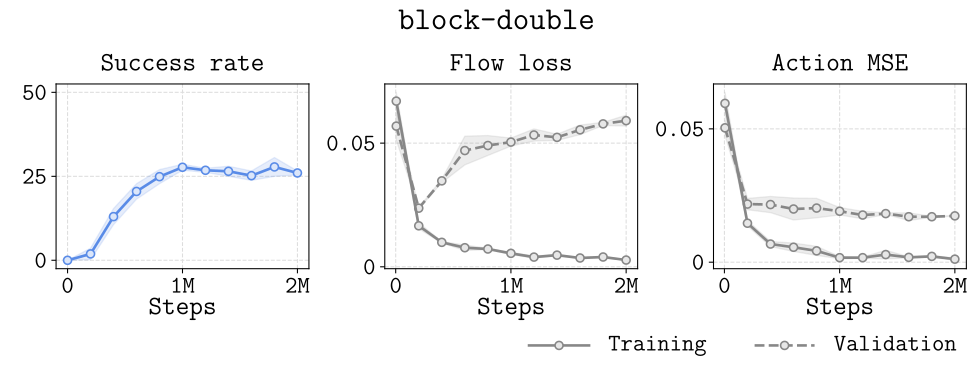
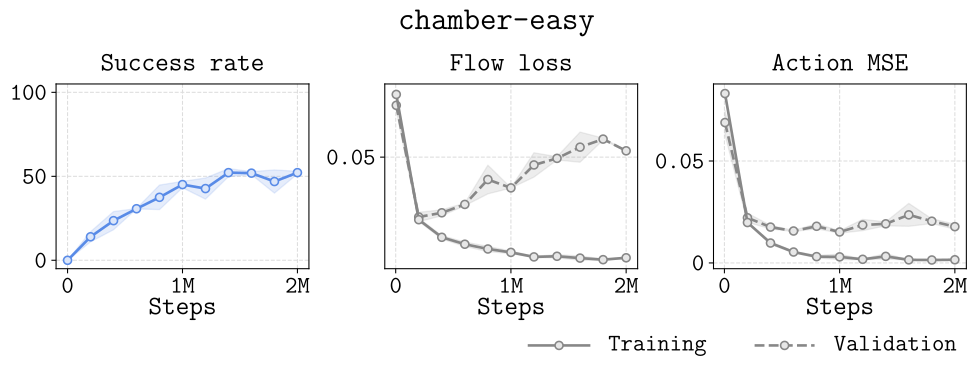
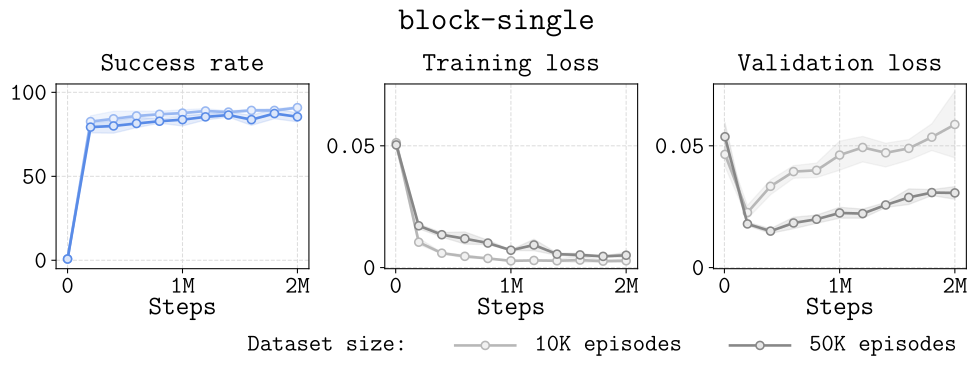
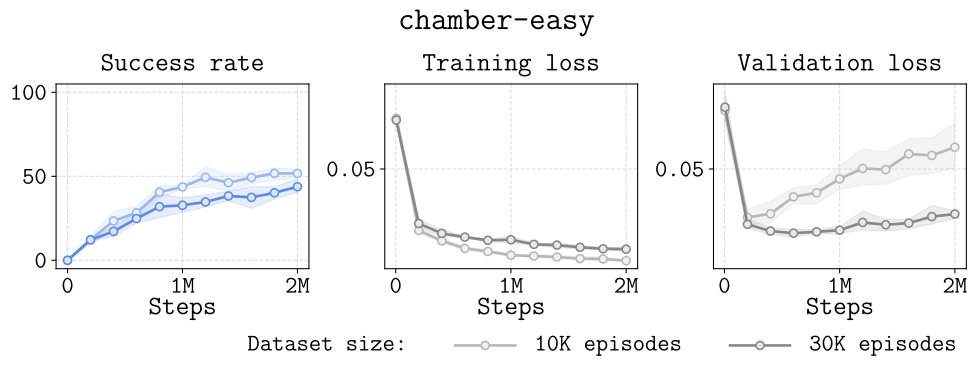
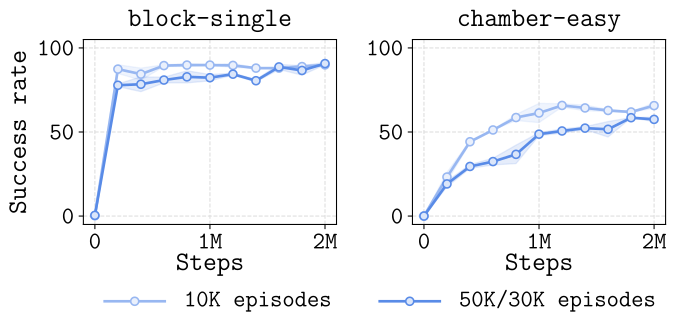
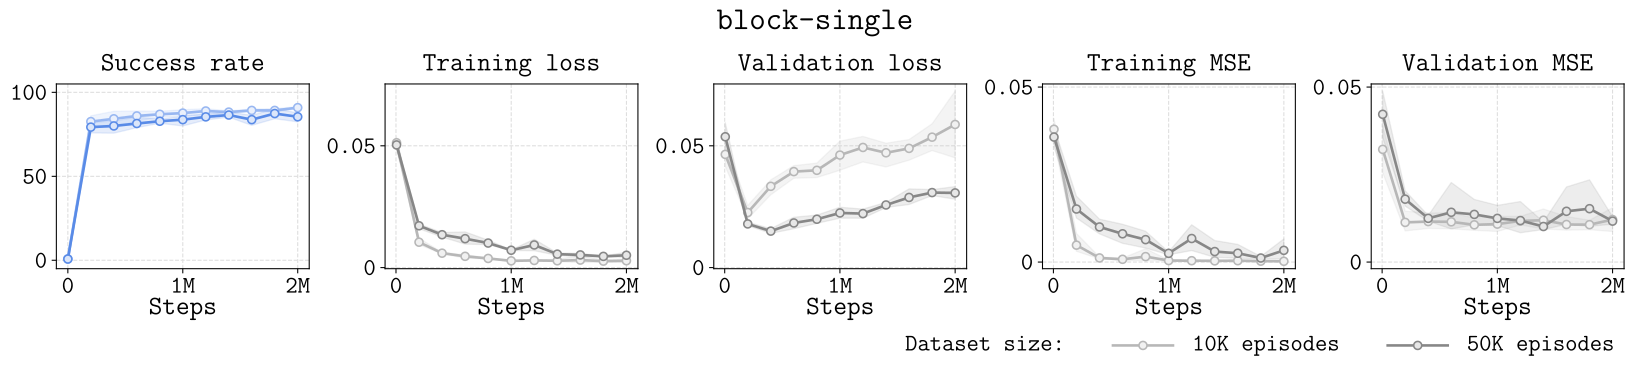
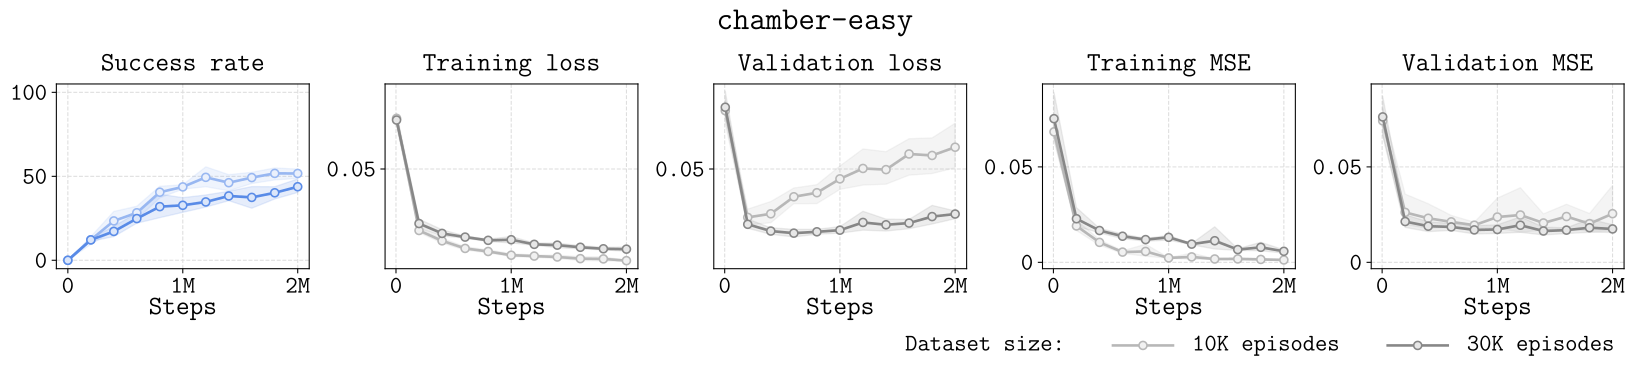
Observation: on block-double-task1 and chamber-easy-task2, success continues improving after validation flow loss begins rising. Selecting the checkpoint with minimum validation loss would give substantially worse control. In separate experiments, smaller datasets also outperform larger datasets sampled independently from the same distribution: 10K versus 50K block episodes and 10K versus 30K chamber episodes. Figure 4 averages four independently sampled datasets per setting.
Loss-mismatch hypothesis: generated-action MSE tracks performance better than flow velocity loss, consistent with Allshire et al. (2026), but can flatten while success still rises. It also fails to explain the dataset size reversal fully; Figures 3 and 17 preserve both metrics.
Capacity hypothesis: repeating the size comparison with four-times-larger, 540M-parameter policies does not eliminate the reversal. Limited capacity alone is therefore insufficient under this test.
Distribution-shift hypothesis: overfitting might help a policy follow nearby demonstrated trajectory segments, reducing compounding errors Ross et al. (2011) Pari et al. (2022). Learned representations could still generalize across randomized episodes. The authors regard this as plausible, indirectly supported by the feature experiments, but leave quantitative testing and a complete explanation unresolved.
5.2 Mystery 2: Open-loop is often better than closed-loop
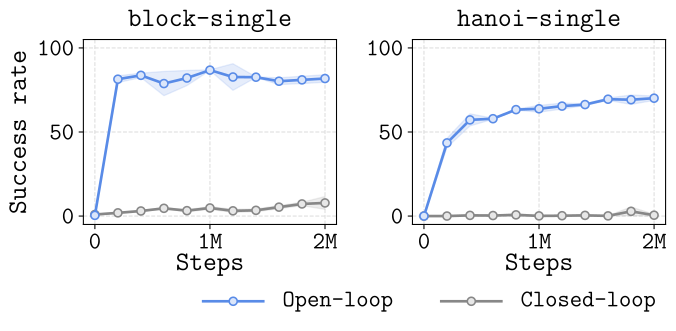
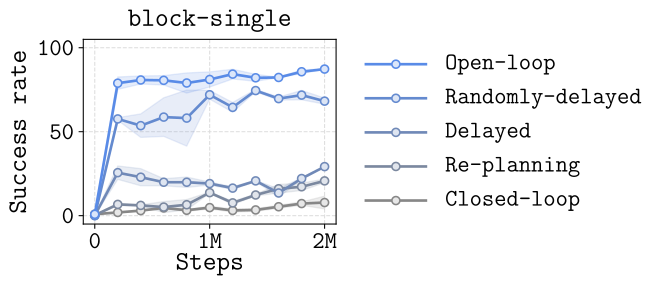
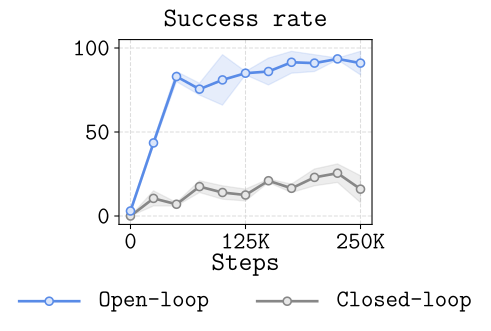
Observation: with streaming data on block-single-task1 and hanoi-single-task1, one-action policies almost completely fail while length-25 chunks succeed. Data scarcity, finite-dataset overfitting, and inference delay do not explain these particular comparisons.
Compounding-error hypothesis: sampling a new stochastic action every step may accumulate errors more quickly; longer chunks trade fewer decisions against a more complex prediction problem. Figure 7 compares current-state single actions, 25-action chunks, chunks replanned after their first action, a fixed 24-step delayed observation, and a randomly delayed observation with delay sampled from 0–9.
The randomly delayed single-action policy performs strongly, though below chunked execution. Because it still samples every step, compounding errors alone cannot explain the whole gap. This parallels evidence from human-data studies Lazzati et al. (2026).
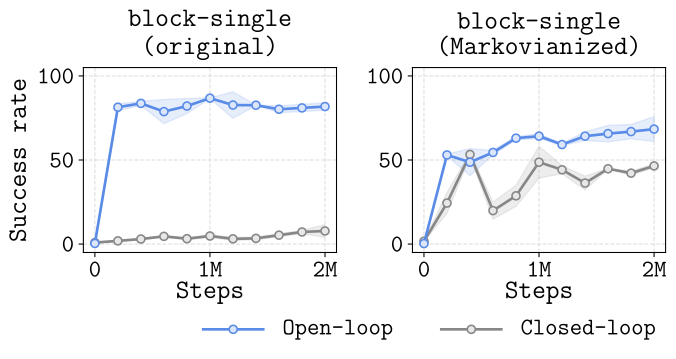
Non-Markovianity hypothesis: one-step state-conditioned policies cannot represent all temporal dependencies in the demonstrations. Regenerating the scripted plan at every step “Markovianizes” the data. This reduces, but does not remove, the closed-loop/open-loop gap. Both temporal mismatch and compounding errors may contribute; neither is established as a complete explanation.
5.2.1 Aside: What about history conditioning?
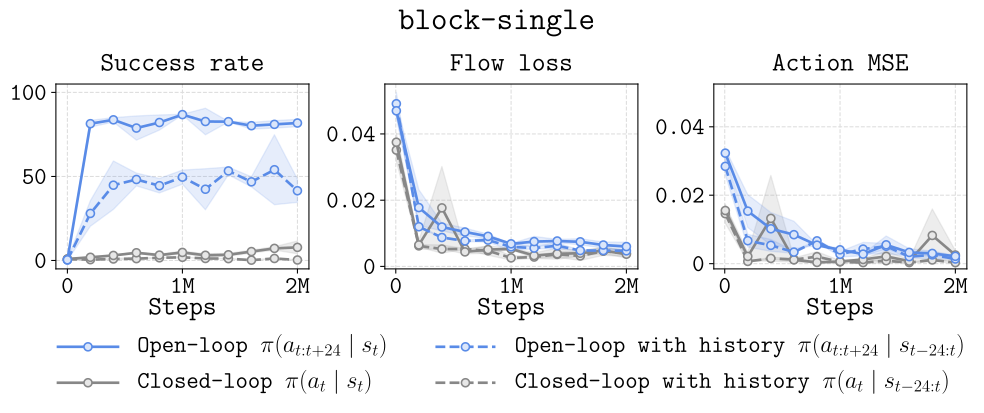
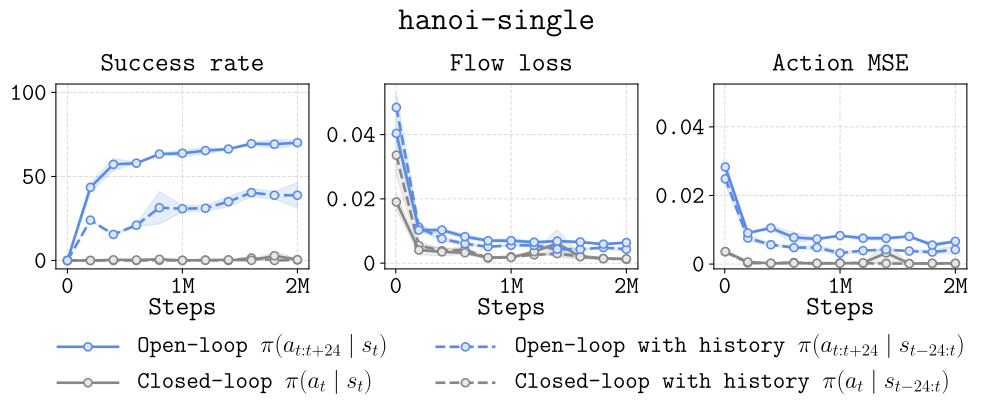
Conditioning on the current and previous 24 states could represent temporal information similar in extent to a 25-action chunk. Yet history-conditioned policies can perform worse despite lower flow loss and action MSE, even with streaming data.
Two proposed explanations remain open: causal confusion, in which previous behavior provides a shortcut that fails during autonomous execution, and greater susceptibility to distribution shift in the larger history input space de Haan et al. (2019) Wen et al. (2020) Sobol Mark et al. (2026). Better fitting the demonstrations does not guarantee better rollout behavior.
5.3 Mystery 3: Policies should be (very) large
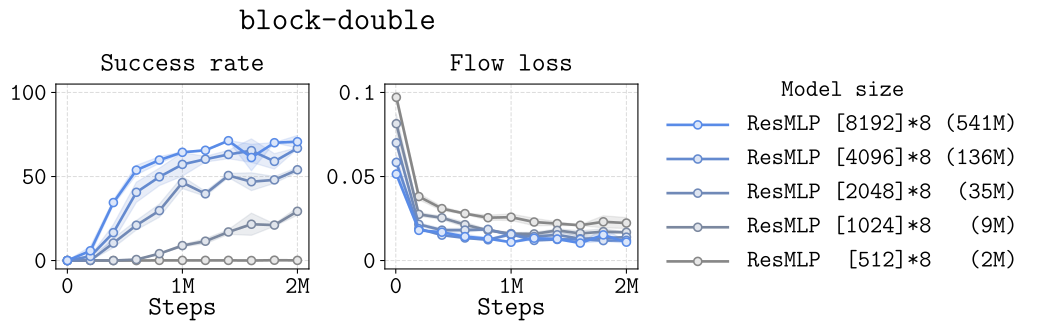
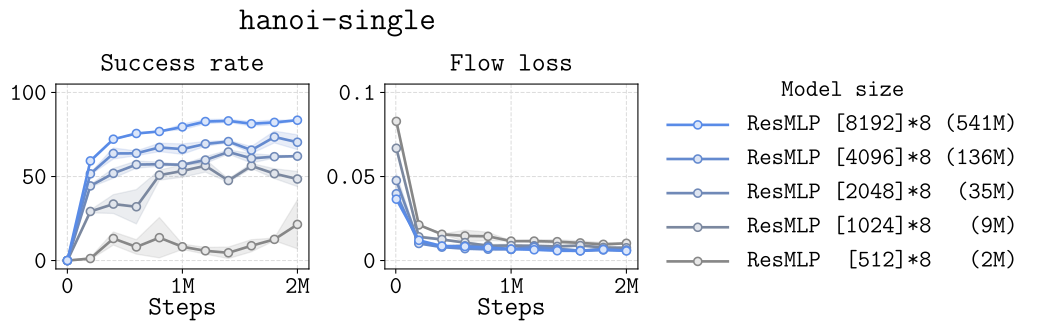
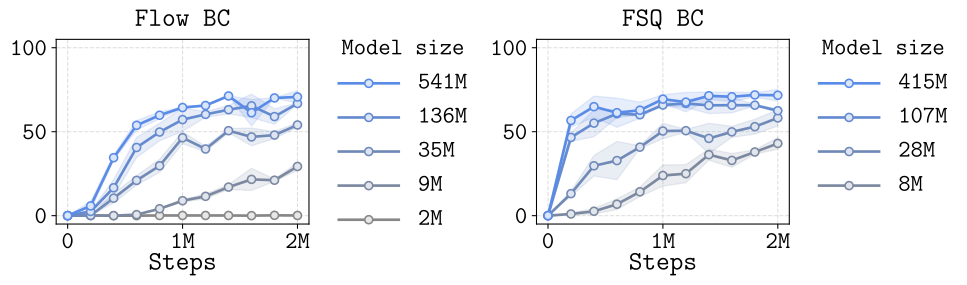
OCBench performance improves up to eight-layer, width-8192 residual MLPs with roughly 0.5 billion parameters, despite state observations and simple manipulation tasks. Earlier synthetic tasks often saturate with much smaller networks. The scaling resembles reports from human demonstrations Pan et al. (2026).
Behavior-complexity hypothesis: narrow, diverse human-like behavior may simply be difficult to model accurately. This motivates large action experts, but the tested result is improvement to roughly 0.5B parameters; a billion-scale requirement is a conjecture, not a demonstrated threshold.
Flow-objective hypothesis: flow matching may require extra capacity or training effort because of noisy coupling Pertsch et al. (2025) Driess et al. (2025). To test this, the authors tokenize chunks using FSQ and train an autoregressive policy Mentzer et al. (2024). Smaller autoregressive models outperform similarly sized flow models, but they still improve with size. Flow matching alone therefore does not explain the scaling.
5.4 Mystery 4: Features matter even with enough data
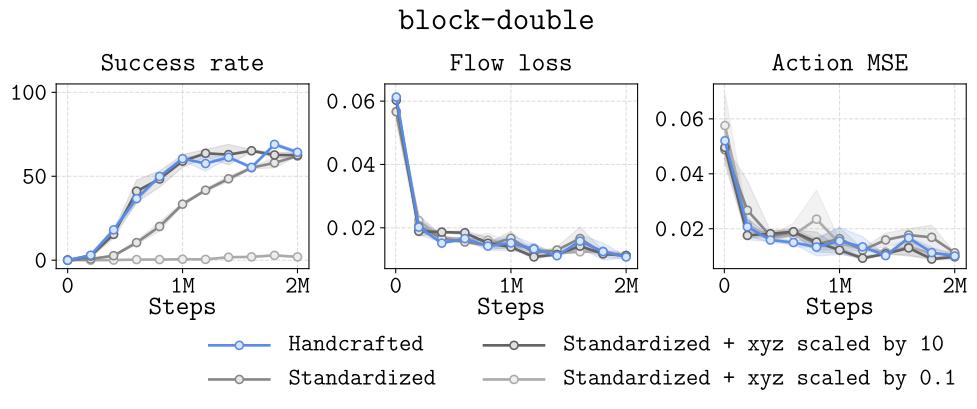
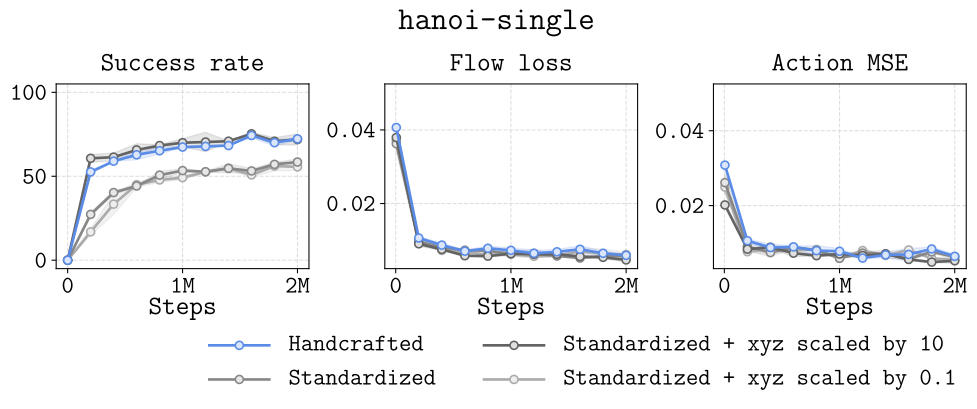
Observation: under streaming data, handcrafted feature scales, standardized features, and standardized features with position coordinates multiplied by 0.1 or 10 produce substantially different success rates. These inputs contain the same information, and their training/validation flow losses and action MSEs are almost indistinguishable.
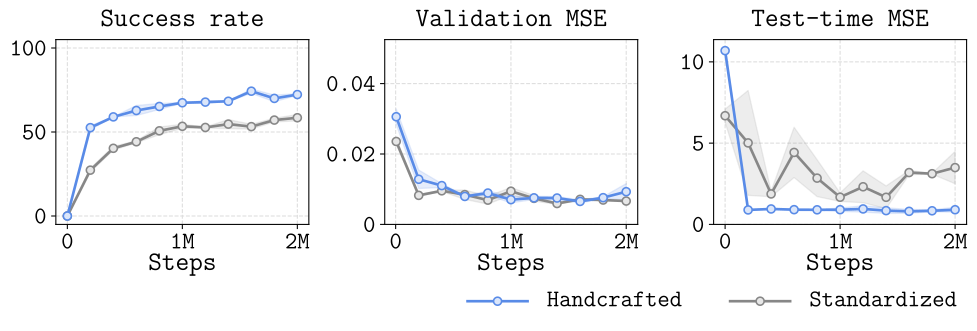
Generalization hypothesis: feature emphasis changes how a policy acts on states reached during its own rollout. On hanoi-single-task1, a fresh scripted oracle plan is generated at each visited state, allowing action error to be measured there. This test-time MSE varies across feature choices and correlates with success better than training or validation MSE.
The result supports a distribution-shift explanation: fitting demonstrated states equally well can conceal different autonomous behavior. Oracle MSE is still imperfect because it ignores multiple valid actions, so it is evidence about generalization rather than a complete performance metric.
6 Closing remarks
OCBench is a controlled research environment, not a replacement for real demonstrations. Its scripts reproduce several observed patterns but remain synthetic; real-world validation is necessary. Most analyses are state-based, and the paper does not settle the competing causal explanations.
Reinforcement learning is outside the evaluated scope. Variable demonstration speeds, subtask boundaries, and labels are supplied to support future work on learning from suboptimal data, hierarchical control, and throughput as well as success.
Acknowledgments
The authors acknowledge camera-design and benchmark feedback, support from KFAS, NSF, and ONR, and computing resources from UC Berkeley’s Savio cluster.
Appendix A Tasks and datasets
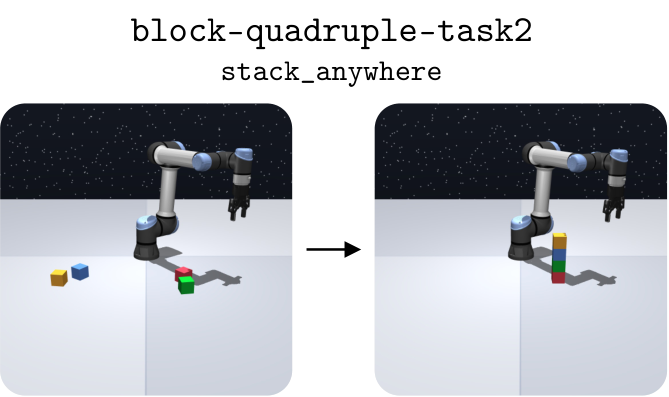
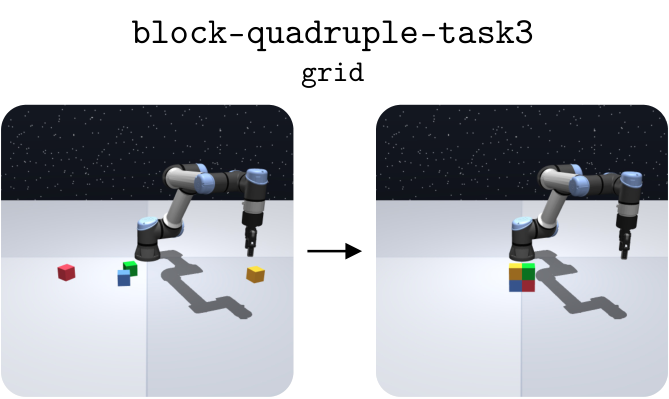
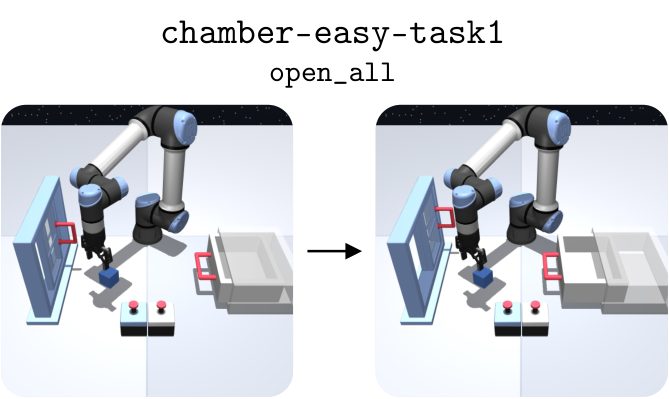
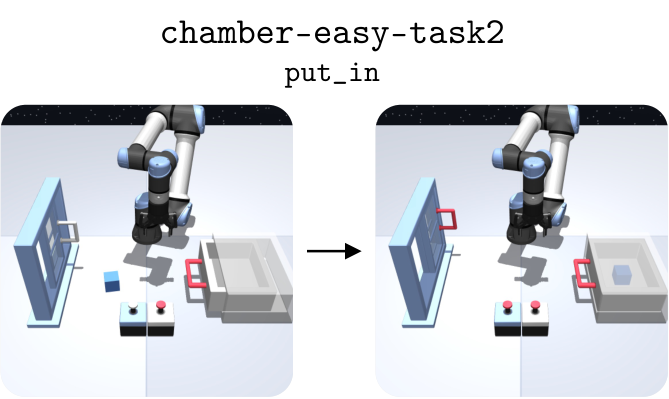
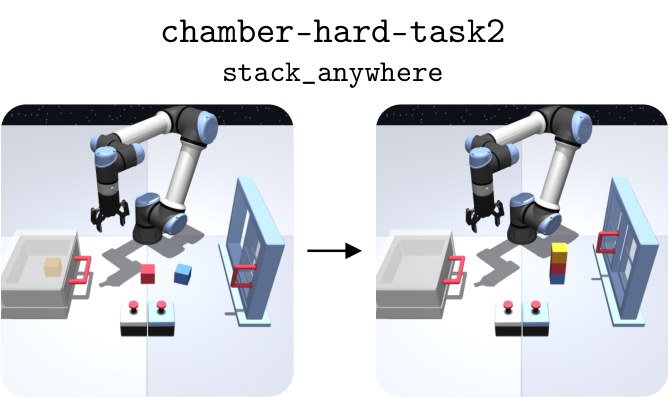
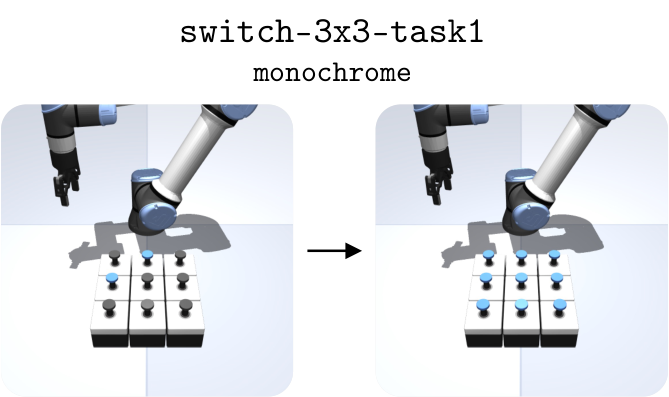
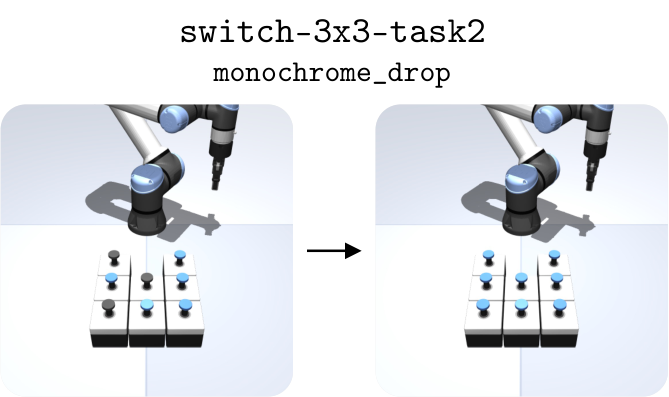
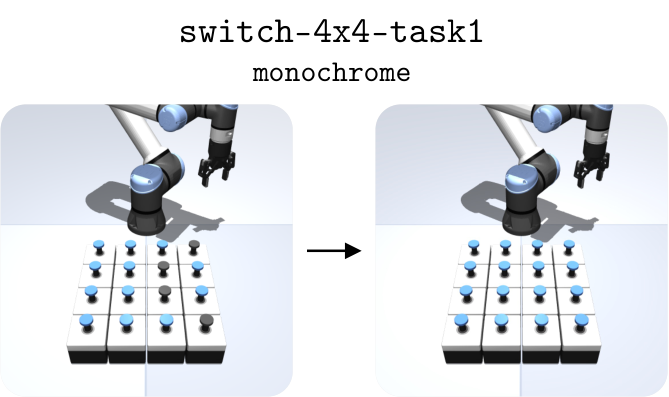
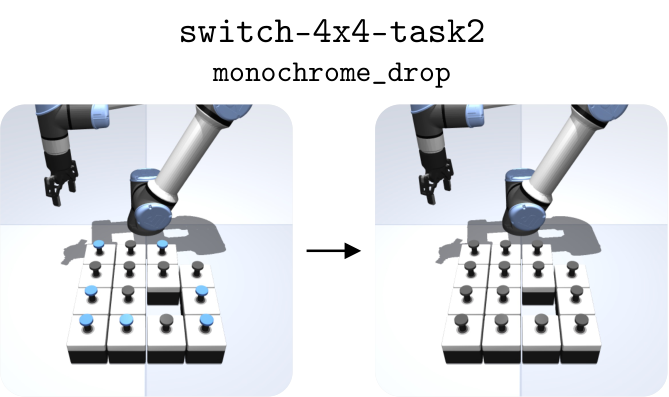
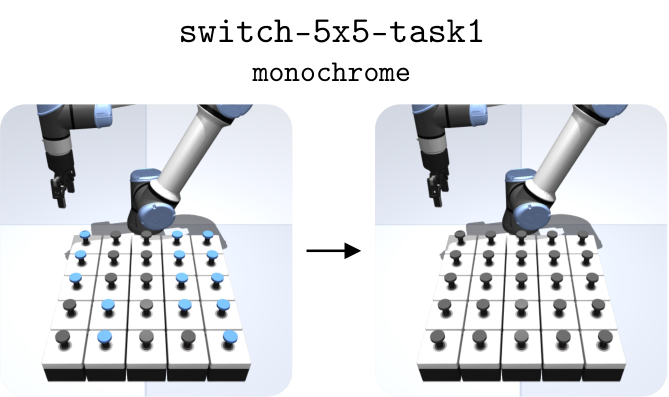
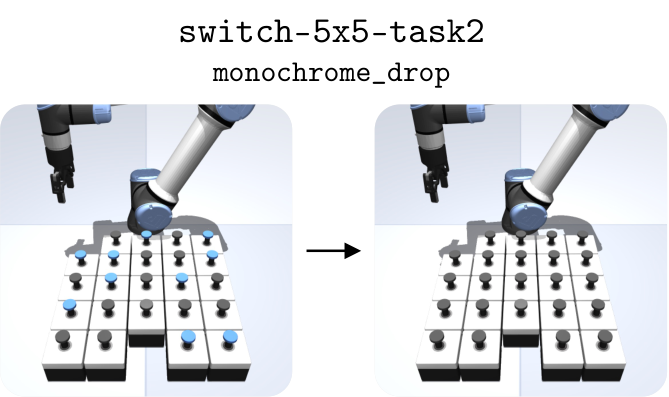
Task families: block has eight tasks covering fixed placement, stacking anywhere, and a four-block grid. Chamber has seven tasks combining blocks, drawers, windows, and locks, with randomized layouts and subtask order, occasional mistakes, and horizons up to 5,500 steps. Switch has six Lights Out tasks on 3×3, 4×4, and 5×5 boards, including missing-button variants; its demonstrations are deliberately highly suboptimal.
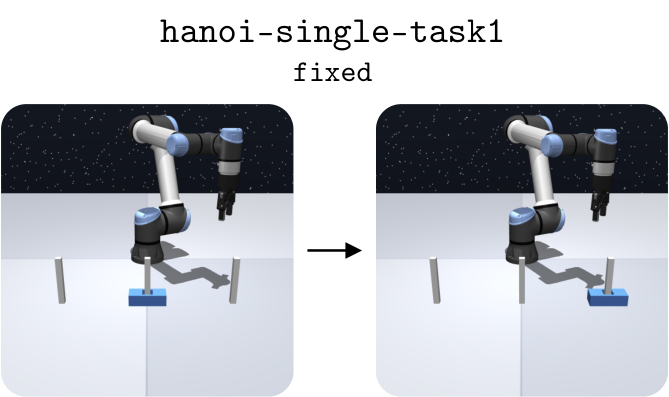
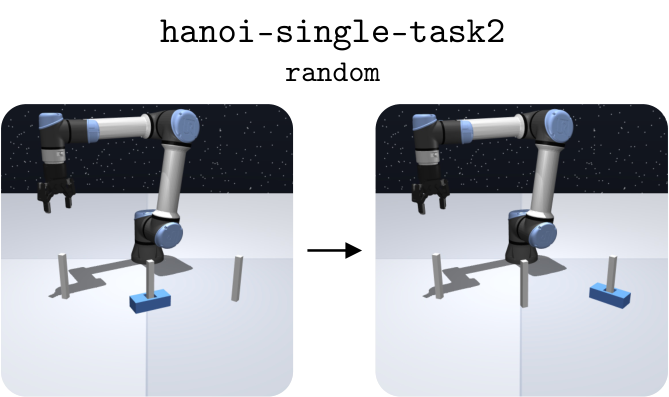
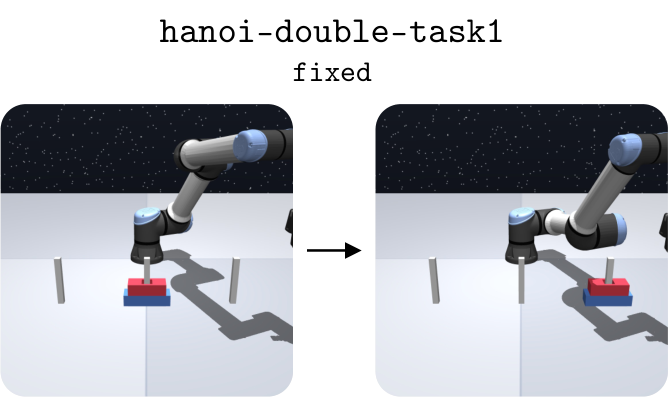
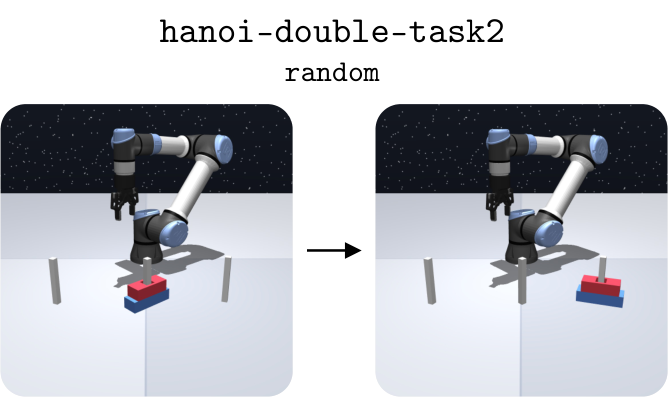
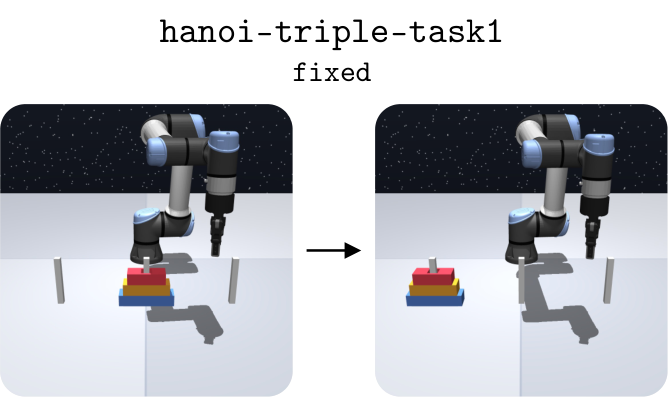
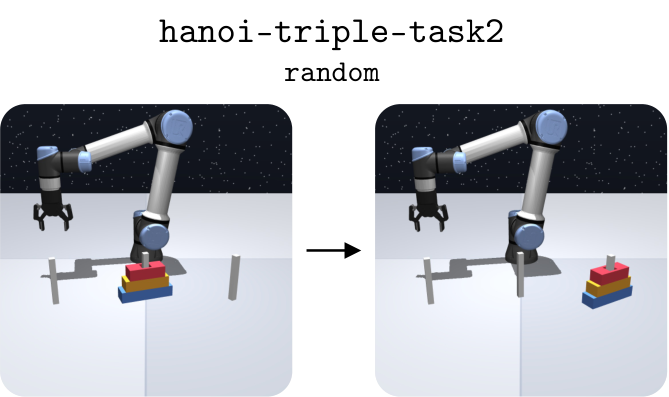
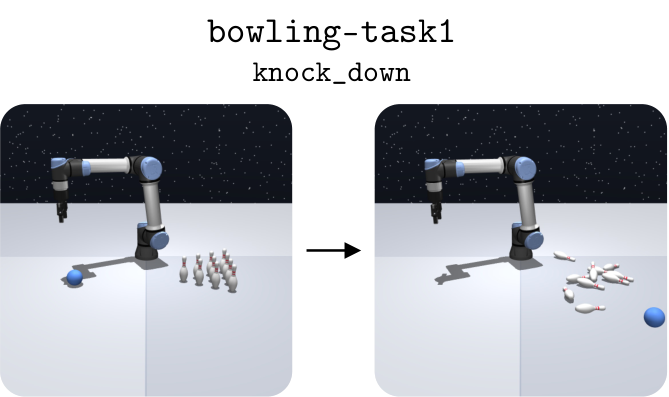
Hanoi has six tasks with one to three tightly fitting disks, fixed or randomized peg positions, and horizons up to 7,000 steps. Bowling has one task requiring a push that knocks down pins despite varied dynamics. Tables 3–5 retain task dimensions, horizons, and dataset specifications.
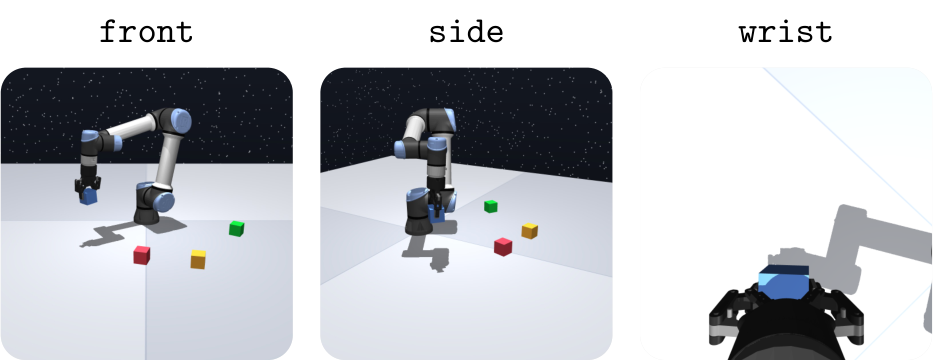
Lite variants combine 10 Hz control, approximately twice-as-fast motion, and fixed gripper roll/pitch. Nominal trajectories are about ten times shorter, and smaller policies suffice. Visual versions provide front, side, and wrist images at 224×224 RGB. Provided image datasets record observations every 25 steps, one set per default action chunk; only selected visual datasets are supplied because of storage limits.
Rewards and evaluation: non-bowling tasks terminate on success with reward 1 and otherwise give zero. Bowling gives 0.1 per newly fallen pin; all returns lie in [0,1]. Throughput multiplies success rate by maximum/mean episode length, with failures included in the mean. Bowling table entries instead report mean return multiplied by 100.
Datasets also contain full simulation states for observation reconstruction and atomic-subtask labels, targets, success indicators, and high-level mistake flags. These support detailed analysis and future hierarchical-control studies.
Equation 1
| (1) |
Appendix B How is OCBench different from previous synthetic benchmarks?
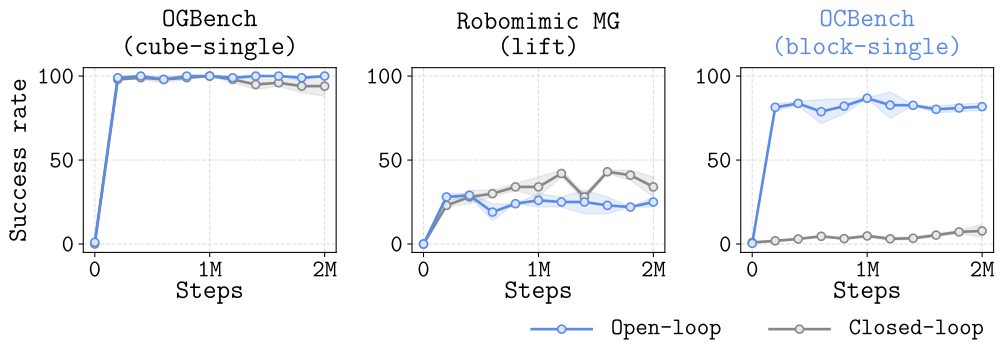
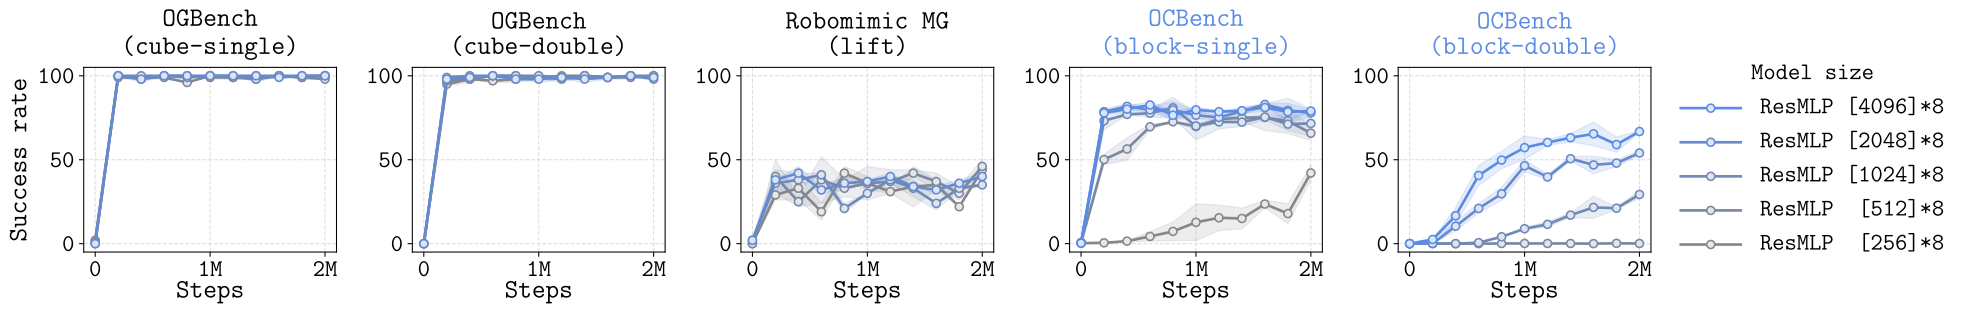
On comparable pick-and-place tasks, OGBench and Robomimic MG show a smaller benefit from chunking and saturate at much smaller networks than OCBench Park et al. (2025a) Mandlekar et al. (2021). The authors attribute this tentatively to less narrow and less temporally correlated synthetic trajectories. These comparisons concern selected tasks, rather than establishing a universal ranking of benchmarks.
The action-histogram comparison uses OGBench-style scripts, Robomimic machine-generated data, OCBench, and human BiPlay trajectories. OGBench-style data are regenerated for a compatible single task; absolute human action targets are converted to relative actions. Different robots have different joint ranges, so absolute histogram values are not directly comparable.
Table 1 preserves the broader differences: OCBench supports general robotic tasks, randomized environments, GPU acceleration, and 7-D joint control at 50 Hz, whereas OGBench uses goal-reaching tasks and 5-D end-effector control at 20 Hz.
Appendix C Additional results
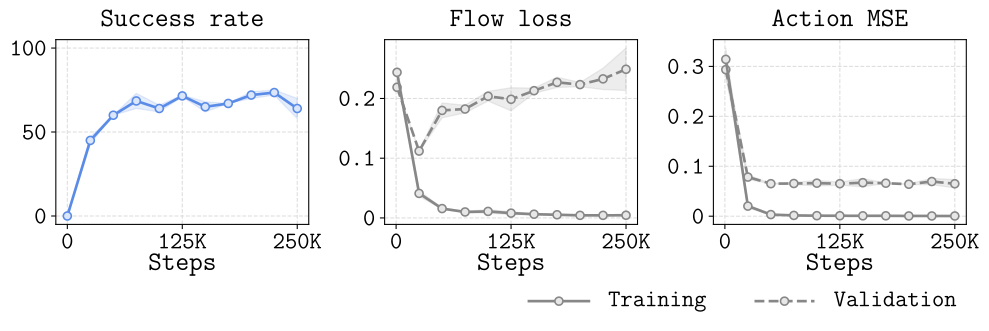
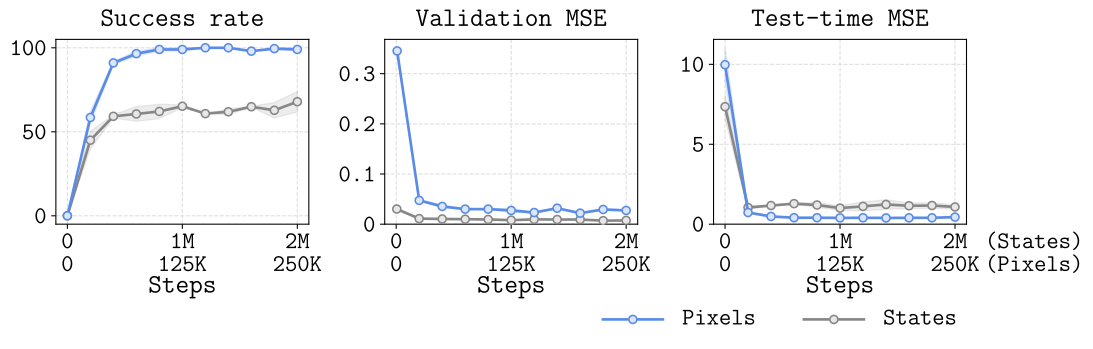
Figure 17 further shows that action MSE does not explain dataset size reversal fully. Preliminary visual-task experiments in Figure 18 reproduce three patterns: useful continued training despite overfitting, stronger chunked execution, and test-time error that can oppose validation-error trends when comparing state and pixel inputs.
Tables 6–7 provide reference results for deterministic BC, flow BC, and FSQ BC. They average two seeds and report standard deviations, unlike the main plots’ confidence intervals. Many difficult tasks remain near zero success, and the benchmark tables are preliminary rather than a comprehensive algorithm comparison.
Appendix D Implementation details
The repository provides code, datasets, and exact commands for reproducing the benchmark tables: OCBench.
D.1 Methods
Implementations use JAX. Except for bowling, training keeps only successful episodes. Default chunks contain 25 actions, or three in lite tasks. Residual MLPs connect every two layers. Action normalization maps per-dimension first/99th percentiles to −1/+1 and clips to [−5,5]; the gripper is only clipped to [−1,1].
Benchmark agents train for two million steps, with 500 evaluation rollouts every 50,000 steps. Reported performance averages the final five checkpoints. Streaming runs replace their dataset with 25,000 new episodes every 100,000 steps, rather than retaining an ever-growing archive.
BC: deterministic action regression with MSE. FBC: flow velocity prediction with Beta(1,1.5) time sampling that emphasizes noisier inputs; this accelerates training here compared with uniform sampling. FSQBC: jointly train a state-conditioned quantizing autoencoder with L1 reconstruction loss and an autoregressive token policy. Four tokens, each with [8,5,5,5] quantization levels, permit up to 1000⁴ chunk codes per state.
Visual policies use a shared ConvNeXt V2-N encoder for the three cameras. Their 640-dimensional outputs concatenate to 1,920 dimensions before a width-4096, eight-layer residual MLP. Training uses random image crops.
D.2 Hyperparameters
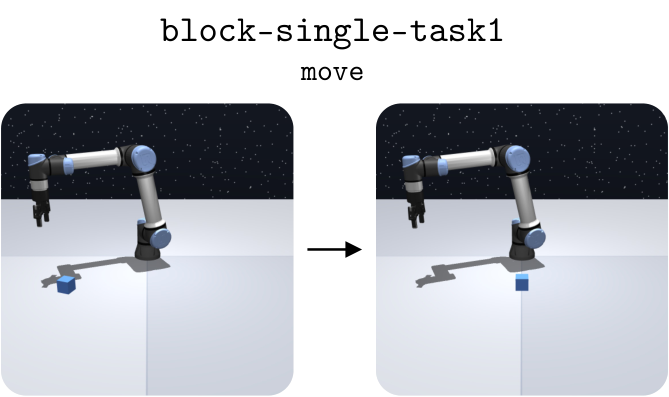
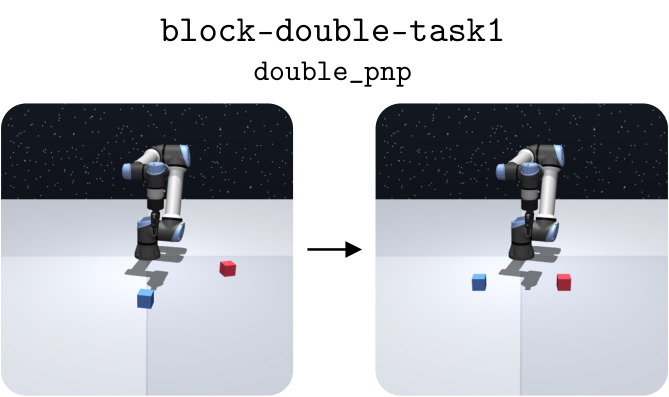
Table 2 retains defaults: Adam at learning rate 10⁻⁴; two million gradient steps, or 250K for visual tasks; batch size 1,024, or 256 for FSQBC and visual tasks. BC/FBC use width-4096 residual MLPs and FSQBC width 2048, each eight layers; lite widths are 1024 and 512. Layer normalization is enabled. Figures 19–23 and Tables 3–7 preserve the complete task illustrations, specifications, datasets, and benchmark results.
| Hyperparameter | Value |
|---|---|
| Gradient steps | M (default), K (visual) |
| Optimizer | Adam (Kingma & Ba, 2015) |
| Learning rate | |
| Batch size | (default), (FSQBC, visual) |
| ResMLP size (BC, FBC) | (default), (lite) |
| ResMLP size (FSQBC) | (default), (lite) |
| MLP normalization | Layer normalization (Ba et al., 2016) |
| Action chunk length | (default), (lite) |
| Task | State dimensions | Action dimensions | Maximum episode length |
|---|---|---|---|
| block-single-task1-v0 | 28 | 7 | 1250 |
| block-double-task1-v0 | 37 | 7 | 2500 |
| block-double-task2-v0 | 37 | 7 | 2500 |
| block-triple-task1-v0 | 46 | 7 | 3750 |
| block-triple-task2-v0 | 46 | 7 | 3750 |
| block-quadruple-task1-v0 | 55 | 7 | 5000 |
| block-quadruple-task2-v0 | 55 | 7 | 5000 |
| block-quadruple-task3-v0 | 55 | 7 | 5000 |
| chamber-easy-task1-v0 | 53 | 7 | 4000 |
| chamber-easy-task2-v0 | 53 | 7 | 4000 |
| chamber-easy-task3-v0 | 53 | 7 | 4000 |
| chamber-medium-task1-v0 | 62 | 7 | 5000 |
| chamber-medium-task2-v0 | 62 | 7 | 5000 |
| chamber-hard-task1-v0 | 71 | 7 | 5500 |
| chamber-hard-task2-v0 | 71 | 7 | 5500 |
| switch-3x3-task1-v0 | 64 | 7 | 1500 |
| switch-3x3-task2-v0 | 64 | 7 | 1500 |
| switch-4x4-task1-v0 | 99 | 7 | 1500 |
| switch-4x4-task2-v0 | 99 | 7 | 1500 |
| switch-5x5-task1-v0 | 144 | 7 | 4000 |
| switch-5x5-task2-v0 | 144 | 7 | 4000 |
| hanoi-single-task1-v0 | 39 | 7 | 1000 |
| hanoi-single-task2-v0 | 39 | 7 | 1000 |
| hanoi-double-task1-v0 | 44 | 7 | 3000 |
| hanoi-double-task2-v0 | 44 | 7 | 3000 |
| hanoi-triple-task1-v0 | 49 | 7 | 7000 |
| hanoi-triple-task2-v0 | 49 | 7 | 7000 |
| bowling-task1-v0 | 102 | 7 | 500 |
| block-lite-single-task1-v0 | 28 | 7 | 200 |
| block-lite-double-task1-v0 | 37 | 7 | 400 |
| block-lite-double-task2-v0 | 37 | 7 | 400 |
| block-lite-triple-task1-v0 | 46 | 7 | 600 |
| block-lite-triple-task2-v0 | 46 | 7 | 600 |
| block-lite-quadruple-task1-v0 | 55 | 7 | 800 |
| block-lite-quadruple-task2-v0 | 55 | 7 | 800 |
| block-lite-quadruple-task3-v0 | 55 | 7 | 800 |
| chamber-lite-easy-task1-v0 | 53 | 7 | 500 |
| chamber-lite-easy-task2-v0 | 53 | 7 | 500 |
| chamber-lite-easy-task3-v0 | 53 | 7 | 500 |
| chamber-lite-medium-task1-v0 | 62 | 7 | 600 |
| chamber-lite-medium-task2-v0 | 62 | 7 | 600 |
| chamber-lite-hard-task1-v0 | 71 | 7 | 700 |
| chamber-lite-hard-task2-v0 | 71 | 7 | 700 |
| switch-lite-3x3-task1-v0 | 64 | 7 | 300 |
| switch-lite-3x3-task2-v0 | 64 | 7 | 300 |
| switch-lite-4x4-task1-v0 | 99 | 7 | 300 |
| switch-lite-4x4-task2-v0 | 99 | 7 | 300 |
| switch-lite-5x5-task1-v0 | 144 | 7 | 800 |
| switch-lite-5x5-task2-v0 | 144 | 7 | 800 |
| hanoi-lite-single-task1-v0 | 39 | 7 | 300 |
| hanoi-lite-single-task2-v0 | 39 | 7 | 300 |
| hanoi-lite-double-task1-v0 | 44 | 7 | 900 |
| hanoi-lite-double-task2-v0 | 44 | 7 | 900 |
| hanoi-lite-triple-task1-v0 | 49 | 7 | 2100 |
| hanoi-lite-triple-task2-v0 | 49 | 7 | 2100 |
| Task | State dimensions | Action dimensions | Maximum episode length |
| visual-block-single-task1-v0 | 32242243 | 7 | 1250 |
| visual-block-double-task1-v0 | 32242243 | 7 | 2500 |
| visual-block-double-task2-v0 | 32242243 | 7 | 2500 |
| visual-block-triple-task1-v0 | 32242243 | 7 | 3750 |
| visual-block-triple-task2-v0 | 32242243 | 7 | 3750 |
| visual-block-quadruple-task1-v0 | 32242243 | 7 | 5000 |
| visual-block-quadruple-task2-v0 | 32242243 | 7 | 5000 |
| visual-block-quadruple-task3-v0 | 32242243 | 7 | 5000 |
| visual-chamber-easy-task1-v0 | 32242243 | 7 | 4000 |
| visual-chamber-easy-task2-v0 | 32242243 | 7 | 4000 |
| visual-chamber-easy-task3-v0 | 32242243 | 7 | 4000 |
| visual-chamber-medium-task1-v0 | 32242243 | 7 | 5000 |
| visual-chamber-medium-task2-v0 | 32242243 | 7 | 5000 |
| visual-chamber-hard-task1-v0 | 32242243 | 7 | 5500 |
| visual-chamber-hard-task2-v0 | 32242243 | 7 | 5500 |
| visual-switch-3x3-task1-v0 | 32242243 | 7 | 1500 |
| visual-switch-3x3-task2-v0 | 32242243 | 7 | 1500 |
| visual-switch-4x4-task1-v0 | 32242243 | 7 | 1500 |
| visual-switch-4x4-task2-v0 | 32242243 | 7 | 1500 |
| visual-switch-5x5-task1-v0 | 32242243 | 7 | 4000 |
| visual-switch-5x5-task2-v0 | 32242243 | 7 | 4000 |
| visual-hanoi-single-task1-v0 | 32242243 | 7 | 1000 |
| visual-hanoi-single-task2-v0 | 32242243 | 7 | 1000 |
| visual-hanoi-double-task1-v0 | 32242243 | 7 | 3000 |
| visual-hanoi-double-task2-v0 | 32242243 | 7 | 3000 |
| visual-hanoi-triple-task1-v0 | 32242243 | 7 | 7000 |
| visual-hanoi-triple-task2-v0 | 32242243 | 7 | 7000 |
| visual-bowling-task1-v0 | 32242243 | 7 | 500 |
| visual-block-lite-single-task1-v0 | 32242243 | 7 | 200 |
| visual-block-lite-double-task1-v0 | 32242243 | 7 | 400 |
| visual-block-lite-double-task2-v0 | 32242243 | 7 | 400 |
| visual-block-lite-triple-task1-v0 | 32242243 | 7 | 600 |
| visual-block-lite-triple-task2-v0 | 32242243 | 7 | 600 |
| visual-block-lite-quadruple-task1-v0 | 32242243 | 7 | 800 |
| visual-block-lite-quadruple-task2-v0 | 32242243 | 7 | 800 |
| visual-block-lite-quadruple-task3-v0 | 32242243 | 7 | 800 |
| visual-chamber-lite-easy-task1-v0 | 32242243 | 7 | 500 |
| visual-chamber-lite-easy-task2-v0 | 32242243 | 7 | 500 |
| visual-chamber-lite-easy-task3-v0 | 32242243 | 7 | 500 |
| visual-chamber-lite-medium-task1-v0 | 32242243 | 7 | 600 |
| visual-chamber-lite-medium-task2-v0 | 32242243 | 7 | 600 |
| visual-chamber-lite-hard-task1-v0 | 32242243 | 7 | 700 |
| visual-chamber-lite-hard-task2-v0 | 32242243 | 7 | 700 |
| visual-switch-lite-3x3-task1-v0 | 32242243 | 7 | 300 |
| visual-switch-lite-3x3-task2-v0 | 32242243 | 7 | 300 |
| visual-switch-lite-4x4-task1-v0 | 32242243 | 7 | 300 |
| visual-switch-lite-4x4-task2-v0 | 32242243 | 7 | 300 |
| visual-switch-lite-5x5-task1-v0 | 32242243 | 7 | 800 |
| visual-switch-lite-5x5-task2-v0 | 32242243 | 7 | 800 |
| visual-hanoi-lite-single-task1-v0 | 32242243 | 7 | 300 |
| visual-hanoi-lite-single-task2-v0 | 32242243 | 7 | 300 |
| visual-hanoi-lite-double-task1-v0 | 32242243 | 7 | 900 |
| visual-hanoi-lite-double-task2-v0 | 32242243 | 7 | 900 |
| visual-hanoi-lite-triple-task1-v0 | 32242243 | 7 | 2100 |
| visual-hanoi-lite-triple-task2-v0 | 32242243 | 7 | 2100 |
| Task | Episodes | Transitions | Mean episode length | Success rate | Throughput |
| block-single-task1-v0 | 10K | 7.3M | 729.3 | 88 | 1.51 |
| block-double-task1-v0 | 30K | 53.4M | 1778.9 | 79 | 1.11 |
| block-double-task2-v0 | 30K | 45.3M | 1511.5 | 88 | 1.45 |
| block-triple-task1-v0 | 100K | 287.3M | 2873.0 | 72 | 0.94 |
| block-triple-task2-v0 | 100K | 279.0M | 2790.5 | 72 | 0.96 |
| block-quadruple-task1-v0 | 100K | 405.7M | 4056.8 | 65 | 0.80 |
| block-quadruple-task2-v0 | 100K | 403.3M | 4033.1 | 60 | 0.75 |
| block-quadruple-task3-v0 | 100K | 452.8M | 4527.7 | 33 | 0.37 |
| chamber-easy-task1-v0 | 10K | 19.7M | 1968.5 | 96 | 1.96 |
| chamber-easy-task2-v0 | 10K | 33.0M | 3295.4 | 65 | 0.79 |
| chamber-easy-task3-v0 | 10K | 33.8M | 3377.6 | 58 | 0.69 |
| chamber-medium-task1-v0 | 30K | 128.7M | 4288.8 | 58 | 0.67 |
| chamber-medium-task2-v0 | 30K | 134.0M | 4467.8 | 44 | 0.49 |
| chamber-hard-task1-v0 | 100K | 502.8M | 5028.0 | 42 | 0.46 |
| chamber-hard-task2-v0 | 100K | 490.3M | 4902.9 | 42 | 0.47 |
| switch-3x3-task1-v0 | 10K | 14.3M | 1433.9 | 11 | 0.11 |
| switch-3x3-task2-v0 | 10K | 13.5M | 1352.9 | 21 | 0.24 |
| switch-4x4-task1-v0 | 30K | 43.6M | 1454.1 | 9 | 0.10 |
| switch-4x4-task2-v0 | 30K | 43.9M | 1463.6 | 8 | 0.08 |
| switch-5x5-task1-v0 | 100K | 395.1M | 3951.0 | 5 | 0.05 |
| switch-5x5-task2-v0 | 100K | 395.7M | 3956.7 | 4 | 0.05 |
| hanoi-single-task1-v0 | 10K | 7.1M | 706.8 | 100 | 1.41 |
| hanoi-single-task2-v0 | 10K | 7.1M | 712.1 | 99 | 1.40 |
| hanoi-double-task1-v0 | 30K | 77.9M | 2595.3 | 71 | 0.82 |
| hanoi-double-task2-v0 | 30K | 78.5M | 2615.1 | 69 | 0.79 |
| hanoi-triple-task1-v0 | 100K | 618.2M | 6181.6 | 58 | 0.65 |
| hanoi-triple-task2-v0 | 100K | 618.9M | 6188.9 | 53 | 0.60 |
| bowling-task1-v0 | 10K | 5.0M | 500.0 | 30 | - |
| block-lite-single-task1-v0 | 10K | 0.8M | 77.2 | 97 | 2.50 |
| block-lite-double-task1-v0 | 30K | 5.8M | 193.7 | 95 | 1.96 |
| block-lite-double-task2-v0 | 30K | 4.8M | 159.6 | 98 | 2.45 |
| block-lite-triple-task1-v0 | 100K | 31.6M | 315.7 | 94 | 1.79 |
| block-lite-triple-task2-v0 | 100K | 32.1M | 321.1 | 89 | 1.66 |
| block-lite-quadruple-task1-v0 | 100K | 45.5M | 454.8 | 93 | 1.63 |
| block-lite-quadruple-task2-v0 | 100K | 48.9M | 489.0 | 80 | 1.30 |
| block-lite-quadruple-task3-v0 | 100K | 62.9M | 628.7 | 52 | 0.66 |
| chamber-lite-easy-task1-v0 | 10K | 2.1M | 210.5 | 96 | 2.28 |
| chamber-lite-easy-task2-v0 | 10K | 3.6M | 359.0 | 82 | 1.14 |
| chamber-lite-easy-task3-v0 | 10K | 3.8M | 377.6 | 72 | 0.96 |
| chamber-lite-medium-task1-v0 | 30K | 14.0M | 467.1 | 74 | 0.95 |
| chamber-lite-medium-task2-v0 | 30K | 15.1M | 502.2 | 59 | 0.70 |
| chamber-lite-hard-task1-v0 | 100K | 57.8M | 577.8 | 65 | 0.78 |
| chamber-lite-hard-task2-v0 | 100K | 56.9M | 569.4 | 60 | 0.73 |
| switch-lite-3x3-task1-v0 | 10K | 2.7M | 267.6 | 22 | 0.25 |
| switch-lite-3x3-task2-v0 | 10K | 2.4M | 243.9 | 34 | 0.42 |
| switch-lite-4x4-task1-v0 | 30K | 8.1M | 271.7 | 21 | 0.24 |
| switch-lite-4x4-task2-v0 | 30K | 8.3M | 276.7 | 18 | 0.20 |
| switch-lite-5x5-task1-v0 | 100K | 74.8M | 748.0 | 18 | 0.19 |
| switch-lite-5x5-task2-v0 | 100K | 75.5M | 754.5 | 16 | 0.17 |
| hanoi-lite-single-task1-v0 | 10K | 1.4M | 141.5 | 100 | 2.12 |
| hanoi-lite-single-task2-v0 | 10K | 1.5M | 145.9 | 97 | 1.99 |
| hanoi-lite-double-task1-v0 | 30K | 15.2M | 506.7 | 94 | 1.68 |
| hanoi-lite-double-task2-v0 | 30K | 15.5M | 516.4 | 89 | 1.56 |
| hanoi-lite-triple-task1-v0 | 100K | 122.5M | 1224.8 | 75 | 1.29 |
| hanoi-lite-triple-task2-v0 | 100K | 123.4M | 1234.2 | 70 | 1.20 |
| Task | BC | FBC | FSQBC |
| block-single-task1-v0 | 88 0 | 90 1 | 89 0 |
| block-double-task1-v0 | 51 5 | 60 1 | 72 0 |
| block-double-task2-v0 | 68 3 | 71 2 | 74 2 |
| block-triple-task1-v0 | 1 0 | 2 1 | 29 2 |
| block-triple-task2-v0 | 27 2 | 8 1 | 30 8 |
| block-quadruple-task1-v0 | 0 0 | 0 0 | 0 0 |
| block-quadruple-task2-v0 | 3 0 | 0 0 | 6 2 |
| block-quadruple-task3-v0 | 2 0 | 8 3 | 25 2 |
| chamber-easy-task1-v0 | 65 8 | 73 9 | 88 5 |
| chamber-easy-task2-v0 | 40 0 | 53 0 | 48 5 |
| chamber-easy-task3-v0 | 42 0 | 48 6 | 38 4 |
| chamber-medium-task1-v0 | 7 1 | 12 0 | 27 1 |
| chamber-medium-task2-v0 | 10 3 | 5 0 | 23 1 |
| chamber-hard-task1-v0 | 0 0 | 1 1 | 2 0 |
| chamber-hard-task2-v0 | 1 0 | 0 0 | 8 4 |
| switch-3x3-task1-v0 | 21 0 | 16 1 | 20 2 |
| switch-3x3-task2-v0 | 25 3 | 16 0 | 19 3 |
| switch-4x4-task1-v0 | 8 0 | 5 0 | 6 0 |
| switch-4x4-task2-v0 | 2 0 | 1 0 | 1 0 |
| switch-5x5-task1-v0 | 0 0 | 0 0 | 0 0 |
| switch-5x5-task2-v0 | 0 0 | 0 0 | 0 0 |
| hanoi-single-task1-v0 | 56 1 | 41 31 | 84 10 |
| hanoi-single-task2-v0 | 62 1 | 74 0 | 66 2 |
| hanoi-double-task1-v0 | 23 2 | 21 3 | 20 2 |
| hanoi-double-task2-v0 | 28 2 | 16 11 | 18 3 |
| hanoi-triple-task1-v0 | 18 0 | 4 2 | 1 0 |
| hanoi-triple-task2-v0 | 14 1 | 8 1 | 2 0 |
| bowling-task1-v0 | 39 1 | 35 1 | 32 1 |
| block-lite-single-task1-v0 | 93 0 | 64 9 | 96 0 |
| block-lite-double-task1-v0 | 26 6 | 41 2 | 73 2 |
| block-lite-double-task2-v0 | 46 5 | 53 3 | 74 8 |
| block-lite-triple-task1-v0 | 1 1 | 1 1 | 0 0 |
| block-lite-triple-task2-v0 | 7 1 | 22 6 | 8 2 |
| block-lite-quadruple-task1-v0 | 0 0 | 0 0 | 0 0 |
| block-lite-quadruple-task2-v0 | 0 0 | 0 0 | 0 0 |
| block-lite-quadruple-task3-v0 | 0 0 | 4 4 | 3 1 |
| chamber-lite-easy-task1-v0 | 27 2 | 78 9 | 66 4 |
| chamber-lite-easy-task2-v0 | 11 0 | 35 4 | 22 5 |
| chamber-lite-easy-task3-v0 | 9 1 | 26 6 | 17 4 |
| chamber-lite-medium-task1-v0 | 1 0 | 3 1 | 1 0 |
| chamber-lite-medium-task2-v0 | 0 0 | 2 1 | 0 0 |
| chamber-lite-hard-task1-v0 | 0 0 | 0 0 | 0 0 |
| chamber-lite-hard-task2-v0 | 0 0 | 0 0 | 0 0 |
| switch-lite-3x3-task1-v0 | 2 1 | 6 1 | 1 1 |
| switch-lite-3x3-task2-v0 | 4 0 | 6 1 | 3 1 |
| switch-lite-4x4-task1-v0 | 1 0 | 2 1 | 1 0 |
| switch-lite-4x4-task2-v0 | 1 0 | 1 0 | 0 0 |
| switch-lite-5x5-task1-v0 | 0 0 | 0 0 | 0 0 |
| switch-lite-5x5-task2-v0 | 0 0 | 0 0 | 0 0 |
| hanoi-lite-single-task1-v0 | 59 6 | 9 3 | 84 0 |
| hanoi-lite-single-task2-v0 | 67 2 | 2 1 | 56 2 |
| hanoi-lite-double-task1-v0 | 9 2 | 0 0 | 20 1 |
| hanoi-lite-double-task2-v0 | 0 0 | 0 0 | 0 0 |
| hanoi-lite-triple-task1-v0 | 0 0 | 0 0 | 0 0 |
| hanoi-lite-triple-task2-v0 | 0 0 | 0 0 | 0 0 |
| Task | BC | FBC | FSQBC |
| block-single-task1-v0 | 1.41 0.01 | 1.45 0.04 | 1.40 0.00 |
| block-double-task1-v0 | 0.58 0.07 | 0.71 0.02 | 0.88 0.00 |
| block-double-task2-v0 | 0.95 0.05 | 1.00 0.04 | 1.07 0.05 |
| block-triple-task1-v0 | 0.01 0.00 | 0.02 0.01 | 0.30 0.03 |
| block-triple-task2-v0 | 0.29 0.02 | 0.09 0.01 | 0.33 0.10 |
| block-quadruple-task1-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| block-quadruple-task2-v0 | 0.03 0.00 | 0.00 0.00 | 0.06 0.02 |
| block-quadruple-task3-v0 | 0.02 0.00 | 0.08 0.03 | 0.26 0.02 |
| chamber-easy-task1-v0 | 0.89 0.16 | 1.07 0.18 | 1.54 0.15 |
| chamber-easy-task2-v0 | 0.43 0.00 | 0.61 0.01 | 0.53 0.06 |
| chamber-easy-task3-v0 | 0.46 0.01 | 0.53 0.07 | 0.42 0.05 |
| chamber-medium-task1-v0 | 0.07 0.01 | 0.12 0.00 | 0.28 0.01 |
| chamber-medium-task2-v0 | 0.10 0.03 | 0.05 0.00 | 0.24 0.01 |
| chamber-hard-task1-v0 | 0.00 0.00 | 0.01 0.01 | 0.02 0.00 |
| chamber-hard-task2-v0 | 0.01 0.00 | 0.00 0.00 | 0.08 0.05 |
| switch-3x3-task1-v0 | 0.23 0.00 | 0.17 0.01 | 0.22 0.02 |
| switch-3x3-task2-v0 | 0.27 0.03 | 0.17 0.00 | 0.21 0.03 |
| switch-4x4-task1-v0 | 0.08 0.00 | 0.05 0.00 | 0.06 0.00 |
| switch-4x4-task2-v0 | 0.02 0.00 | 0.01 0.00 | 0.01 0.00 |
| switch-5x5-task1-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| switch-5x5-task2-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| hanoi-single-task1-v0 | 0.63 0.02 | 0.48 0.38 | 1.08 0.16 |
| hanoi-single-task2-v0 | 0.75 0.02 | 0.93 0.00 | 0.81 0.03 |
| hanoi-double-task1-v0 | 0.24 0.03 | 0.22 0.03 | 0.21 0.02 |
| hanoi-double-task2-v0 | 0.30 0.02 | 0.17 0.12 | 0.19 0.03 |
| hanoi-triple-task1-v0 | 0.21 0.00 | 0.05 0.02 | 0.01 0.00 |
| hanoi-triple-task2-v0 | 0.15 0.01 | 0.08 0.01 | 0.02 0.00 |
| block-lite-single-task1-v0 | 1.93 0.00 | 0.93 0.18 | 2.07 0.02 |
| block-lite-double-task1-v0 | 0.28 0.07 | 0.48 0.02 | 1.02 0.07 |
| block-lite-double-task2-v0 | 0.59 0.09 | 0.72 0.07 | 1.19 0.21 |
| block-lite-triple-task1-v0 | 0.01 0.01 | 0.01 0.01 | 0.00 0.00 |
| block-lite-triple-task2-v0 | 0.07 0.01 | 0.24 0.07 | 0.08 0.02 |
| block-lite-quadruple-task1-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| block-lite-quadruple-task2-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| block-lite-quadruple-task3-v0 | 0.00 0.00 | 0.05 0.04 | 0.03 0.01 |
| chamber-lite-easy-task1-v0 | 0.31 0.03 | 1.24 0.25 | 0.96 0.08 |
| chamber-lite-easy-task2-v0 | 0.11 0.00 | 0.39 0.04 | 0.23 0.05 |
| chamber-lite-easy-task3-v0 | 0.09 0.01 | 0.28 0.07 | 0.18 0.04 |
| chamber-lite-medium-task1-v0 | 0.01 0.00 | 0.03 0.01 | 0.01 0.00 |
| chamber-lite-medium-task2-v0 | 0.00 0.00 | 0.02 0.01 | 0.00 0.00 |
| chamber-lite-hard-task1-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| chamber-lite-hard-task2-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| switch-lite-3x3-task1-v0 | 0.02 0.01 | 0.06 0.02 | 0.01 0.01 |
| switch-lite-3x3-task2-v0 | 0.04 0.00 | 0.07 0.01 | 0.04 0.01 |
| switch-lite-4x4-task1-v0 | 0.01 0.00 | 0.02 0.01 | 0.01 0.00 |
| switch-lite-4x4-task2-v0 | 0.01 0.00 | 0.01 0.00 | 0.00 0.00 |
| switch-lite-5x5-task1-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| switch-lite-5x5-task2-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| hanoi-lite-single-task1-v0 | 0.85 0.14 | 0.11 0.04 | 1.49 0.00 |
| hanoi-lite-single-task2-v0 | 1.02 0.05 | 0.02 0.01 | 0.80 0.03 |
| hanoi-lite-double-task1-v0 | 0.10 0.02 | 0.00 0.00 | 0.23 0.01 |
| hanoi-lite-double-task2-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| hanoi-lite-triple-task1-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |
| hanoi-lite-triple-task2-v0 | 0.00 0.00 | 0.00 0.00 | 0.00 0.00 |