Overview
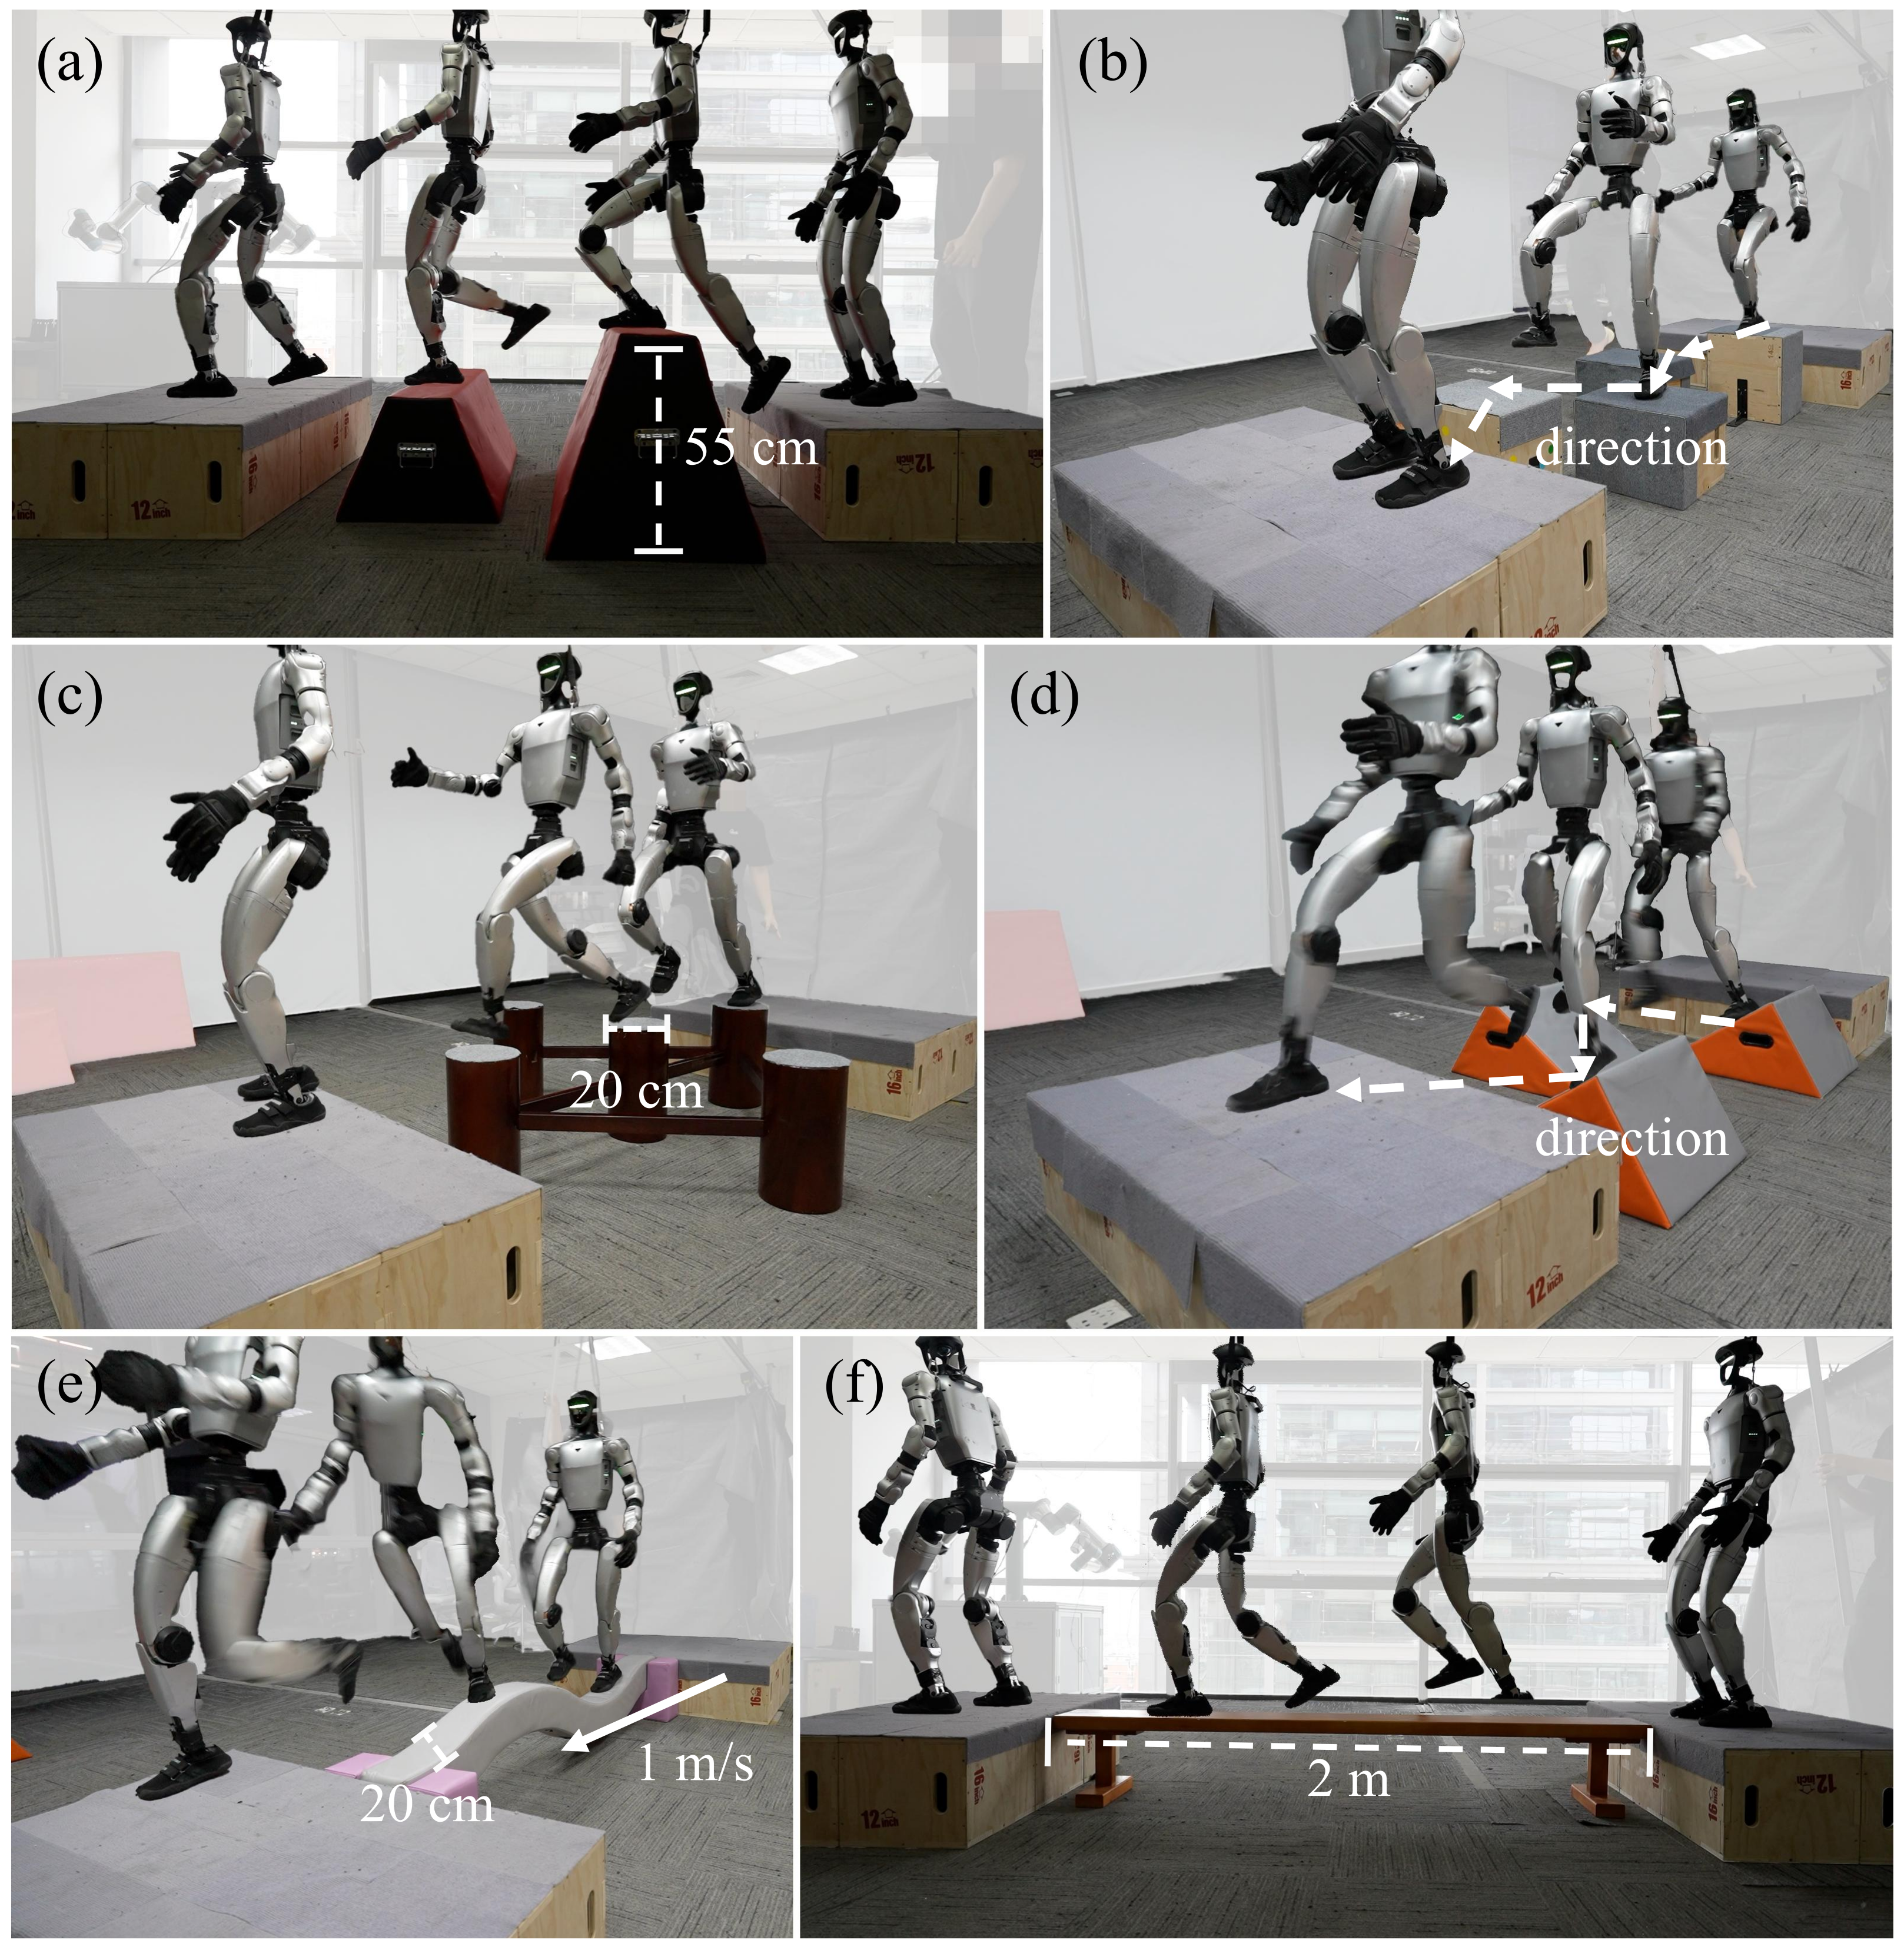
The complete 17-page paper studies depth-guided parkour on a 29-degree-of-freedom Unitree G 1. Figure 1 retains all six selected hardware examples, including 20 cm footholds, a curved narrow support and a 2 m beam. These illustrate the tested apparatus rather than a general outdoor-locomotion guarantee.
At a glance
The policy combines current depth features with a short history, using a hand-designed frame-saliency prior, learned temporal weights and gated residual fusion. A separate alternation loss complements mirror symmetry to discourage synchronized two-leg hopping.
Simulation comparisons and small hardware trials support these components on five terrain families. The paper’s main and appendix ablation aggregates differ, and implementation details contain a stagnation-threshold discrepancy; the notes preserve those distinctions.
1 Introduction
Sparse supports can disappear from an egocentric camera before the robot places its foot. Purely reactive control loses that geometry, while explicit maps add reconstruction and localization work.
This method retains recent depth features and biases their use toward frames with stronger depth discontinuities. The resulting representation joins proprioceptive history in an end-to-end policy. Gait regularization addresses a separate problem: mirror-consistent actions can still collapse into synchronized hopping.
“Depth-only” refers to exteroception. The actor also receives robot state, previous actions and velocity commands.
2 Related Work
The related work connects map-based and image-conditioned traversal, temporal memory, and symmetry-aware policy learning. A short feature history offers a simpler alternative to building a complete terrain map.
The proposed memory is a finite-window fusion mechanism, rather than a recurrent map with indefinitely persistent terrain state. The symmetry objective is an inductive bias; its effect on actual contact timing is evaluated empirically.
3 Problem Formulation
The task traverses elevated discrete platforms. An asymmetric actor–critic policy is trained with PPO [30]; the critic receives additional clean state and base linear velocity. The actor outputs 29 joint-position targets, converted to torques by the retained PD-control equation.
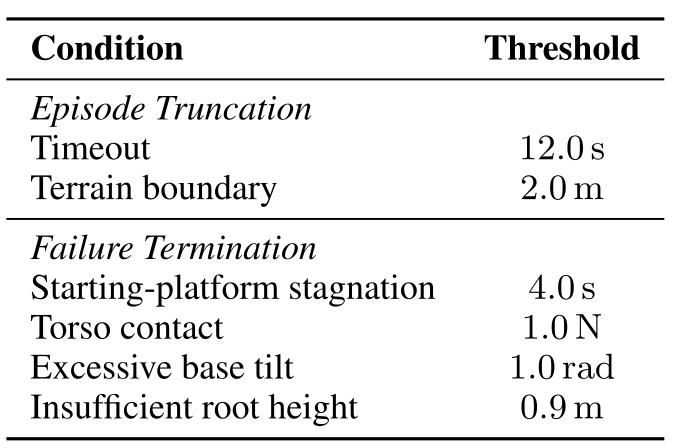
Rewards combine velocity tracking, regularization, safety penalties and an adversarial motion prior. These are training objectives rather than formal safety guarantees. Episodes stop for falls, excessive tilt, boundary/timeout conditions and prolonged starting-platform residence.
The main text says stagnation beyond three seconds terminates an episode; the appendix configuration lists four seconds. Both original descriptions remain available.
The motion-style term follows AMP [26].
Equation 1
| (1) |
4 Method
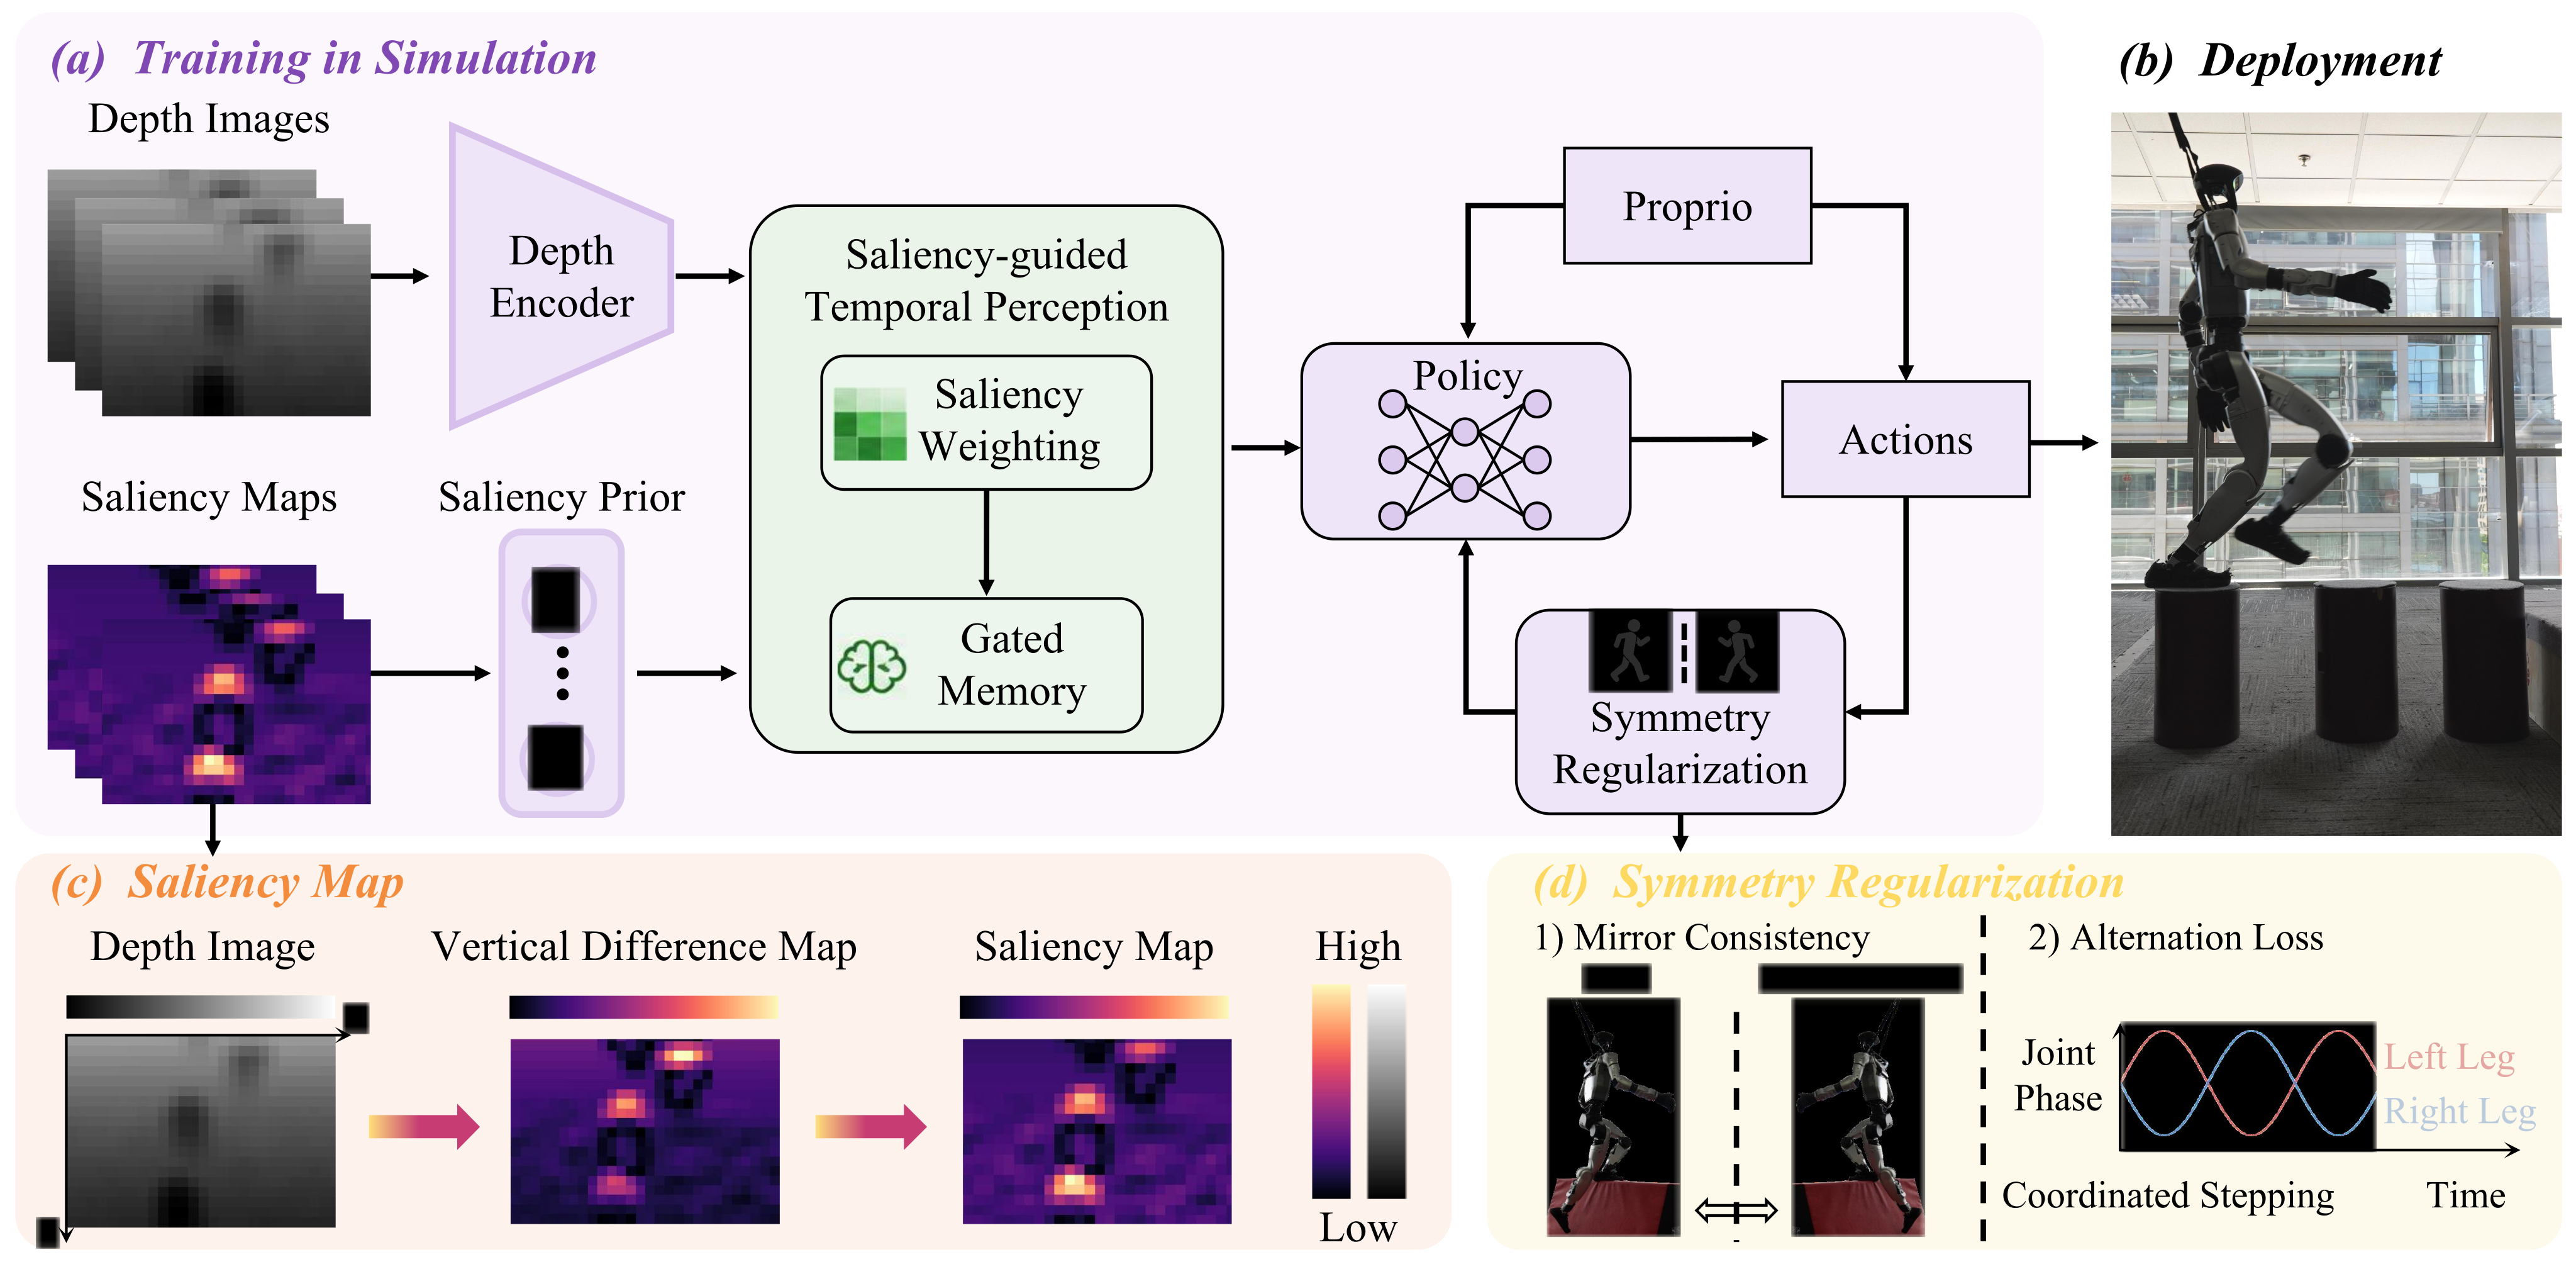
A shared encoder produces current and historical depth latents. Saliency-guided temporal weighting and a learned scalar gate combine them before the policy head. Mirror consistency and an alternation penalty regularize the action policy.
4.1 Saliency Prior
The saliency map takes absolute vertical pixel-to-pixel depth differences, multiplied by relative image row v/H to emphasize lower image regions. Averaging the map yields one scalar prior per frame.
This is a heuristic for potentially useful foothold geometry. It is not a foothold segmentation, a calibrated uncertainty measure or an explicit spatial planner; camera motion and depth artifacts can also create discontinuities.
Equations 2–3
| (2) |
| (3) |
4.2 Temporal Gated Memory
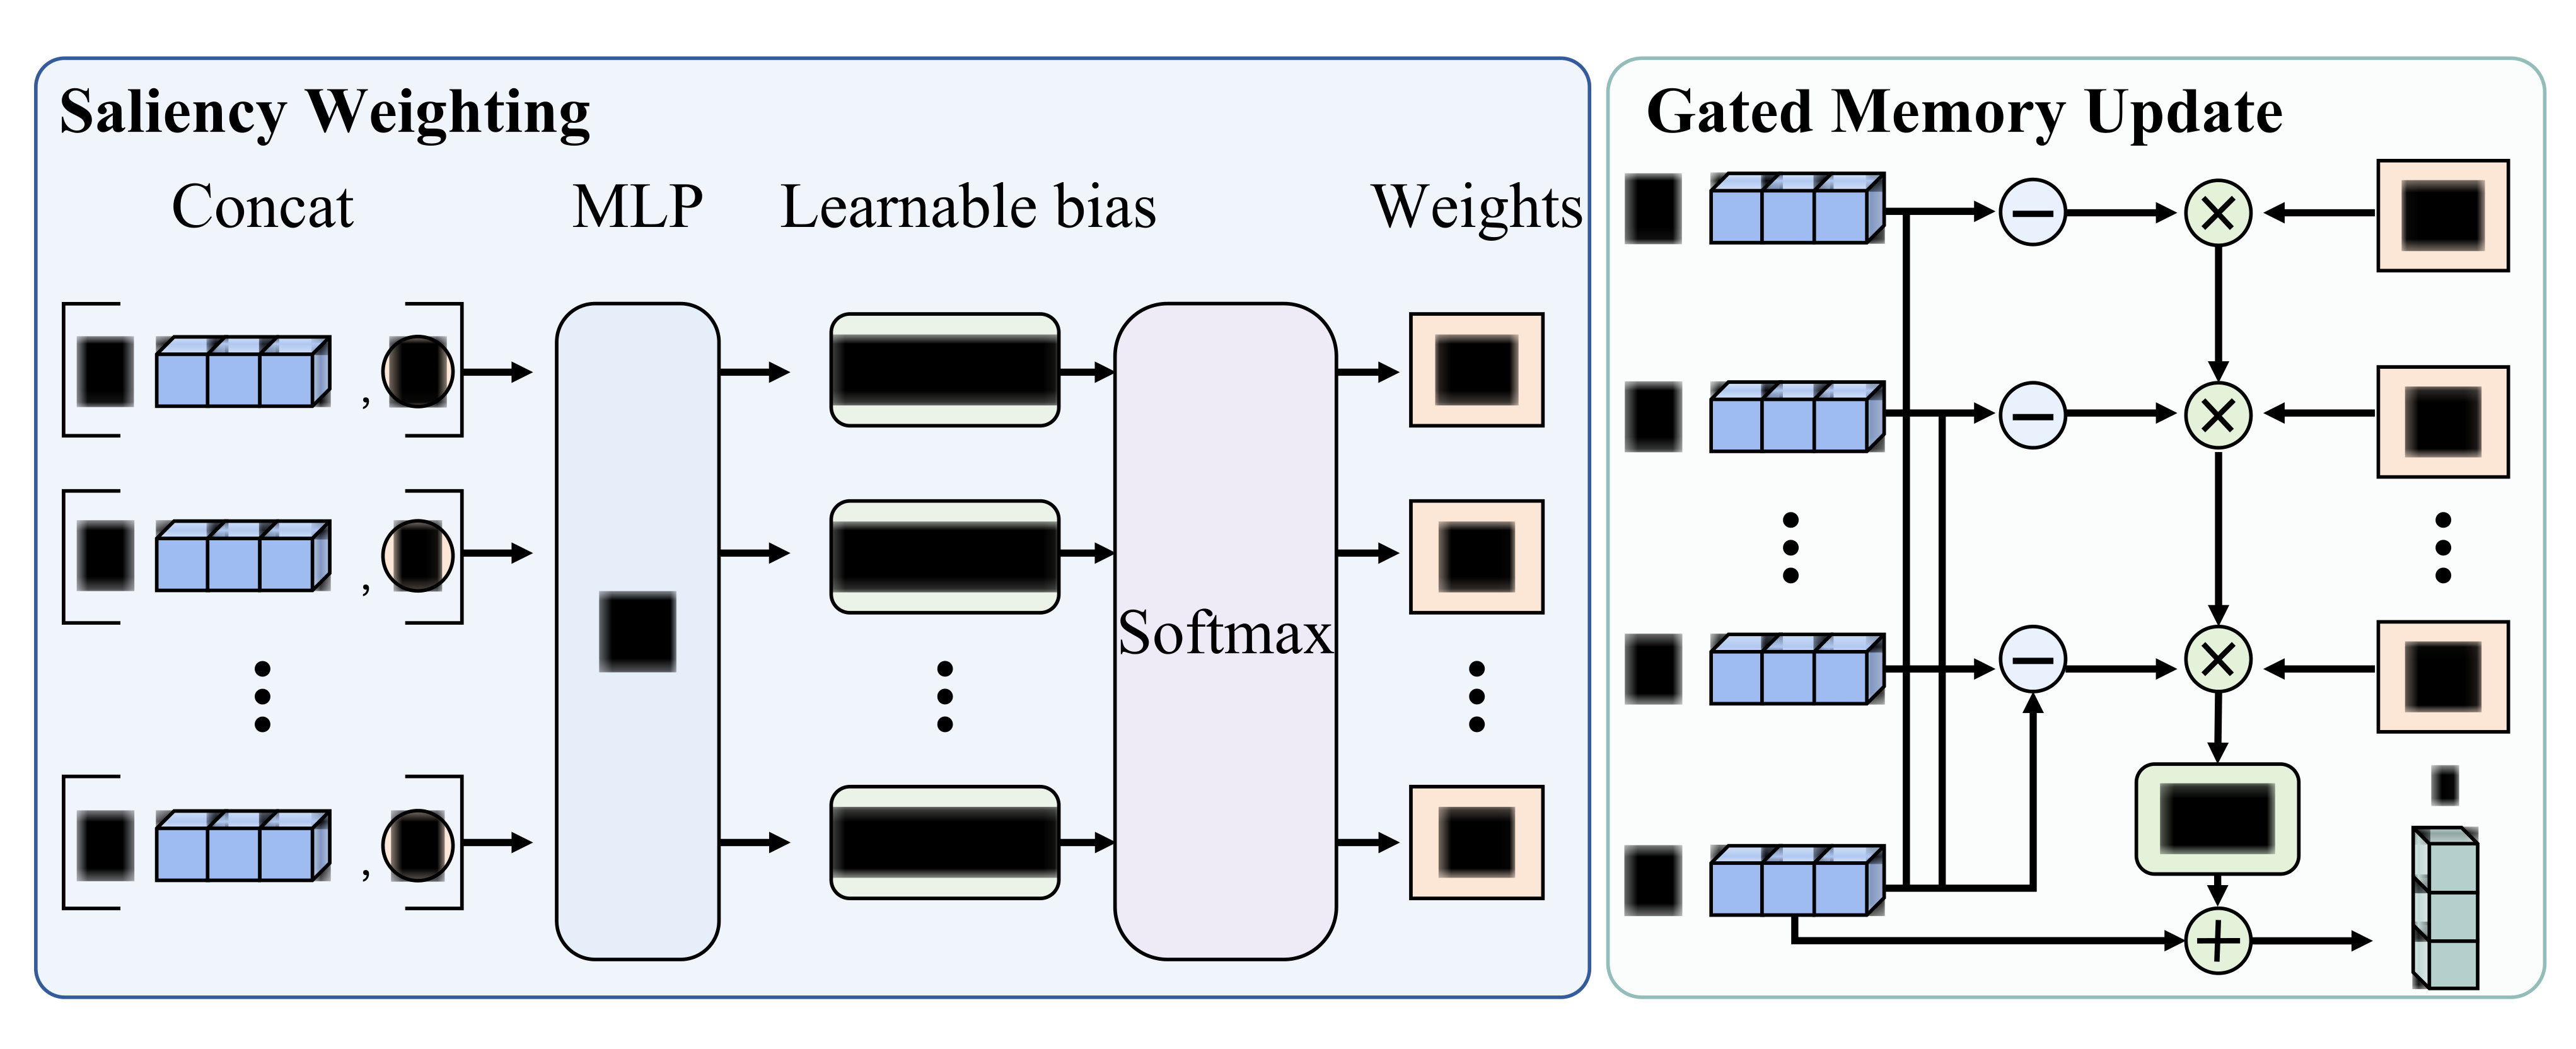
Historical latents are scored by an MLP using their relative saliency, with an additional learned saliency scale and frame bias. Softmax produces temporal weights. A sigmoid of a learned scalar β controls how far the output moves from the current latent toward the weighted history.
Because the weights sum to one, Equation 7 is a blend of current features and weighted historical features. The gate itself is a learned scalar rather than an observation-dependent recurrent update. Selectivity also comes from the frame scores.
The implementation reports a four-frame depth stack; the text does not fully specify sampling intervals, normalization of the relative saliency, encoder widths or all initialization choices.
Equations 4–7
| (4) |
| (5) |
| (6) |
| (7) |
4.3 Symmetry Regularization
Mirror consistency compares the policy output with the mirrored output from mirrored observations. The alternation loss penalizes positive cosine similarity between left/right leg-action subvectors when base speed exceeds a threshold.
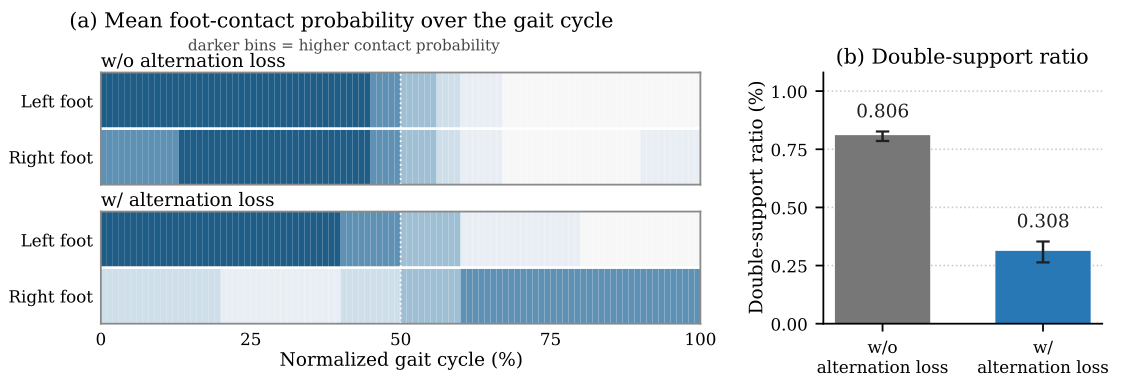
This encourages different leg actions while retaining bilateral structure. It does not directly impose a foot-contact phase schedule. Figure 6 tests whether actual contacts become more alternating.
Equations 8–9
| (8) |
| (9) |
5 Experiments
Experiments ask about simulated traversal, component contributions and hardware transfer. All result tables are retained, including failed ablations and differences between main-text and appendix aggregates.
Accessible table and original citation links
| Terrain Type | Success Rate (%) | Foothold Accuracy (%) | ||
| Hiking | Ours | Hiking | Ours | |
| Boxes | ||||
| Stakes | ||||
| Beams | ||||
| Wedges | ||||
| Trapezoids | ||||
5.1 Simulation Experiments
Training uses Isaac Sim/Isaac Lab, 2,048 parallel G 1 agents and an RTX 4090. Five terrain families—boxes, stakes, beams, wedges and trapezoids—follow a 20×10 difficulty curriculum. These categories appear in training; performance across them is not an unseen-category evaluation.
The policy uses eight proprioceptive frames and a four-frame depth stack. The source reports 5,000 evaluation trials per experiment and three seeds, with means and standard deviations. It does not clearly state whether 5,000 trials is per seed or pooled.
Success means reaching the end without ground contact or falling. Foothold accuracy is the fraction of foot-contact samples within intended supports during inter-platform traversal, rather than the fraction of entire trials completed.
Training uses Isaac Lab [25].
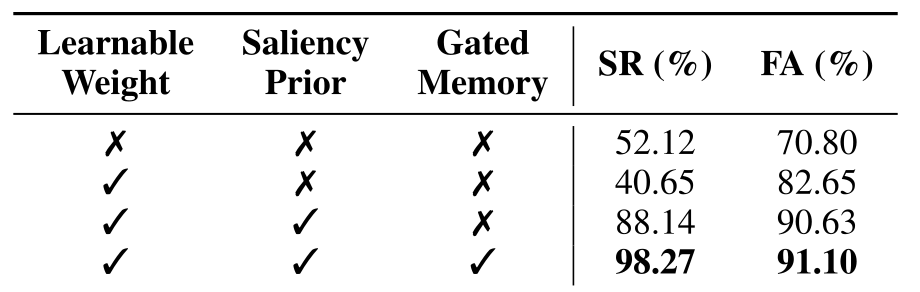
5.1.1 Main Results
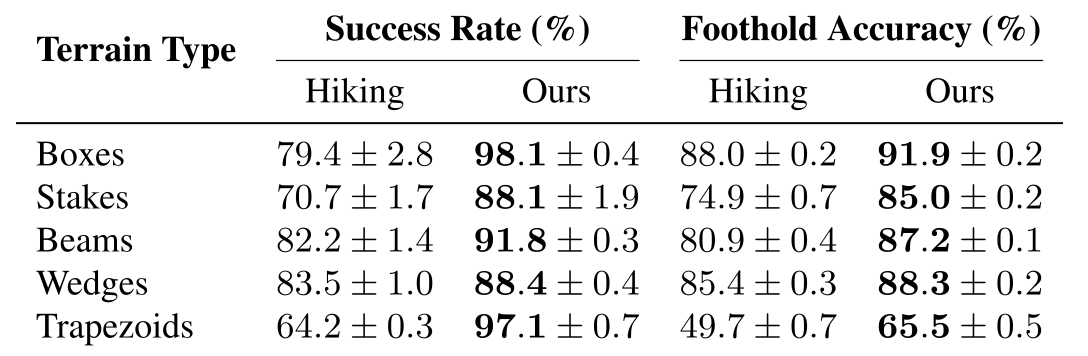
Table 1 averages 92.7% success and 83.6% foothold accuracy, versus 76.0% and 75.8% for the matched-training Hiking baseline: improvements of 16.7 and 7.8 percentage points. Trapezoid foothold accuracy remains 65.5% despite 97.1% trial success.
Table 2 gives 52.12% success for uniform fusion, 40.65% for learned weights alone, 88.14% with saliency and 98.27% with gated fusion. Learned weighting alone reduces success despite improving contact accuracy. The saliency and gate changes are 47.49 and 10.13 percentage points, respectively.
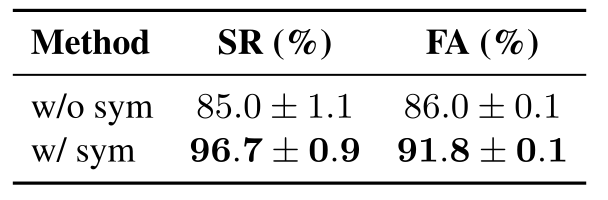
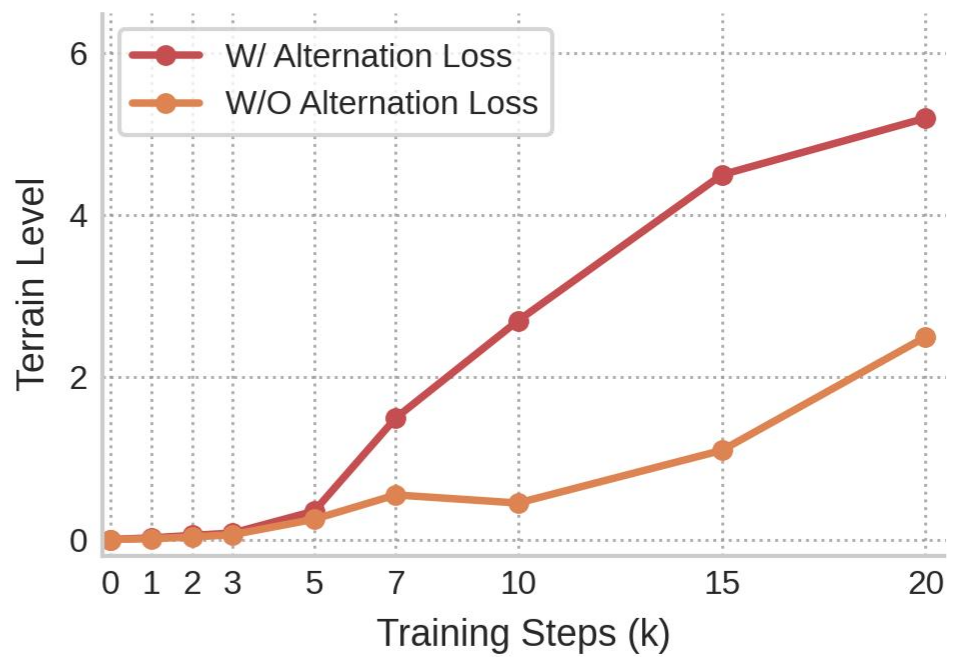
On boxes, symmetry regularization raises success from 85.0% to 96.7% in Table 3. Figure 5 shows faster training with alternation loss. Figure 6 reports double-support ratio falling from 0.806 to 0.308, supporting a change in gait coordination.
These ablation numbers are not interchangeable with Table 1 or the appendix’s terrain-wise ablation. The source does not reconcile their different full-model averages.
The main baseline is Hiking in the Wild [45].
5.2 Real-world Experiments
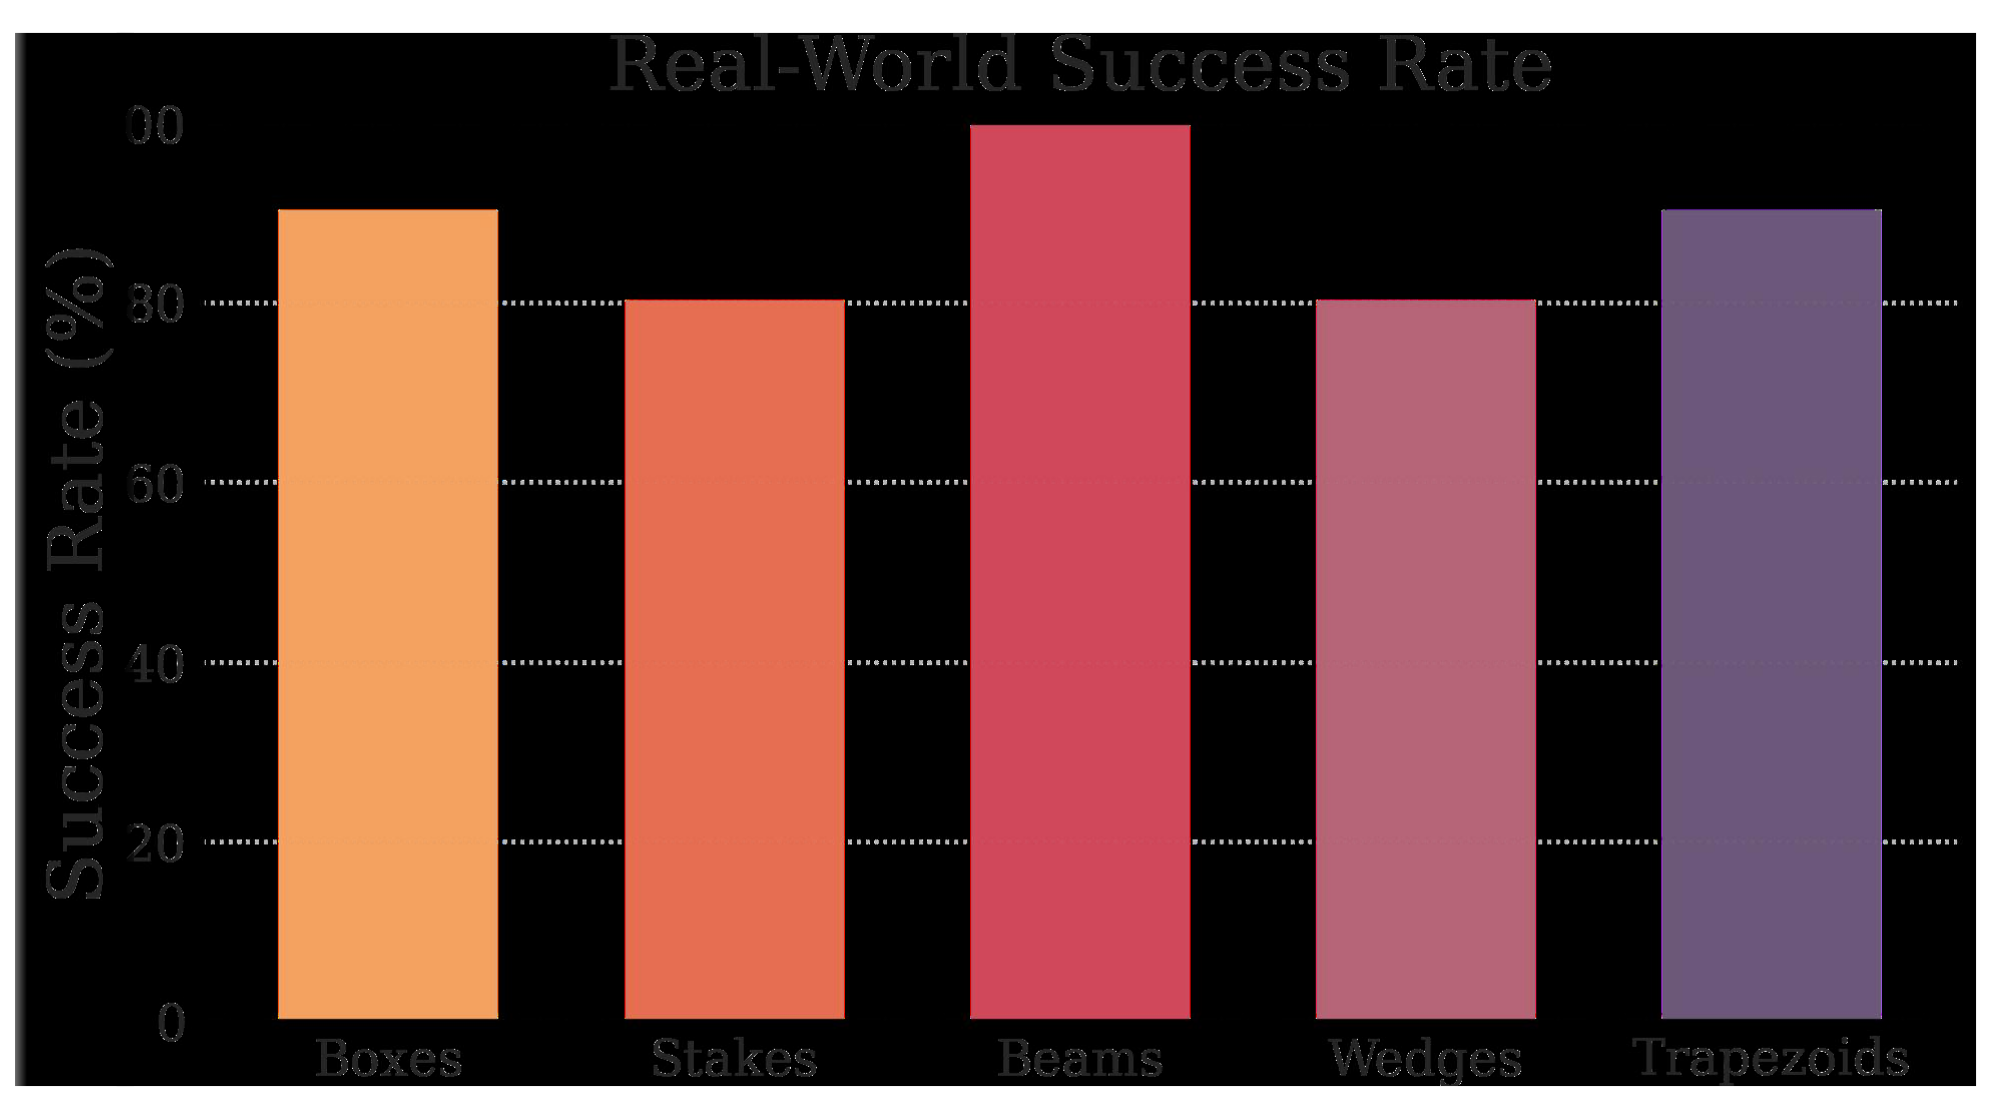
Hardware inference runs at 50 Hz on a Jetson Orin NX under ROS 2. A RealSense D435i captures 480×270 depth at 60 Hz; frames are downsampled to 64×36 and cropped to a 32×18 center-bottom region.
Each terrain setting receives ten independent trials. This is a small evaluation with coarse ten-percentage-point increments, and no hardware baseline comparison or interval estimate is supplied.
5.2.1 Main Results
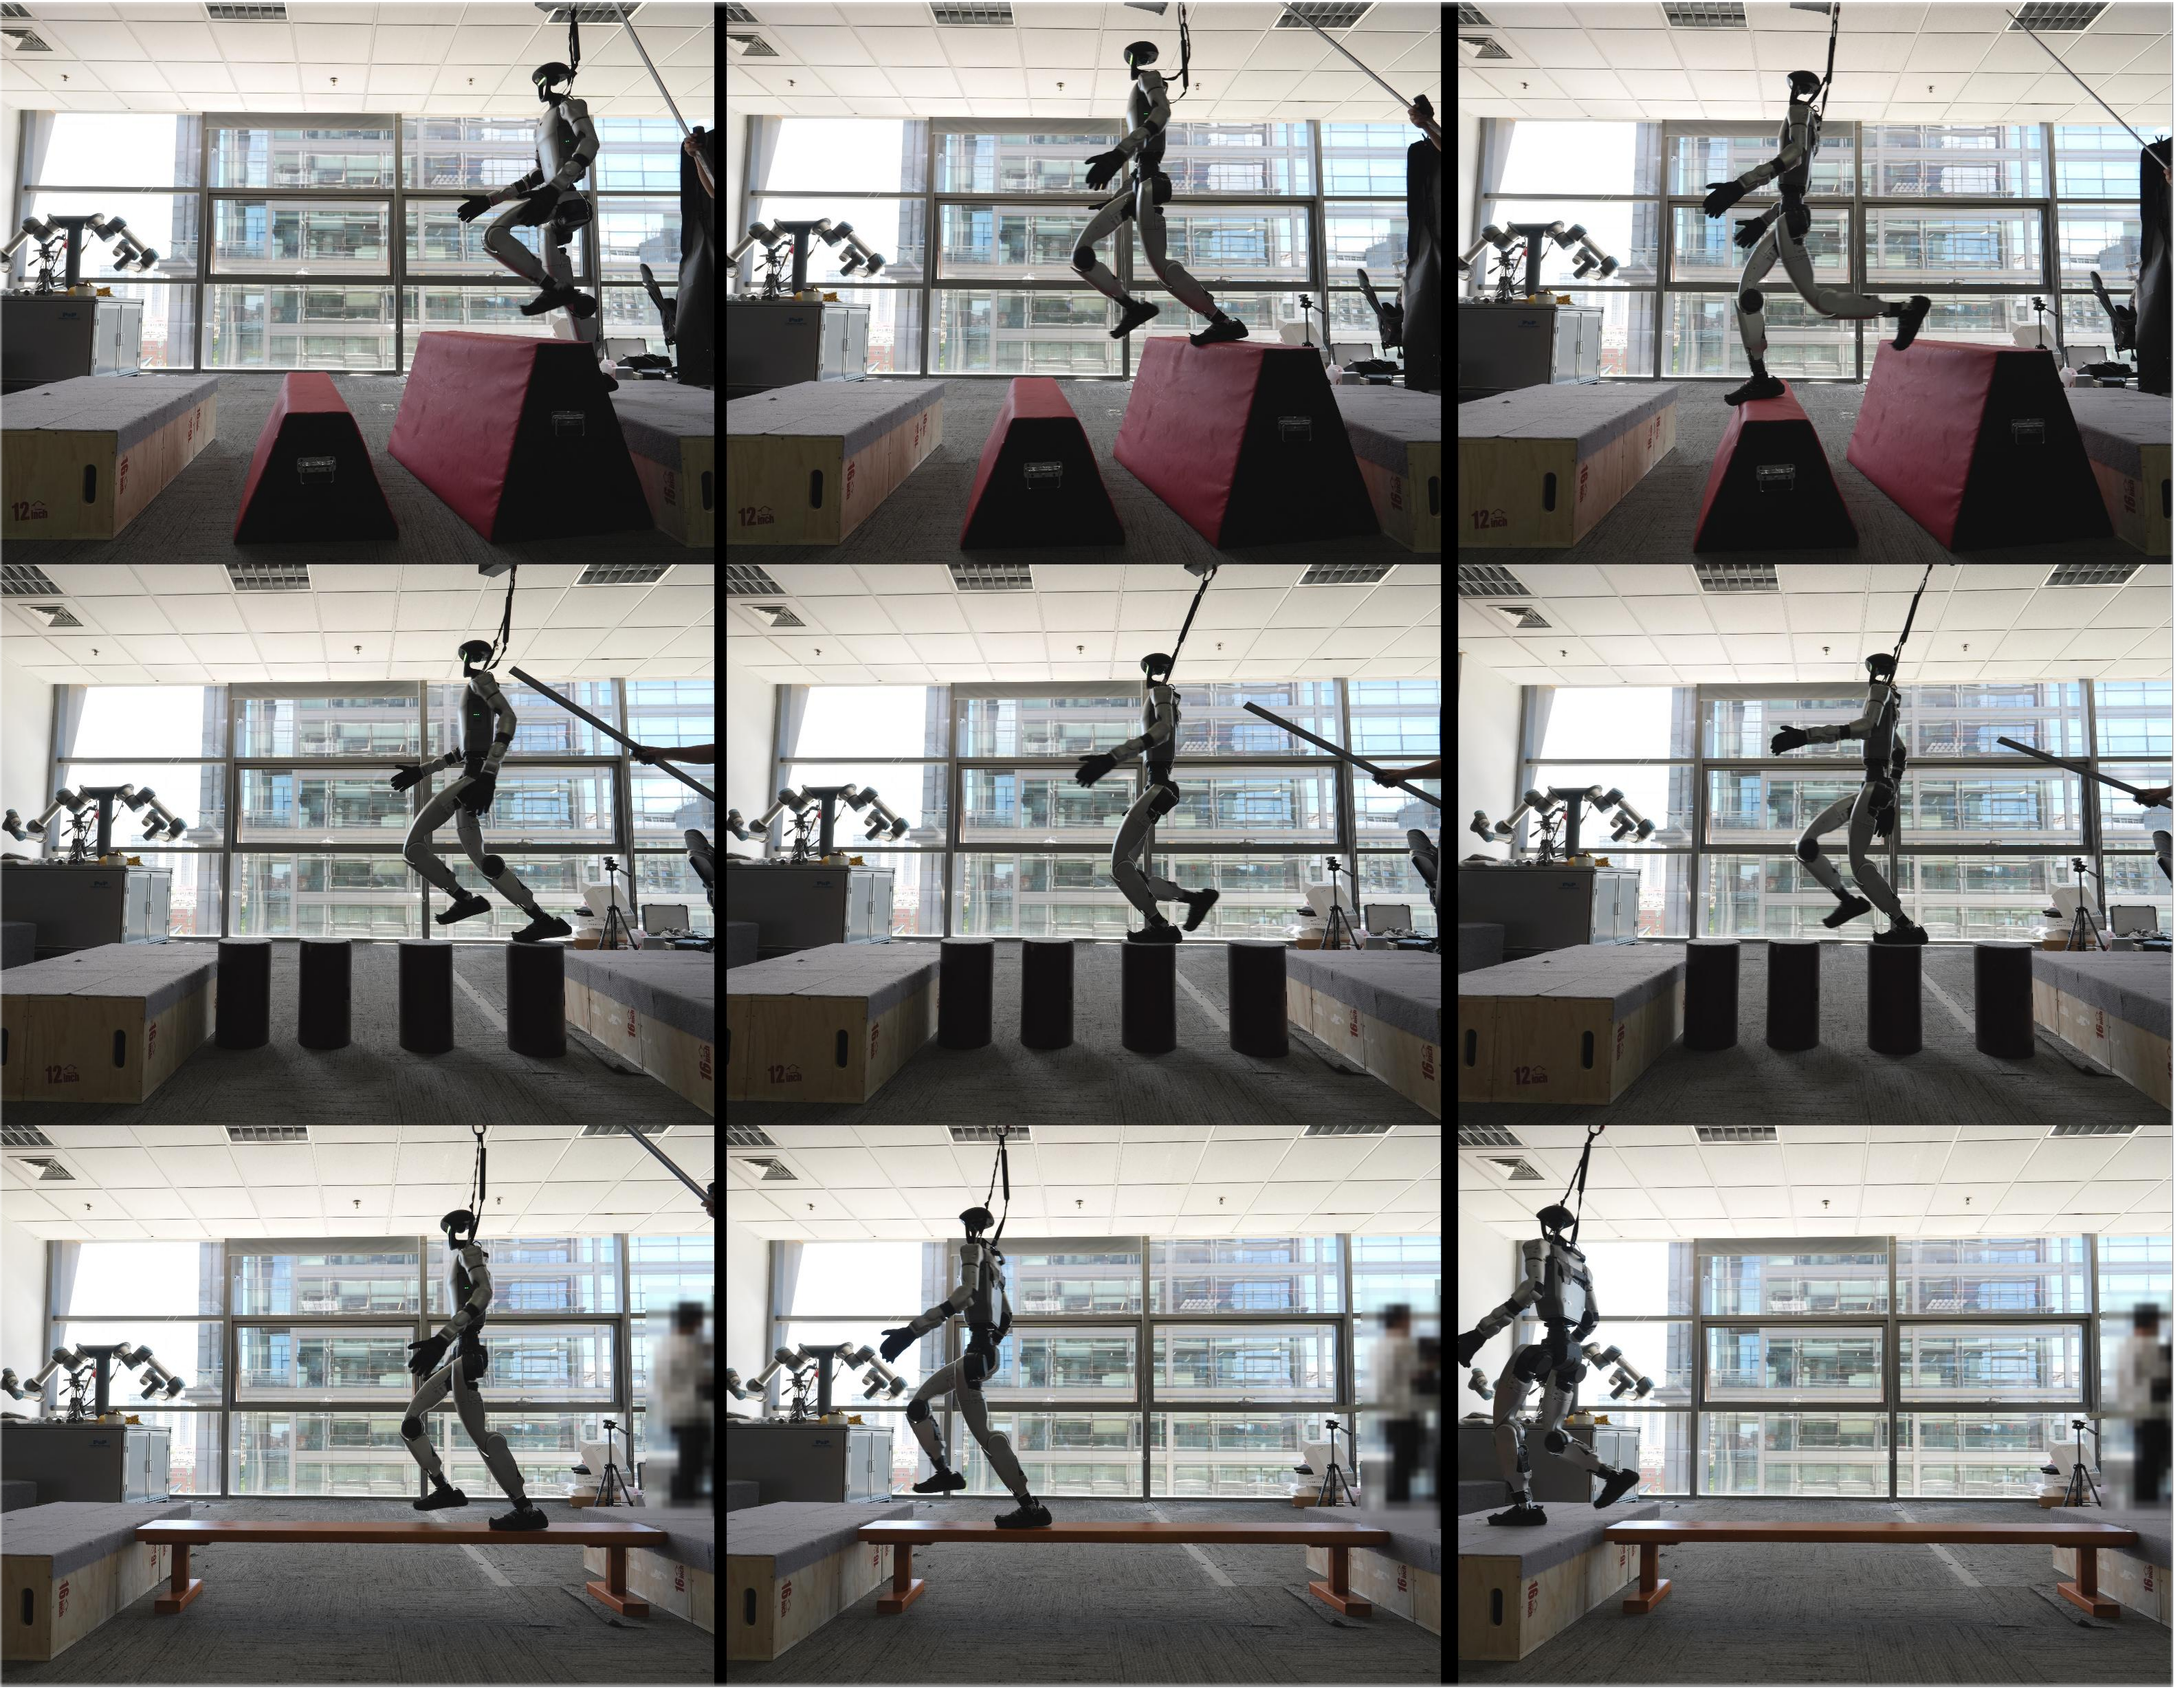
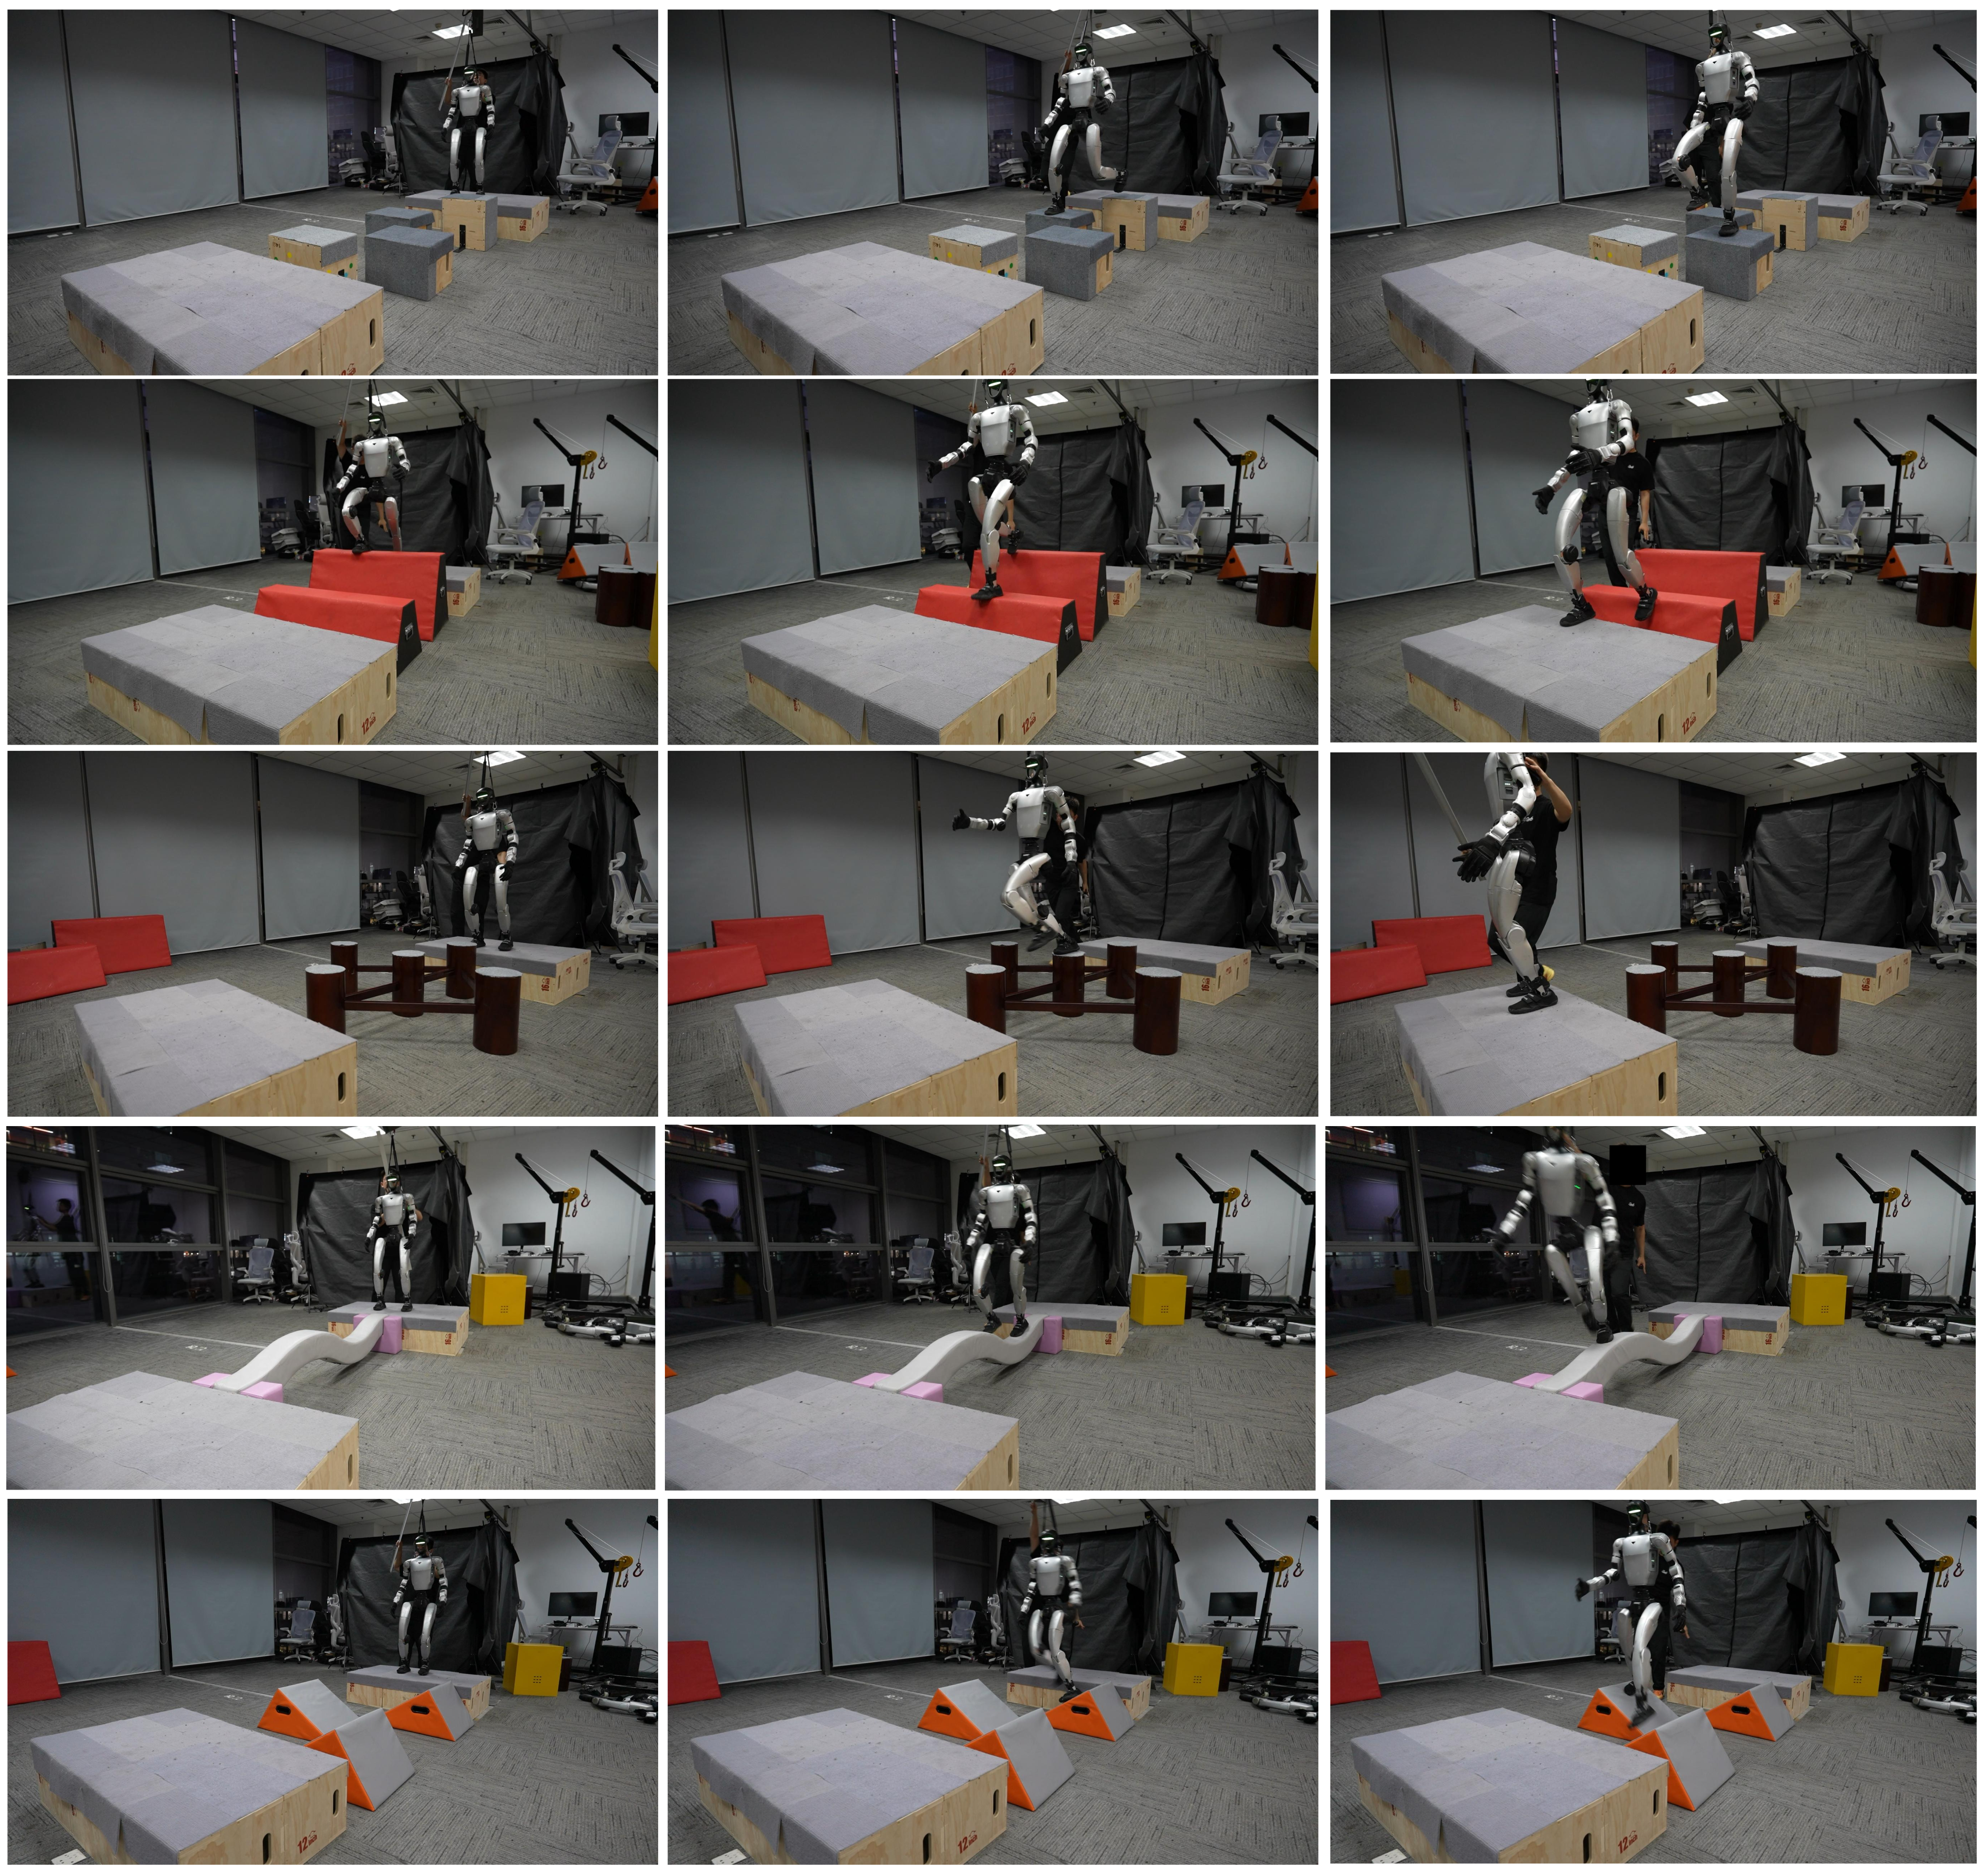
The real-world plot reports high success over the five terrain families, with selected traversal sequences in Figures 1,4 and 9. These show the policy balancing and adjusting foot placement on the indoor apparatus.
Ten trials per setting and selected videos provide evidence of transfer, while leaving uncertainty about longer deployments, unseen layouts, camera failures and broader environments.
6 Conclusion
Saliency-guided short-window features and gait regularization improve the tested humanoid policy. The evidence supports these components within the reported curricula and hardware settings.
The results do not establish general navigation reliability, indefinite terrain memory or safe traversal under arbitrary perception failures.
7 Limitation
Staggered supports can induce poor support-leg choices and cross-stepping. A locally reachable foothold can make the next transition difficult, motivating explicit sequence-level footstep planning.
The camera’s limited field of view also hides upcoming supports during sharp heading changes. Wider or actively controlled perception is proposed future work.
Acknowledgments
The authors thank reviewers, the area chair and Unitree Robotics. Ming-Ju Lee and Zizhuo Wang contributed equally; Hang Zhao and Yiming Li are corresponding authors.
Original project demonstrations
The authors’ project page supplies an overview, full presentation, six one-shot examples and five longer-horizon demonstrations. All 13 original videos and their original posters are preserved locally.
These selected demonstrations supplement the quantitative protocol. They do not provide an independent hardware success-rate estimate or cover all failure cases.
Appendix A Additional Experiments and Analysis
Appendix A adds terrain-wise memory ablations, symmetry illustrations and complete five-terrain hardware snapshot galleries. All original panels and data are retained.
A.1 Ablation Study of Gated Memory
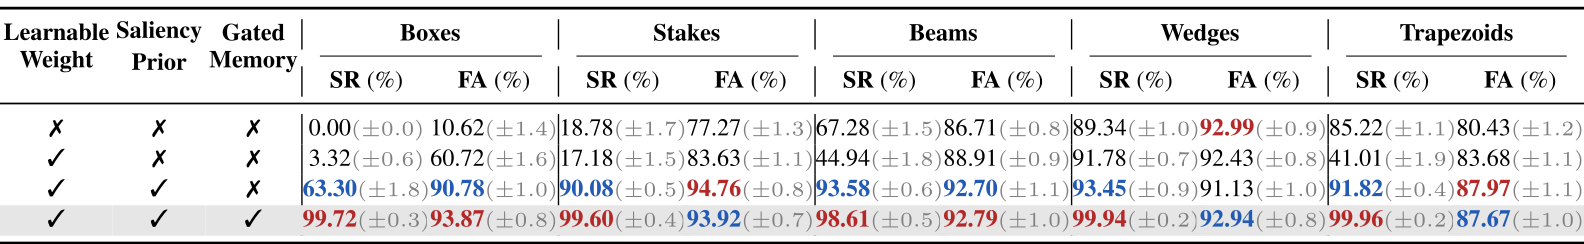
Table 4 expands the memory ablation by terrain. With full fusion, success ranges 98.61–99.96%, averaging about 99.57%, while foothold accuracy averages 92.24%. These differ from Table 2’s 98.27/91.10 and Table 1’s 92.7/83.6; the source gives no reconciliation.
Gated fusion improves success in every displayed terrain, but trapezoid foothold accuracy decreases slightly from 87.97% to 87.67%. The full table preserves every mean, standard deviation and original red/blue ranking.
Accessible table and original citation links
Learnable
Weight
Saliency
Prior
Gated
Memory
Boxes
Stakes
Beams
Wedges
Trapezoids
SR (%)
FA (%)
SR (%)
FA (%)
SR (%)
FA (%)
SR (%)
FA (%)
SR (%)
FA (%)
✗
✗
✗
0.00
10.62
18.78
77.27
67.28
86.71
89.34
92.99
85.22
80.43
✓
✗
✗
3.32
60.72
17.18
83.63
44.94
88.91
91.78
92.43
41.01
83.68
✓
✓
✗
63.30
90.78
90.08
94.76
93.58
92.70
93.45
91.13
91.82
87.97
✓
✓
✓
99.72
93.87
99.60
93.92
98.61
92.79
99.94
92.94
99.96
87.67
A.2 Analysis of Symmetry Regularization
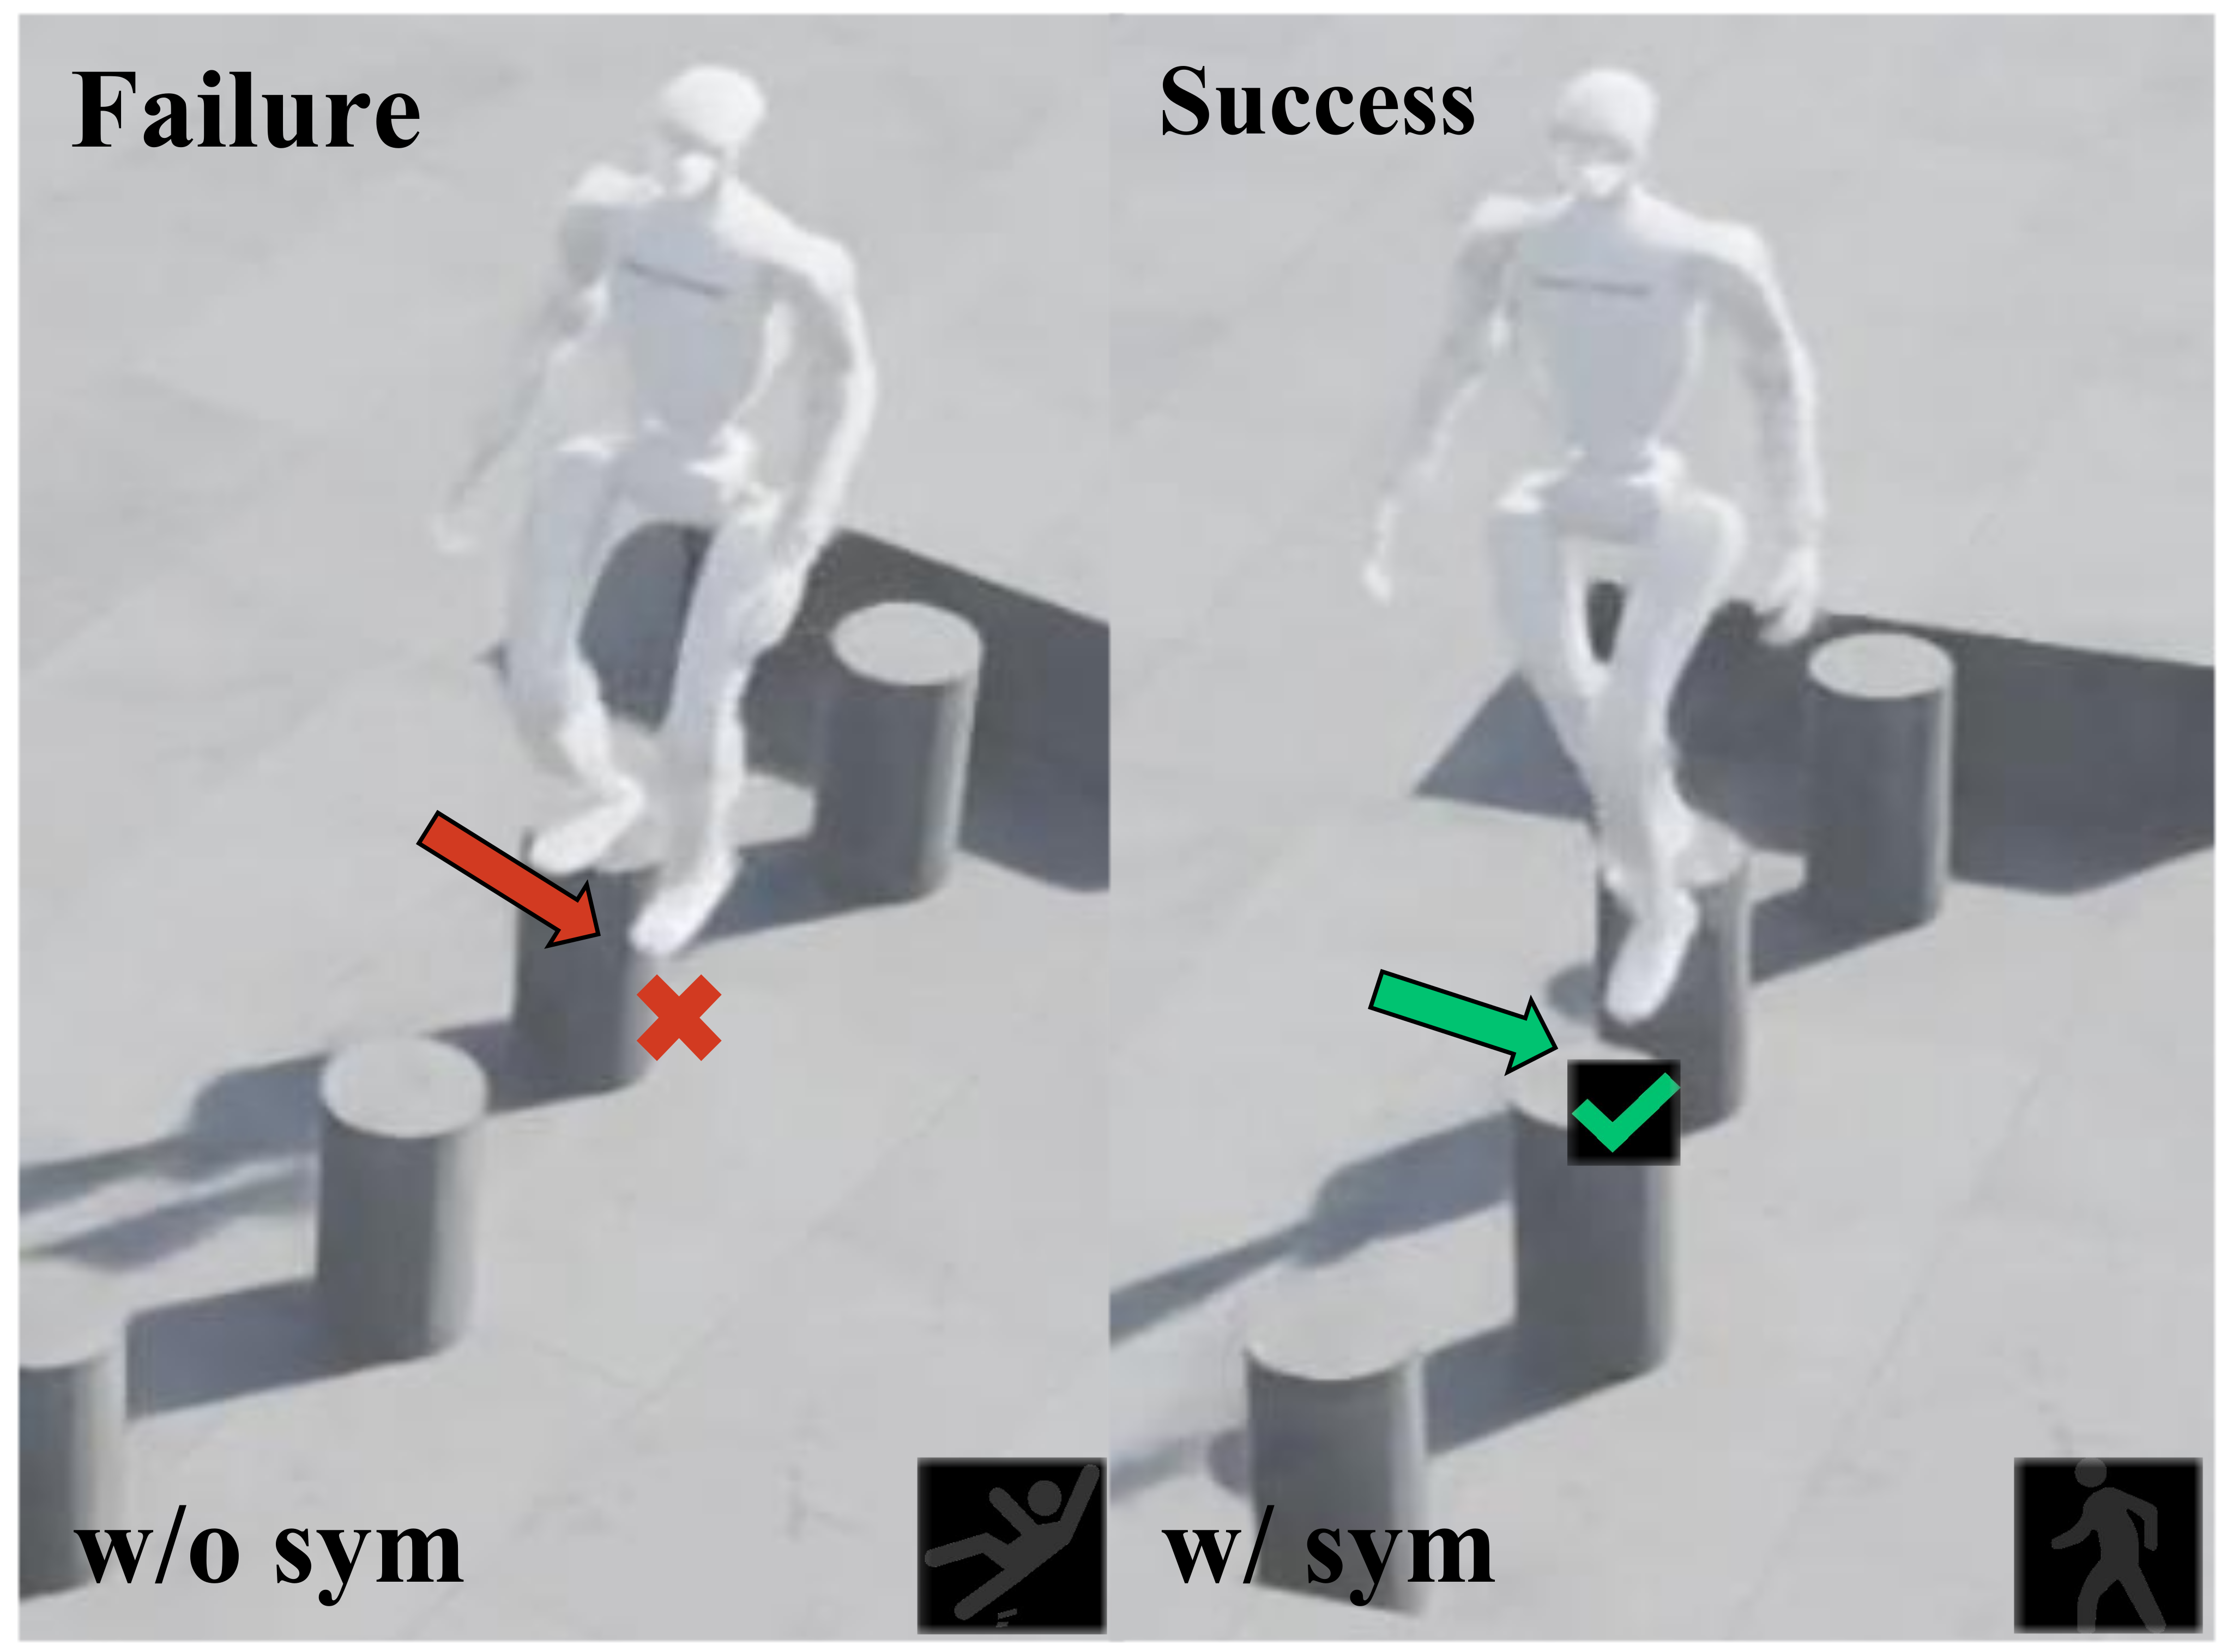
Figure 8 contrasts a failed, poorly coordinated traversal without symmetry regularization against a successful example with it. It illustrates the motivation for avoiding synchronized hops on small supports.
The paired illustration is qualitative. The quantitative evidence comes from the box-terrain comparison and measured contact patterns, rather than an independent count of every gait failure mode.
A.3 Full Real-World Results
Figure 9 retains all fifteen original snapshots across boxes, trapezoids, stakes, beams and wedges. The gallery shows selected support transitions and body adjustments.
It should be read alongside the ten-trial hardware protocol, rather than as an additional estimate of success probability.
Appendix B Implementation Details of Policy Learning
Appendix B preserves the complete evaluation thresholds, observation specifications, reward formulas/weights and optimization settings.
B.1 Simulation Setup and Evaluation Protocol
The appendix restates the 2,048-agent asymmetric PPO setup and five-family 20×10 curriculum. Difficulty changes support spacing, height, size and orientation.
Detailed terrain parameter ranges and a held-out layout split are not specified in this document.
B.2 Evaluation Protocol
The configuration lists a 12-second timeout, a 2 m inward boundary buffer, four-second stagnation termination, 1 N torso-contact threshold, 1 rad tilt threshold and 0.9 m minimum relative root height. All original entries are retained.
The four-second stagnation value conflicts with the main text’s three seconds. Relative root height uses the environment-origin correction defined here; these are episode definitions, rather than runtime safety guarantees.
Accessible table and original citation links
| Condition | Threshold |
| Episode Truncation | |
| Timeout | |
| Terrain boundary | |
| Failure Termination | |
| Starting-platform stagnation | |
| Torso contact | |
| Excessive base tilt | |
| Insufficient root height | |
B.3 Observation Space and Action Interface
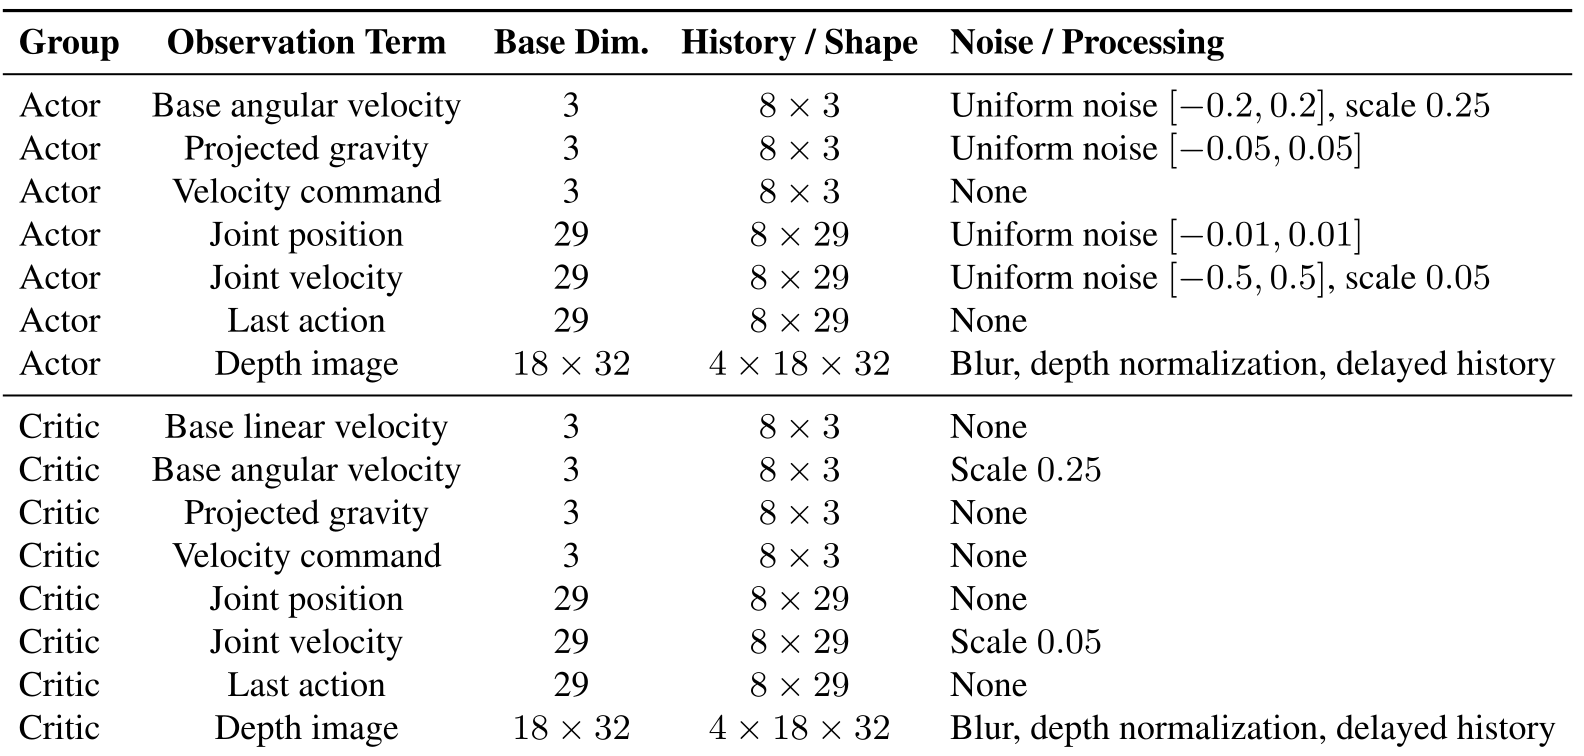
The actor has 96 proprioceptive values per frame, stacked over eight frames for 768 values, plus four 18×32 depth tensors. Joint positions, velocities and actions each have 29 components. Noise ranges and scaling remain in the complete table.
The critic adds privileged base linear velocity and uses clean state, giving 99 values per frame. The actor does not need that privileged velocity measurement at deployment. Blur, depth normalization and delayed history are listed without complete distribution/timing specifications.
Accessible table and original citation links
| Group | Observation Term | Base Dim. | History / Shape | Noise / Processing |
| Actor | Base angular velocity | 3 | Uniform noise , scale | |
| Actor | Projected gravity | 3 | Uniform noise | |
| Actor | Velocity command | 3 | None | |
| Actor | Joint position | 29 | Uniform noise | |
| Actor | Joint velocity | 29 | Uniform noise , scale | |
| Actor | Last action | 29 | None | |
| Actor | Depth image | Blur, depth normalization, delayed history | ||
| Critic | Base linear velocity | 3 | None | |
| Critic | Base angular velocity | 3 | Scale | |
| Critic | Projected gravity | 3 | None | |
| Critic | Velocity command | 3 | None | |
| Critic | Joint position | 29 | None | |
| Critic | Joint velocity | 29 | Scale | |
| Critic | Last action | 29 | None | |
| Critic | Depth image | Blur, depth normalization, delayed history |
B.4 Reward Function
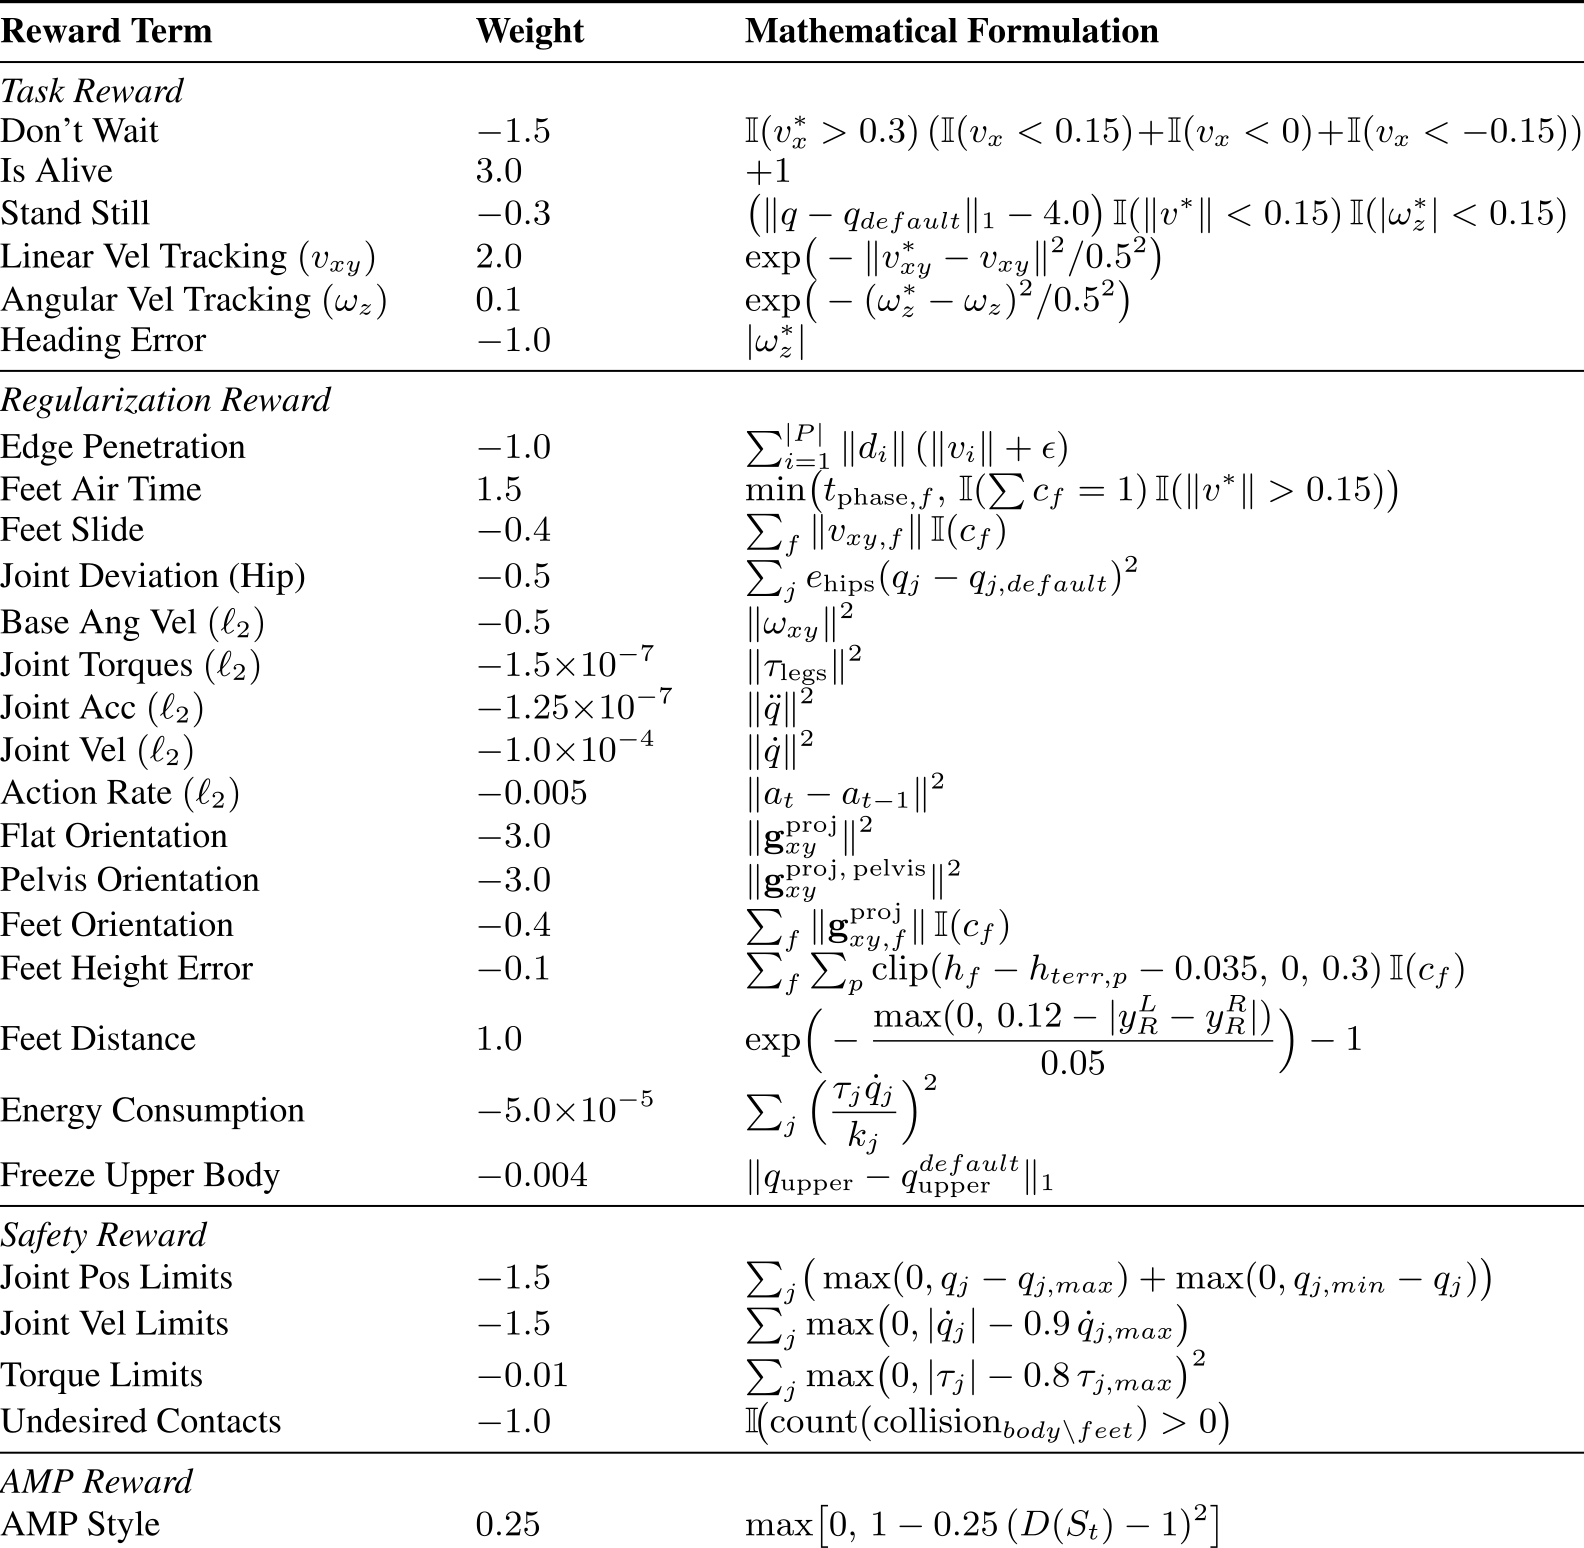
The full reward table retains every task, regularization, joint-limit/contact and motion-prior term. It includes velocity tracking, edge penalties, foot timing/sliding, action rate, energy and an AMP style reward.
The row named “Heading Error” uses commanded yaw-rate magnitude rather than an explicit measured heading discrepancy. Its original label and expression are preserved without silently changing the objective. Reward penalties should not be read as guaranteed constraint enforcement.
Equation
Accessible table and original citation links
| Reward Term | Weight | Mathematical Formulation |
| Task Reward | ||
| Don’t Wait | ||
| Is Alive | ||
| Stand Still | ||
| Linear Vel Tracking | ||
| Angular Vel Tracking | ||
| Heading Error | ||
| Regularization Reward | ||
| Edge Penetration | ||
| Feet Air Time | ||
| Feet Slide | ||
| Joint Deviation (Hip) | ||
| Base Ang Vel | ||
| Joint Torques | ||
| Joint Acc | ||
| Joint Vel | ||
| Action Rate | ||
| Flat Orientation | ||
| Pelvis Orientation | ||
| Feet Orientation | ||
| Feet Height Error | ||
| Feet Distance | ||
| Energy Consumption | ||
| Freeze Upper Body | ||
| Safety Reward | ||
| Joint Pos Limits | ||
| Joint Vel Limits | ||
| Torque Limits | ||
| Undesired Contacts | ||
| AMP Reward | ||
| AMP Style | ||
B.5 Training Details
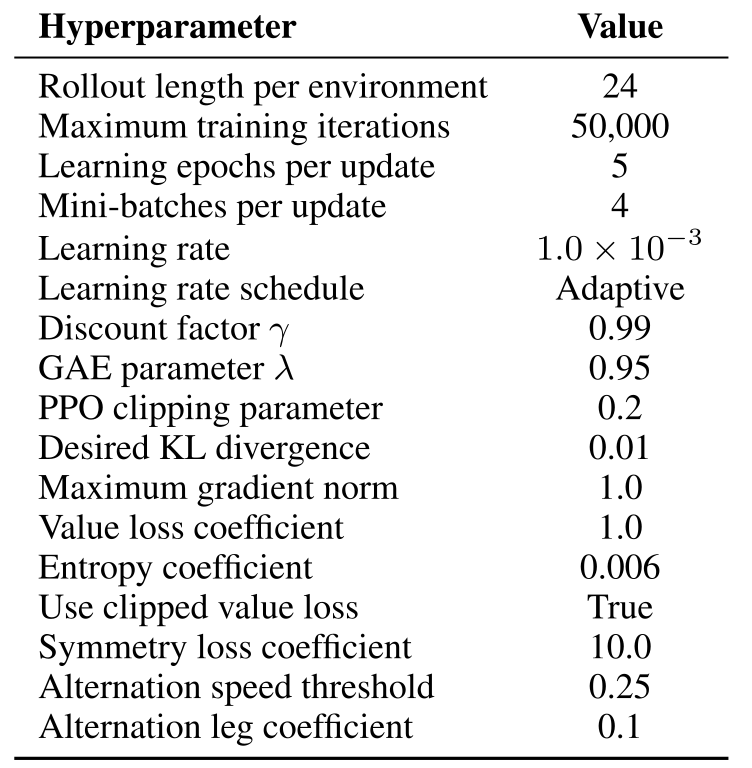
Each update collects 24 steps from 2,048 environments, or 49,152 transitions. PPO uses five epochs, four minibatches, learning rate 10⁻³ with an adaptive schedule, discount 0.99, GAE 0.95, clip 0.2 and desired KL 0.01; the maximum is 50,000 iterations.
Mirror-loss weight is 10.0, alternation weight 0.1 and alternation speed threshold 0.25. The complete table includes entropy/value weights and gradient clipping. A maximum iteration count is not a reported wall-clock training duration.
Accessible table and original citation links
| Hyperparameter | Value |
| Rollout length per environment | 24 |
| Maximum training iterations | 50,000 |
| Learning epochs per update | 5 |
| Mini-batches per update | 4 |
| Learning rate | |
| Learning rate schedule | Adaptive |
| Discount factor | 0.99 |
| GAE parameter | 0.95 |
| PPO clipping parameter | 0.2 |
| Desired KL divergence | 0.01 |
| Maximum gradient norm | 1.0 |
| Value loss coefficient | 1.0 |
| Entropy coefficient | 0.006 |
| Use clipped value loss | True |
| Symmetry loss coefficient | 10.0 |
| Alternation speed threshold | 0.25 |
| Alternation leg coefficient | 0.1 |