Overview
Success-conditioned constrained reinforcement learning for docking: preventing policies from hovering near a goal to avoid constraint penalties, with complete theory, pseudocode, figures and ablations.
At a glance
Termination-based constraint learning can reward safe-looking inactivity when approaching a goal activates constraints and shortens future return. SCoCaT adds a success-value critic whose targets ignore those artificial terminations, then combines its advantage with the original reward advantage. Simulated planar and six-degree-of-freedom docking improve over CaT, with a measurable compliance tradeoff; four physical runs per method demonstrate limited zero-shot transfer. The method learns constraint-aware behavior but does not supply a deployment-time safety certificate.
1 Introduction
Constraints as Terminations (CaT) reduces future reward through violation-dependent survival probabilities, leaving a policy-network forward pass at deployment. Near a terminal goal, this can favor hovering just outside the active-constraint corridor. SCoCaT gives in-tolerance states a separate success signal, inspired by Direct Behavior Specification, and trains that value stream using only environment endings. This preserves CaT’s reward stream while adding an incentive to enter and remain at the goal. The spacecraft motivation is constrained onboard computation; the experiments do not establish that all model-predictive or barrier controllers are infeasible on all flight hardware.
Contributions.
The contributions are a stylized analysis of hovering, a two-critic PPO implementation and docking experiments on simulated planar/6-DoF vehicles plus an air-bearing testbed. The theoretical claims depend on reward, survival and horizon assumptions; empirical compliance is separate from formal safety.
2 Related Work
Related work contrasts primal-dual constraint penalties, early-termination reformulations, safety-budget state augmentation and gradient projection. CaT’s prior locomotion evaluations emphasize continuing dense-reward tasks. SCoCaT adapts success bootstrapping from an off-policy Lagrangian approach to on-policy termination-based learning. Separate critics change the success target’s continuation rule; they do not automatically guarantee the combined policy satisfies every constraint.
Reinforcement learning for spacecraft proximity operations.
Prior spacecraft RL demonstrates docking/proximity control, while runtime assurance and barrier methods supply external constraint handling at added online computation. Air-bearing platforms and UAVs are established terrestrial analogues. This paper evaluates internalized constraints through simulated spacecraft and a planar air-bearing deployment; orbital flight and broad cross-embodiment validation remain outside its evidence.
3 Methodology
The formulation bounds discounted occupancy of individual constraint violations. CaT converts these constraints into a modified survival-weighted objective. Such a surrogate and observed violation rates are distinct from proving that the trained neural policy satisfies the original chance constraints.
Equation 1
| (1) |
3.1 Problem Formulaton
Feasibility collapse means concentrating near the goal boundary while rarely entering the goal. Proposition 1’s zero-reward absorbing goal makes hovering preferable under any discounted objective; its proof does not require CaT’s goal-entry penalty. The specifically CaT-dependent case is Proposition 1b: a rewarding, non-absorbing goal becomes less valuable when repeated survival discount suppresses its return. The three-state model isolates a possible mechanism, not a complete proof that every docking failure has this cause.
3.2 Constraints as Terminations
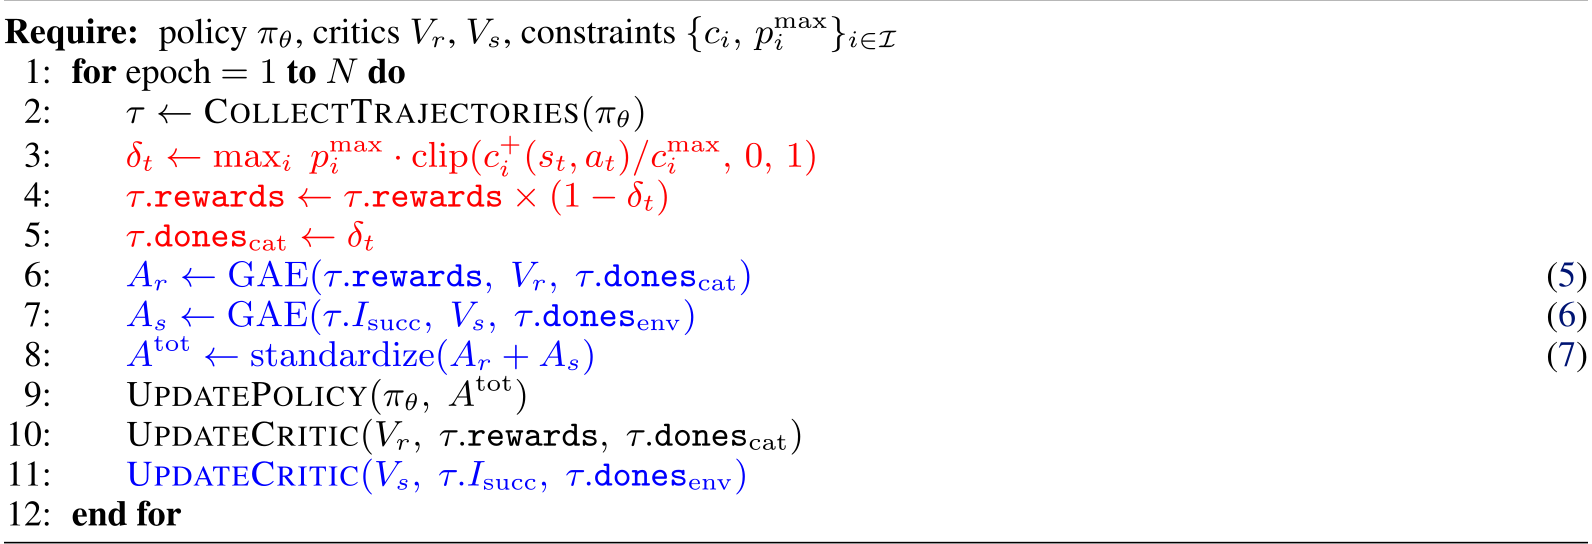
Each constraint produces a clipped violation magnitude scaled by its severity; the largest sets the step’s termination probability. CaT weights the future reward by survival. The actual pseudocode additionally scales the current reward by one minus that probability. Hard constraints reset immediately; softer violations reduce effective return without adding an online safety optimizer.
Equation 2
| (2) |
3.3 Success-Conditioned Constraints as Terminations (SCoCaT)
A per-step binary success indicator requires position, orientation, linear-velocity and angular-velocity tolerances simultaneously. It supplies credit before an entire 100-step hold is completed, but remains sparse outside the narrow corridor. A continuous alternative gives smoothly increasing pose credit and a near-goal velocity penalty. It helps sparse-reward exploration but changes the practical tradeoff. The original indicator formulas are retained.
Equations 3–4
| (3) |
| (4) |
Dual advantage streams.
The reward critic uses CaT-modified continuation, while the success critic bootstraps through artificial CaT terminations and stops only at environment endings. Two GAE streams therefore estimate different returns. Feeding CaT termination into both would damp success values precisely where goal approach activates constraints. This separation is the central mechanism, rather than simply appending a success bonus to the original reward.
Equations 5–6
| (5) | ||||
| (6) |
Advantage scalarization.
The implementation sums reward and success advantages, then standardizes their sum per batch. It does not independently normalize each stream, so their relative scale still matters: reward is multiplied by 0.1 while success is not. The stylized result removes the hover optimum when success value exceeds the lost hover return. Equal scalarization introduces no new weight in this implementation, but it is not invariant to arbitrary reward scaling or a guarantee of neural PPO convergence. The complete colored algorithm is preserved in native PDF form.
Equations 7–8
| (7) |
| (8) |
3.4 Implementation Details
Implementation separates training success signals, evaluation metrics and constraint severity. These definitions are essential to interpreting the reported gains.
Task definition.
Training requires 100 consecutive in-tolerance steps, with 10 mm position tolerance and orientation tolerance 2° on the planar platform or 10° on CubeSat. Evaluation relaxes planar orientation to 0.1 rad and tightens linear velocity from 0.05 to 0.01 m/s; angular velocity remains below 5°/s. Entry means ever reaching the pose corridor; TCR means occupying it for at least 10% of an episode, without requiring consecutive steps; GCO is time occupancy. Hold requires 100 consecutive pose-corridor steps, while declared success additionally applies the terminal velocity gate. TCR is therefore a dwell diagnostic, not the declared success criterion. Final errors marked with a star condition on corridor entry and omit failed-to-enter episodes. Constraint severity distinguishes hard bounds/collision, hardware-related limits and softer preferences.
4 Experiments
Both platforms use eight binary thrusters; CubeSat’s oblique corner thrusters require coordinated actuation for translations and rotations. Five training seeds share Isaac Lab/PPO infrastructure and a 50,000-step tolerance curriculum. Comparisons include unconstrained PPO, CaT with/without curriculum, success-bonus variants and a gradient-projection sibling. Unconstrained PPO is a reference tradeoff, not a mathematical upper bound on achievable success. Only the planar platform is tested physically.
4.1 Simulation Results
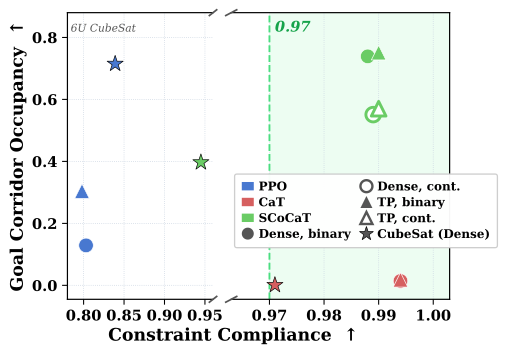
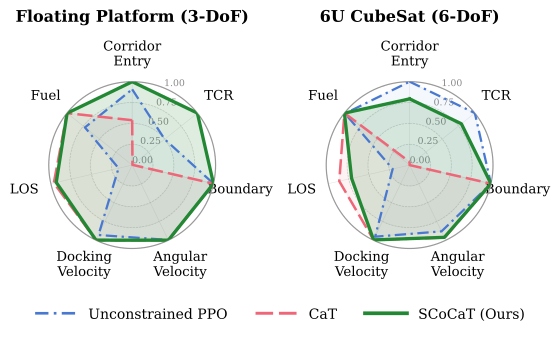
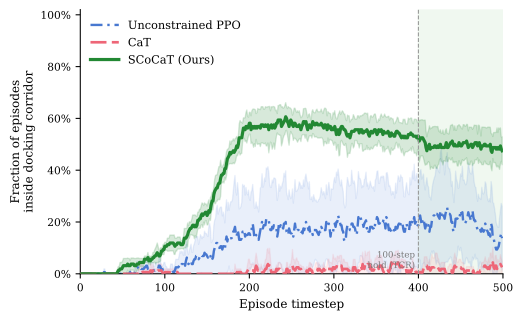
On the planar simulation, dense-reward SCoCaT reaches 90.6±6.6% declared success, versus zero for PPO and CaT, with 98.8% aggregate compliance versus CaT’s 99.4%. The headline 250-fold increase compares TCR 1.000 to 0.004, not declared docking success. On CubeSat, SCoCaT’s 61.3% declared success exceeds CaT’s zero but falls below PPO’s 93.1%; compliance is 94.5%, versus 97.1% and 83.9%. Seeds are highly variable. Dense/terminal-proximity planar rewards perform similarly, but binary success fails with sparse terminal reward; continuous success partly recovers it. Adding success directly as a reward bonus raises dwell while worsening constraint violations. High CaT compliance can reflect avoiding the corridor rather than successful controlled docking.
Sim-to-Real Transfer on Floating Platform Testbed.
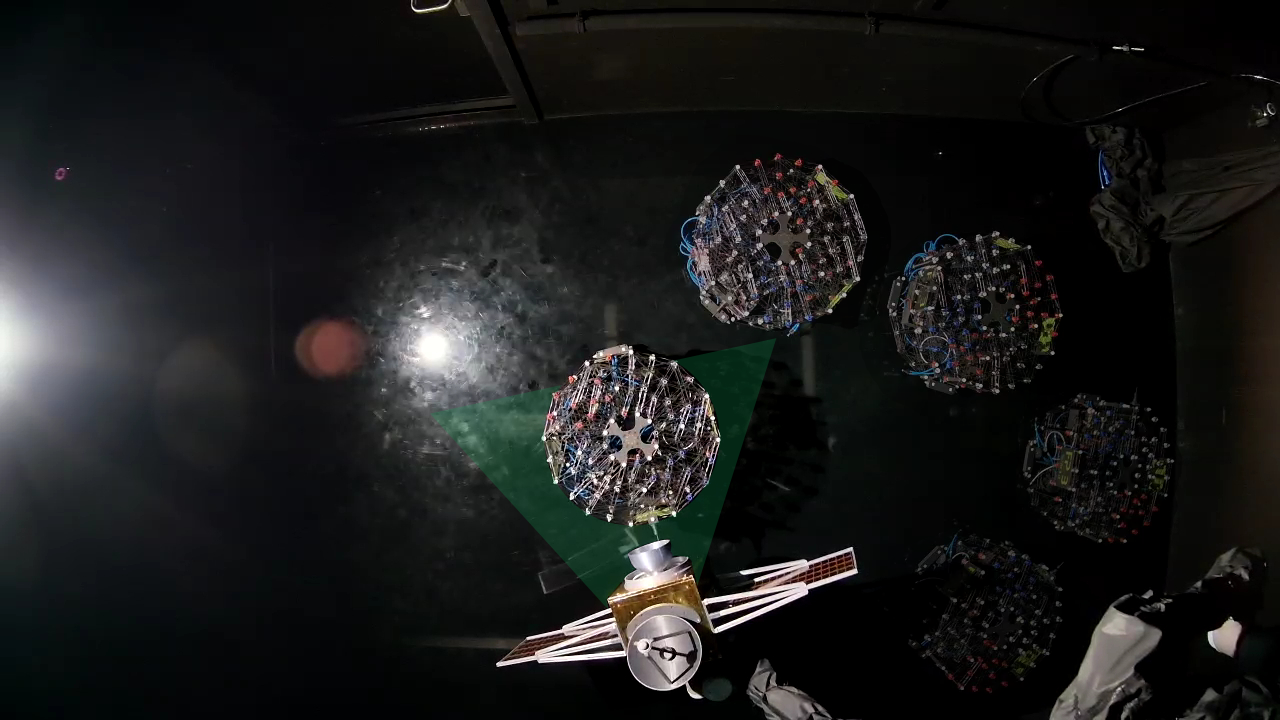
Policies trained with terminal-proximity reward transfer without hardware fine-tuning to an OptiTrack-observed air-bearing platform with 5 Hz binary thrusters. Training randomizes mass by ±0.15 kg and applies constant disturbance force/torque magnitudes up to 0.2 N/0.2 Nm. Hardware scoring is pose-only at 10 mm/0.1 rad: PPO succeeds 4/4, CaT 0/4 and SCoCaT 3/4. SCoCaT reduces several violations versus PPO, but angular velocity is not a pass/fail gate. The CaT-versus-SCoCaT comparison has reported Fisher p=0.14; four runs per method support feasibility, not a powered superiority claim or the full simulation success criterion. Figure 2’s right panel is simulation occupancy, not a hardware learning curve.
5 Conclusion
Decoupling success continuation from artificial constraint termination substantially improves docking engagement over CaT in these experiments. The planar simulation meets the declared criterion reliably, while CubeSat retains a safety/success and seed-stability tradeoff. Physical transfer demonstrates feasibility under pose-only scoring; it does not establish orbital readiness or certified constraint satisfaction.
6 Limitations
Limitations include mission-dependent scalarization/severity choices, PPO-only implementation, a systematic angular-velocity sim-to-real gap, CubeSat compliance loss and bimodal seeds, and no observation-noise randomization. Hardware testing has four runs per method and omits velocity from its success criterion. Generalization beyond the two docking embodiments remains untested. The CubeSat aggregate compliance gap is mainly line-of-sight, but the original table also shows a small angular-rate difference, so “entirely” line-of-sight is stronger than the tabulated values.
Acknowledgments
The authors acknowledge European Union grant 101161690 for the Ice2Thrust (S4I2T) project and reviewer/area-chair feedback.
Appendix A Proofs
The proofs compare stylized hover and goal-reaching returns. They clarify which assumptions yield a CaT-specific pathology and how success-value scaling changes the preference. Original formulas remain available, including a survival-indexing inconsistency noted below.
Proof of Proposition 1
Proposition 1 compares a positive-reward hover state with an absorbing goal that yields no future reward. Hover dominance in that model follows from giving up the remaining reward horizon.
Setup.
The three states are far, just outside the goal and inside the goal. The outside state has reward R and zero artificial termination; the absorbing goal has zero reward. These assumptions deliberately simplify docking dynamics and exploration.
Value of the hover policy.
Hovering forever collects the geometric discounted sum R/(1−gamma), because no constraint termination applies there. This establishes the reference value used in both propositions.
Equation 9
| (9) |
Value of any goal-entering policy.
Entering the absorbing goal at any finite step truncates the positive hover-reward series, producing strictly smaller return. This proves the stated toy-model preference, but the entry constraint itself is unnecessary for this particular argument.
Equation 10
| (10) |
Scope of the argument, and the role of condition (ii).
Proposition 1b instead gives a non-absorbing goal positive reward. Under the appendix’s survival convention, hovering wins when R exceeds kappa times goal reward, with kappa about 0.023 at gamma=0.99 and termination probability 0.3. The source’s Equation 12 writes a series beginning at t=0 with factor (1−delta)^t, but its closed form includes an extra leading (1−delta). Equation 2 likewise begins survival before the current step, whereas Algorithm 1 scales current reward. The original equations are preserved; their off-by-one convention is not silently repaired. The qualitative conclusion that repeated survival discount suppresses goal value remains distinct from this exact threshold convention.
Equations 11–12
| (11) |
| (12) |
Proof of Proposition 2
The second proof adds a success return that continues independently of CaT’s artificial termination. It compares goal-reaching-and-staying behavior with hovering, under its stated value and horizon assumptions.
Setup.
Define the combined objective as CaT reward return plus an environment-terminated success return. In the idealized infinite-horizon comparison, the successful policy remains in the goal and receives one success unit per step. Actual reset-after-hold behavior is handled separately by the finite-horizon refinement.
Objective comparison.
Hovering receives no success return; reaching the goal at step k adds a discounted success stream. Under the binary infinite-horizon model, the difference is positive when the scaled hover reward R is below one. This is a conditional comparison of policies, not a statement that an untrained critic immediately supplies that value.
Equations 13–15
| (13) | ||||
| (14) |
| (15) |
The threshold on R , in three forms.
The stated thresholds are R<1 for binary infinite-horizon success, R<0.67 using the claimed in-tolerance continuous-signal floor, and about R<0.64 for a 598-step horizon with a 100-step hold. Reward scaling gives R≤0.099 or 0.198 for the two dense configurations, while success stays unscaled. The appendix checks these sufficient bounds; the continuous floor depends on the specified smoothing/tolerance assumptions, and the separate refinements should not be read as an exhaustive theorem for arbitrary rewards or critic errors.
Equation 16
| (16) |
Local optimality.
The proof mixes an arbitrarily small amount of a better goal-reaching policy into the hover policy to argue hover is not a local optimum of the idealized objective. This policy-space reasoning does not establish convergence of a parameterized, finite-sample PPO implementation.
Advantage interpretation.
The advantage interpretation separates lost hover reward from discounted success value. Goal entry becomes favorable once the success estimate exceeds the hover-value threshold. Using CaT endings in the success critic could reduce that estimate and restore the failure. The claimed value convergence is part of the stylized argument, not a general monotonicity guarantee for nonlinear critic training.
Equations 17–18
| (17) | ||||
| (18) |
Appendix B Reward Bonus vs. Two-Critic: Why They Differ
A success bonus and a separate success critic have different continuation semantics. Dense planar bonus variants attain high occupancy but worsen docking-velocity violations from 0.001 to 0.037 and line-of-sight violations from 0.066 to 0.826 compared with SCoCaT. These measured differences motivate the separate critic, without proving all scalarizations preserve constraints.
Bellman decomposition.
An additive bonus inserted after current-reward survival scaling is still bootstrapped using CaT termination. Its value decomposes into the CaT reward value and a survival-damped success value. SCoCaT’s success critic instead uses environment-only continuation, so the fixed-point targets differ.
Equations 19–20
| (19) |
| (20) |
Why constraint compliance degrades.
The bonus competes with constraint pressure inside a single reward/value stream, and the ablation shows substantially worse compliance. The prose says the bonus can fire despite excessive velocity, but the binary indicator defined in Equation 3 explicitly gates on velocity; that explanation is internally inconsistent if the same indicator is used. The empirical result is retained without treating that sentence as a verified implementation detail.
Equation 21
| (21) |
Why the two-critic formulation preserves constraint compliance.
The two-critic formulation leaves the reward advantage’s CaT penalty intact and adds a success advantage with different continuation. Binary success additionally requires velocity tolerance. This structural separation explains the intended mechanism, but the combined policy gradient can still trade objectives; the reported nonzero violation rates are evidence against reading “preserves compliance” as an unconditional guarantee.
Appendix C Training Details
Episodes start 0.01–4 m from a randomly positioned goal, at zero linear/angular velocity. Planar heading spans 0–180°; CubeSat yaw spans 0–180° and pitch/roll 0–90° independently. The goal lies within 2 m of the origin. These training distributions define the reported generalization envelope.
C.1 Constraints
Table 3 retains all constraint thresholds and severity values. Hard bounds and planar collision reset immediately. Docking-speed limits apply within 0.5 m: 0.05 m/s planar and 0.1 m/s CubeSat, distinct from the stricter success gates. Angular thresholds/severities also differ by platform, despite the main text’s broad “same values” description. Fuel and line-of-sight remain softer terms. The curriculum raises medium/soft severities from 0.05 to 0.125 over an episode; that is a separate baseline configuration.
Sensitivity Analysis for p i max .
The three-seed severity sweep reduces fuel violations from roughly 63% to 3% and keeps docking-speed violations near/below 1.1%, while line-of-sight remains above 84%. However, line-of-sight severity is not swept, and this earlier constraint implementation predates the paper’s later speed definition; its absolute rates are not comparable to the main table’s 0.066 line-of-sight value. The sweep demonstrates nonuniform response, not that simply increasing line-of-sight severity was tested and failed.
| Regime | Eff. (dock / ang / fuel) | Dock.Vel. | Fuel | LoS |
|---|---|---|---|---|
| Soft | 0.075 / 0.05 / 0.025 | |||
| Mid | 0.30 / 0.20 / 0.10 | |||
| Hard | 1.0 / 1.0 / 1.0 |
| Threshold | ||||||
| ID | Constraint | FP | CS | FP | CS | Definition |
| Out-of-bounds | Exits workspace boundary. | |||||
| Collision | – | – | Contact force with target. | |||
| Docking velocity | Linear speed within of port. | |||||
| Angular velocity | Body angular rate during approach. | |||||
| Fuel consumption | -norm of thrust commands per step. | |||||
| Line of sight | Heading deviation from port direction. | |||||
| Hard (): immediate reset. Medium: hardware-critical. Soft: operational preference. | ||||||
C.2 Observations
Observations include body-frame velocities, relative goal information and the previous action. Planar angles use sine/cosine pairs; CubeSat orientation uses the first two columns of a rotation matrix. Table 4’s base state dimensions are eight and fifteen before the separately concatenated previous action. State estimation comes from simulation or motion capture; degraded-observation robustness is untested.
C.3 Hyperparameters
Policy, reward critic and success critic have independent weights, each with two 64-unit ELU hidden layers. The policy is multi-categorical for binary thrusters; critics are deterministic regressors. Training uses 4,096 environments, 32-step rollouts, eight learning epochs, gamma 0.99, GAE lambda 0.95 and reward scale 0.1. The complete table retains PPO clipping, adaptive learning-rate and normalization choices, including no time-limit bootstrap.
| Hyperparameter | Value |
|---|---|
| Rollouts per update | 32 |
| Number of environments | 4,096 |
| Learning epochs per update | 8 |
| Mini-batches per epoch | 8 |
| Discount factor | |
| GAE | 0.95 |
| Optimiser | Adam |
| Learning rate | |
| LR scheduler | KLAdaptiveLR |
| KL target threshold | 0.008 |
| KL factor (halve/double) | 2.0 |
| LR factor | 1.5 |
| Gradient norm clip | 1.0 |
| : ratio clip | 0.2 |
| : value clip | 0.2 |
| Clip predicted values | True |
| : entropy scale | 0.0 |
| scale | 2.0 |
| KL early-stop threshold | 0 (disabled) |
| State pre-processor | RunningStandardScaler |
| clip threshold | 5.0 |
| Value pre-processor | RunningStandardScaler |
| Reward shaper scale | 0.1 |
| Random exploration steps | 0 |
| Time-limit bootstrap | False |
C.4 Reward Formulations
Terminal-proximity reward is smooth in final pose but emitted only at episode end; sparse reward is a terminal binary pose test. Dense reward includes pose attraction, progress, boundary and velocity terms and can be negative. Although the prose says safety enters exclusively through terminations, these dense boundary/velocity penalties overlap safety-related quantities. All exact formulas remain in Table 6; the practical objective should be read from those formulas.
| Reward | Notes | |
|---|---|---|
| Terminal-proximity |
Dense signal
at episode-end | |
| Dense |
|
Every-step |
| Sparse | Terminal; binary |
Appendix D Full Ablation Study: Floating Platform (3-DoF)
The full planar tables show all reward/success-signal/bonus/projection combinations. Dense SCoCaT achieves near-unit entry/TCR and GCO 0.739, but declared success is 0.906 in Table 7. Sparse binary success fails to bootstrap; continuous success reaches TCR 0.492 with standard deviation 0.473. Bonus variants often improve occupancy or conditional final error while degrading compliance. Conditional error metrics exclude non-entering runs, and high-variance sparse results should not be read as reliable docking.
| Method | TCR | Hold | Decl. | Compl. |
|---|---|---|---|---|
| PPO | 0.488 | 0.011 | ||
| CaT | 0.008 | |||
| SCoCaT | 0.001 | 0.066 | 0.066 | 0.002 |
| Method | Ent. | TCR | GCO | Pos.∗ (mm) | Hdg.∗ (∘) | Dwell∗ (mm) | App. (m/s) |
|---|---|---|---|---|---|---|---|
| PPO | 0.154 | 0.488 | 0.123 | 19.7 | 0.074 | 18.5 | 0.019 |
| PPO (TP) | 0.003 | 0.053 | 1.5 | 0.044 | 1.3 | 0.004 | |
| PPO (sparse) | – | – | – | – | |||
| CaT | 0.374 | 0.008 | 0.015 | 12.2 | 0.107 | 9.2 | 0.003 |
| CaT (TP) | 0.155 | 0.006 | 0.009 | 4.3 | 0.069 | 4.3 | 0.003 |
| CaT+Curr | 0.214 | 0.003 | 19.4 | 0.293 | 3.9 | 0.006 | |
| CaT+Curr (TP) | 0.297 | 0.005 | 4.3 | 0.089 | 1.5 | 0.005 | |
| CaT+Curr (sparse) | – | – | – | – | |||
| SCoCaT | 0.001 | 0.001 | 0.014 | 0.5 | 0.025 | 0.5 | 0.004 |
| SCoCaT (cont.) | 0.001 | 0.001 | 0.052 | 0.9 | 0.029 | 0.8 | 0.003 |
| SCoCaT (TP) | 0.001 | 0.001 | 0.006 | 0.4 | 0.039 | 0.4 | 0.004 |
| SCoCaT (TP, cont.) | 0.001 | 0.001 | 0.041 | 0.5 | 0.026 | 0.5 | 0.003 |
| SCoCaT (sparse) | – | – | – | – | |||
| SCoCaT (sparse, cont.) | 0.474 | 0.473 | 0.262 | 2.8 | 0.346 | 2.2 | 0.010 |
| SCoCaT-bonus | 0.005 | 0.3 | 0.015 | 0.3 | 0.004 | ||
| SCoCaT-bonus (cont.) | 0.008 | 0.2 | 0.020 | 0.2 | 0.004 | ||
| SCoCaT-bonus (TP) | 0.001 | 0.001 | 0.009 | 0.2 | 0.007 | 0.1 | 0.004 |
| SCoCaT-bonus (TP, cont.) | 0.021 | 0.3 | 0.032 | 0.4 | 0.005 | ||
| SCoCaT-bonus (sparse) | – | – | – | – | |||
| SCoCaT-bonus (sparse, cont.) | 0.001 | 0.001 | 0.010 | 0.3 | 0.024 | 0.3 | 0.009 |
| SCoCaT (Both) | 0.001 | 0.001 | 0.011 | 0.2 | 0.014 | 0.2 | 0.004 |
| SCoCaT (Both, cont.) | 0.007 | 0.007 | 0.028 | 0.5 | 0.021 | 0.6 | 0.006 |
| SCoCaT (Both, TP) | 0.001 | 0.001 | 0.013 | 0.3 | 0.050 | 0.3 | 0.005 |
| SCoCaT (Both, TP, cont.) | 0.001 | 0.002 | 0.090 | 1.3 | 0.025 | 1.3 | 0.006 |
| SCoCaT (Both, sparse) | – | – | – | – | |||
| SCoCaT (Both, sparse, cont.) | 0.001 | 0.001 | 0.014 | 0.3 | 0.011 | 0.3 | 0.004 |
| CaT-PEGrad | 0.381 | 0.328 | 0.081 | 1.0 | 0.081 | 1.2 | 0.002 |
| CaT-PEGrad (cont.) | 0.264 | 0.178 | 0.033 | 3.6 | 0.063 | 2.8 | 0.001 |
| CaT-PEGrad (TP) | 0.327 | 0.266 | 0.062 | ||||
| CaT-PEGrad (TP, cont.) | 0.191 | 0.156 | 0.030 | 2.2 | 0.085 | 1.8 | 0.003 |
| Method | Compl. | Dock.Vel. | Ang.Vel. | LoS | Fuel |
|---|---|---|---|---|---|
| PPO | 0.011 | 0.037 | 0.001 | 0.025 | 0.048 |
| PPO (TP) | 0.014 | 0.003 | 0.001 | 0.094 | 0.052 |
| PPO (sparse) | 0.136 | 0.005 | 0.400 | 0.007 | 0.490 |
| CaT | 0.003 | ||||
| CaT (TP) | 0.001 | 0.003 | |||
| CaT+Curr | 0.010 | 0.001 | 0.031 | 0.036 | |
| CaT+Curr (TP) | 0.005 | 0.001 | 0.020 | 0.012 | |
| CaT+Curr (sparse) | 0.099 | 0.007 | 0.124 | 0.377 | 0.356 |
| SCoCaT | 0.002 | 0.001 | 0.009 | ||
| SCoCaT (cont.) | 0.001 | 0.005 | |||
| SCoCaT (TP) | 0.002 | 0.001 | 0.011 | ||
| SCoCaT (TP, cont.) | 0.001 | 0.001 | 0.007 | ||
| SCoCaT (sparse) | 0.133 | 0.006 | 0.317 | 0.322 | 0.423 |
| SCoCaT (sparse, cont.) | 0.056 | 0.001 | 0.334 | 0.004 | |
| SCoCaT-bonus | 0.008 | 0.001 | 0.001 | 0.043 | 0.011 |
| SCoCaT-bonus (cont.) | 0.008 | 0.001 | 0.001 | 0.030 | 0.024 |
| SCoCaT-bonus (TP) | 0.006 | 0.001 | 0.002 | 0.047 | 0.023 |
| SCoCaT-bonus (TP, cont.) | 0.011 | 0.001 | 0.001 | 0.045 | 0.031 |
| SCoCaT-bonus (sparse) | 0.100 | 0.004 | 0.389 | 0.072 | 0.220 |
| SCoCaT-bonus (sparse, cont.) | 0.039 | 0.001 | 0.036 | 0.213 | 0.150 |
| SCoCaT (Both) | 0.007 | 0.001 | 0.040 | ||
| SCoCaT (Both, cont.) | 0.005 | 0.002 | 0.028 | ||
| SCoCaT (Both, TP) | 0.015 | 0.010 | 0.028 | 0.044 | 0.009 |
| SCoCaT (Both, TP, cont.) | 0.002 | 0.001 | 0.012 | 0.001 | |
| SCoCaT (Both, sparse) | 0.175 | 0.010 | 0.426 | 0.335 | 0.431 |
| SCoCaT (Both, sparse, cont.) | 0.002 | 0.002 | 0.001 | 0.010 | 0.001 |
| CaT-PEGrad | 0.112 | 0.005 | 0.434 | 0.313 | 0.001 |
| CaT-PEGrad (cont.) | 0.003 | 0.021 | |||
| CaT-PEGrad (TP) | 0.114 | 0.010 | 0.450 | 0.243 | 0.054 |
| CaT-PEGrad (TP, cont.) | 0.019 | 0.010 | 0.089 | 0.014 |
D.1 CaT-PEGrad.
The appendix’s PEGrad adaptation computes separate reward/success PPO gradients, projects the reward gradient orthogonal to success, rescales it and combines it with success as the primary direction. This reverses the main text’s description of projecting success against reward; the retained appendix formulas specify the reported derivation. Orthogonality is a local first-order property, not a finite-step guarantee of improved success or safety. Extra backward passes and critic-only clipping preserve that construction. It improves over CaT on some engagement measures but trails SCoCaT in the reported tradeoff.
Equations 22–25
| (22) | ||||
| (23) |
| (24) |
| (25) |
Appendix E Full Ablation Study: 6U CubeSat (6-DoF)
CubeSat binary SCoCaT has entry/TCR 0.794, hold 0.694 and declared success 0.613±0.359, compared with PPO’s 0.931±0.068 and CaT’s zero declared success. Continuous SCoCaT enters every episode but declares success only 0.450±0.489. Thus entry is not successful holding, and seed variability is substantial. Binary compliance is 0.945 versus CaT 0.971: line-of-sight violations rise 0.135→0.286, while angular violations also rise slightly 0.035→0.039 and docking-speed violations remain 0.004. The aggregate is an average across constraint types, not a probability of a violation-free episode.
Appendix F Obstacle Avoidance Results
Adding an obstacle activates hard collision termination. Binary SCoCaT reaches the pose-corridor SR diagnostic in 0.770 of episodes, versus PPO 0.237 and CaT 0.027, with reported per-timestep collision violations rounded to zero. Aggregate compliance is 0.965 versus CaT 0.982. The table’s SR is episode success at the real-experiment pose criterion, not the fully velocity-gated declared metric. Rare collision risk cannot be inferred to be zero from rounded timestep rates. The prose calls the obstacle cylindrical and the caption spherical; both original descriptions are retained.