Overview
At a glance
This edition follows the complete thirty-one-page arXiv v1, including thirteen numbered figures, seven tables, the design algorithm and all seventy-five numbered equations. The catalog’s RSS publication link is retained; the reviewed text and illustrations are explicitly the arXiv version.
A portrait-to-hardware pipeline adapts a modular linkage template to different face geometries, then generates speaking/listening expressions from paired audio and maps them to calibrated robot actuators. The mechanical optimizer achieves collision-free sampled assemblies for ten of fifteen tested heads. A hundred-participant video study favors the complete interaction system over the tested ablations.
The contribution is automated parameter adaptation within a fixed mechanism topology, coupled to conversational animation and physical calibration. The experiments do not establish arbitrary-face manufacturability, continuous-motion collision guarantees, identity-disjoint conversational generalization or measured end-to-end response latency.
I Introduction
Existing expressive robot faces generally require custom mechanical redesign for each geometry. This work makes a reusable template the starting point: reconstruct and scale a face, synthesize module geometry, resolve assembly interference, then generate and retarget interactive motion.
Conversational embodiment requires listener behavior as well as speech articulation. The proposed audio model conditions on both interlocutors and switches between speaking and listening; region-specific regressors convert animation parameters into physical commands. Large-scale personalized deployment is a motivation, not an evaluated fleet-scale result.
II Related Work
II-A Mechanical Face Platform
Pneumatic, tendon, linkage and soft actuation have enabled progressively richer robot faces. Platforms such as EMO and Morpheus demonstrate expressive control, but adapting their geometry remains a mechanical-design problem. The proposed template trades unrestricted architectural choice for repeatable parameter optimization.
II-B Automatic Robot Design
Computational mechanism synthesis, including mechanical characters and linkage-based characters, provides the design precedent. Robot morphology/control optimization additionally considers dynamics and tasks. Facial packaging demands many small mechanisms fit together inside a constrained shell, motivating explicit assembly collision refinement.
II-C Talking Head Generation and Expression Mapping
Audio-driven 3D animation supplies expression coordinates more directly usable by robots than rendered 2D video. DualTalk models reciprocal conversational behavior; learned animatronic mapping such as Smile Like You Mean It addresses the avatar–hardware gap. This system combines paired-audio generation with semantic regional mapping.
III Automated Scalable Mechanism Design
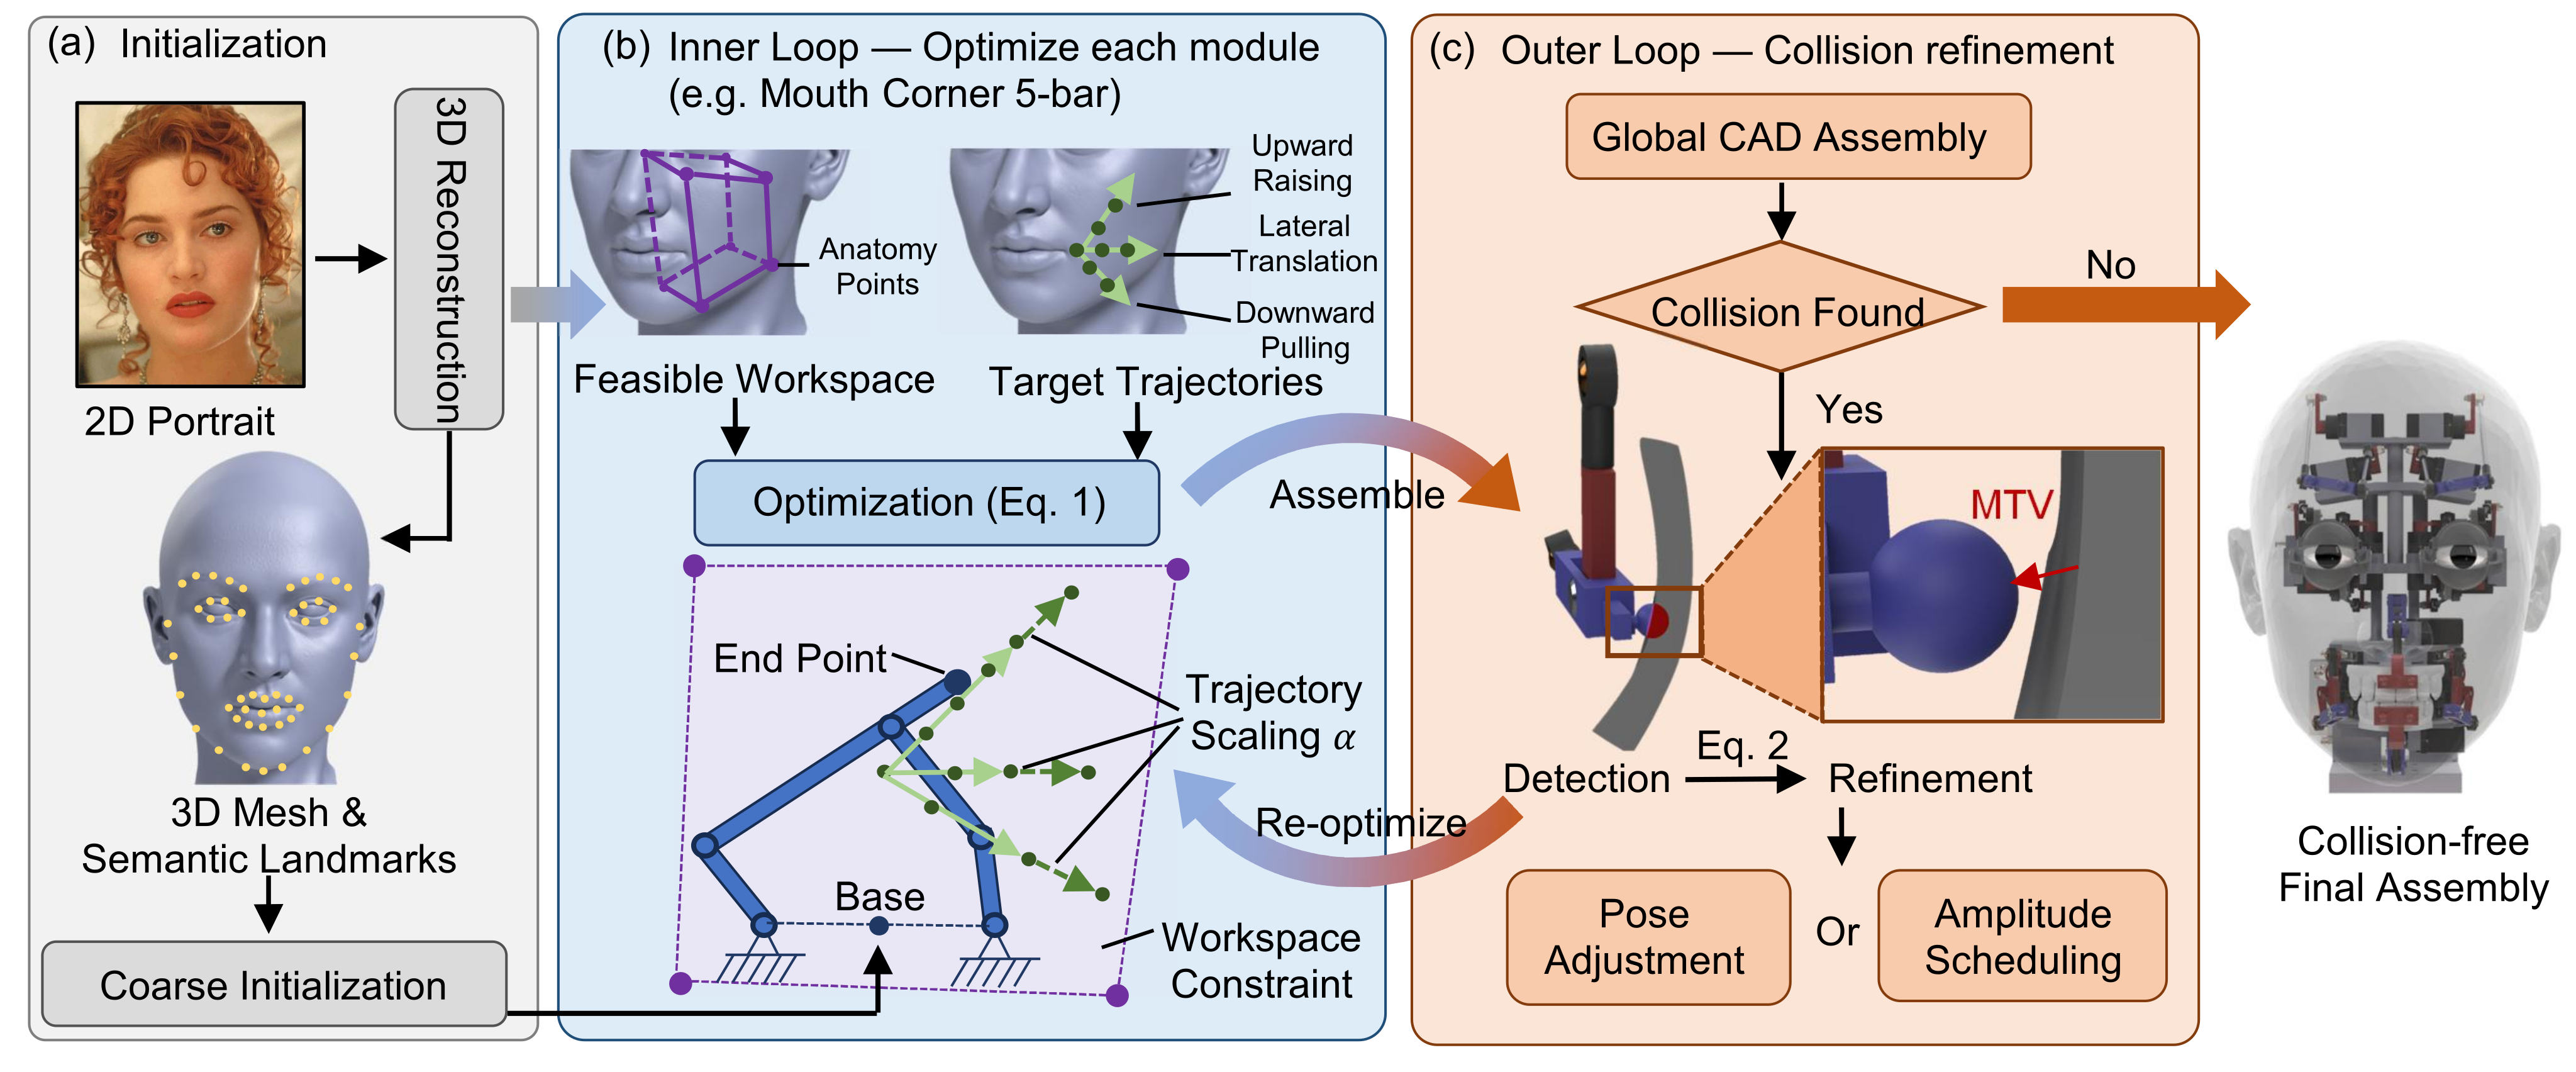
The hardware pipeline initializes a fixed modular architecture from reconstructed facial landmarks, optimizes selected mechanisms independently, and then revisits them after assembly-level collision checks. It optimizes continuous parameters and motion amplitudes rather than searching new linkage topologies.
III-A Parametric Face Template Design
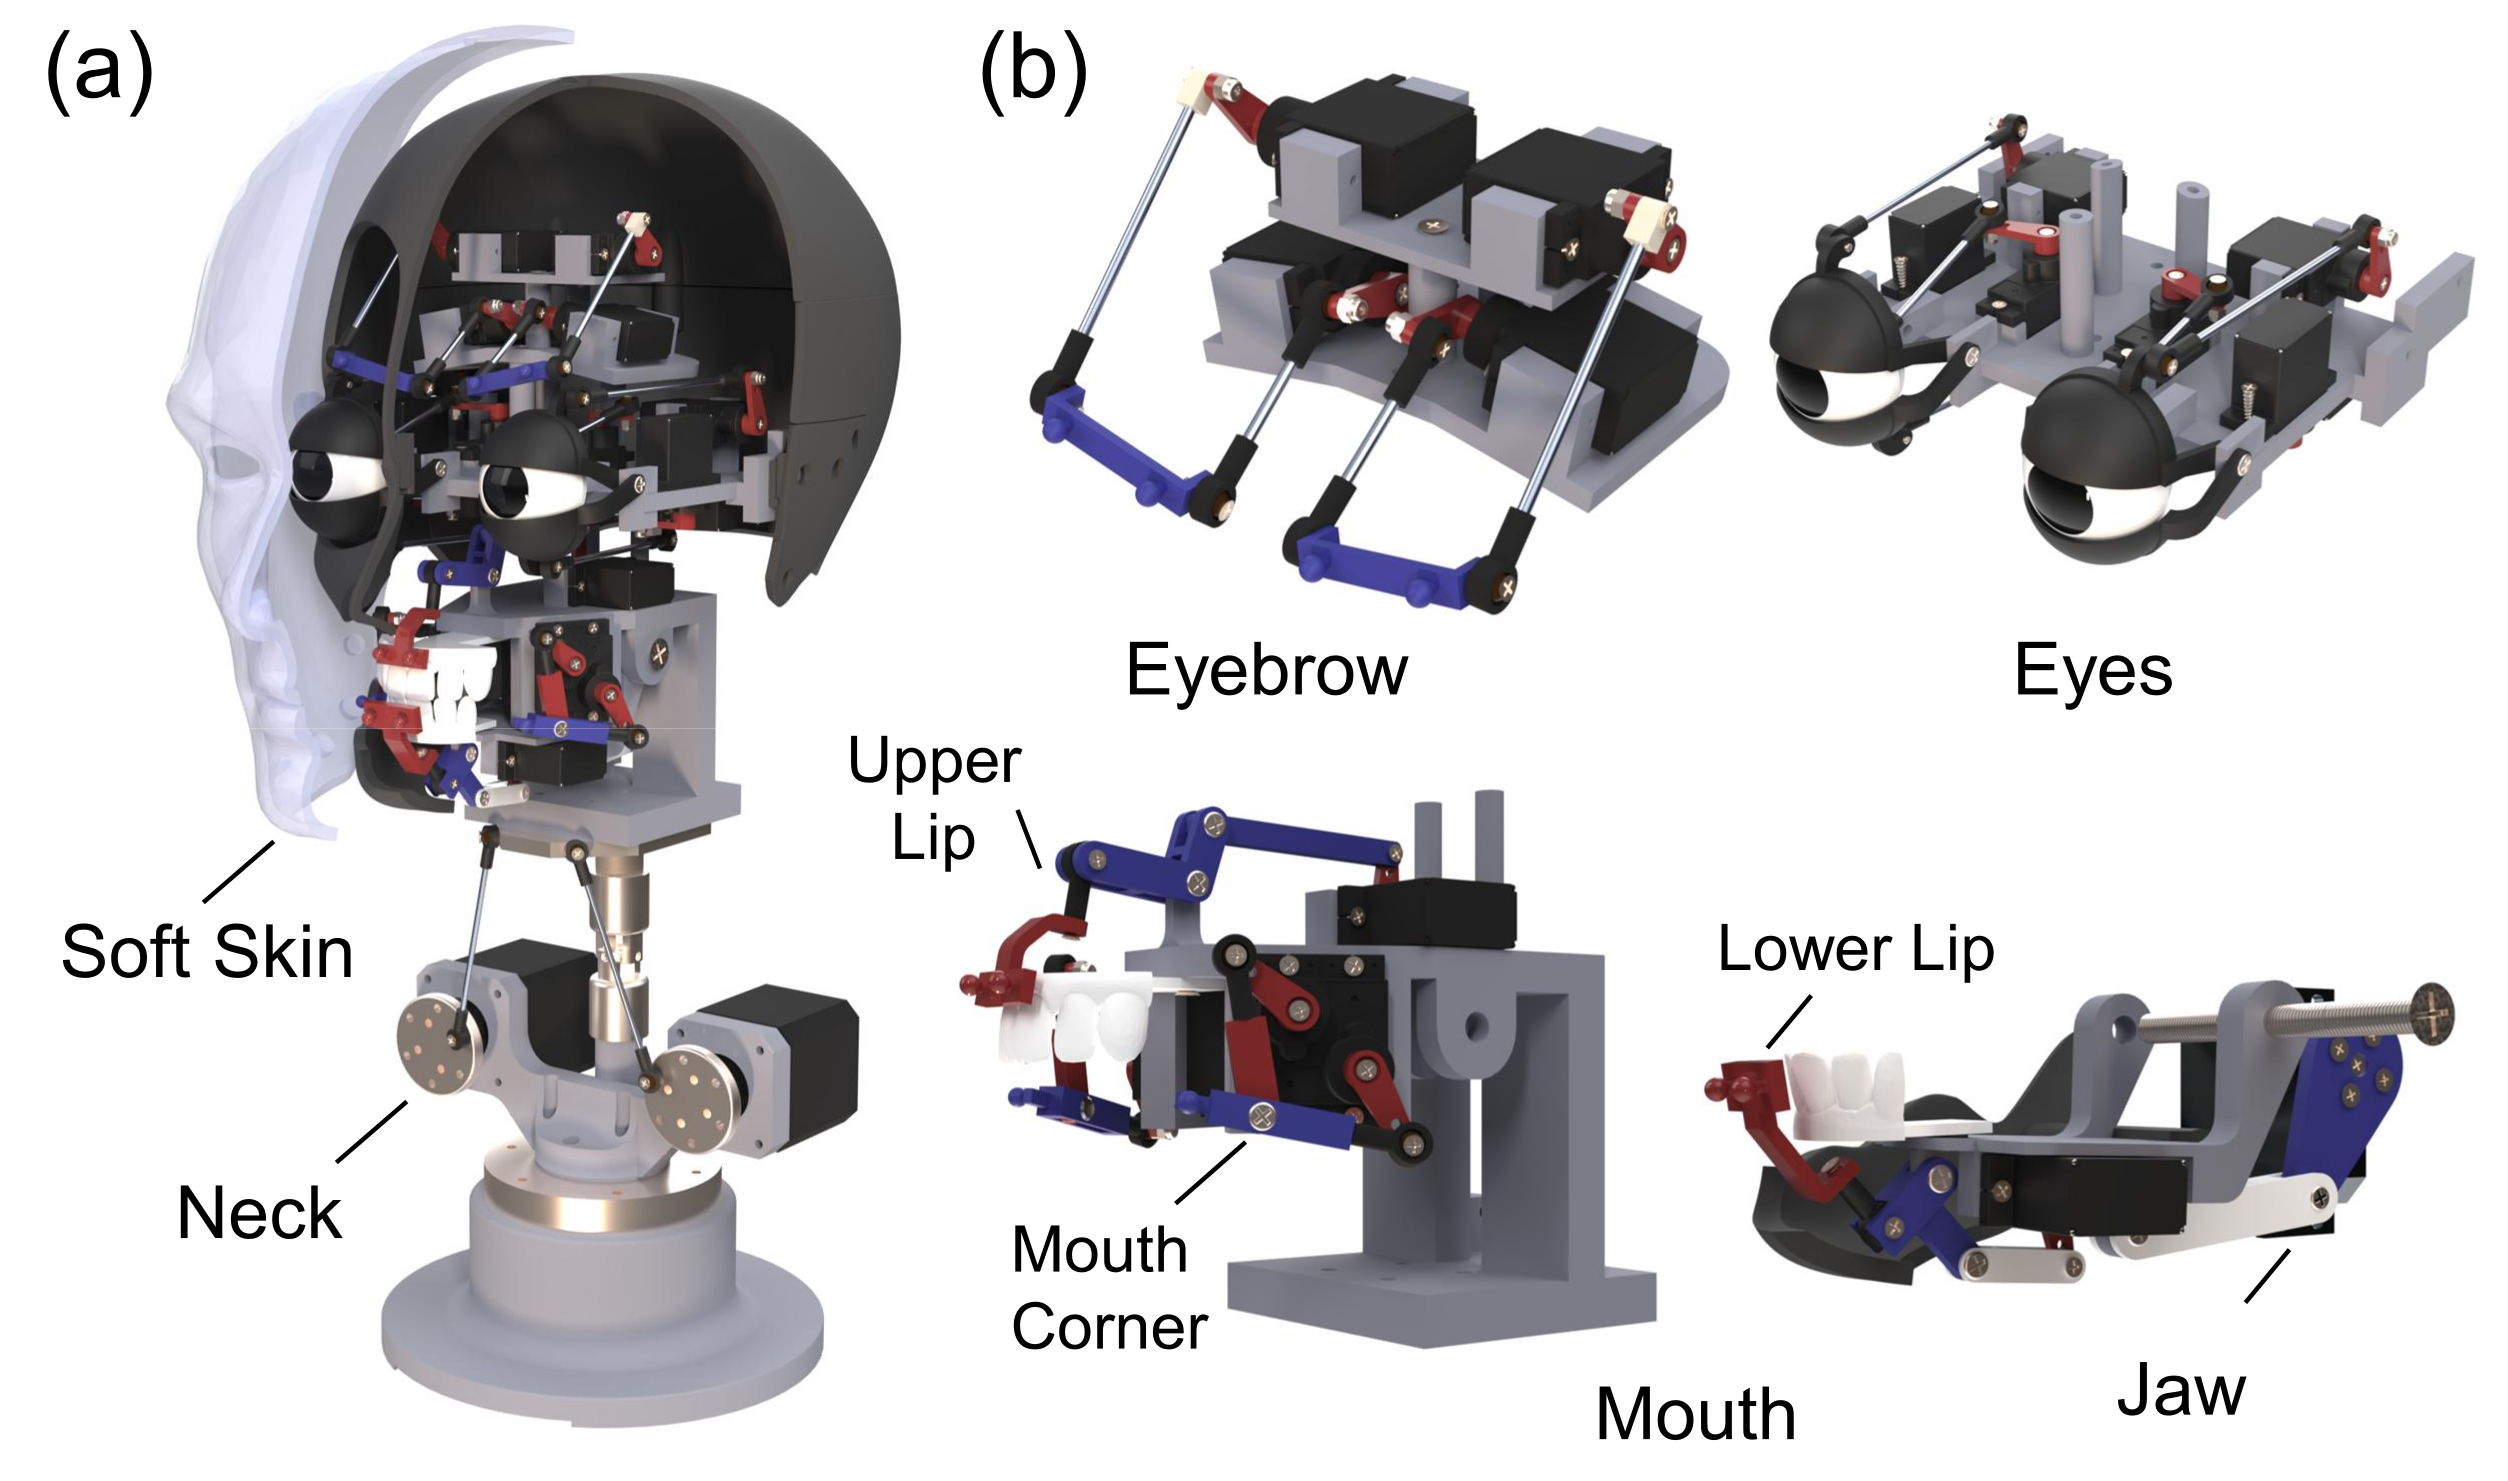
Two-DoF spatial six-bar brow mechanisms control inner-brow and ridge motion. The eyes have eight DoFs: four eyelids plus two rotations per eyeball. Four-bar upper/lower lips, two-input five-bar mouth corners and a four-bar jaw provide mouth motion. The neck combines two parallel pitch/roll inputs with separate yaw.
The hardware section states twenty-one facial actuators, while the explicitly enumerated two brows, eight eye DoFs and seven mouth/jaw outputs sum to nineteen. The source does not reconcile this count; the separate three neck actuators should not silently resolve it.
III-B Hierarchical Automatic Design
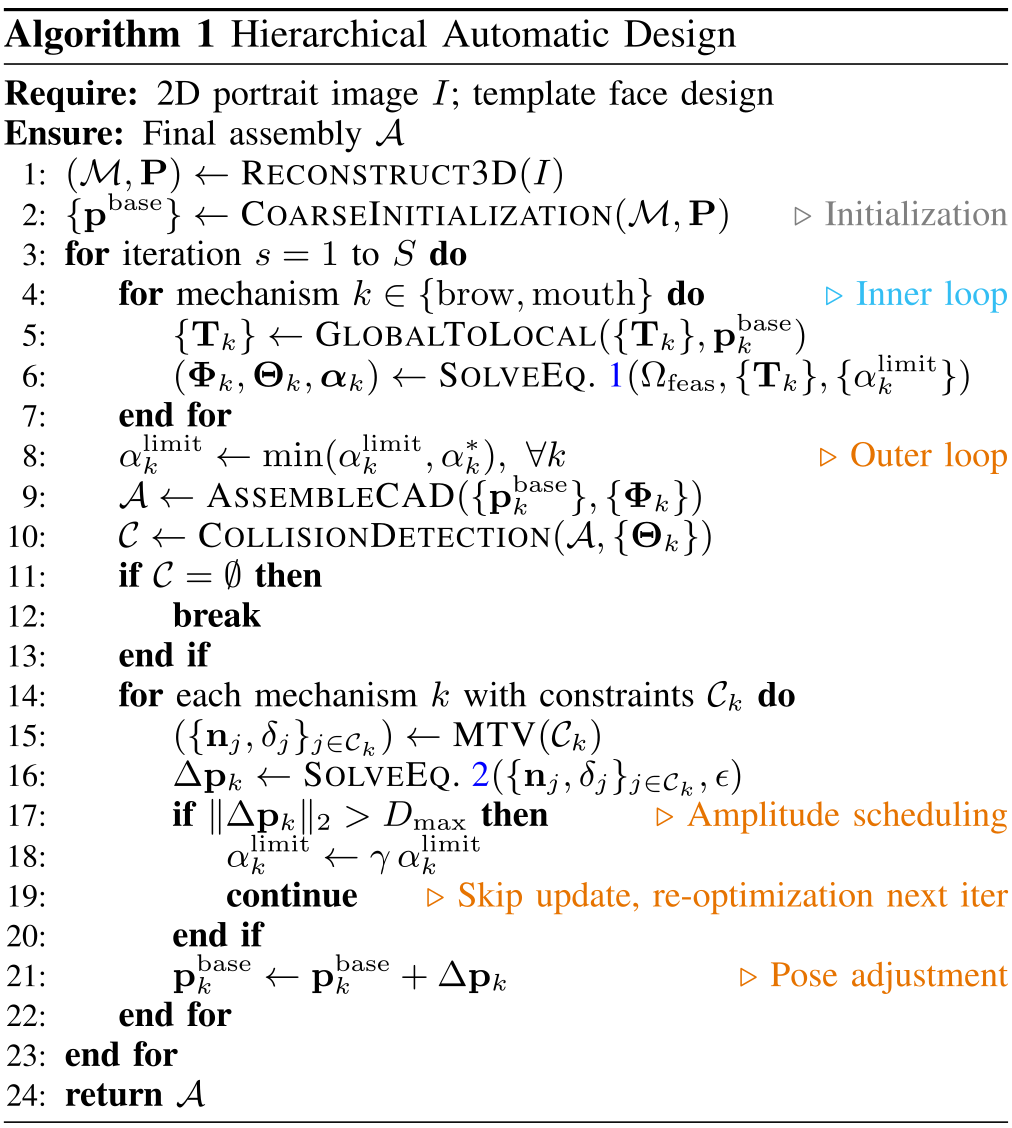
The outer loop alternates kinematic synthesis and geometric repair. Small base translations are accepted; excessive corrections instead reduce allowable expression amplitude. Termination at the iteration limit can retain a failed assembly, as the reported failures demonstrate.
III-B 1 Coarse initialization
Metrical face reconstruction produces a mesh and semantic landmarks from the portrait. A chosen physical scale places the template in CAD. Eye and jaw geometry are fixed after initialization; brow and mouth bases use scaled template offsets and their link lengths undergo subsequent optimization.
III-B 2 Module-wise kinematic design optimization
Eight canonical trajectories derived from facial Action Units specify vertical brow/lip motion and raising, lateral and lowering corner motion. Each trajectory has an amplitude coefficient and ten sampled configurations. Regional anatomical envelopes constrain the attachment points.
Equation 1 minimizes inverse amplitude and trajectory error while subtracting a manipulability reward. It jointly fits link lengths, sampled joint configurations and amplitudes. This is a nonconvex, sampled kinematic objective; the term encourages usable local motion without proving a global optimum or modeling silicone elasticity and actuator torque.
Equation 1
| (1) | ||||
Original selectable algorithm
III-B 3 Global CAD assembly and collision-driven refinement
FCL detects assembly interference along the sampled motion. Each contact yields a separation normal and penetration depth; a quadratic program finds the minimum-norm base translation satisfying all linearized clearance constraints. A shift above three millimetres instead multiplies the amplitude limit by 0.9 and triggers reoptimization.
At most ten outer iterations use a 0.5 mm clearance. New interference can follow a local repair, and opposing constraints can make the translation problem infeasible. Checking ten trajectory waypoints does not certify continuous paths or arbitrary combinations of actuator commands.
Equation 2
| (2) |
IV Interaction Synthesis and Control
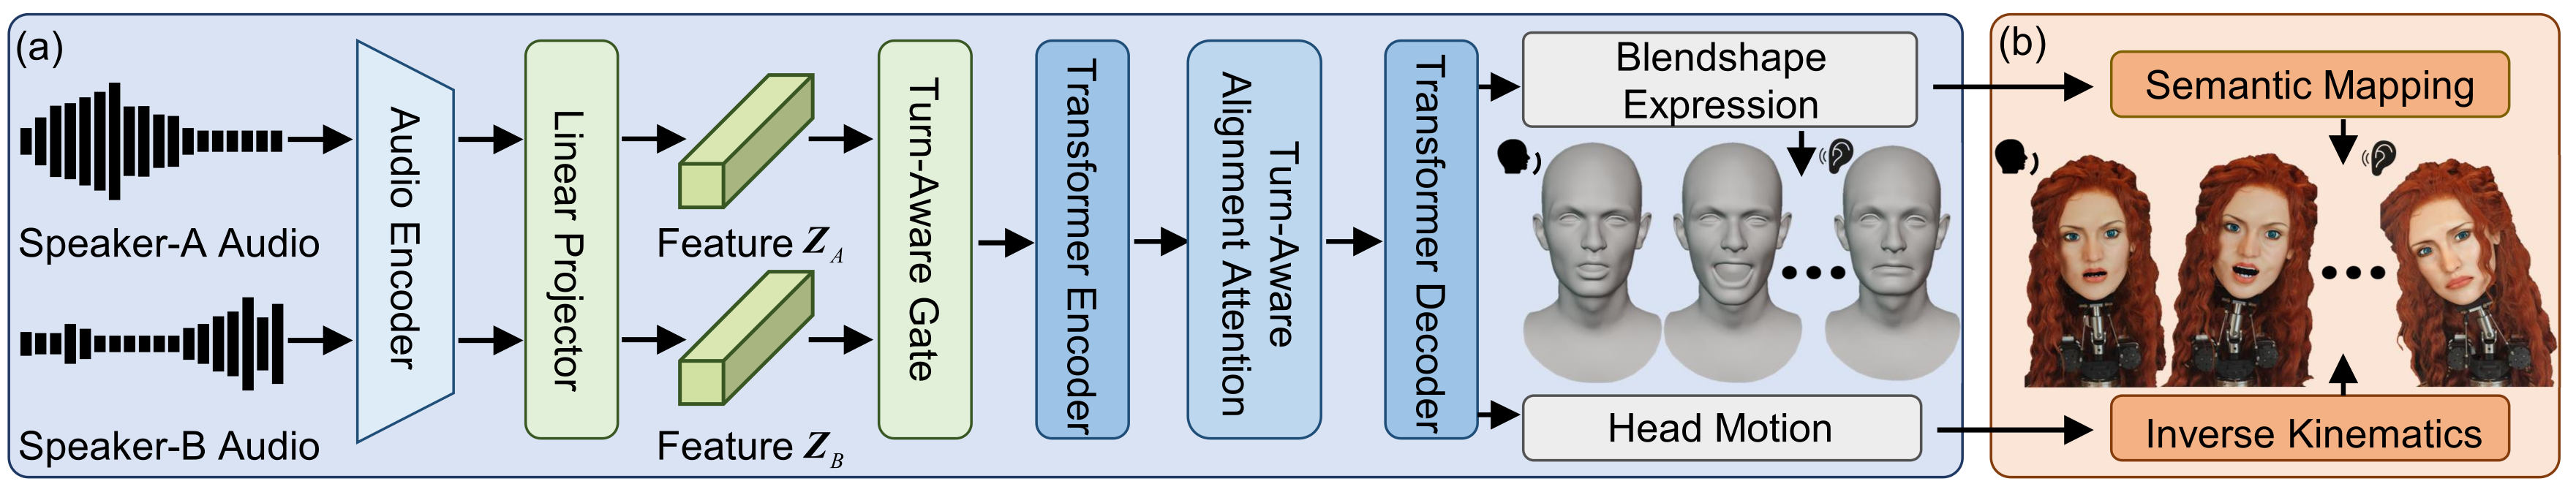
The control pipeline separates conversational motion generation from embodiment-specific inverse mapping. The first predicts an animated face; the second uses calibration data for each manufactured head, while analytical neck inverse kinematics handles head pose.
IV-A Interactive Talking Head Synthesis
A shared wav2vec 2.0 audio encoder and linear projection produce two aligned feature streams. Temporal/style embeddings precede intensity-derived gating: the target’s audio dominates while it speaks and the partner’s audio dominates while it listens. A transformer predicts fifty-two blendshapes and three head angles.
Training uses paired conversational video with MediaPipe motion labels. The mostly nonoverlapping-turn assumption simplifies gating; overlapped speech may be imperfectly represented by a single weighted mixture. Unlike the cited DualTalk setup, partner future motion is not an input. The supplied architecture nevertheless does not specify a complete causal masking/window/lookahead protocol or measured end-to-end latency.
Equation 3
| (3) |
IV-B Human-to-Robot Facial Expression Mapping
Facial coefficients are partitioned into eyebrow, eye, mouth and jaw regions. Separate MLPs learn motor commands from corresponding coefficients, while neck angles use inverse kinematics. For each head, three thousand Latin-hypercube motor configurations are photographed and labeled with MediaPipe after actuation bounds are calibrated.
This is supervised per-head inverse mapping, not zero-shot transfer to an uncalibrated mechanism. Individual coefficient bounds or actuator limits do not by themselves guarantee feasibility of every combined facial expression.
V Experiment
V-A Experimental Setup
The fabricated heads use PLA components, silicone skin, 9 g facial servos, three NEMA 17 neck motors and a Jetson AGX Orin with 32 GB memory. Commands update at 30 Hz through the stated I²C/PWM interface. The twenty-one facial-actuator claim is retained with the module-count qualification above.
V-B Evaluation of the Automatic Design Flow
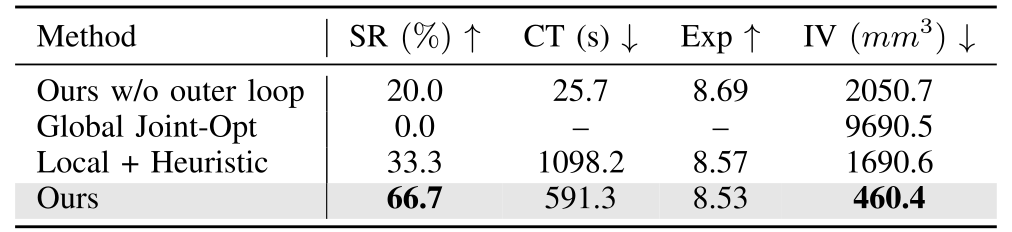
Across fifteen heads, success is 20% for local-only synthesis, 0% for joint optimization, 33.3% for heuristic repair and 66.7% for the proposed hierarchy. Successful-run convergence times are 25.7, unavailable, 1098.2 and 591.3 seconds respectively; expressiveness is 8.69, unavailable, 8.57 and 8.53.
Convergence time and expressiveness include only successful runs, hence different successful head subsets. Intersection volume averages use zero for successes and final residual overlap for failures. The reported 1.9× runtime advantage over heuristic repair is conditional on success, not an all-head time-to-valid-design comparison.
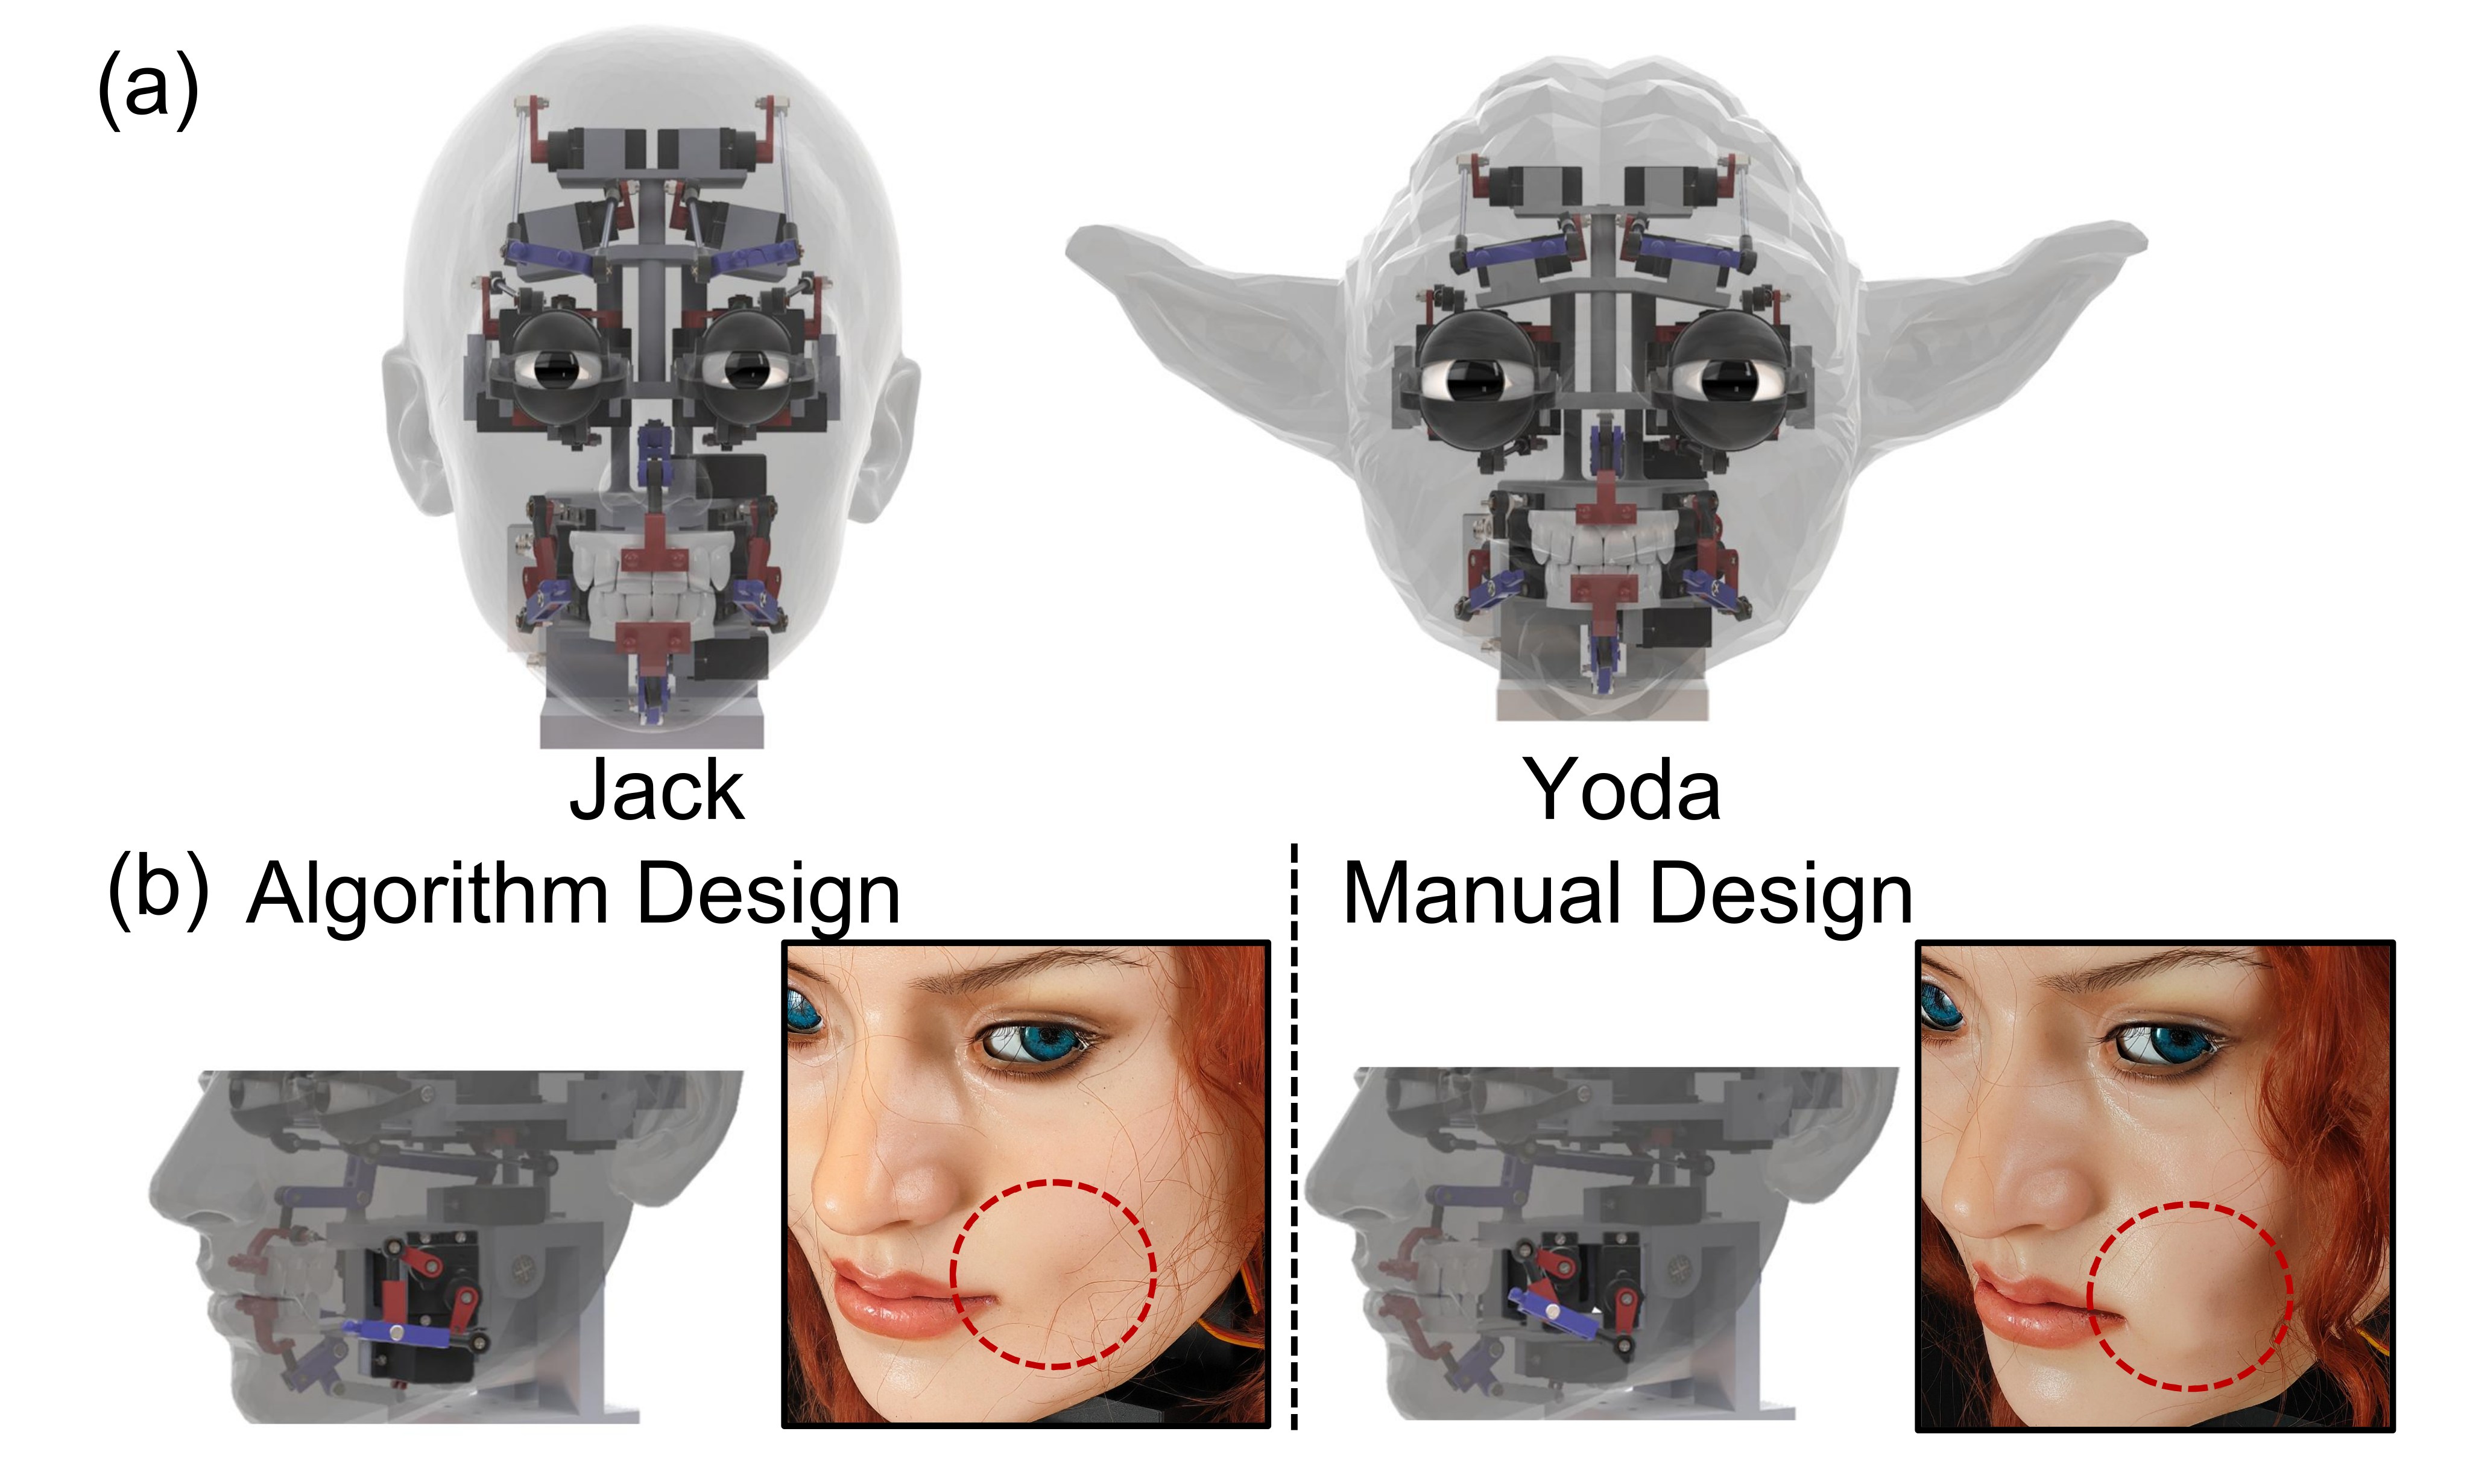
Two senior engineers required an average 22.8 hours to design one compact head manually, versus 11.7 minutes of optimization. This selected design-time comparison excludes printing, skin fabrication and assembly. Qualitative corner-motion improvement does not establish the same gain for every geometry.
V-C Evaluation of Conversational Motion Synthesis
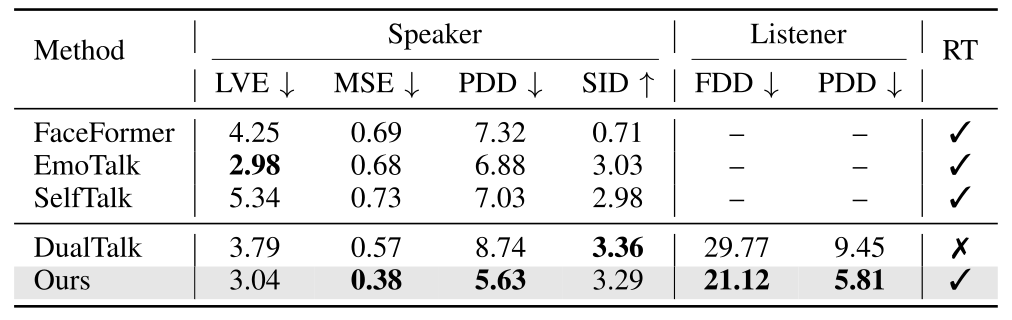
The authors train FaceFormer, EmoTalk, SelfTalk, DualTalk and the proposed model on their dataset. The proposed speaker MSE/PDD are 0.38/5.63 and listener FDD/PDD 21.12/5.81, improving those reported comparisons. Its LVE 3.04 is worse than EmoTalk’s 2.98, and SID 3.29 is below DualTalk’s 3.36.
The table labels real-time support as a capability distinction; it does not supply complete pipeline latency. Motion-distribution statistics and coefficient error are complementary metrics, not direct measurements of conversational understanding or physical interaction safety.
V-D Evaluation of Expression Mapping Results
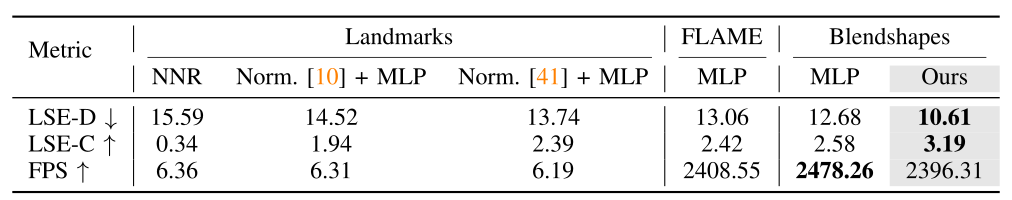
Region-wise mapping gives LSE-D 10.61 and LSE-C 3.19, compared with 12.68/2.58 for a global blendshape regressor and weaker landmark/FLAME baselines. Its 2396.31 FPS is a mapping-network measurement on Orin, not the full audio-to-motion rate or the 30 Hz physical command rate. Global blendshape and FLAME regressors are slightly faster.
Landmark methods include rendering and re-detection, unlike coefficient-based inputs, so these timings compare complete stated mapping routes rather than matched neural-network compute. LSE searches temporal offsets, and therefore cannot independently establish low response latency.
V-E End-to-End Conversation Demonstration
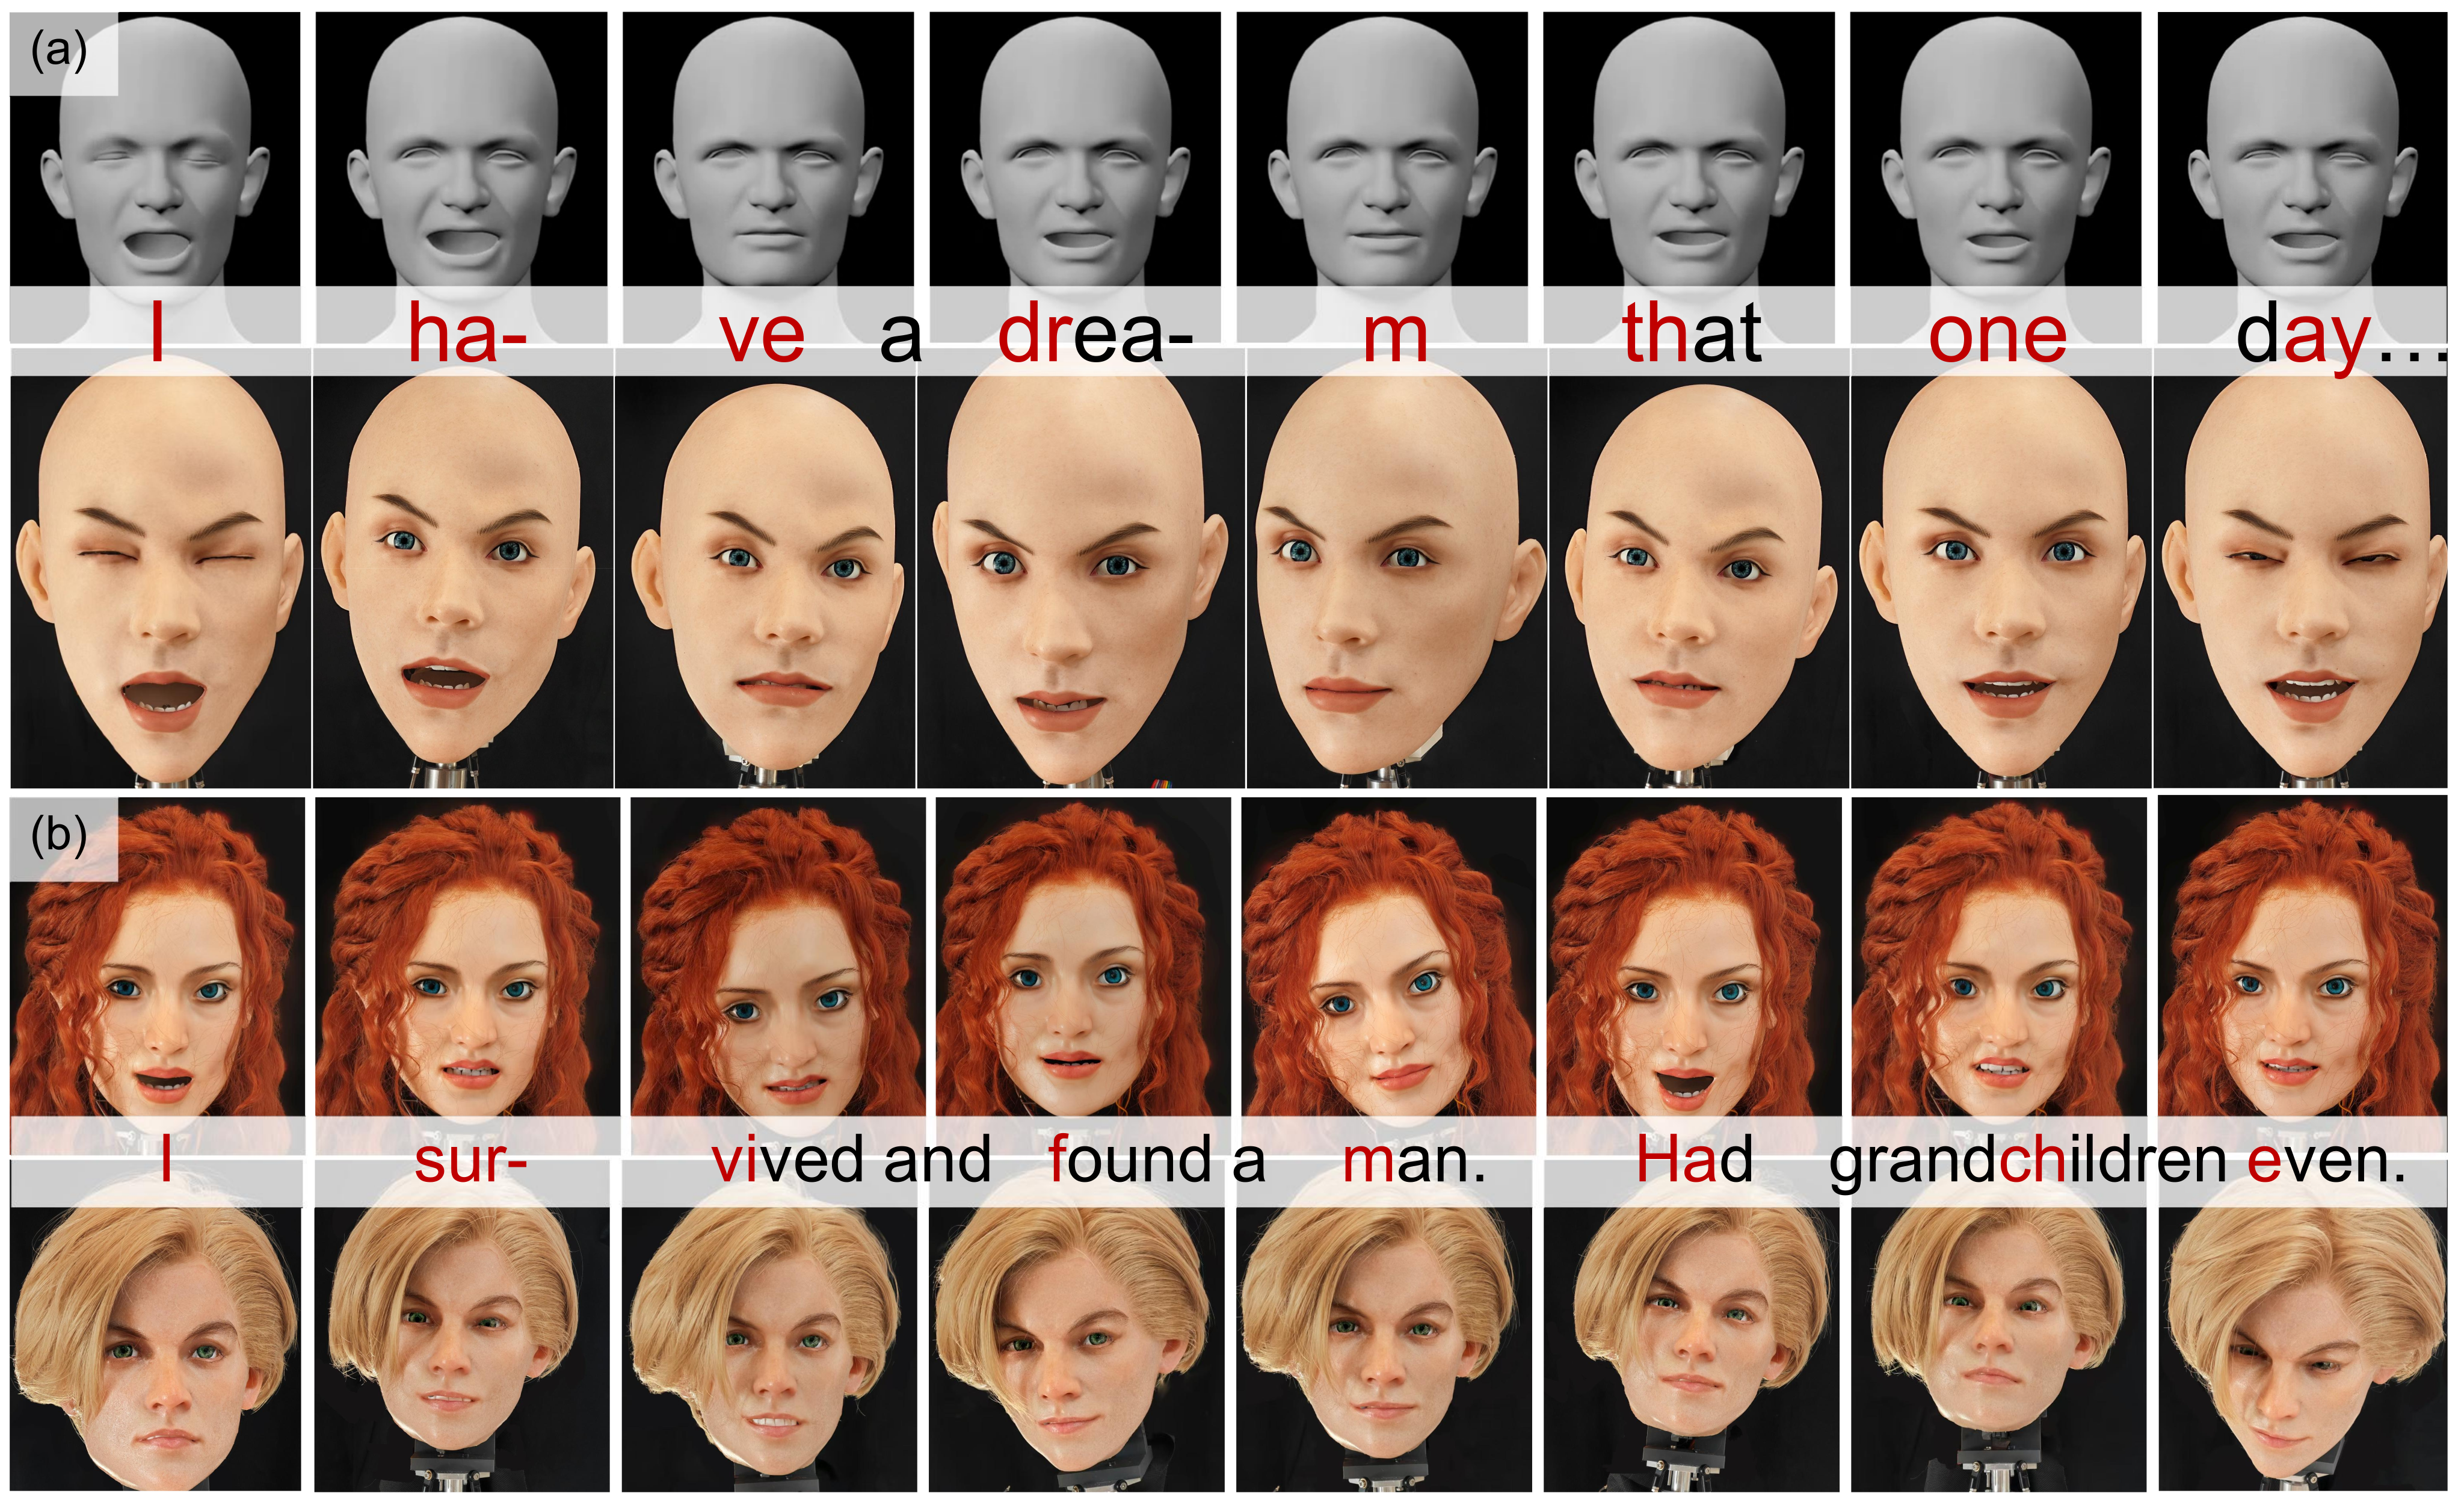
Demonstrations combine Doubao Voice dialogue with the facial pipeline and stage dyadic fictional-character scenes. Figures retain speaking and listening expressions across human–robot, robot–robot and avatar–robot settings. These are selected interaction examples, not a quantitative language-by-language robustness test.
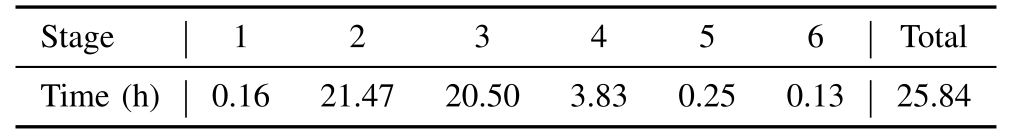
The time breakdown totals 25.84 hours by overlapping 21.47 hours of printing with 20.50 hours of skin production. Other stages are 0.16 hours optimization, 3.83 assembly, 0.25 calibration collection and 0.13 mapping training. Sequentially adding every stage gives 46.34 hours; the reported total explicitly depends on parallel fabrication.
Original selectable table
| Stage | 1 | 2 | 3 | 4 | 5 | 6 | Total |
|---|---|---|---|---|---|---|---|
| Time (h) | 0.16 | 21.47 | 20.50 | 3.83 | 0.25 | 0.13 | 25.84 |
V-F User study
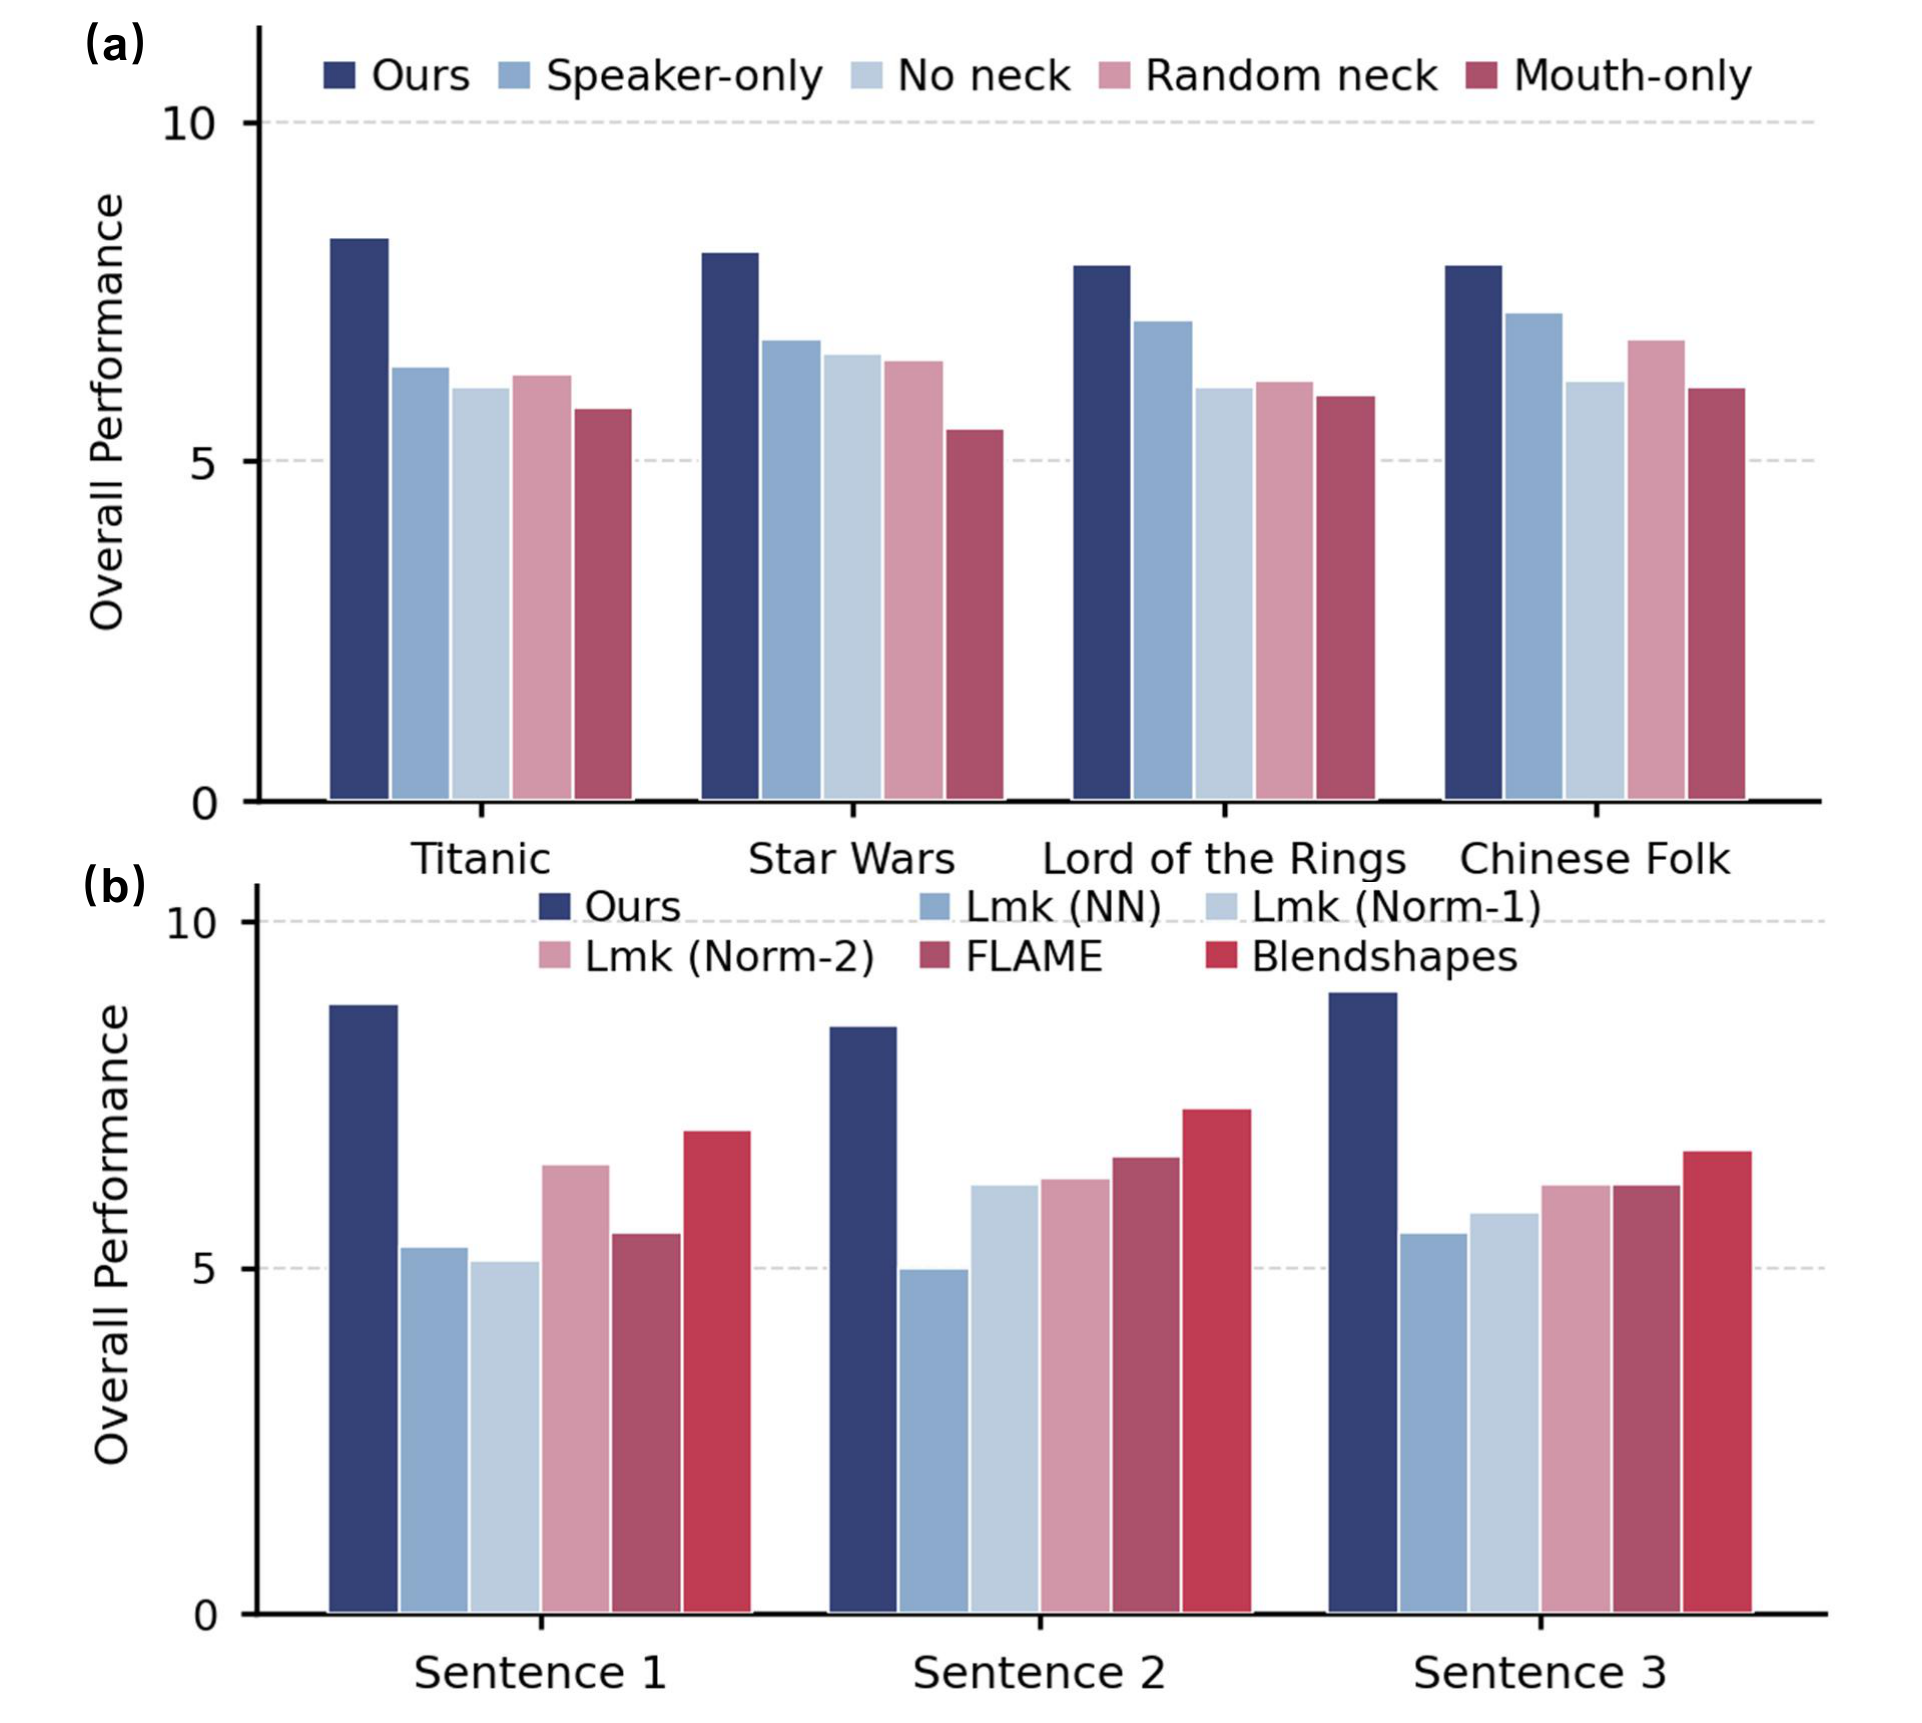
A hundred participants view reference clips and randomized, method-blinded robot variants. The complete system receives the highest mean ratings across four interaction excerpts and three mapping sentences. The comparisons support the tested contribution of listener cues, coordinated neck motion and full-face mapping; no variability intervals or inferential tests accompany these reported means.
VI Conclusion
The work connects automated adaptation of a reusable facial mechanism with paired-audio motion and per-head retargeting. Its demonstrated scope is a fifteen-head design experiment, selected physical dialogues and short video-based perceptual evaluations. More general geometry, material-aware synthesis and broader interaction quality remain open.
-A Overview
The appendix supplies kinematic derivations, optimization and network settings, fabrication details, extended demonstrations, demographic counts and limitations. These details clarify the sampled nature of feasibility checks, calibration requirements and the distinction between network throughput and physical interaction timing.
-B Extended Related Work
-B 1 Mechanical Face Platform
The historical survey spans FACS-oriented actuation, compliant materials, full humanoids and high-fidelity android faces. Prior platforms illustrate several viable architectures, but each has geometry-specific mechanisms and calibration. The proposed optimizer addresses reuse within its own template; the survey is not an empirical comparison against every listed platform.
-B 2 Automatic Robot Design
Linkage synthesis and motion retargeting motivate parameterized mechanical design. Dynamics-aware co-optimization elsewhere solves different task and packaging problems. Facial methods that tune actuator locations or skin properties motivate combining trajectory fitting with assembly collision checks here.
-B 3 Talking Head Generation and Expression Mapping
Three-dimensional speech animation has progressed from lip motion to emotional, cross-identity and dyadic behavior. Physical retargeting uses landmarks, action semantics and learned inverse models. The present modular pipeline retains intermediate coefficients, making errors and calibration needs at both stages relevant.
-C Mechanism Kinematic Analysis
The derivations give forward models for linkage synthesis and inverse models for the neck. Mobility counts describe generic configurations; closed-loop branch selection, singularities and geometric feasibility still matter. Every original displayed relation is retained.
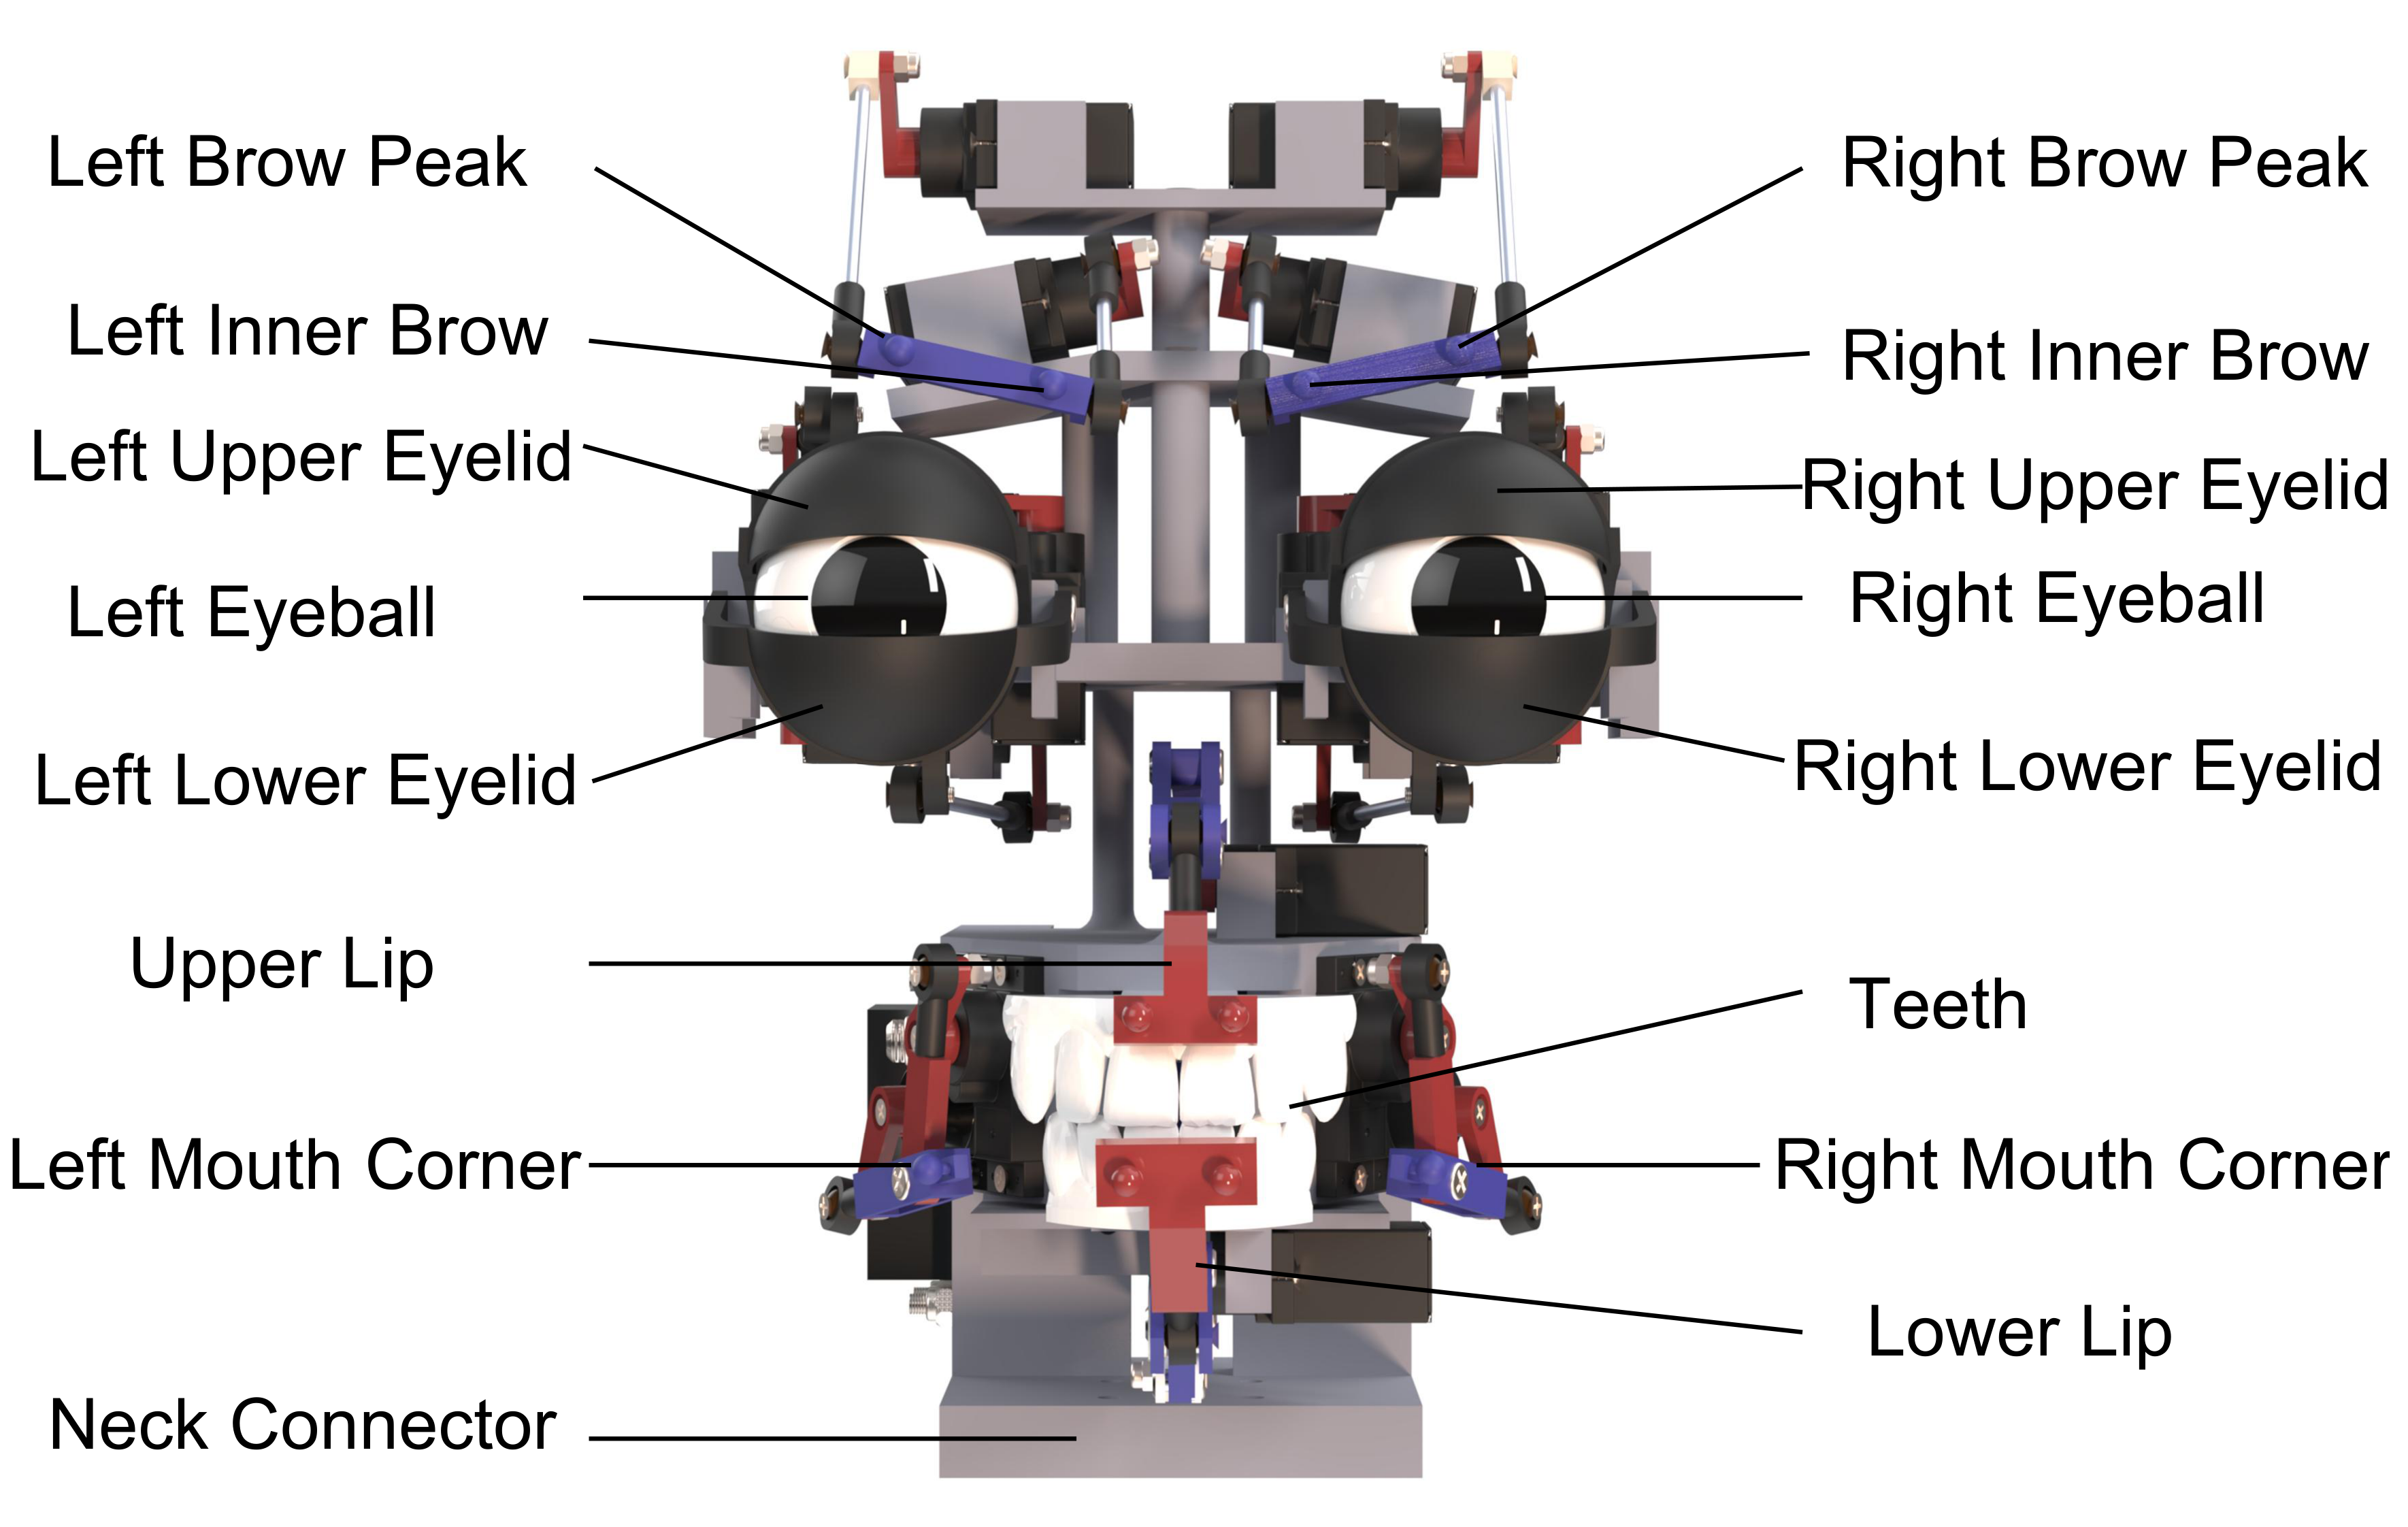
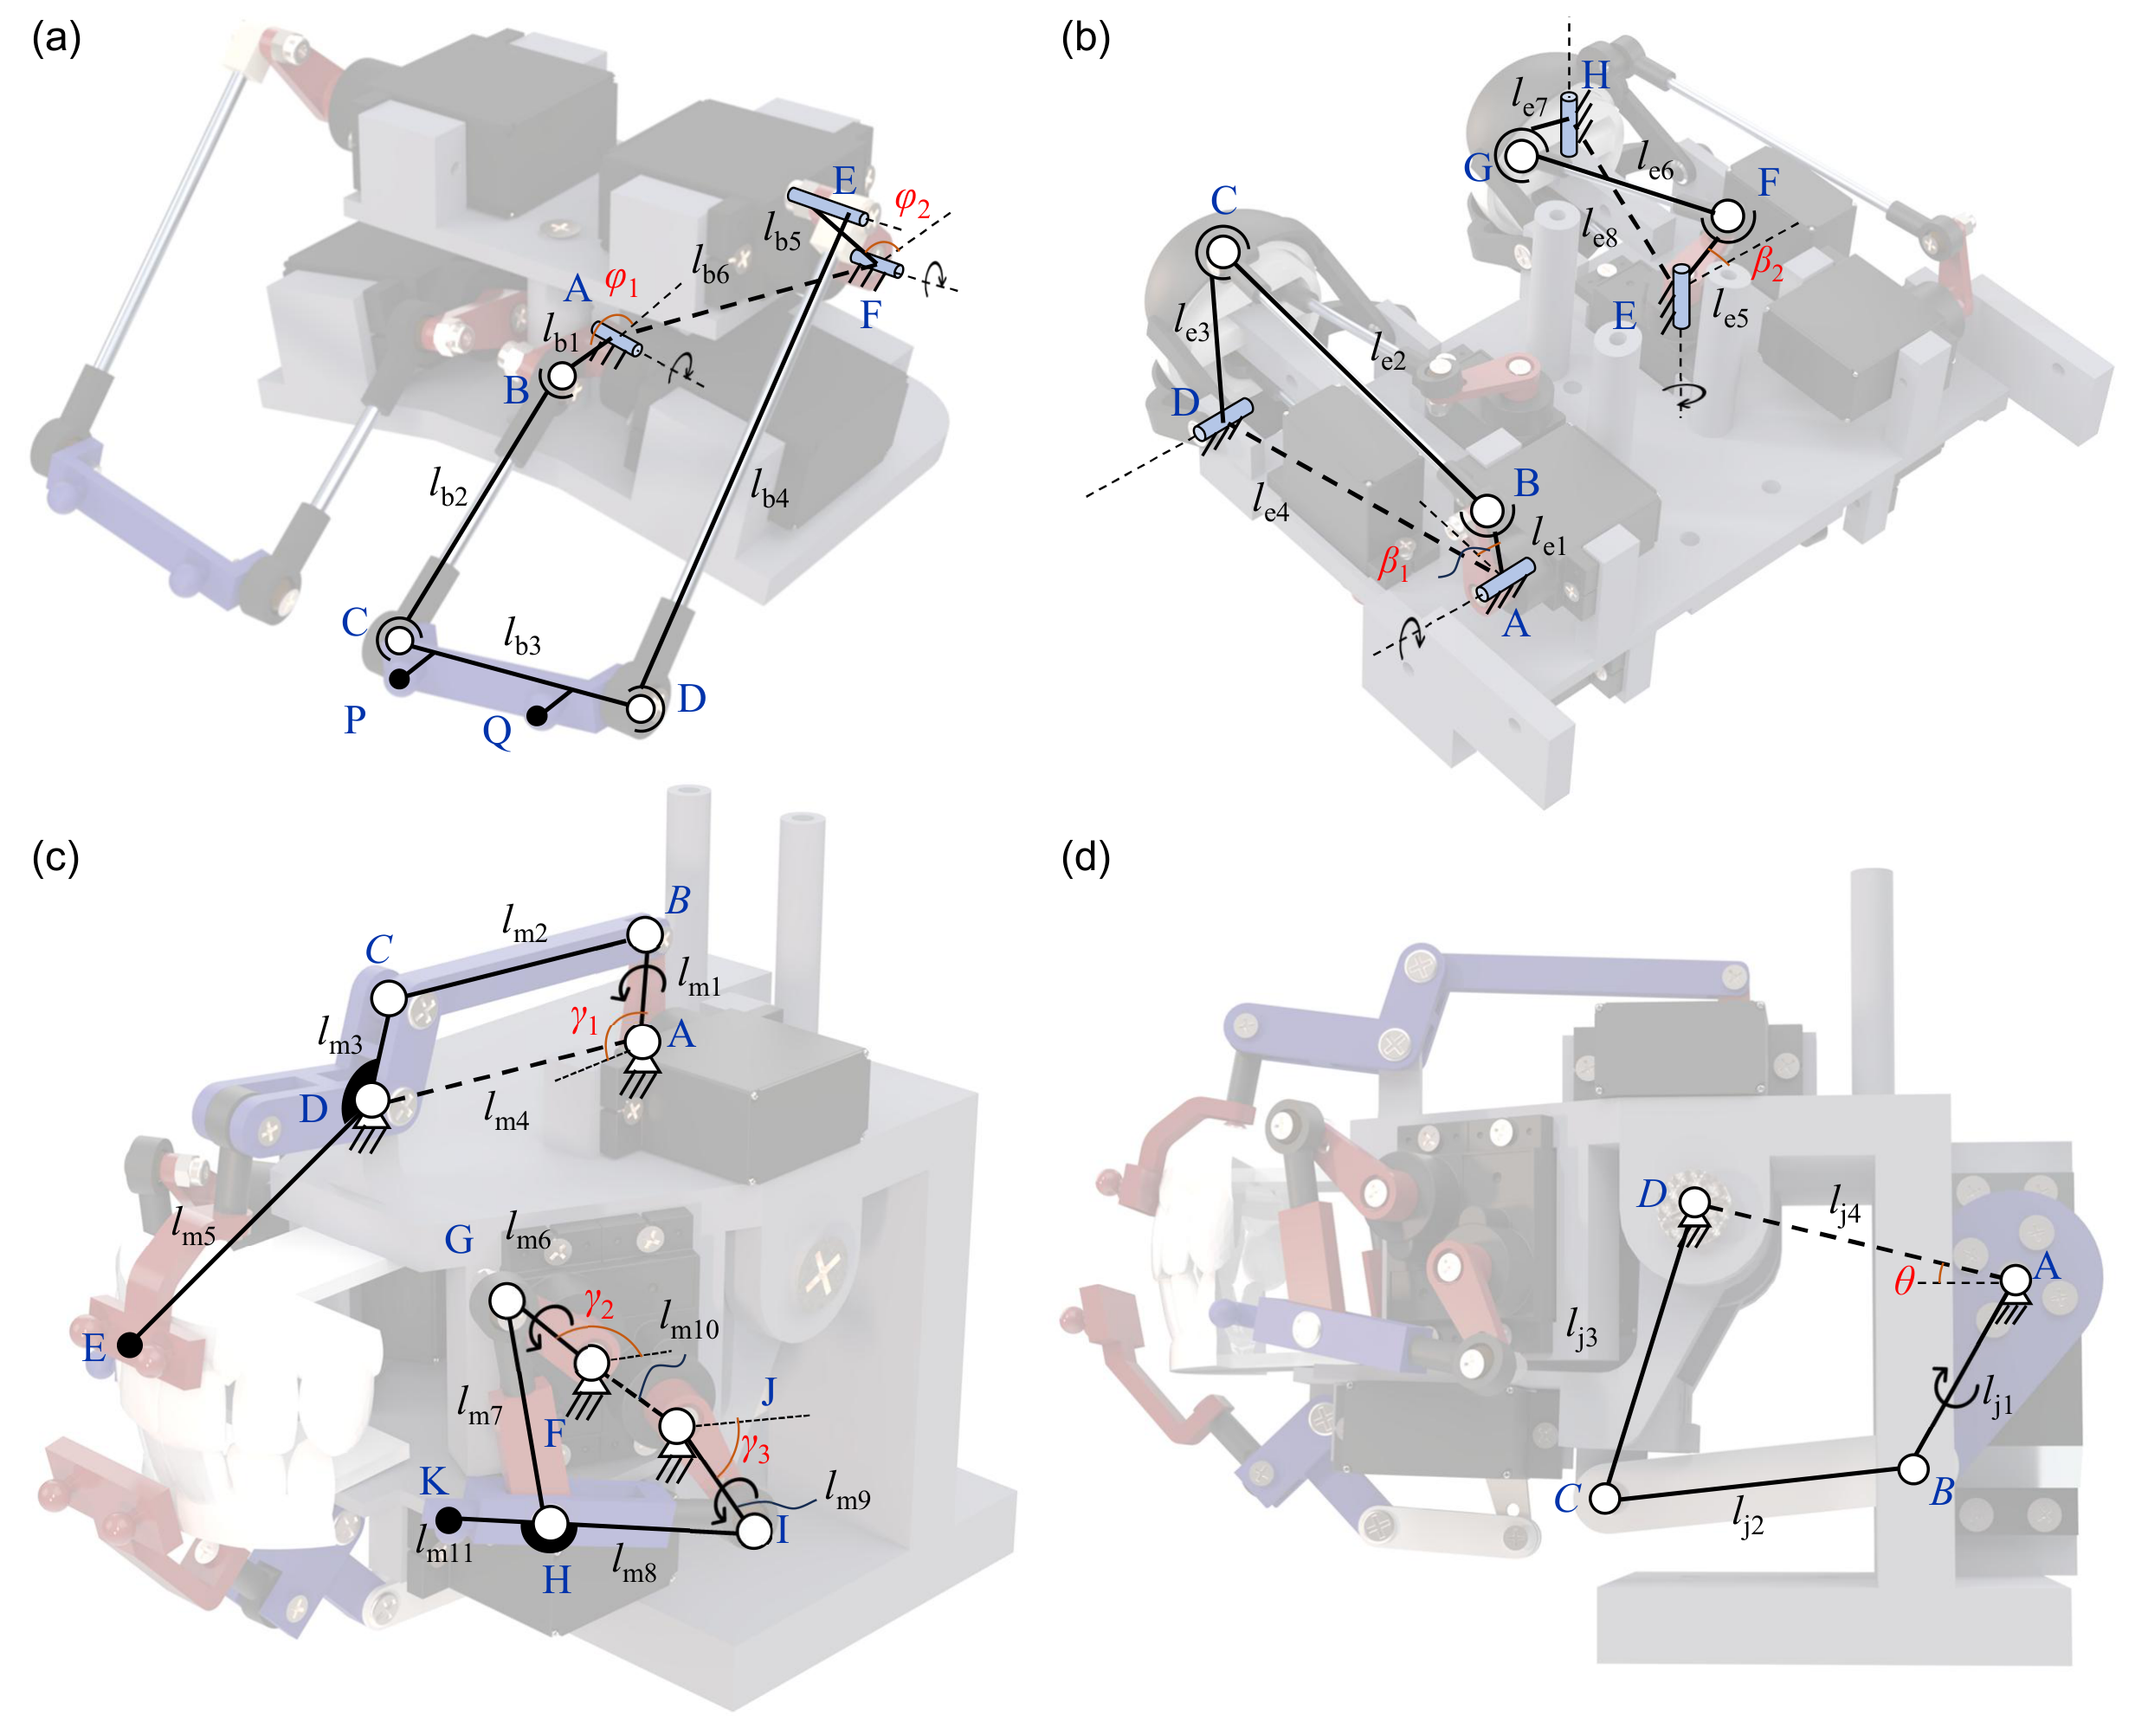
-C 1 Eyebrow module
The brow loop has three revolute and three spherical joints. The stated spatial mobility count is six; removing two passive axial twists and imposing two attachment-plane constraints yields two effective DoFs, assuming independent constraints.
Given two motor angles, six unknown coordinates for joints C and D satisfy three link-distance constraints, a revolute-axis constraint and two planar skin-attachment constraints. Newton–Raphson solves this closure system using the previous configuration as initialization. Its 6×6 closure Jacobian is monitored through determinant or minimum singular value. Local solvability and branch continuation require nonsingularity; a mobility count alone does not prove a globally unique assembly.
Equations A.1–A.16
| (A.1) |
| (A.2) |
| (A.3) |
| (A.4) |
| (A.5) |
| (A.6) |
| (A.7) |
| (A.8) |
| (A.9) |
| (A.10) |
| (A.11) |
| (A.12) |
| (A.13) |
| (A.14) |
| (A.15) |
| (A.16) |
-C 2 Eyes module
Each eye uses four four-bar linkages: two eyelids and two eyeball rotation inputs. The bilateral assembly therefore has eight DoFs, allowing independent coordinated gaze and eyelid control. The paper does not supply an equally detailed equation-by-equation eye closure derivation.
-C 3 Mouth module
Upper/lower lips use planar four-bar circle-intersection solutions followed by a fixed follower-link attachment offset. The two intersection branches correspond to alternate assemblies, selected by continuity and joint limits. A positive center separation and feasible link lengths are required; clamping a negative square-root argument to zero is a numerical convention, not proof that an infeasible loop closes.
Each mouth corner is a two-input planar five-bar mechanism. Two driven crank endpoints define a second circle intersection, with the explicit triangle inequality limiting reachability. A rigid extension maps the floating joint to the skin attachment. Varying link ratios, input angles and base orientation changes the feasible motion region used in synthesis.
Equations A.17–A.32
| (A.17) |
| (A.18) |
| (A.19) |
| (A.20) |
| (A.21) |
| (A.22) |
| (A.23) |
| (A.24) |
| (A.25) |
| (A.26) |
| (A.27) |
| (A.28) |
| (A.29) |
| (A.30) |
| (A.31) |
| (A.32) |
-C 4 Jaw module
Jaw opening uses a compact four-bar mechanism with two ground pivots. Its placement and geometry are fixed after coarse initialization rather than optimized together with the brow/lip/corner mechanisms.
-C 5 Neck module
The neck assumes a fixed platform origin with rotational motion. In a yaw-compensated frame, each crank-and-rod closure reduces to a scalar sinusoidal equation for one motor angle. A real solution requires the normalized right-hand side to lie within ±1 and a nonzero sinusoid amplitude.
Each side admits two inverse-sine branches; the controller chooses a branch inside joint limits nearest the previous command. At zero amplitude the closure is either infeasible or underdetermined, and the authors exclude that singular case from nominal operation. The original Euler-order and coordinate equations remain visible; the notes do not substitute a different convention.
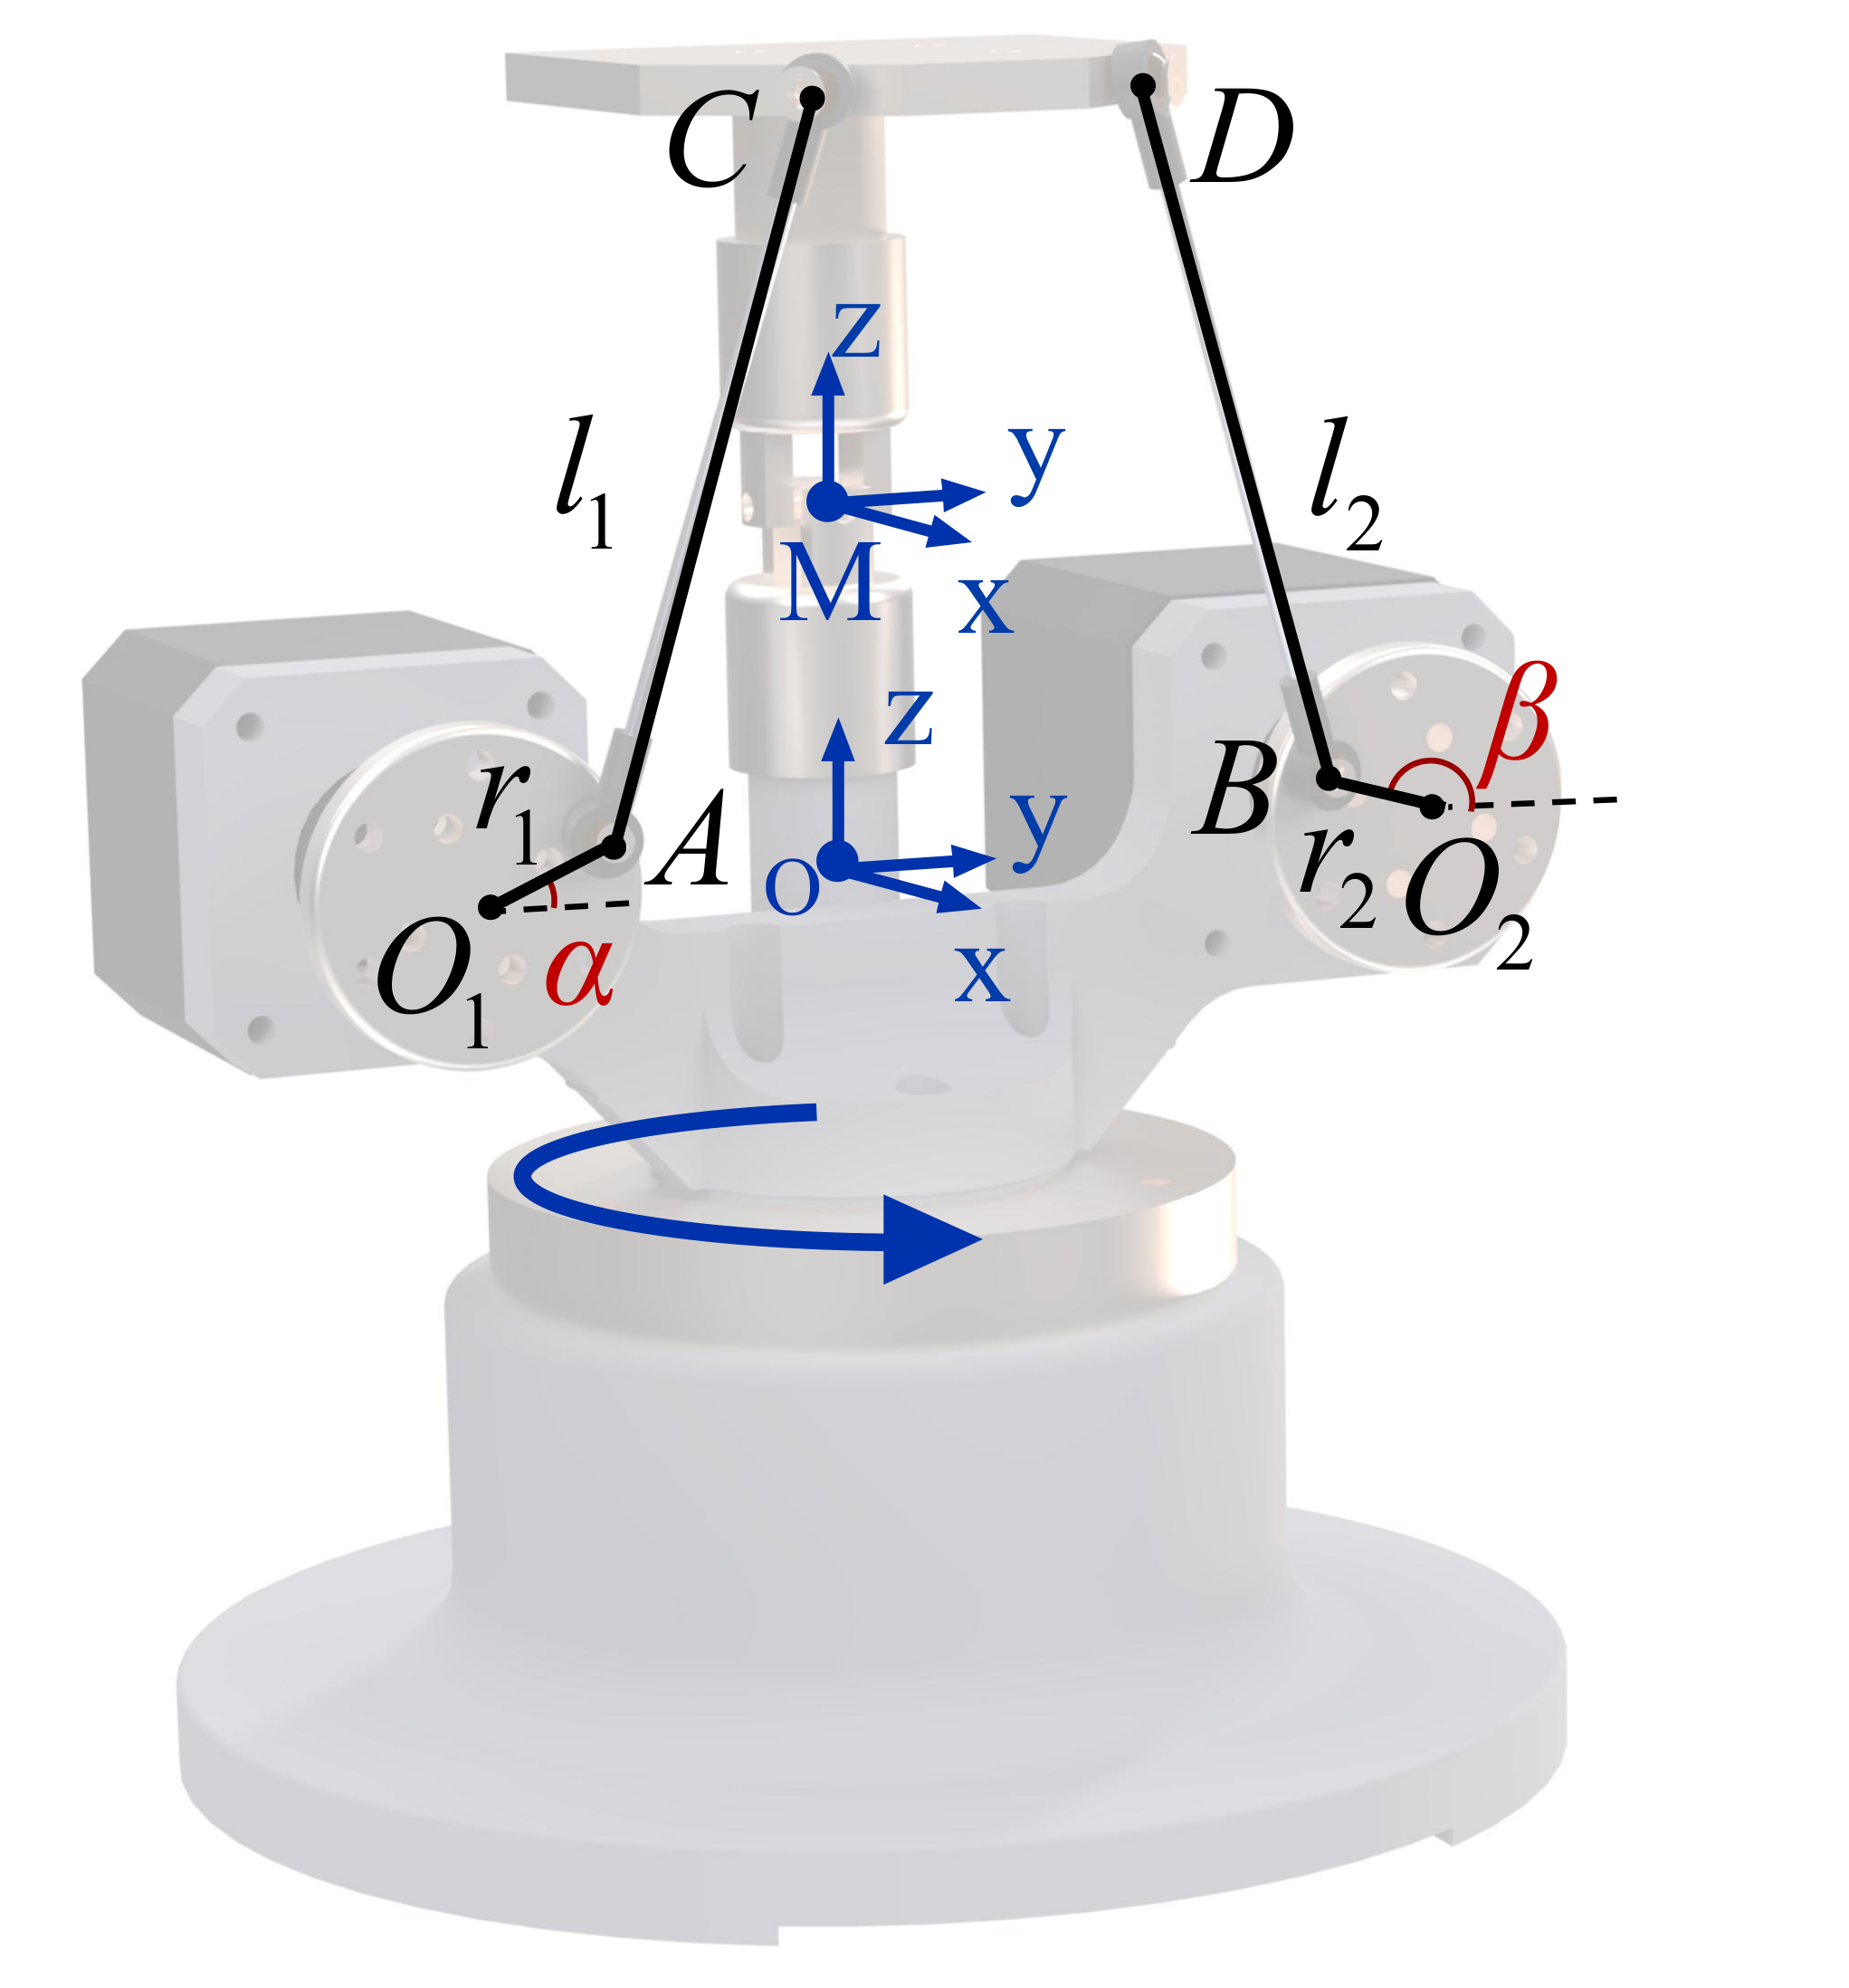
Equations A.33–A.47
| (A.33) |
| (A.34) |
| (A.35) |
| (A.36) |
| (A.37) |
| (A.38) |
| (A.39) |
| (A.40) |
| (A.41) |
| (A.42) |
| (A.43) |
| (A.44) |
| (A.45) |
| (A.46) |
| (A.47) |
-C 6 Architecture matters
Applying the same synthesis procedure to Morpheus yields 2/15 successes. Its tendon components are excluded because the current framework supports linkages only. This is evidence about compatibility of the retained linkage subset with this optimizer, not a comparison of complete Morpheus capabilities against the new hardware.
-D Optimization Algorithm Details
-D 1 Initialization of geometric parameters and layout
Brow bases follow scaled eye-to-brow template offsets. Eye centers and radii are fitted from landmark spheres, then adjusted for skin, eyelid and assembly clearance. Lip/corner attachments align with corresponding landmarks while initially retaining template link lengths. The jaw follows a scaled eye-to-jaw offset and remains fixed.
These initialization rules encode geometric priors; reconstruction, chosen physical scaling and the assumption that template relative placement transfers to a new face remain inputs to success.
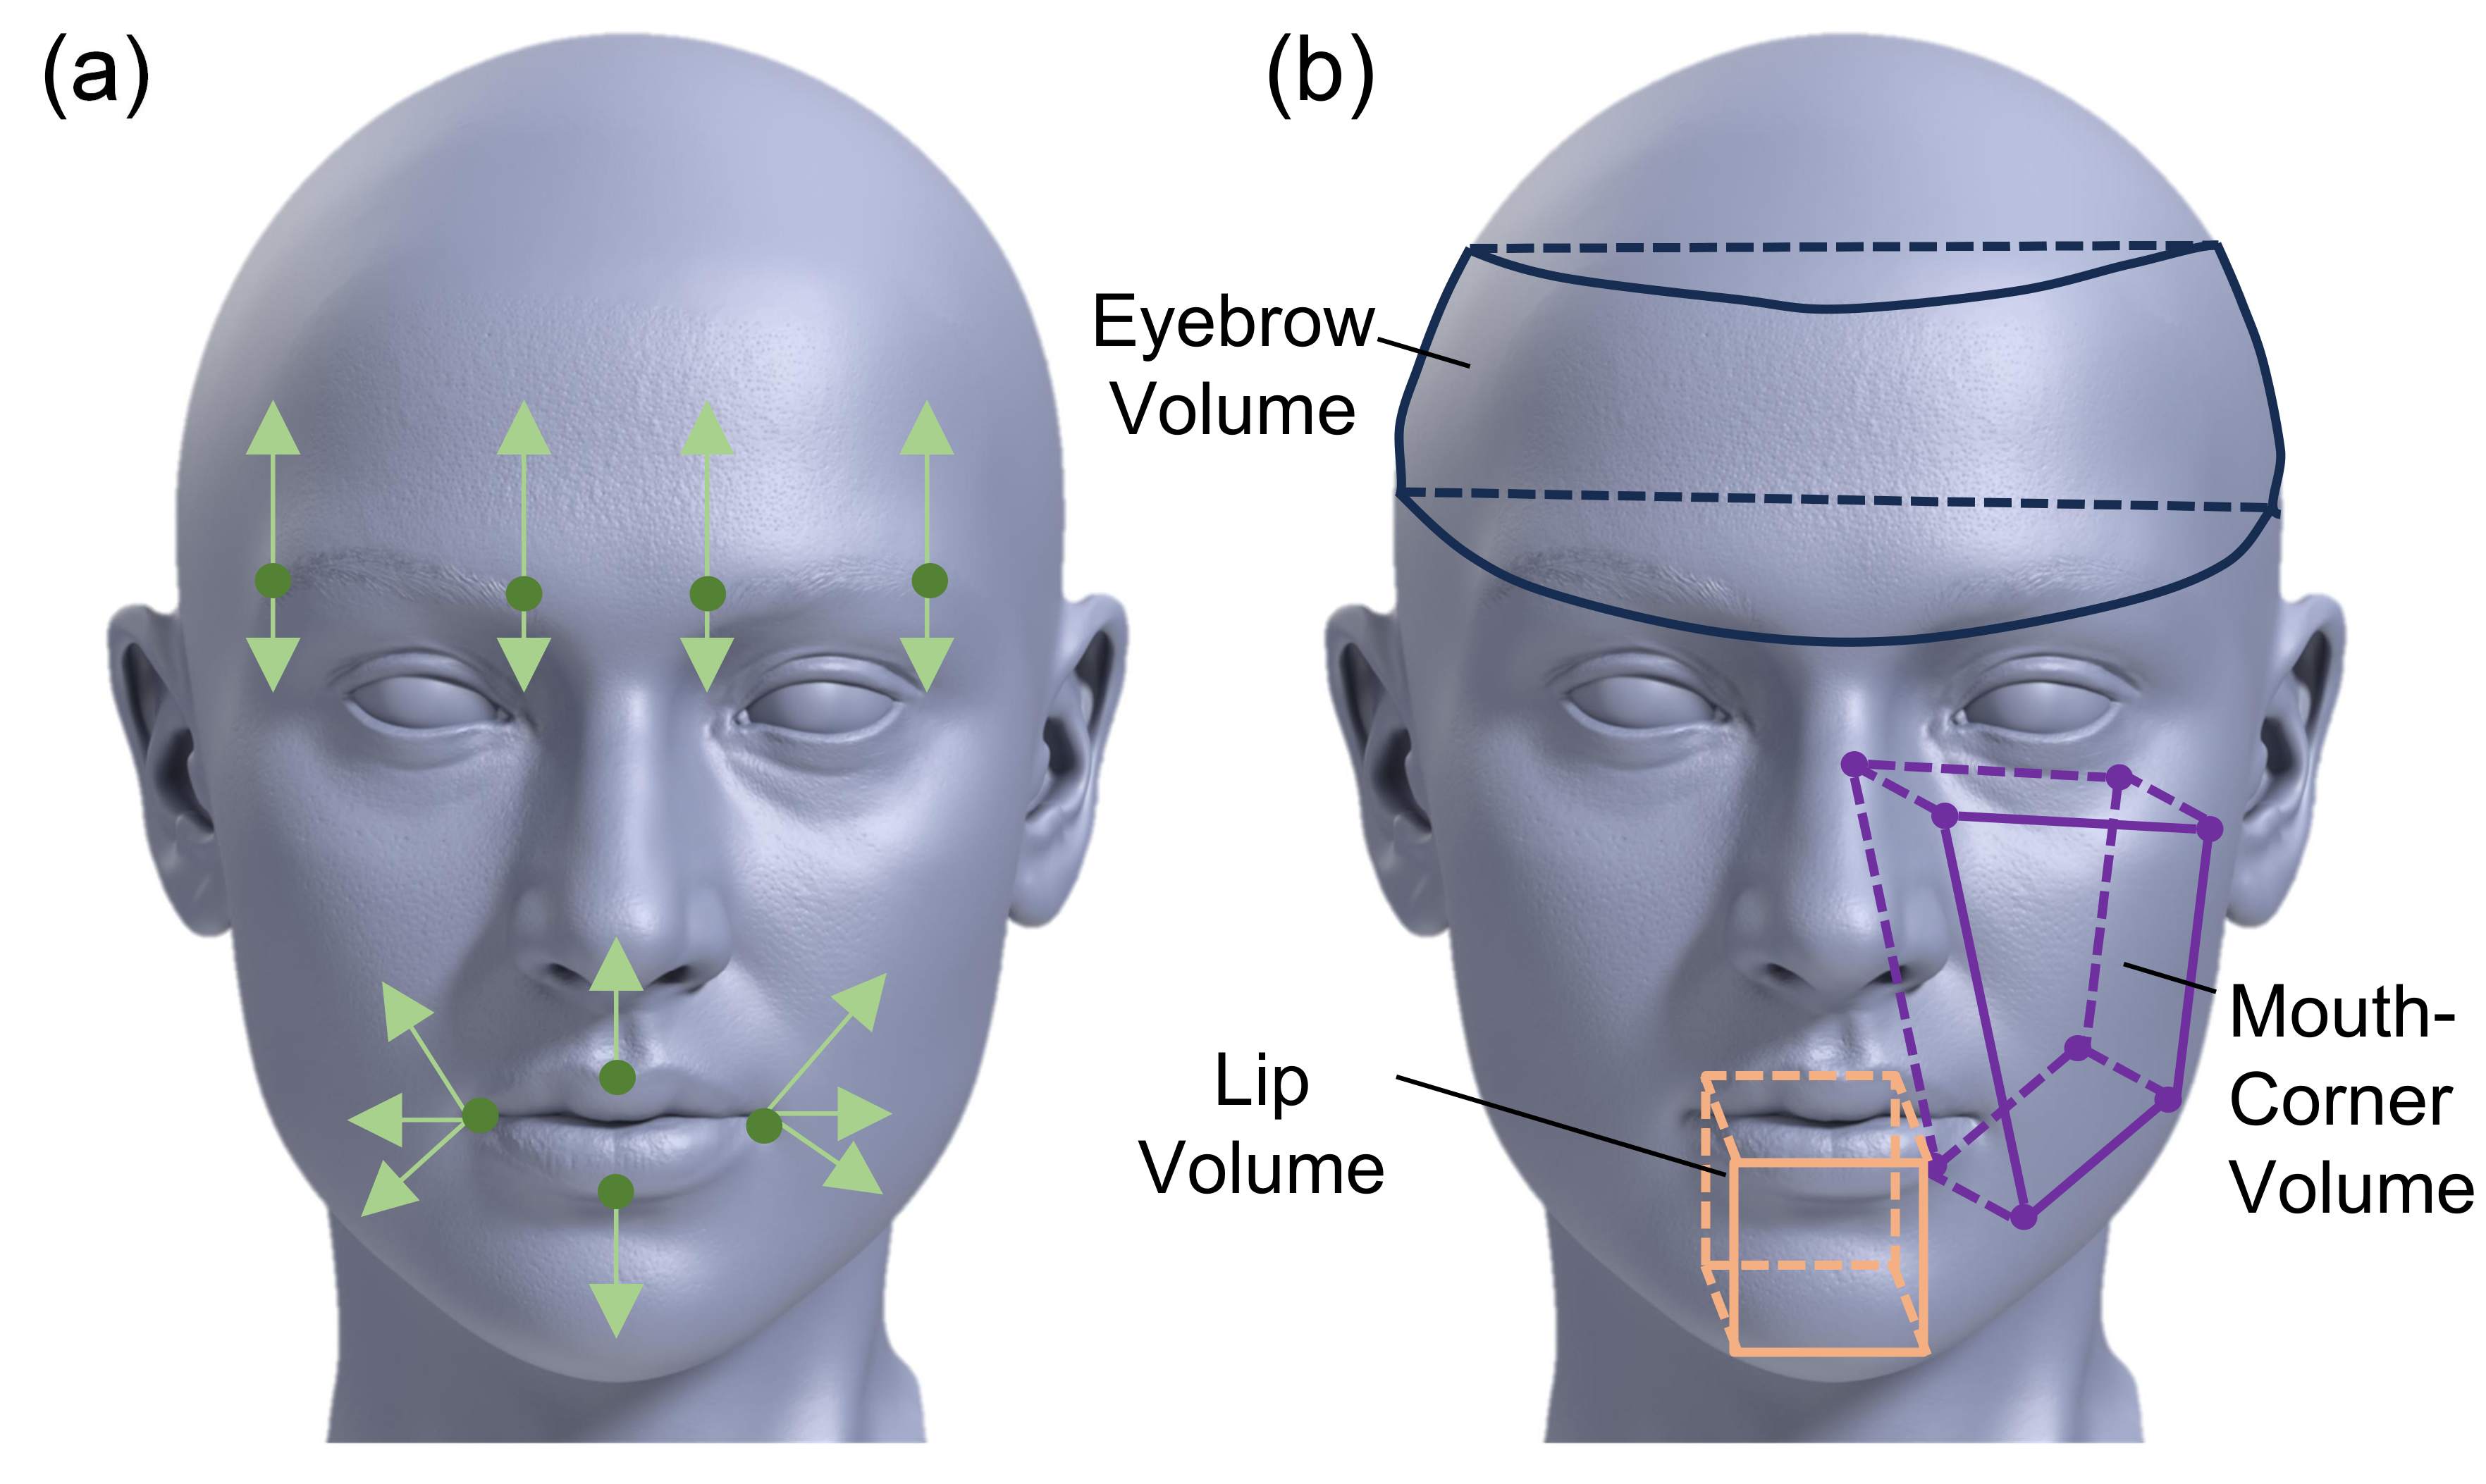
-D 2 Determine anatomy-guided feasible motion volumes
Brow attachment motion lies between planes 10 mm below and 50 mm above the lowest eyebrow landmark and the local face boundary. A cheek plane extruded 50 mm inward bounds corner motion. Lips remain within ±10 mm of the midsagittal plane and no more than 30 mm above neutral.
These envelopes constrain geometric motion; they are not a measured silicone deformation, stress or torque model. They retain sufficient freedom for search without proving that every enclosed configuration is physically comfortable or dynamically realizable.
-D 3 Determine AU-derived trajectories
Inner-brow and brow-peak attachments follow vertical targets, as do upper/lower lip midpoints. Corner targets span upward raising, lateral translation and downward pulling. Optimization scales these prescribed directions, rather than learning arbitrary expressions or changing mechanism topology.
-D 4 Optimization parameters
Table A.1 specifies eight trajectories, ten waypoints, amplitude floor 0.1 and initial ceiling 2.0. Amplitude, fit and manipulability weights are 1, 10 and 0.1. Inner L-BFGS uses at most one hundred iterations with tolerance 10⁻⁶; outer repair uses at most ten rounds, 0.5 mm clearance, a 3 mm shift threshold and 0.9 amplitude decay.
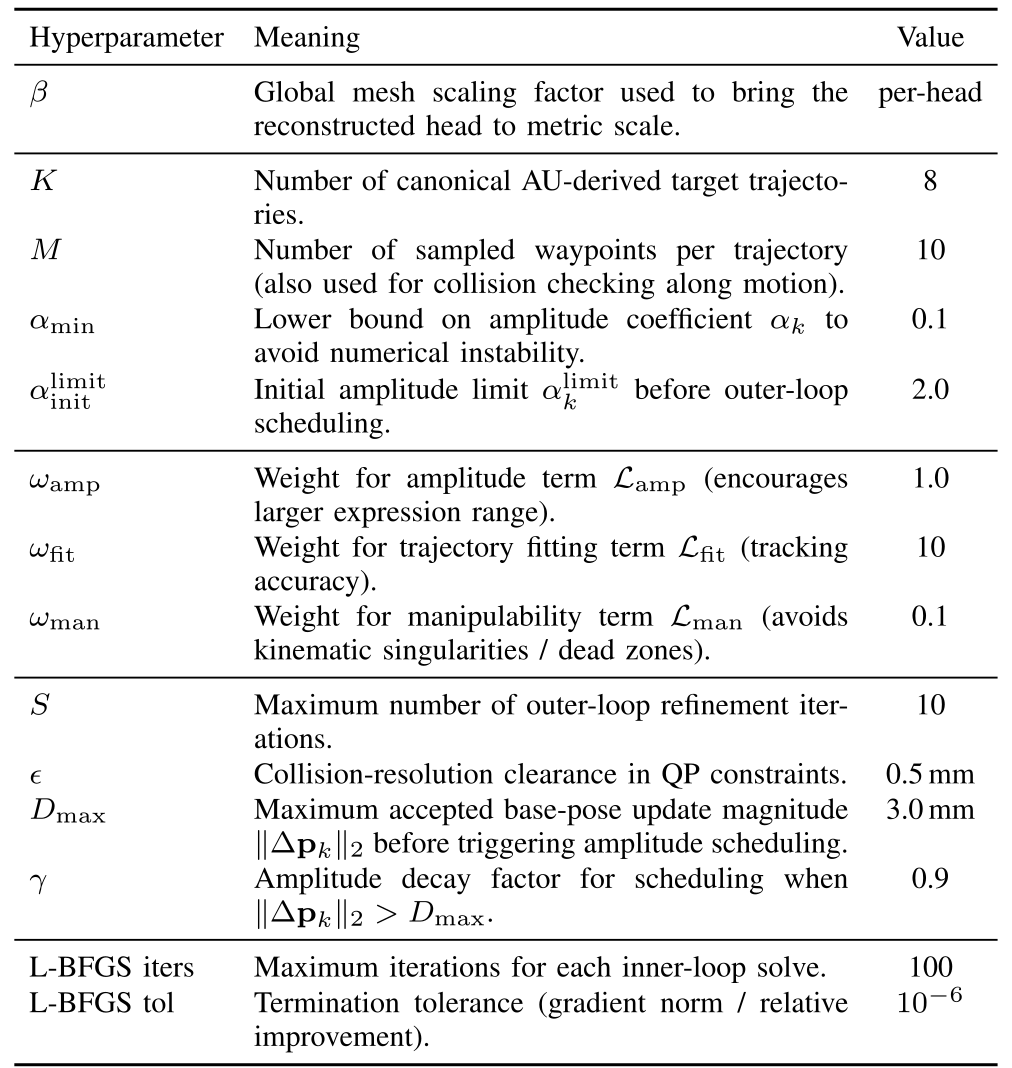
Original selectable table
| Hyperparameter | Meaning | Value |
| Global mesh scaling factor used to bring the reconstructed head to metric scale. | per-head | |
| Number of canonical AU-derived target trajectories. | 8 | |
| Number of sampled waypoints per trajectory (also used for collision checking along motion). | 10 | |
| Lower bound on amplitude coefficient to avoid numerical instability. | 0.1 | |
| Initial amplitude limit before outer-loop scheduling. | 2.0 | |
| Weight for amplitude term (encourages larger expression range). | 1.0 | |
| Weight for trajectory fitting term (tracking accuracy). | 10 | |
| Weight for manipulability term (avoids kinematic singularities / dead zones). | 0.1 | |
| Maximum number of outer-loop refinement iterations. | 10 | |
| Collision-resolution clearance in QP constraints. | 0.5 mm | |
| Maximum accepted base-pose update magnitude before triggering amplitude scheduling. | 3.0 mm | |
| Amplitude decay factor for scheduling when . | 0.9 | |
| L-BFGS iters | Maximum iterations for each inner-loop solve. | 100 |
| L-BFGS tol | Termination tolerance (gradient norm / relative improvement). |
-D 5 Baselines
Local-only optimization omits inter-module coupling. The global baseline merges mechanism objectives with base-position and squared collision-volume penalties in one problem. The heuristic baseline sums centroid-based repulsion directions and applies a fixed step rather than solving the minimum-translation program.
The printed global objective explicitly contains position and overlap penalties; the prose broadly describes relaxation of geometric constraints. These implementations evaluate particular solver/penalty choices, not the impossibility of every joint-optimization strategy.
Equations A.48–A.51
| (A.48) |
| (A.49) |
| (A.50) |
| (A.51) |
Equations A.52–A.53
| (A.52) |
| (A.53) |
-D 6 Diverse facial mechanism synthesis visualization
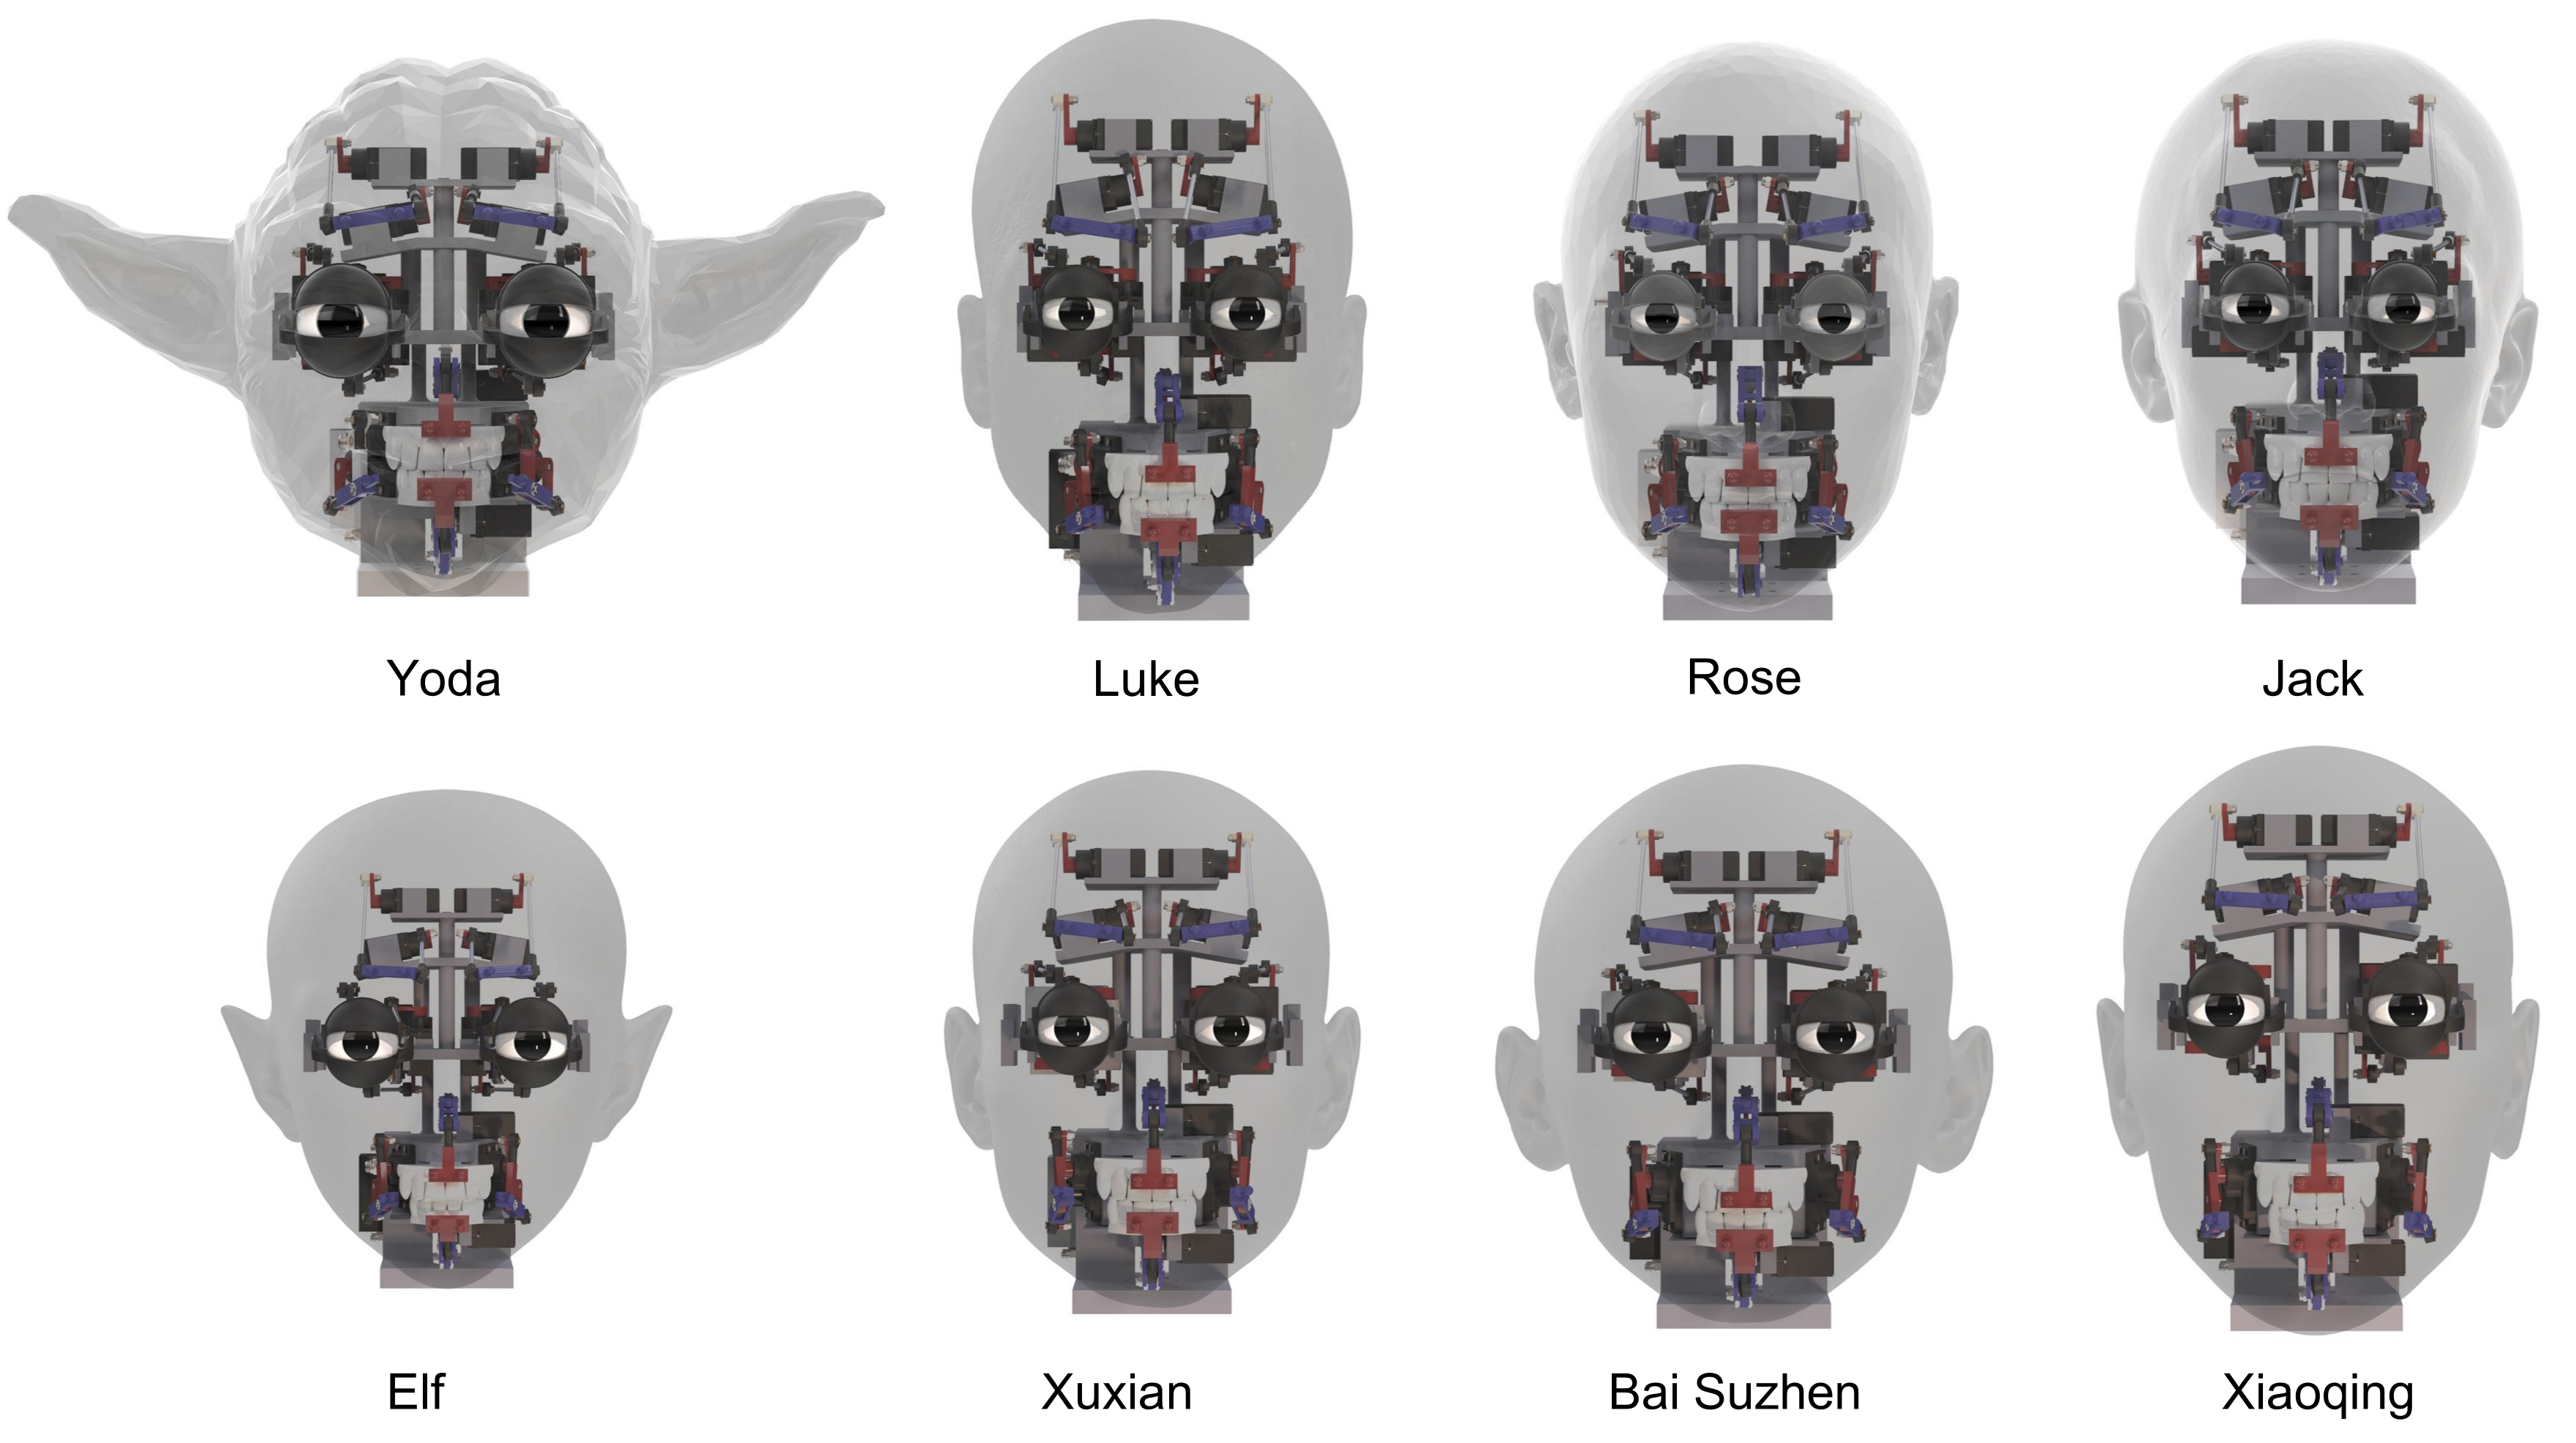
Eight selected successful assemblies illustrate a range of human, stylized and nonhuman faces, including Yoda, Luke, Rose, Jack, an elf and three White Snake characters. The relative-scale montage preserves all heads; it is a successful subset rather than the complete fifteen-case outcome distribution.
-D 7 Failure cases
A pointed chin can leave insufficient room for the fixed mouth mechanisms. Multi-module interlocking can also require topology changes rather than small translations, with mutually inconsistent separation constraints. The algorithm may stop with residual collisions or strongly reduced amplitudes; parameter adaptation alone cannot repair an empty feasible set.
-E Manufacture Details
-E 1 3D printed materials
PLA parts are produced on a Bambu Lab P1S with 0.1–0.2 mm joint clearances. Printing time sums component batches on one printer. These fabrication tolerances are supplied design choices, not a reported durability or repeatability characterization.
-E 2 Silicone face skin
Skin casting uses a printed outer mold and inner core with release agent. The two-part RTV silicone is mixed 1:1, vacuum-degassed for ten minutes at the stated −0.1 MPa and cured for four hours at 25 °C. The skin attaches magnetically to permit access and replacement.
-E 3 Actuator choice and noise testing
The chosen 180-degree microservos and three neck steppers serve different packaging/torque demands. The physical command loop is synchronized to 30 FPS animation. The paper reports an idle noise floor of 30 dB at 0.5 m.
Its claim that 60–65 dB conversational speech masks actuation noise is not accompanied by a measured active-motion noise level or controlled masking study. Idle noise alone does not establish that the robot is perceptually silent during movement.
-F Talking Head Synthesis Details
-F 1 Network architecture
Projected paired-audio features receive learnable time and identity-style embeddings. The activity gate interpolates the target and partner streams. Three-layer encoder and decoder stacks use width 256, four heads and feed-forward width 512. A turn-change-derived bias modifies attention logits, while motion queries carry sinusoidal positions.
An MLP expands to 512 then returns to 256 before the 55-coordinate output. A sigmoid bounds the fifty-two blendshapes; three Euler angles form the pose branch. The exact construction of the attention-bias matrix, causal protocol and complete latency are not specified by the supplied equation alone.
Equations A.54–A.56
| (A.54) |
| (A.55) |
| (A.56) |
-F 2 Loss function
Training combines framewise squared error over the 55-dimensional target with squared error between predicted and target first differences. This encourages matching observed motion and velocities. It is not simply a penalty forcing every velocity toward zero; the loss weights are named without numerical values here.
Equations A.57–A.60
| (A.57) |
| (A.58) |
| (A.59) |
| (A.60) |
-F 3 Training details
The conversational model uses Adam at learning rate 10⁻⁴ for two hundred epochs, batch size thirty-two, on four NVIDIA L20 GPUs. Reported training time is about twenty hours. The per-head inverse mapper has a separate, much shorter training stage.
-F 4 Evaluation metrics
LVE averages each frame’s maximum lip-vertex distance; coefficient MSE measures reconstruction. PDD compares the standard deviations of head-angle velocities, and FDD does the same for upper-face coefficients. Matching these statistics does not require matching the complete motion sequence.
SID is cluster-assignment entropy, favoring diverse generated motion. The appendix describes listener diversity although Table II places SID under the speaker columns; both source presentations are retained. Cluster count and uncertainty intervals are not supplied in this definition.
Equations A.61–A.63
| (A.61) |
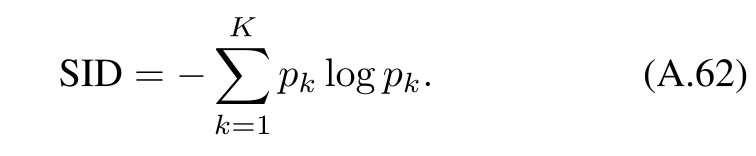
Original selectable MathML
| (A.62) |
| (A.63) |
-F 5 Dataset details
The data contain fifty hours, 1,052 identities and 5,858 clips averaging 2.5 turns, split into 5,282 training and 576 test clips. Interview-style YouTube material and RealTalk are filtered for visible faces, usable audio and natural turn-taking.
TransNetV2 segments scenes, tracked ordering keeps identities aligned, and SAM Audio separates synchronized 16 kHz streams. MediaPipe supplies fifty-two expression coefficients and three head angles per frame at 30 FPS. The stated split is by clips; an identity-disjoint test is not explicitly documented. Pseudolabel and audio-separation errors remain possible.
-G Mapping Network Details
-G 1 Baseline details
Landmark baselines use 468 two-dimensional points: nearest-neighbor command retrieval, min–max alignment plus a global MLP, or rest-relative scaling/clamping plus a global MLP. FLAME fitting yields shape, expression and pose descriptors, dropping fixed identity and global head rotation for the inverse regressor. The full fifty-two blendshapes provide another global-MLP baseline.
These alternatives differ in representation, preprocessing and interference between regions. Regional mapping uses semantic structure while retaining the same supervised calibration setting; no baseline provides a zero-calibration comparison.
Equations A.64–A.68
| (A.64) |
| (A.65) |
| (A.66) |
| (A.67) |
| (A.68) |
-G 2 Evaluation metrics
Audio and mouth-video windows are embedded by a pretrained synchronization model. LSE-D averages the minimum audio–visual distance over candidate temporal offsets. LSE-C averages the margin between the median offset distance and the best distance.
The search compensates for temporal misalignment, so a favorable score can coexist with constant delay inside the offset window. These metrics evaluate alignment quality under the stated matching rule rather than direct turn-response latency.
Equations A.69–A.72
| (A.69) |
| (A.70) |
| (A.71) |
| (A.72) |
-G 3 Semantic region-wise mapping network
The mouth/jaw mapper takes twenty-three blendshapes through 256/128 hidden layers with layer normalization, ReLU and 0.1 dropout. Seven outputs drive upper lip, lower lip, two motors for each corner and jaw. Other regional mappers reuse the architecture with different input/output sizes.
Calibration samples are randomly split 80/10/10. Adam uses learning rate 10⁻³, weight decay 10⁻⁵, batch 128, five hundred warmup steps and five hundred epochs. The reported approximately 0.02 MSE is a training loss, not a physical tracking distance or a documented held-out-test error.
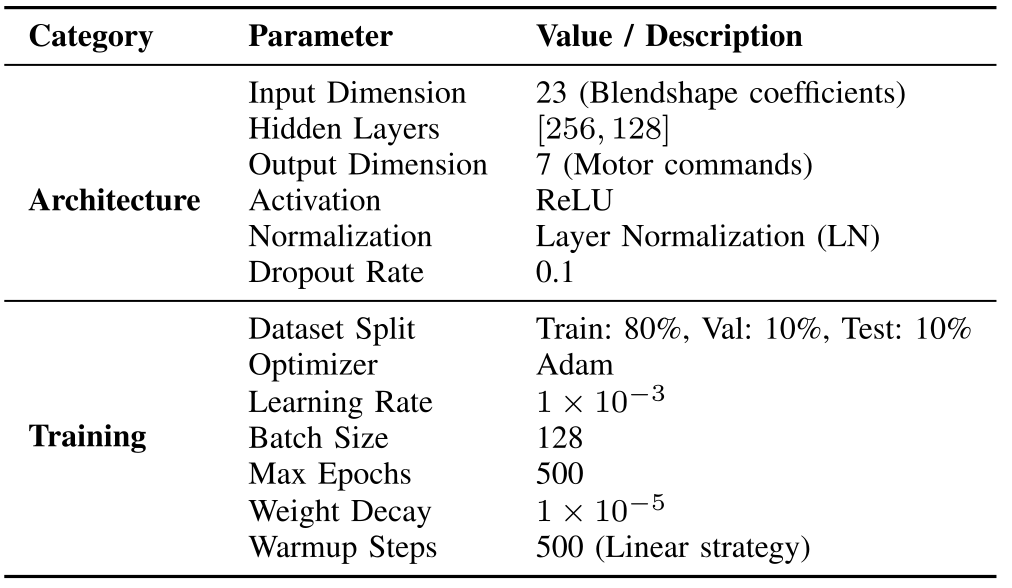
Original selectable table
| Category | Parameter | Value / Description |
| Architecture | Input Dimension | 23 (Blendshape coefficients) |
| Hidden Layers | ||
| Output Dimension | 7 (Motor commands) | |
| Activation | ReLU | |
| Normalization | Layer Normalization (LN) | |
| Dropout Rate | 0.1 | |
| Training | Dataset Split | Train: 80%, Val: 10%, Test: 10% |
| Optimizer | Adam | |
| Learning Rate | ||
| Batch Size | 128 | |
| Max Epochs | 500 | |
| Weight Decay | ||
| Warmup Steps | 500 (Linear strategy) |
-H Extended Visualization
The extended examples cover live human dialogue, paired physical characters and mixed digital/physical embodiment, with complete visual sequences retained. Narrative transcripts illustrate selected exchanges; they do not independently measure emotion understanding, social benefit or the robot’s subjective experiences.
-H 1 Real-time human-robot interaction
A semi-structured human–robot conversation explores the fictional theme of learning to be human. It demonstrates a selected live dialogue using the voice system, but the accompanying transcript provides no timed response distribution or controlled cross-language accuracy measurement.
-H 2 Dyadic robot-robot dialogue
The Titanic reunion and Yoda–Luke scenes stage affectionate and reflective dialogue with different speaking styles. Alternating facial activity and listener responses illustrate synchronized embodiment. The creative scenes are demonstrations, not a quantitative test of unrestricted autonomous conversation.
-H 3 Hybrid avatar-robot interaction
A screen avatar converses with a physical elf about remaining in the real world. This mixed embodiment illustrates reuse of the audiovisual/retargeting pipeline. Statements about feeling, smell or perception belong to the scripted character dialogue and are not measurements of robot experience or sensory capabilities.
-I User Study Details
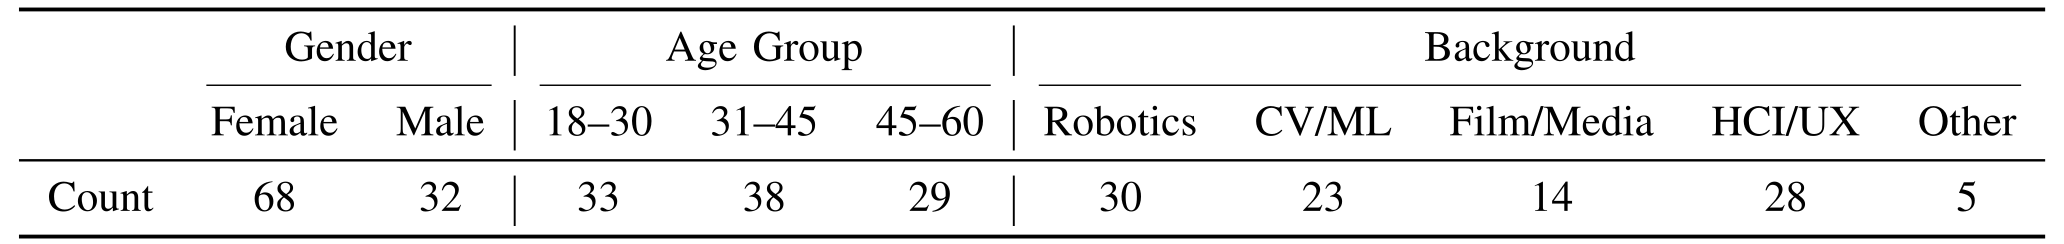
The hundred participants comprise sixty-eight women and thirty-two men; age groups 18–30, 31–45 and 45–60 contain thirty-three, thirty-eight and twenty-nine people. Self-reported backgrounds are robotics thirty, CV/ML twenty-three, film/media fourteen, HCI/UX twenty-eight and other five. This is the reported study sample, not a representative population claim.
-I 1 Study 1: Interaction performance on movie dialogue excerpts
Four reference-conditioned excerpts compare the complete system with speaker-only, no-neck, random-neck and mouth-only variants in randomized, single-blind order. The ten-point scale anchors poor through excellent overall naturalness, expression and coherence.
Complete-system means are 7.9–8.3, versus 6.4–7.2 speaker-only, 6.1–6.6 no-neck, 6.2–6.8 random-neck and 5.5–6.1 mouth-only. The source presents mean bars without dispersion or significance tests. These short video judgments support the tested combination of cues, not longitudinal engagement or a general causal explanation of every individual rating.
-I 2 Study 2: Perceived mapping quality.
Three short utterances compare six mappings after a reference avatar animation. Method order is randomized and identities concealed. Regional mapping receives the highest mean scores, followed by the stronger coefficient-based alternatives; nearest-neighbor landmarks are weakest.
The results align with the supplied synchronization metrics, while varying representation and regional structure together. They do not separately prove that a particular semantic decomposition is optimal across all faces or dialogue styles.
-J Limitations and Future Work
-J 1 Mechanical reconfigurability and modular extensibility
Rigid CAD-level placement burdens optimization when global facial proportions vary. Mechanically adjustable interpupillary spacing or module separation could ease adaptation, but this reconfigurable hardware is proposed rather than implemented in the reported template.
-J 2 Unified end-to-end learning framework
The audio, animation and retargeting stages can accumulate errors and add computation. Direct audio/text-to-actuator learning is proposed to reduce these costs; no such end-to-end physical learner or corresponding latency improvement is evaluated here.
-J 3 Differentiable simulation and sim-to-real adaptation
A material-aware differentiable simulator could model rigid–silicone coupling and supply synthetic calibration data. Accurate contact, skin properties and sim-to-real transfer remain future work, rather than existing guarantees of the geometric design optimizer.
-J 4 Towards full-body embodiment and interaction
The current platform actuates face and neck only. Coordinating torso posture and co-speech gestures is a proposed extension for whole-body interaction, requiring additional hardware, training and evaluation.