Reading guide
All fourteen pages and Appendices A–B are covered here, with six complete figures, six exact tables, five numbered equations, the original mathematical/protocol context and thirty references. The key idea is to supervise the input noise of a frozen generative policy using inverted expert corrections. Frozen weights preserve the base decoder, while the learned noise controller can still change performance on other tasks. The world-action extension also has a limited backpropagation step that the appendix makes explicit.
At a glance
FlowDAgger converts corrective actions into latent noise targets and trains a small observation-conditioned controller to reproduce them. This avoids full model finetuning and improves tested action-head, diffusion and world-action policies with interactive supervision. The inversion procedure and its costs differ by base family; fixed-point convergence is conditional, and world-action terminal inversion uses local gradients. Reported prior preservation is relative: held-out mean success still drops from 0.96 to 0.88, with a larger decline on one task.
1 Introduction
Large generative policies already contain useful behaviors, but deployment-specific failures motivate adaptation. Rather than editing model weights or adding arbitrary action residuals, FlowDAgger changes the noise entering the same frozen decoder. Expert corrections supply a supervised target after inversion. This is a different adaptation interface with promising sample/memory results, not a proof that every desired correction is representable, all generated actions remain high-probability under the original prior, or unrelated skills stay unchanged.
Original mathematical definitions, inversion conditions and experimental protocol
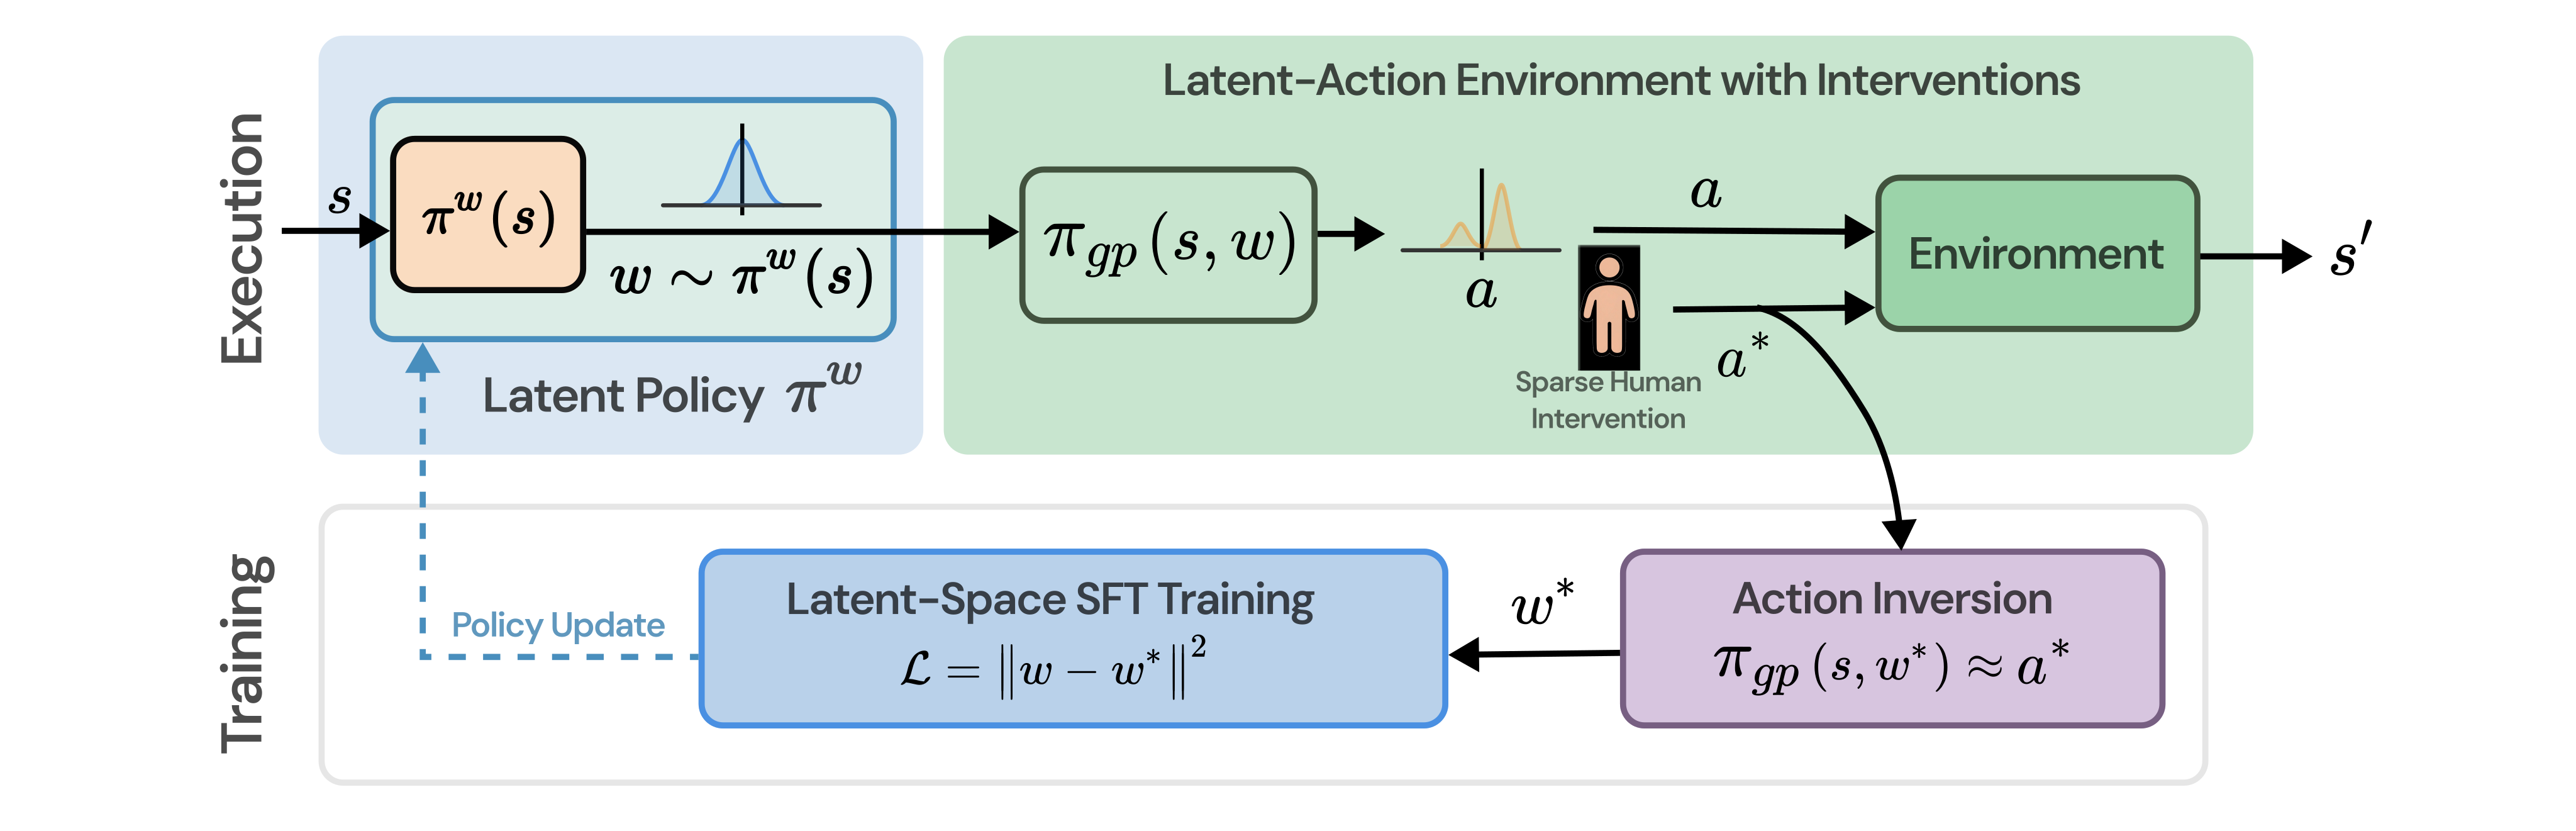
In this work, we adapt generative robot policies from human corrections by learning in the policy’s latent space. Prior latent-space methods show that a frozen generative policy can be steered effectively through its noise variables, but human experts intervene by providing corrective actions, not noise targets. Key to our approach is action inversion – a mechanism for mapping a human expert’s intervention actions into corresponding latent-space vectors via reverse-time integration and local refinement. Given an observation and an expert action , we invert to a noise vector such that the base policy’s generative process from at reproduces . Each pair becomes supervision for a small latent policy that operates within the generative process of the frozen base policy. We never modify the base policy’s weights, relying only on forward passes through the base model and adapting it entirely through its input noise.
2 Related Work
The paper connects generative manipulation, interactive imitation, residual learning, latent-space reinforcement learning and sample inversion. Its contribution joins human-gated on-policy corrections with noise-space regression, avoiding a task reward as the primary policy-training signal. Baseline differences in supervision and human effort still matter when comparing equal episode budgets.
Generative robot policies.
The target policies generate action chunks by transforming noise through a deterministic ODE-style sampler. Flow matching directly learns the velocity field; diffusion has a probability-flow interpretation. Applying the method to a particular deployed sampler requires inverting its actual discretization, conditioning and terminal transforms; it is not automatically applicable to every stochastic sampling scheme unchanged.
Interactive imitation and human-in-the-loop learning.
DAgger collects corrective labels on states visited by the current policy, addressing covariate shift relative to offline demonstrations. Human-gated variants decide when to intervene, and residual variants keep a base frozen while altering executed actions. FlowDAgger keeps the intervention loop but learns the correction before decoding, in noise space. Expert consistency and correction coverage remain requirements.
Latent and noise-space policy learning.
DSRL also steers a frozen policy’s noise but learns from task reward and autonomous exploration. FlowDAgger instead converts expert action labels to noise labels. This isolates a useful supervision choice, while stronger direct corrective information is not the same resource as sparse reward; matched rollout counts alone do not match expert time or annotation effort.
Inversion in generative models.
Image-model inversion motivates the reverse procedure, but few-step robot action samplers need a different treatment of discretization error. The method solves each Euler step’s implicit inverse, and the world-action case inverts a joint latent. The latter’s terminal denoising transform is locally optimized with gradients, as Appendix A explains. A single universal gradient-free recipe would omit that exception.
3 Background
The base decoder maps an observation and noise vector to a whole action chunk. A learned noise policy changes the resulting action distribution while keeping decoder parameters fixed. The equations define the sampler, its Euler approximation and the interactive correction setting; conditioning may include observation history. Decoder immutability and output-distribution immutability are different properties.
Generative action policies.
An initial Gaussian sample is integrated through a velocity field to obtain the action chunk. This deterministic map provides the inversion target for a fixed observation. The formal ODE description does not establish a narrow safe action manifold or high original-prior density for every noise a new controller might choose. Reachability and numerical conditioning can constrain usable inverses.
Original mathematical definitions, inversion conditions and experimental protocol
We consider a pretrained generative policy that maps an observation to a distribution over an action space , where is an action chunk of horizon . We use “observation” for the policy’s full input, which may include a history of past sensor readings. Given , the policy draws a noise sample from the noise space and transforms it into by integrating an ordinary differential equation (ODE) defined by a learned velocity field :
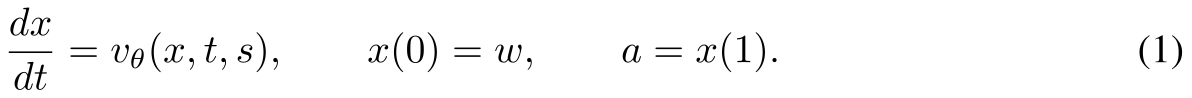
Original selectable equation
Equation 1
| (1) |
Original mathematical definitions, inversion conditions and experimental protocol
We write for the resulting noise-to-action map, , and for the action distribution it induces when . Both flow-matching [16] and diffusion policies [1] fit this description: the former learns the velocity field directly, while the latter’s reverse process admits an equivalent probability-flow ODE. FlowDAgger applies to any base policy of this form.
Euler discretization.
With K Euler steps, each update uses its current intermediate state and time. Few-step action heads use approximately ten steps, making their discrete inverse important. Reversing a continuous trajectory approximately is not identical to inverting the actual Euler map. Extra inversion iterations and verification passes add compute beyond ordinary action generation.
Original mathematical definitions, inversion conditions and experimental protocol
In practice, the map is evaluated with a -step Euler discretization of step size . With and , the action is produced by the recurrence
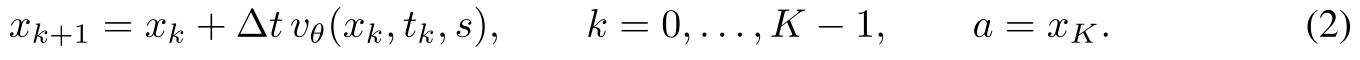
Original selectable equation
Equation 2
| (2) |
Original mathematical definitions, inversion conditions and experimental protocol
Flow-matching action heads typically use a small number of steps ( on the order of 10), in contrast to the long schedules ( in the 100s) common in image diffusion. This few-step regime is central to the inversion procedure in Section 4.1.
Noise as the adaptation surface.
Replacing Gaussian noise with a state-conditioned vector steers behavior through the unchanged decoder. The deployed noise policy is deterministic, so it can collapse or shift the base action distribution. There is no explicit density/divergence constraint proving the selected noise stays typical under the pretrained Gaussian. Preserving useful priors is evaluated empirically rather than guaranteed by frozen weights alone.
Original mathematical definitions, inversion conditions and experimental protocol
For a fixed observation , the base policy is a deterministic map from noise to action, so the noise sample alone determines the action. The action distribution is therefore controlled entirely by the distribution over . This exposes the noise space as a surface for adapting the policy without modifying : replacing the standard draw with a state-conditioned choice of steers the policy’s behavior while leaving the pretrained generative process intact [14].
Human-in-the-loop adaptation.
The operator overrides unsatisfactory behavior with an expert action at the current observation. These visited-state pairs define the correction data. The method does not need a hand-designed task reward for its main supervised update, but collecting corrections and identifying successful autonomous rollouts still requires supervision or outcome judgments. Intervention episodes contain multiple potential action corrections; episode count is not an action-label count.
Original mathematical definitions, inversion conditions and experimental protocol
We consider the standard interactive setting, where a human may intervene in behavior induced by a pretrained policy. At each step, the policy proposes an action; when the behavior is unsatisfactory, the expert takes over and provides a corrective action for the current observation . This yields correction pairs on states the deployed policy actually visits, as in DAgger [9]. Our goal is to use these corrections to adapt the policy efficiently – without modifying the base policy’s weights or using a reward signal.
4 Method
First invert corrections under the frozen sampler, then regress the resulting noise with a small controller while aggregating on-policy data. Action-head inversion and joint world-action inversion share that structure but have different variables and numerical details. Native equations and complete appendix conditions remain alongside the short notes.
4.1 Action Inversion
Starting at the expert action, solve each reverse Euler equation by repeated substitution, working backward through all K steps. This fixed-point map contracts when the step size times the velocity-field Lipschitz constant is below one. The paper does not establish a global bound ensuring that condition for every learned policy/state, and five iterations are an empirical default rather than an exact inverse guarantee.
Main-text cost is K×M forward velocity calls without sampler-chain backpropagation for action heads. Table 6 lists60 calls at K=10,M=5 versus the formula’s50, consistent with an additional K-call pass whose precise overhead is not explained. The reconstruction table supplies nonzero measured errors; ‘near zero independent of step size’ should be read with conditioning and finite-iteration limits.
Original mathematical definitions, inversion conditions and experimental protocol
Latent-space adaptation methods typically rely on rewards or supervision already expressed in the policy’s latent space. Human interventions, however, arrive as corrective actions. Action inversion converts these action-space corrections into noise-space supervision: given an observation and corrective action , it recovers a noise vector such that the frozen generative policy reproduces the correction, ; the pair is then a supervision target for the noise policy.
Original mathematical definitions, inversion conditions and experimental protocol
The map composes Euler steps (Section 3) and has no closed-form inverse, so we invert it one step at a time. Each forward step rearranges to the implicit equation , which we solve by fixed-point iteration:
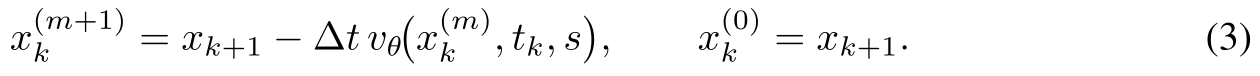
Original selectable equation
Equation 3
| (3) |
Original mathematical definitions, inversion conditions and experimental protocol
The right-hand side is a contraction in whenever ( the Lipschitz constant of in its first argument), so the iteration converges geometrically and a few steps suffice; we use (Section B.2). Running backward from recovers , and we take .
Original mathematical definitions, inversion conditions and experimental protocol
Solving each step’s implicit equation, rather than taking one explicit reverse pass, is what makes inversion reliable here. A single explicit reverse step evaluates the velocity at rather than , an discrepancy; this is negligible under image-diffusion schedules () but not for few-step action heads (, ). It is also more damaging here: robot actions are small, so an error negligible against image latents can be a large fraction of the action. The fixed-point solution of Equation 3 drives each step’s residual to near zero independent of ; Section B.1 compares against trajectory-level and optimization-based variants.
Original mathematical definitions, inversion conditions and experimental protocol
Inverting one correction costs evaluations of , requires no backpropagation through the base policy, and runs online as corrections are collected.
4.2 Inverting World-Action Models
World-action models jointly generate actions, future state and value, so an isolated action-head inverse is unavailable. The extension instead targets the complete generated latent tensor. It preserves the base state/value slices while editing the action slice, then inverts the joint process. This is a heuristic for keeping the edit small; a corrected action paired with the old predicted future is not thereby proven physically consistent.
Inverting the joint process.
Cosmos-Policy’s joint tensor has16×9×28×28=112,896 entries. Expert-minus-base action deltas edit its action frame while other clean-latent slices stay fixed. The EDM schedule ends at nonzero noise, requiring the extra terminal solve in Appendix A. Inversion always operates on the full joint process, even when the eventual controller emits a lower-dimensional basis code.
Original mathematical definitions, inversion conditions and experimental protocol
In Cosmos-Policy the generative variable is a joint latent tensor whose frames decode to the action chunk, predicted future states , and a value estimate (shape ). The forward sampler decodes this whole tensor with a shared denoiser, so we invert the same joint process: the reverse-ODE recovers a joint-latent noise of the same shape. We build the inversion target from the base policy’s own predicted clean latent , perturbing only the action frame: with the expert-minus-base action delta added to the action frame – a minimal-delta swap that stays on the base manifold – while the state and value frames are held at the base policy’s outputs. The reverse pass recovers a reproducing the full , not just the action slice, and supervises the noise policy as before. Cosmos-Policy uses an EDM-style schedule rather than a flow-matching ODE; the per-step inversion of Section 4.1 carries over with a small modification at the nonzero terminal noise level (Section A.1).
4.3 FlowDAgger: Human-in-the-Loop Adaptation
The noise policy is the trainable adaptation component; the foundation decoder remains frozen. Its observation encoder and MLP regress inverted correction targets, and training interleaves with deployment. The equal-mixture replay design retains autonomous behavior examples alongside corrections instead of fitting only the intervention states.
Noise policy.
At deployment the small policy deterministically proposes noise, which the base model decodes. This makes the new controller inexpensive compared with finetuning the decoder, but does not eliminate the base model’s inference cost or guarantee the same behavior on unseen observations. Its architecture, optimization and family-specific output parameterization affect transfer.
Original mathematical definitions, inversion conditions and experimental protocol
FlowDAgger adapts the base policy through a small noise policy – an observation encoder followed by an MLP, with its own parameters , separate from the frozen base policy. At deployment the base policy’s standard noise draw is replaced by , which is deterministic at deployment and is the only trained component, so the executed action is

Original selectable equation
Equation 4
| (4) |
Adaptation loop.
Corrections are inverted and accumulated across rounds. A second buffer stores the noise from successful autonomous transitions; each batch draws half from that buffer and half from interventions. This anchors training on behaviors that already work while keeping sparse corrections influential. Coverage, success selection and label consistency matter; equal sampling is not a proof of retained behavior outside those buffers.
Original mathematical definitions, inversion conditions and experimental protocol
FlowDAgger collects corrections on-policy, in the DAgger fashion [9]. The current policy is deployed with a human operator in the loop; when the operator judges its behavior unsatisfactory, they intervene with a corrective action , producing a correction pair on a state the deployed policy actually visited. Action inversion (Section 4.1) converts each correction into a noise-space target , which is added to a training set . The noise policy is trained to regress these targets by minimizing
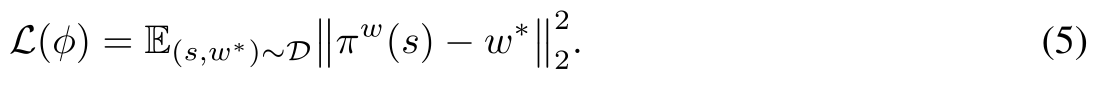
Original selectable equation
Equation 5
| (5) |
Original mathematical definitions, inversion conditions and experimental protocol
Deployment, correction, inversion, and training are interleaved: is aggregated across rounds, so later corrections target the states induced by the adapted policy. Corrections are sparse relative to the policy’s own transitions, so regressing on corrections alone overfits the handful of intervened states. FlowDAgger therefore structures as two buffers: inverted corrections fill an intervention buffer, while the noise that produced each transition of the policy’s successful autonomous rollouts fills a second buffer. Every training batch draws in equal proportion from the two. The autonomous buffer keeps anchored to the base policy’s behavior on states it already handles, while the fixed share keeps the sparse corrections prominent in every update.
5 Experiments
The evaluation tests adaptation efficiency, policy-family transfer, held-out skills and physical task performance. Simulation generally uses fifty extra episodes, with three seeds and twenty-five evaluation rollouts per seed unless noted. Appendix transfer curves instead use a single seed and fifteen rollouts per point. Hardware has a separate thirty-rollout caption and five-to-twenty correction-episode budgets; keep these protocols distinct.
5.1 Setup
MetaWorld supplies simulation tasks; FR3 Duo and Dual UR5e provide single-arm and bimanual real tasks. Primary base models are π0.5 and Cosmos-Policy, with Gr00t and a state-only diffusion policy tested in the appendix. Baselines alter weights, add residuals or learn noise from reward. Equal episode budgets do not equalize every labeled action, human minute, compute update or base pretraining resource.
Tasks and platforms.
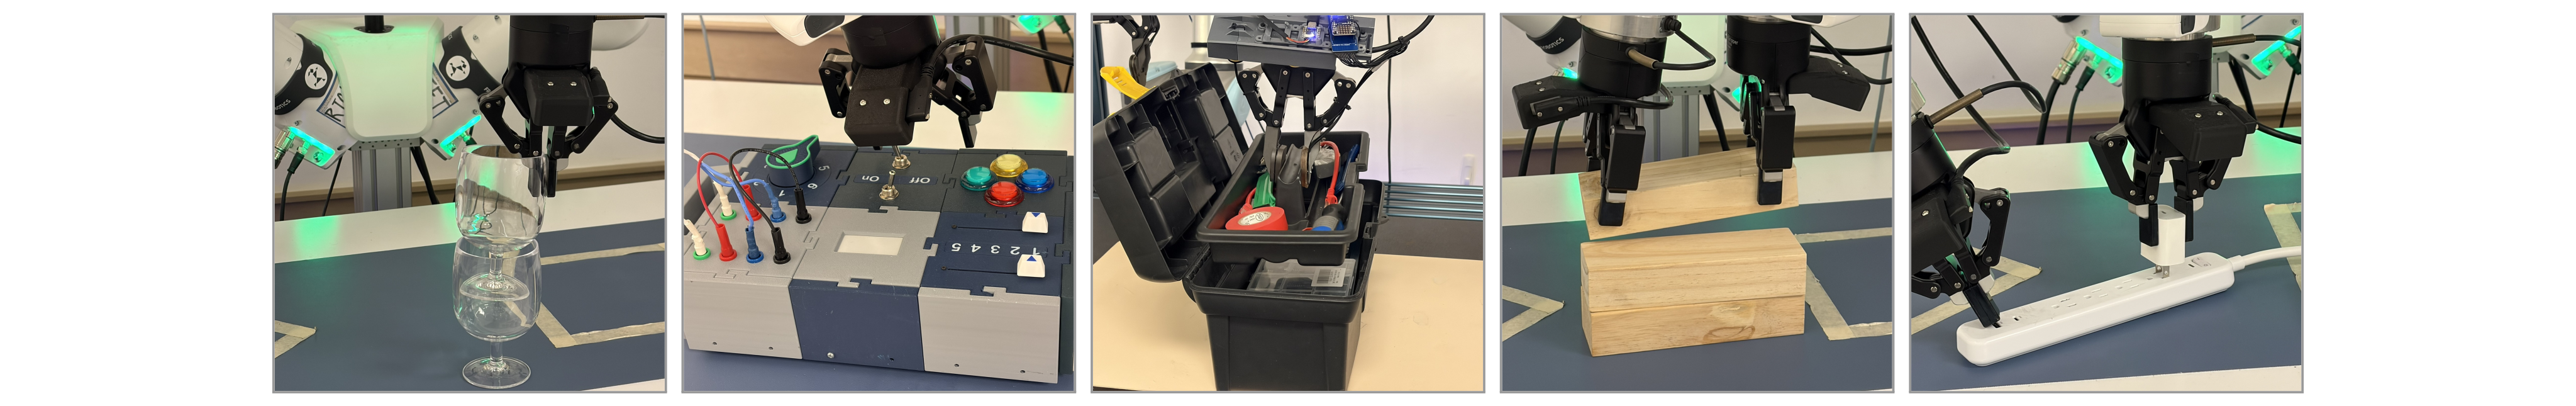
Real tasks span block picking, glassware stacking, BusyBox button/slider/wire actions, Jenga, toolbox packing and plug insertion. Two physical platforms broaden the setting, but each task remains a particular setup with a small evaluation sample. The representative photos and original before/after clips remain; clips are examples rather than additional evaluation trials.
Base policies.
π0.5 exercises action-head inversion, while Cosmos-Policy requires joint world-action inversion. Appendix Gr00t and diffusion experiments add architectural breadth but each covers a single task with a single seed. Family transfer here means the adaptation idea works on those tested models, not that one learned noise controller transfers unchanged between models or embodiments.
Original mathematical definitions, inversion conditions and experimental protocol
We adapt a state-of-the-art representative of each major generative architecture family: [2], an action-head VLA, and Cosmos-Policy [4], a WAM. uses the action-space inversion of Section 4.1; Cosmos-Policy exercises the joint world-action inversion of Section 4.2. Appendix B reports analogous results for a second VLA (Gr00t N1.7 [3]) and a vanilla diffusion policy [1], confirming the findings are not specific to these two base policies.
Baselines and protocol.
SFT uses offline demonstrations and full-weight behavior cloning; LoRA-DAgger and residual DAgger use the correction stream in different adaptation spaces; DSRL uses sparse reward and autonomous exploration. The usual budget is fifty additional rollouts with three-seed evaluation. These comparisons test both the adaptation interface and different available supervision, so the advantage over reward-only learning should not be attributed solely to an optimization trick.
Original mathematical definitions, inversion conditions and experimental protocol
We compare against baselines spanning the adaptation design space. The frozen base policy fixes the starting performance. SFT applies full-weight behavioral cloning to offline demonstrations, isolating the covariate-shift correction on-policy supervision provides. LoRA-DAgger and Residual-DAgger consume the same human-gated correction stream as FlowDAgger but apply each correction in low-rank weights and an action-space residual, respectively, isolating the effect of adapting in noise space. DSRL [14] also adapts in noise space but learns from sparse reward and autonomous exploration rather than corrections, isolating the supervision signal. Unless noted, every method gets a matched budget of additional rollouts (on-policy with optional intervention for the correction-based methods, offline demonstrations for SFT, autonomous for DSRL), and we report mean success rate over seeds, rollouts each.
5.2 FlowDAgger adapts π0.5 from a handful of corrections
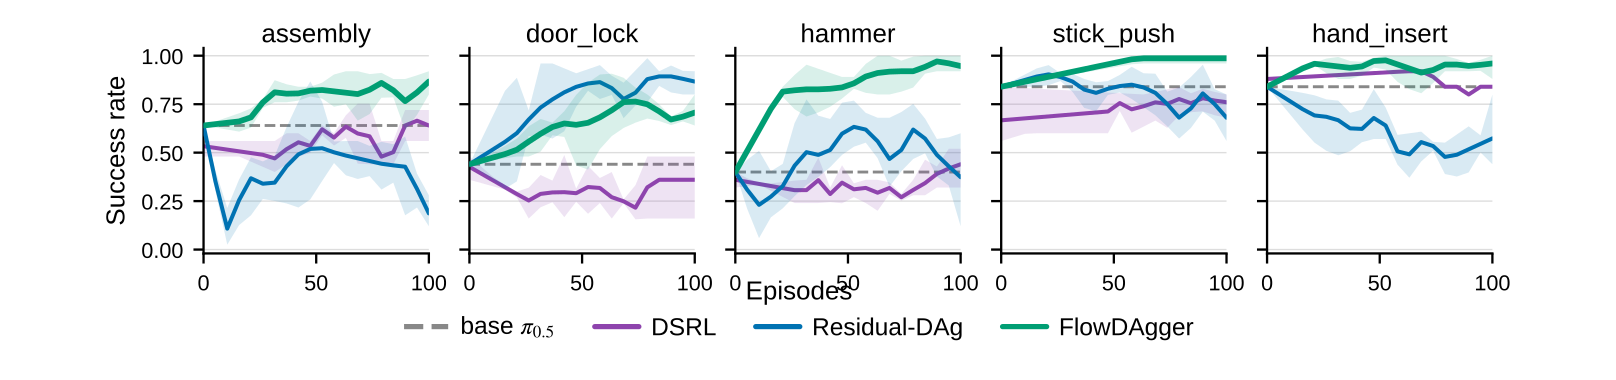
Across twelve MetaWorld tasks, FlowDAgger’s mean success is 0.78 versus 0.53 frozen and 0.71 SFT, and it leads on eight tasks. It is not best on bin picking, box close, dial turn or door lock. The five learning curves illustrate faster gains and fewer collapses in the displayed settings, but three-seed min/max shading is not a confidence interval or a proof of universal stability. The frozen decoder still has to represent a useful correction.
Original model notation in the section title
Section title:
Original mathematical definitions, inversion conditions and experimental protocol
Table 1 compares FlowDAgger against every baseline on twelve MetaWorld tasks with as the base policy. FlowDAgger gives the largest mean improvement over the frozen base () and wins on eight of the twelve tasks. The action- and weight-space DAgger baselines consume the same correction stream but gain far less, so the advantage comes from where the correction is applied, not from the corrections alone. DSRL barely moves the base: a sparse reward and autonomous exploration cannot discover in rollouts the corrective behavior a handful of interventions supply directly. Figure 3 shows the same over training: FlowDAgger climbs fastest and highest and rises smoothly on all five tasks, while Residual-DAgger learns erratically, oscillating on Hammer and climbing then collapsing below the base on Assembly and Hand Insert.
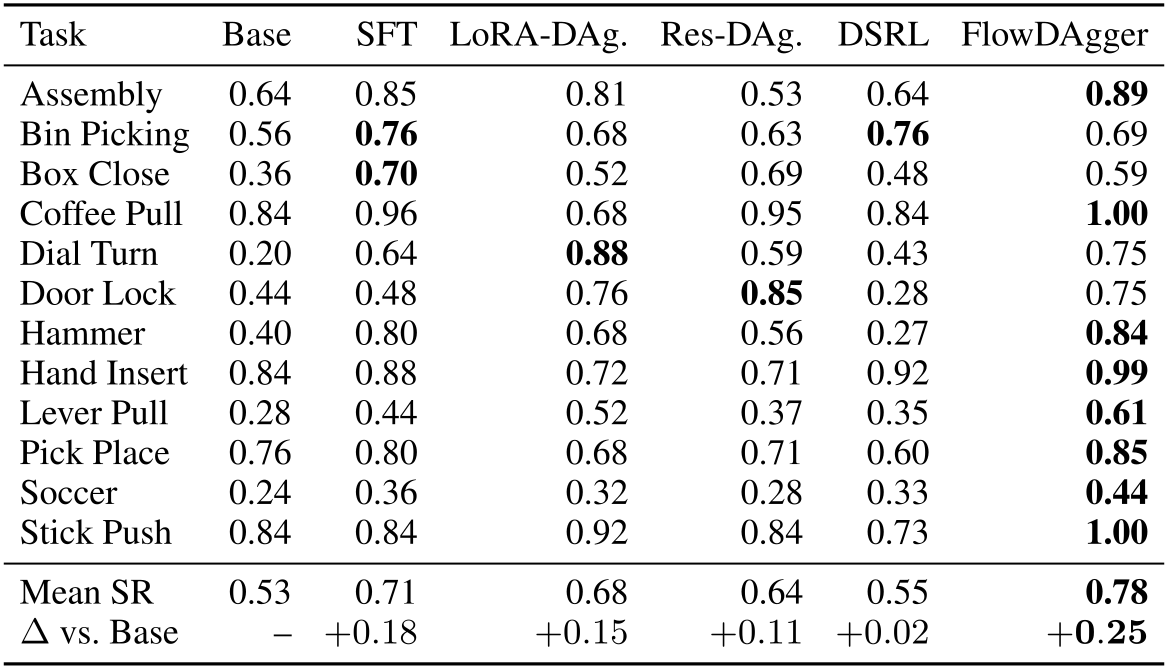
Accessible original table, all values and grouped headers
| Task | Base | SFT | LoRA-DAg. | Res-DAg. | DSRL | FlowDAgger |
|---|---|---|---|---|---|---|
| Assembly | 0.64 | 0.85 | 0.81 | 0.53 | 0.64 | 0.89 |
| Bin Picking | 0.56 | 0.76 | 0.68 | 0.63 | 0.76 | 0.69 |
| Box Close | 0.36 | 0.70 | 0.52 | 0.69 | 0.48 | 0.59 |
| Coffee Pull | 0.84 | 0.96 | 0.68 | 0.95 | 0.84 | 1.00 |
| Dial Turn | 0.20 | 0.64 | 0.88 | 0.59 | 0.43 | 0.75 |
| Door Lock | 0.44 | 0.48 | 0.76 | 0.85 | 0.28 | 0.75 |
| Hammer | 0.40 | 0.80 | 0.68 | 0.56 | 0.27 | 0.84 |
| Hand Insert | 0.84 | 0.88 | 0.72 | 0.71 | 0.92 | 0.99 |
| Lever Pull | 0.28 | 0.44 | 0.52 | 0.37 | 0.35 | 0.61 |
| Pick Place | 0.76 | 0.80 | 0.68 | 0.71 | 0.60 | 0.85 |
| Soccer | 0.24 | 0.36 | 0.32 | 0.28 | 0.33 | 0.44 |
| Stick Push | 0.84 | 0.84 | 0.92 | 0.84 | 0.73 | 1.00 |
| Mean SR | 0.53 | 0.71 | 0.68 | 0.64 | 0.55 | 0.78 |
| vs. Base | – |
Compute efficiency.
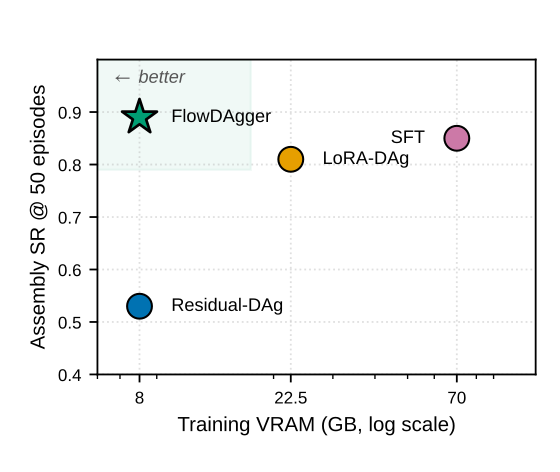
The approximately 8 GB training footprint is reported for adapting π0.5 with the small noise policy; the comparison plot uses Assembly at fifty episodes. This supports a memory advantage for that configuration, not an eight-gigabyte bound for every world-action model or a full latency/energy benchmark. Inversion, base inference and expert collection still cost time, and appendix inversion timings use an RTX 5090.
Original mathematical definitions, inversion conditions and experimental protocol
Because FlowDAgger trains only a small noise policy, adaptation fits in the same GB that deploying already requires. It can therefore run on a single consumer GPU. Figure 4 plots success rate against this training footprint, where FlowDAgger sits alone in the upper-left – as accurate as any baseline at a fraction of the memory.
5.3 Adaptation transfers across base-policy families
On seven shared MetaWorld tasks, π0.5 improves from 0.53 to 0.79 mean success and Cosmos-Policy from 0.53 to 0.74. The latter gain comes from full joint inversion despite no separable action head. These are within-model improvements from different pretrained bases; they do not isolate every pretraining or action-representation difference. Gr00t and diffusion appendix results support breadth with narrower statistical coverage.
Original mathematical definitions, inversion conditions and experimental protocol
The same noise-space adaptation procedure works across generative policy families. Table 2 applies FlowDAgger to , an action-head VLA with action-space inversion, and to Cosmos-Policy, a WAM with joint world-action inversion. The gains are comparable on both, even though Cosmos-Policy produces actions only as slices of a joint world-action latent rather than from a separable action head. This suggests that FlowDAgger does not depend on an action-only generative process. Appendix B extends the result to Gr00t N1.7 and a diffusion policy.
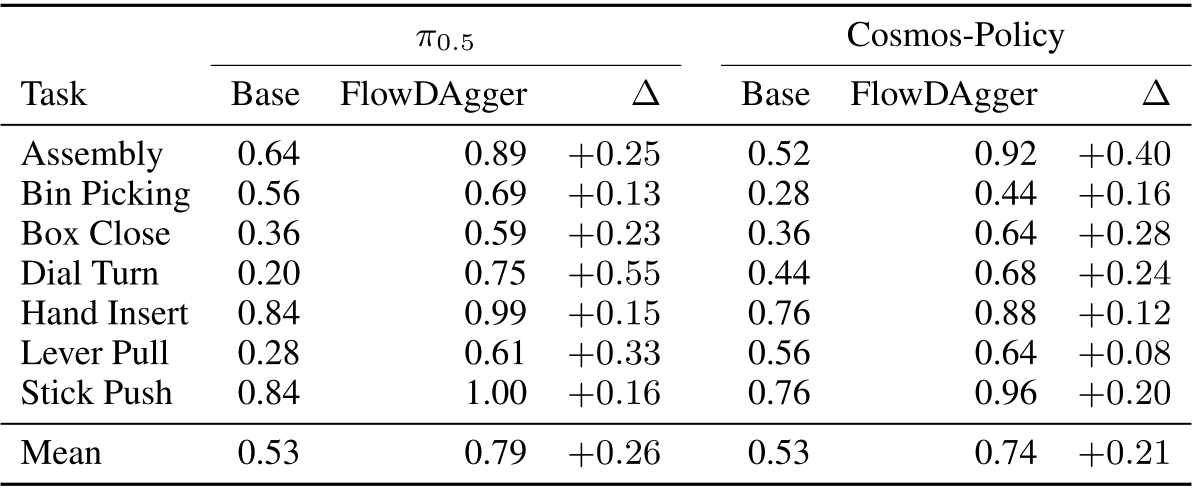
Accessible original table, all values and grouped headers
| Cosmos-Policy | |||||||
|---|---|---|---|---|---|---|---|
| Task | Base | FlowDAgger | Base | FlowDAgger | |||
| Assembly | 0.64 | 0.89 | 0.52 | 0.92 | |||
| Bin Picking | 0.56 | 0.69 | 0.28 | 0.44 | |||
| Box Close | 0.36 | 0.59 | 0.36 | 0.64 | |||
| Dial Turn | 0.20 | 0.75 | 0.44 | 0.68 | |||
| Hand Insert | 0.84 | 0.99 | 0.76 | 0.88 | |||
| Lever Pull | 0.28 | 0.61 | 0.56 | 0.64 | |||
| Stick Push | 0.84 | 1.00 | 0.76 | 0.96 | |||
| Mean | 0.53 | 0.79 | 0.53 | 0.74 | |||
5.4 Noise-space adaptation preserves the base prior
After adapting on Hammer, FlowDAgger has 0.84 task success and 0.88 held-out mean, compared with the frozen base’s 0.40 and 0.96. It loses eight percentage points on held-out mean and forty points on Push alone (0.96→0.56), while Plate improves. Thus it preserves the tested prior better than the listed alternatives, rather than preserving every skill unchanged. Weight-space baselines degrade much more under this particular adaptation protocol; no general retention theorem is established.
Original mathematical definitions, inversion conditions and experimental protocol
Because FlowDAgger steers the frozen policy through its noise input, adaptation should change the task behavior without rewriting unrelated skills. We test this by adapting each method on Hammer ( episodes; demos for SFT at a matched gradient-step budget) and evaluating on five held-out tasks that the base policy nearly saturates. FlowDAgger preserves the held-out tasks best while also achieving the largest in-distribution gain. Weight-space baselines buy their Hammer improvement by collapsing held-out performance, while Residual-DAgger preserves the prior only because it barely adapts. Only FlowDAgger does both.
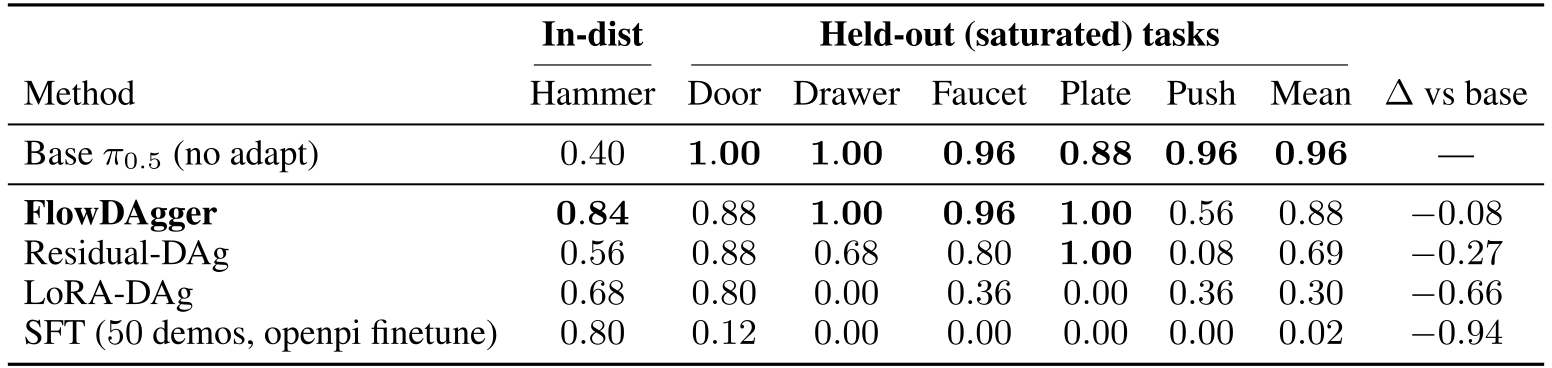
Accessible original table, all values and grouped headers
| In-dist | Held-out (saturated) tasks | |||||||
|---|---|---|---|---|---|---|---|---|
| Method | Hammer | Door | Drawer | Faucet | Plate | Push | Mean | vs base |
| Base (no adapt) | — | |||||||
| FlowDAgger | ||||||||
| Residual-DAg | ||||||||
| LoRA-DAg | ||||||||
| SFT ( demos, openpi finetune) | ||||||||
5.5 Real-world adaptation
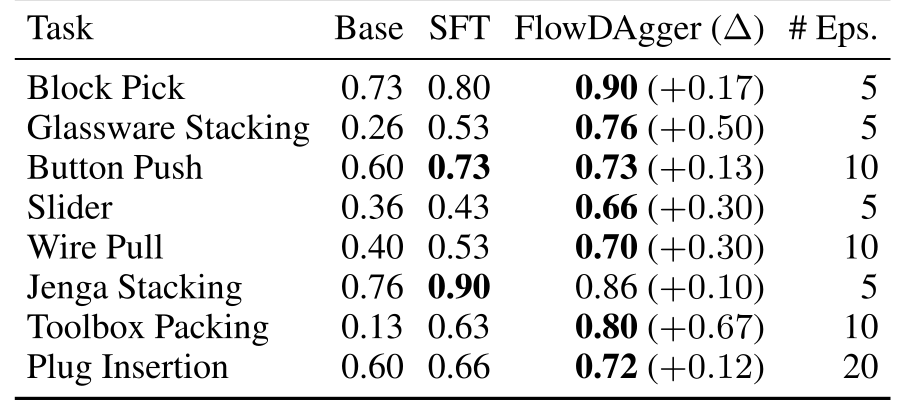
Five-to-twenty additional correction episodes improve all eight hardware tasks over the frozen base. Against SFT, FlowDAgger wins six tasks, ties Button Push at 0.73 and loses Jenga 0.86 versus 0.90; the prose’s ‘every task except Jenga’ omits the tie. Toolbox improves 0.13→0.80 with ten additional episodes, not necessarily ten individual corrective actions.
Table 4 says thirty evaluation rollouts; the global three-seed protocol and decimal values such as 0.72 leave exact aggregation unclear, so integer success counts are not reconstructed. Project captions disclose already-trained bases using fifty toolbox, thirty glassware and one hundred plug demonstrations. The added episodes are adaptation effort beyond those base data, and the clips are shown at three-times speed.
Accessible original table, all values and grouped headers
| Task | Base | SFT | FlowDAgger () | # Eps. |
|---|---|---|---|---|
| Block Pick | 0.73 | 0.80 | 0.90 () | 5 |
| Glassware Stacking | 0.26 | 0.53 | 0.76 () | 5 |
| Button Push | 0.60 | 0.73 | 0.73 () | 10 |
| Slider | 0.36 | 0.43 | 0.66 () | 5 |
| Wire Pull | 0.40 | 0.53 | 0.70 () | 10 |
| Jenga Stacking | 0.76 | 0.90 | 0.86 () | 5 |
| Toolbox Packing | 0.13 | 0.63 | 0.80 () | 10 |
| Plug Insertion | 0.60 | 0.66 | 0.72 () | 20 |
Original mathematical definitions, inversion conditions and experimental protocol
We evaluate on two real robot platforms (an FR3 Duo and a Dual UR5e) across eight tasks spanning single-arm, bimanual, and contact-rich manipulation. With only five to twenty intervention episodes, FlowDAgger substantially improves the frozen base on every task. On Toolbox Packing, for example, ten corrections raise success from to , turning a largely unusable policy into a reliable one without modifying the foundation model (Table 4). FlowDAgger also outperforms SFT, a full fine-tuning baseline, on every task except Jenga Stacking, where SFT edges ahead.
6 Limitations
The frozen model limits representable behavior, and poorly conditioned or multimodal dynamics can make inversion inaccurate. Adaptation also inherits the coverage and consistency of expert interventions. The small regression controller can change behavior away from corrected states despite unchanged decoder weights. More data or weight adaptation may be needed for genuinely new skills; the results do not establish arbitrary-correction reachability or guaranteed retention/safety.
7 Conclusion
FlowDAgger makes human action corrections usable as supervised latent decisions of a fixed generative robot model. The tested systems improve with small adaptation budgets and often retain more held-out performance than finetuning alternatives. Its practical value is that adaptation can target a lightweight controller, while inversion conditioning, human supervision, model-family details and remaining skill degradation determine the limits.
Original before and after demonstrations
Twelve unchanged original clips show frozen-base and adapted examples for toolbox packing, glassware stacking and plug insertion. Clip A/B labels follow the source filenames without assuming synchronized camera angles or extra trials. The official page says three-times playback speed; local preview posters are extracted from the original files. The examples retain visual evidence of behavior while the paper’s tables define evaluation outcomes.
Appendix A World-Action Model Inversion Details
The world-action appendix is essential: it specifies the EDM schedule, a local gradient-based terminal inverse, the failure of an action-frame-only alternative and the lower-dimensional controller parameterization. These details qualify the main text’s broad forward-pass-only description. Full joint inversion and the controller’s output dimension are different choices.
A.1 Inverting the EDM diffusion schedule
Cosmos uses a one-Euler EDM schedule from noise 80 to 4, followed by a terminal denoiser. Fixed-point inversion reverses the schedule update, while a short Adam solve recovers the pre-terminal latent and backpropagates through one denoiser per step. It avoids gradients through the entire chained sampler but is not fully gradient-free. The terminal solve’s complete iteration/settings and a separate world-action timing/memory breakdown are not reported here.
Original mathematical definitions, inversion conditions and experimental protocol
Cosmos-Policy generates with an EDM-style diffusion process rather than a flow-matching ODE, which changes the recurrence inversion must undo. The noise schedule does not terminate at zero noise: it runs from a large down to a nonzero (here , ), and the forward sampler we invert is a 1-Euler integrator over followed by a single terminal denoise . The 1-Euler integration is inverted with the same per-step fixed-point iteration as in Section 4.1, applied to the reverse of the EDM update; because each step depends only on the current latent and noise level, the reversal is memoryless and gradient-free. The terminal denoise at is a strong transform – the schedule does not bottom out near identity – so a single explicit reverse step cannot invert it. We recover its input with a short local Adam solve anchored at the base policy’s own pre-terminal state, backpropagating through one denoiser call per Adam step. This terminal solve is the only part of the inversion that backpropagates through the base model; like the rest of the inverter it requires no backprop through the chained sampler and runs online as corrections are collected.
A.2 Why action-frame-only inversion is insufficient
An earlier 112-dimensional action-frame-only optimization held other frames fixed and differentiated through the chained sampler. Reconstruction error remained about 0.04 on base actions and 0.076 on expert actions, worsening with longer schedules. Joint inversion performs better in this comparison. The limited variant study does not prove all action-only optimizers face an irreducible error floor, nor that finite fixed-point inversion is exact for every joint latent.
Original mathematical definitions, inversion conditions and experimental protocol
An earlier variant of the inverter optimized only the action-frame noise (112 dimensions in our configuration) with Adam, held the non-action frames at a fixed reference, and minimized the action-reconstruction loss through the chained denoiser calls of the forward sampler. This consistently floored at a non-trivial reconstruction error – about even when inverting the base policy’s own actions and on real expert actions – and grew worse with more denoising steps, because the chained-denoiser objective is sharply non-convex in the action-frame noise alone. Inverting the joint process instead replaces that hard optimization with the exact per-step fixed-point inverse described in Section 4.2 and a single small autograd-based solve at .
A.3 Parameterizing the noise policy for world-action models
Action-head controllers can regress chunk-shaped noise directly. For the 112,896-dimensional world-action latent, the default controller instead predicts 64 PCA coefficients fit from warmup inverted targets; full latent regression is an alternative. The basis can stabilize learning while restricting reachable noise to that fitted subspace. Full inversion still precedes this compression, and retaining a successful-noise basis does not prove all corrected actions are exactly expressible by it.
Original mathematical definitions, inversion conditions and experimental protocol
For action-head base policies the noise is action-chunk shaped and low-dimensional enough that the noise policy regresses it directly. Because is trained by supervised regression on inverted-noise targets rather than by reinforcement learning, it tolerates this dimensionality without the reductions that noise-space RL requires: DSRL [14], for instance, collapses ’s -dimensional chunk noise to a single per-step vector repeated across the chunk to keep SAC stable.
Original mathematical definitions, inversion conditions and experimental protocol
World-action models are different. The joint noise returned by the inverter is of order dimensions, too high for to regress directly even under supervision. We compared two options for ’s output. Full: regress the entire joint latent – maximum capacity but no prior. Basis: regress PCA coefficients fit on inverted-noise targets collected during a brief base-policy warmup, anchoring the output to the manifold of successful base-policy noises. Both worked; the basis parameterization was somewhat more stable and is the default in our Cosmos-Policy experiments. Either choice is downstream of inversion, which always operates on the full joint process.
Appendix B Additional Experiments
Additional tests compare inversion recipes/iteration budgets and adapt two more policy families. They separate reconstruction error, inversion time and downstream success. The single-task appendix curves support transfer examples; their single-seed protocol should not be merged with the main three-seed statistics.
Original mathematical definitions, inversion conditions and experimental protocol
This appendix reports supplementary experimental results. Section B.1 gives the full inversion-procedure comparison and Section B.2 the iteration-count sweeps. Sections B.3 and B.4 replicate the main-paper experiments with two additional pretrained generative policies as the base model – Gr00t N1.7 [3] (a second action-head VLA) and a vanilla diffusion policy [1] – to confirm that the findings are not specific to and Cosmos-Policy.
B.1 Inversion procedure comparison
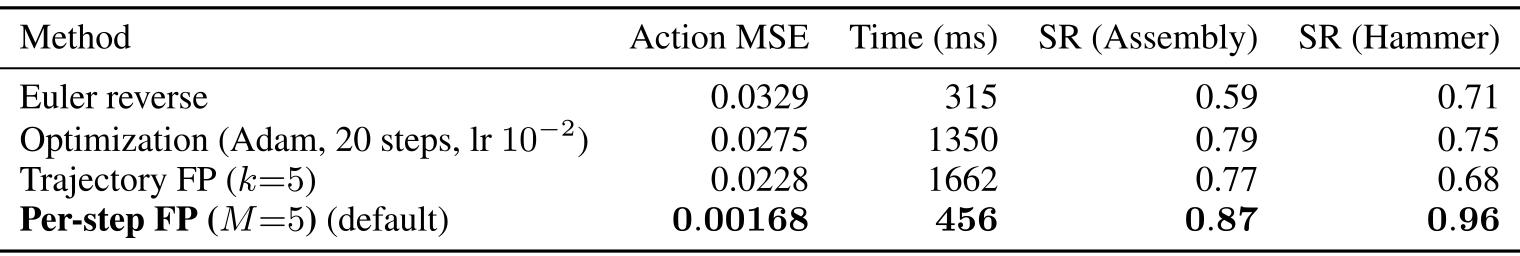
Twenty-nine identical scripted-expert Assembly chunks test four inverses at K=10. Default per-step fixed points yield action MSE 0.00168 versus 0.0329 for explicit reverse and 0.0228 for trajectory fixed points, about 19.6× and 13.6× lower. At 456 ms per chunk, the default is slower than the 315 ms explicit reverse, but faster than 1350 ms Adam and 1662 ms trajectory inversion. These are medians after warmup on an RTX 5090, not a measured deployed control-loop deadline.
Downstream Assembly/Hammer success favors accurate inversion in the reported comparisons. A reconstruction-error threshold or permanently higher attainable success ceiling is not proved by these few recipes and tasks. Action error units/range and the scripted-expert setup remain with the original table.
Original mathematical definitions, inversion conditions and experimental protocol
We compare the per-step fixed-point inversion of Section 4.1 against (i) a single explicit Euler reverse pass, (ii) trajectory-level fixed-point inversion, which corrects the global trajectory-reconstruction residual [27], and (iii) optimization-based inversion (Adam on an action-reconstruction loss backpropagated through the frozen decoder). All variants invert the same scripted-expert chunks on the assembly task and reconstruct through the frozen decoder with the standard -step Euler schedule (Table 5).
Original mathematical definitions, inversion conditions and experimental protocol
Per-step fixed-point inversion is roughly an order of magnitude more accurate than every trajectory-level alternative – at its Action MSE is lower than Euler reverse and lower than trajectory-level FP – and faster per chunk. Cranking the baselines does not close the gap: trajectory FP saturates by and a 20-step Adam refinement only matches a single Euler pass (Section B.2). Both correct a global residual they cannot attribute to any single step, and at the per-step linearization errors are too large to remove this way. This is consistent with trajectory-level inversion results for image diffusion and rectified flow [26, 27], established under the far smaller per-step errors of –-step schedules; few-step flow-matching action heads sit in a different regime, and the per-step solve is what restores accuracy there.
Original mathematical definitions, inversion conditions and experimental protocol
These reconstruction gaps carry downstream. Training the noise policy on each inverter’s targets, per-step FP reaches / SR on assembly/hammer versus / for Euler reverse, with the trajectory-level and Adam variants clustered between (their order swaps across tasks within seed noise). Inaccurate inversion is not merely slower: Euler-reverse supervision pushes the noise policy below the frozen base on assembly ( vs ), since targets noisier than Action MSE corrupt rather than steer the policy. Accurate inversion therefore sets a strictly higher ceiling, not just a faster path to it.
B.2 Inversion iteration counts
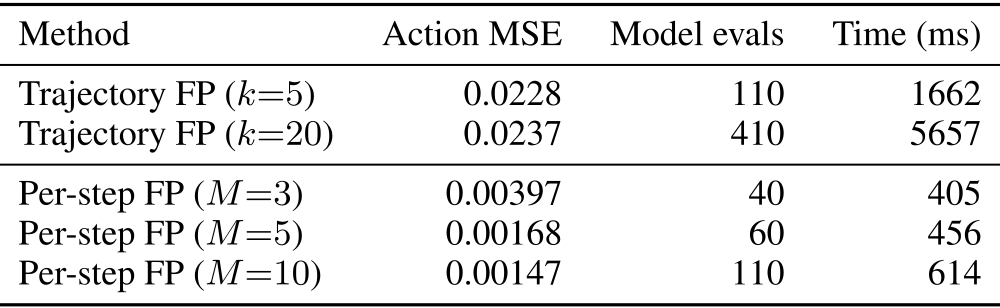
Increasing per-step M from 3 to 5 cuts MSE 0.00397→0.00168; M=10 improves it only to 0.00147 while time rises 456→614 ms. At 110 reported model calls, trajectory k=5 has 0.0228 error/1662ms versus per-step M=10 at 0.00147/614ms, about 15.5× lower error and 2.7× faster. Counts match K(M+1) and K(2k+1) in this table, including more than the main text’s inverse-only KM formula. The observed plateau of a trajectory variant is an empirical sweep, not a general impossibility result for every optimizer.
Original mathematical definitions, inversion conditions and experimental protocol
Table 6 sweeps the inner iteration count of per-step fixed-point inversion (Equation 3) and the outer iteration count of trajectory-level fixed-point inversion, with all other settings matching Table 5. The two sweeps are not directly comparable on a per-iteration basis because and parametrize different objects: each iteration is a full forward-plus-reverse pass over the -step trajectory ( model evaluations), while each iteration is a single velocity evaluation at one of the reverse steps. The natural matched-compute pairing is therefore ( model evals) against ( model evals); even at matched compute, per-step FP yields lower Action MSE than trajectory-level FP, and runs faster.
Original mathematical definitions, inversion conditions and experimental protocol
For per-step FP, Action MSE drops from to , then only further at while wall-clock rises by ; the per-step contraction has effectively converged by , which we use as the default. For trajectory-level FP, raising from to produces no measurable improvement – the algorithm has already extracted all the information it can from the global residual, and the remaining error is the irreducible per-step linearization error that the trajectory-level formulation cannot address.
B.3 Gr00t N1.7
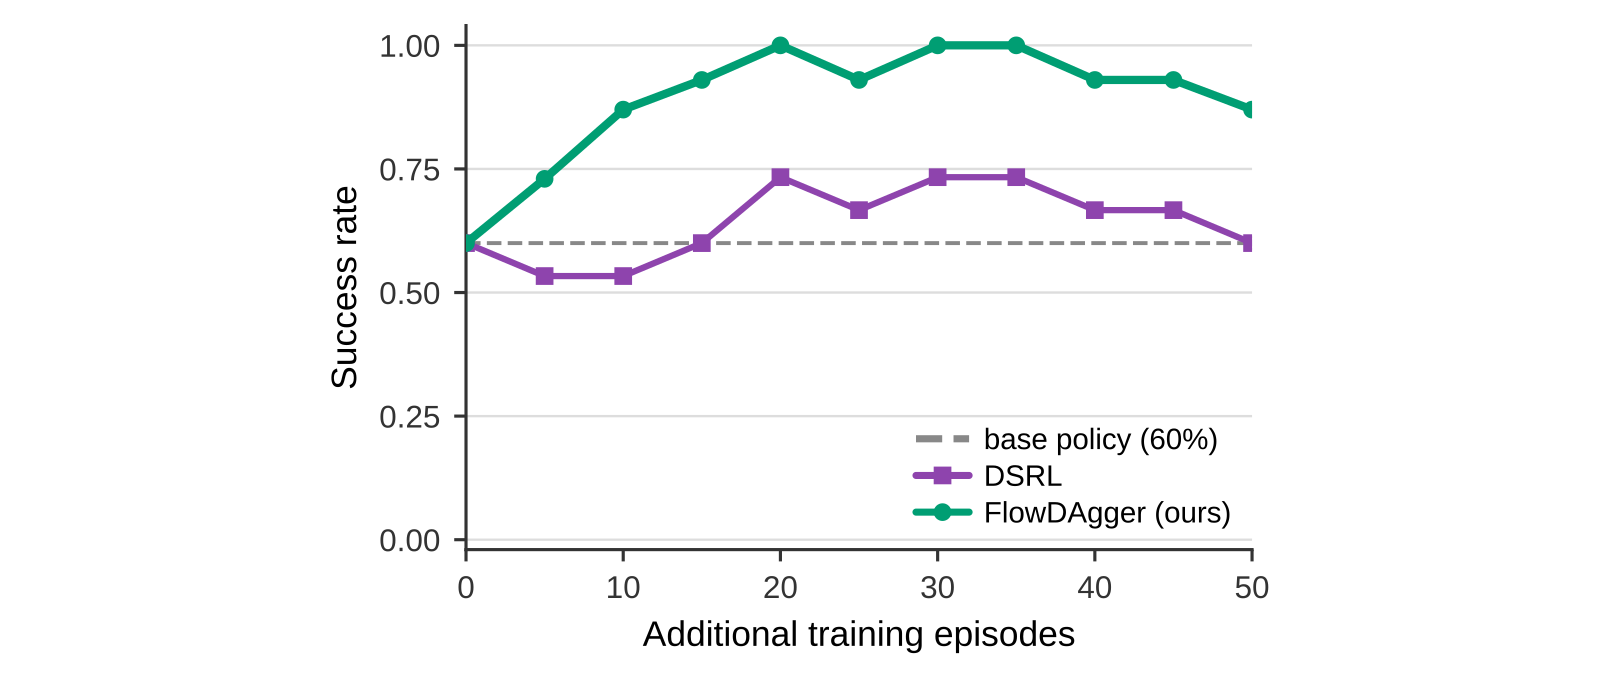
Gr00t’s LIBERO-10 checkpoint is adapted on held-out LIBERO-90 task 57, with scripted-expert corrections versus reward-only DSRL. The described noise space has 5,280 dimensions and a ten-term DCT basis gives 1,320 effective coordinates for tractability. This is one task and one seed, fifteen evaluation rollouts per point. The green curve reaches 100% but later falls below it, ending around 87%; the caption’s ‘saturates near 100%’ should not imply persistent perfect success. It begins near the 60% base and is already above it at five episodes.
Original mathematical definitions, inversion conditions and experimental protocol
We replace with Gr00t N1.7 [3], a second action-head VLA built on a Qwen3-VL backbone with a DiT flow-matching head. We use the LIBERO-10 checkpoint released by the authors and evaluate on LIBERO-90 task 57 (pick up the cream cheese and put it in the tray), which is held out from the checkpoint’s training set and zero-shots at 60% success. Both methods adapt the same frozen base policy from 50 episodes of additional online experience; FlowDAgger uses scripted-expert interventions, while DSRL uses task reward only. To make SAC tractable in Gr00t’s -dimensional noise space, we project noise onto a DCT-II polynomial basis (-dimensional effective action space).
Original mathematical definitions, inversion conditions and experimental protocol
Figure 5 shows that the qualitative finding from the main paper transfers to Gr00t: FlowDAgger’s noise-space supervision rapidly drives the success rate to ceiling, while DSRL is restricted to the much smaller signal of task reward and converges to a lower plateau roughly percentage points below FlowDAgger’s peak.
B.4 Diffusion Policy
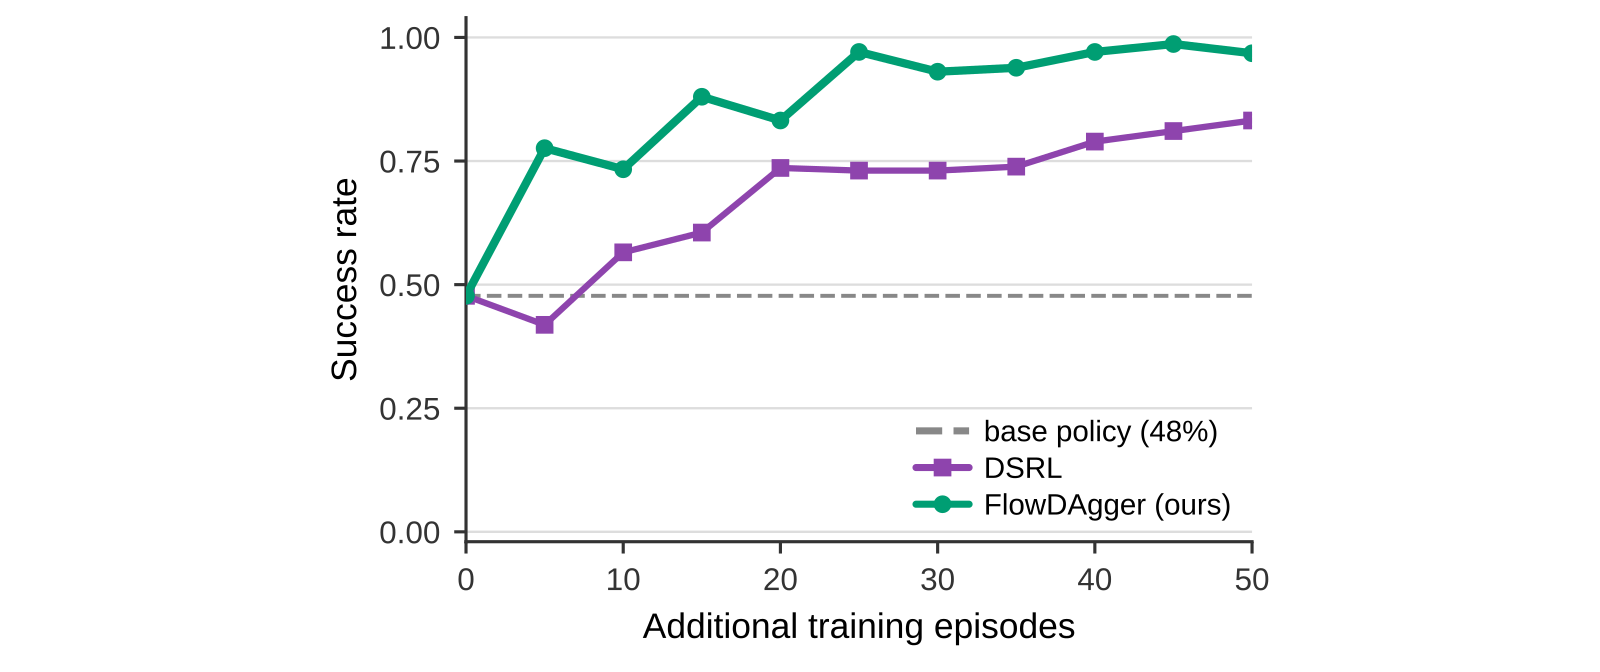
A state-only diffusion policy on robomimic LIFT starts near 48% success. With fifty online episodes, the displayed single-seed, fifteen-rollout evaluations show FlowDAgger approaching 97% and DSRL around 80%. This is another useful policy-family example with low-dimensional observations; it is not a direct visual-input robustness test or a multi-seed guarantee. More informative rewards and smaller noise space may help DSRL, as the authors suggest.
Original mathematical definitions, inversion conditions and experimental protocol
We additionally evaluate on a vanilla DDPM-based diffusion policy [1], adapting it on the robomimic LIFT task [30] from low-dimensional state observations. The base policy zero-shots at , and both methods are given additional online episodes.