Overview
StereoPolicy learns task-relevant binocular features directly from rectified image pairs, retaining a conventional diffusion or vision-language-action policy without reconstructing depth.
At a glance
A shared two-dimensional image encoder and alternating self/cross-attention fuse synchronized stereo observations into action-conditioned features. Tests span three simulation benchmarks and seven physical tabletop/mobile tasks. Stereo fusion improves the tested monocular and simple two-image controls, including pretrained VLA backbones. Its strongest claims concern these matched configurations: transparent glass remains difficult, and avoiding explicit depth reconstruction does not remove camera setup requirements.
1 Introduction
Monocular policies can confuse depth and precise alignment, while reconstructed depth/point clouds introduce sensing errors, missing transparent geometry, and processing latency. StereoPolicy trains binocular fusion through the action objective, using existing two-dimensional visual priors without explicit depth supervision. The study examines task success, camera geometry, encoder/fusion design, and adaptation of pretrained VLAs. It does not claim that all point-cloud policies or all pretrained stereo models are intrinsically inferior.
2 Method
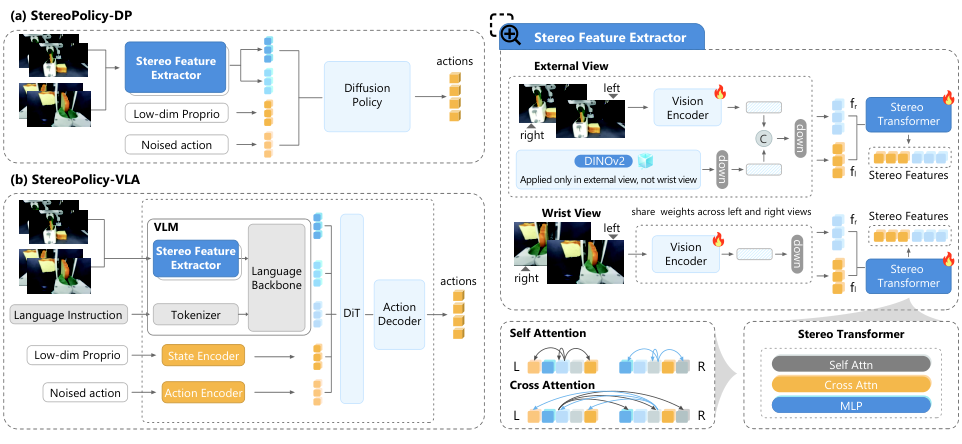
The same perception idea is used in two settings: a diffusion-policy backbone trained from scratch on each task, and pretrained VLA backbones finetuned with stereo features. Within each camera rig the left/right pair is fused; embeddings from separate rigs and robot state are then aggregated.
2.1 Stereo Feature Extraction
Each camera view supplies a synchronized left/right image pair. The encoder produces binocular features for control rather than an explicit disparity map, depth map, or reconstructed three-dimensional scene.
Stereo image encoding
Left and right images share encoder weights. ResNet18/FPN features are augmented with frozen DINOv2 features on external views, then projected to a common dimension. DINOv2 hurts wrist-view performance in this study and is omitted there; the suggested explanation of egocentric domain mismatch is a hypothesis, not an independently isolated mechanism.
Equation 1
| (1) |
Stereo feature fusion
The Stereo Transformer alternates attention within each image and cross-attention between images. Two-dimensional rotary positional embeddings encode image coordinates in cross-attention queries and keys. The action loss trains these correspondences without a disparity target.
Equation 2
| (2) |
Multi-view aggregation
Fusion is performed separately within each stereo camera rig. The resulting view embeddings are concatenated with proprioception to condition the action backbone; this step does not explicitly reconstruct a common three-dimensional scene.
Equation 3
| (3) |
2.2 StereoPolicy-DP : Diffusion Policy with StereoPolicy
Diffusion Policy denoises a future action sequence conditioned on stereo observations. The encoder, stereo fusion, and action network are optimized jointly with the standard noise-prediction loss; DINOv2 remains frozen. At inference, iterative denoising produces the action sequence from Gaussian noise. The stereo representation changes conditioning while retaining the diffusion policy objective.
Equation 4
| (4) |
2.3 StereoPolicy-VLA : Adapting Monocular VLA to Stereo Inputs
For a pretrained VLA, shared visual encoding and stereo fusion replace the monocular image embedding while language, state, and the action backbone retain their interfaces. Finetuning adapts the system to downstream tasks. Preserving the backbone architecture does not mean the entire pretrained system is frozen.
Equation 5
| (5) |
3 Experiments
Experiments ask whether stereo fusion improves matched RGB/depth/point-cloud controls, transfers to pretrained VLAs, depends on camera geometry, and can be replaced by generic pretrained stereo representations.
3.1 Tasks and Environments
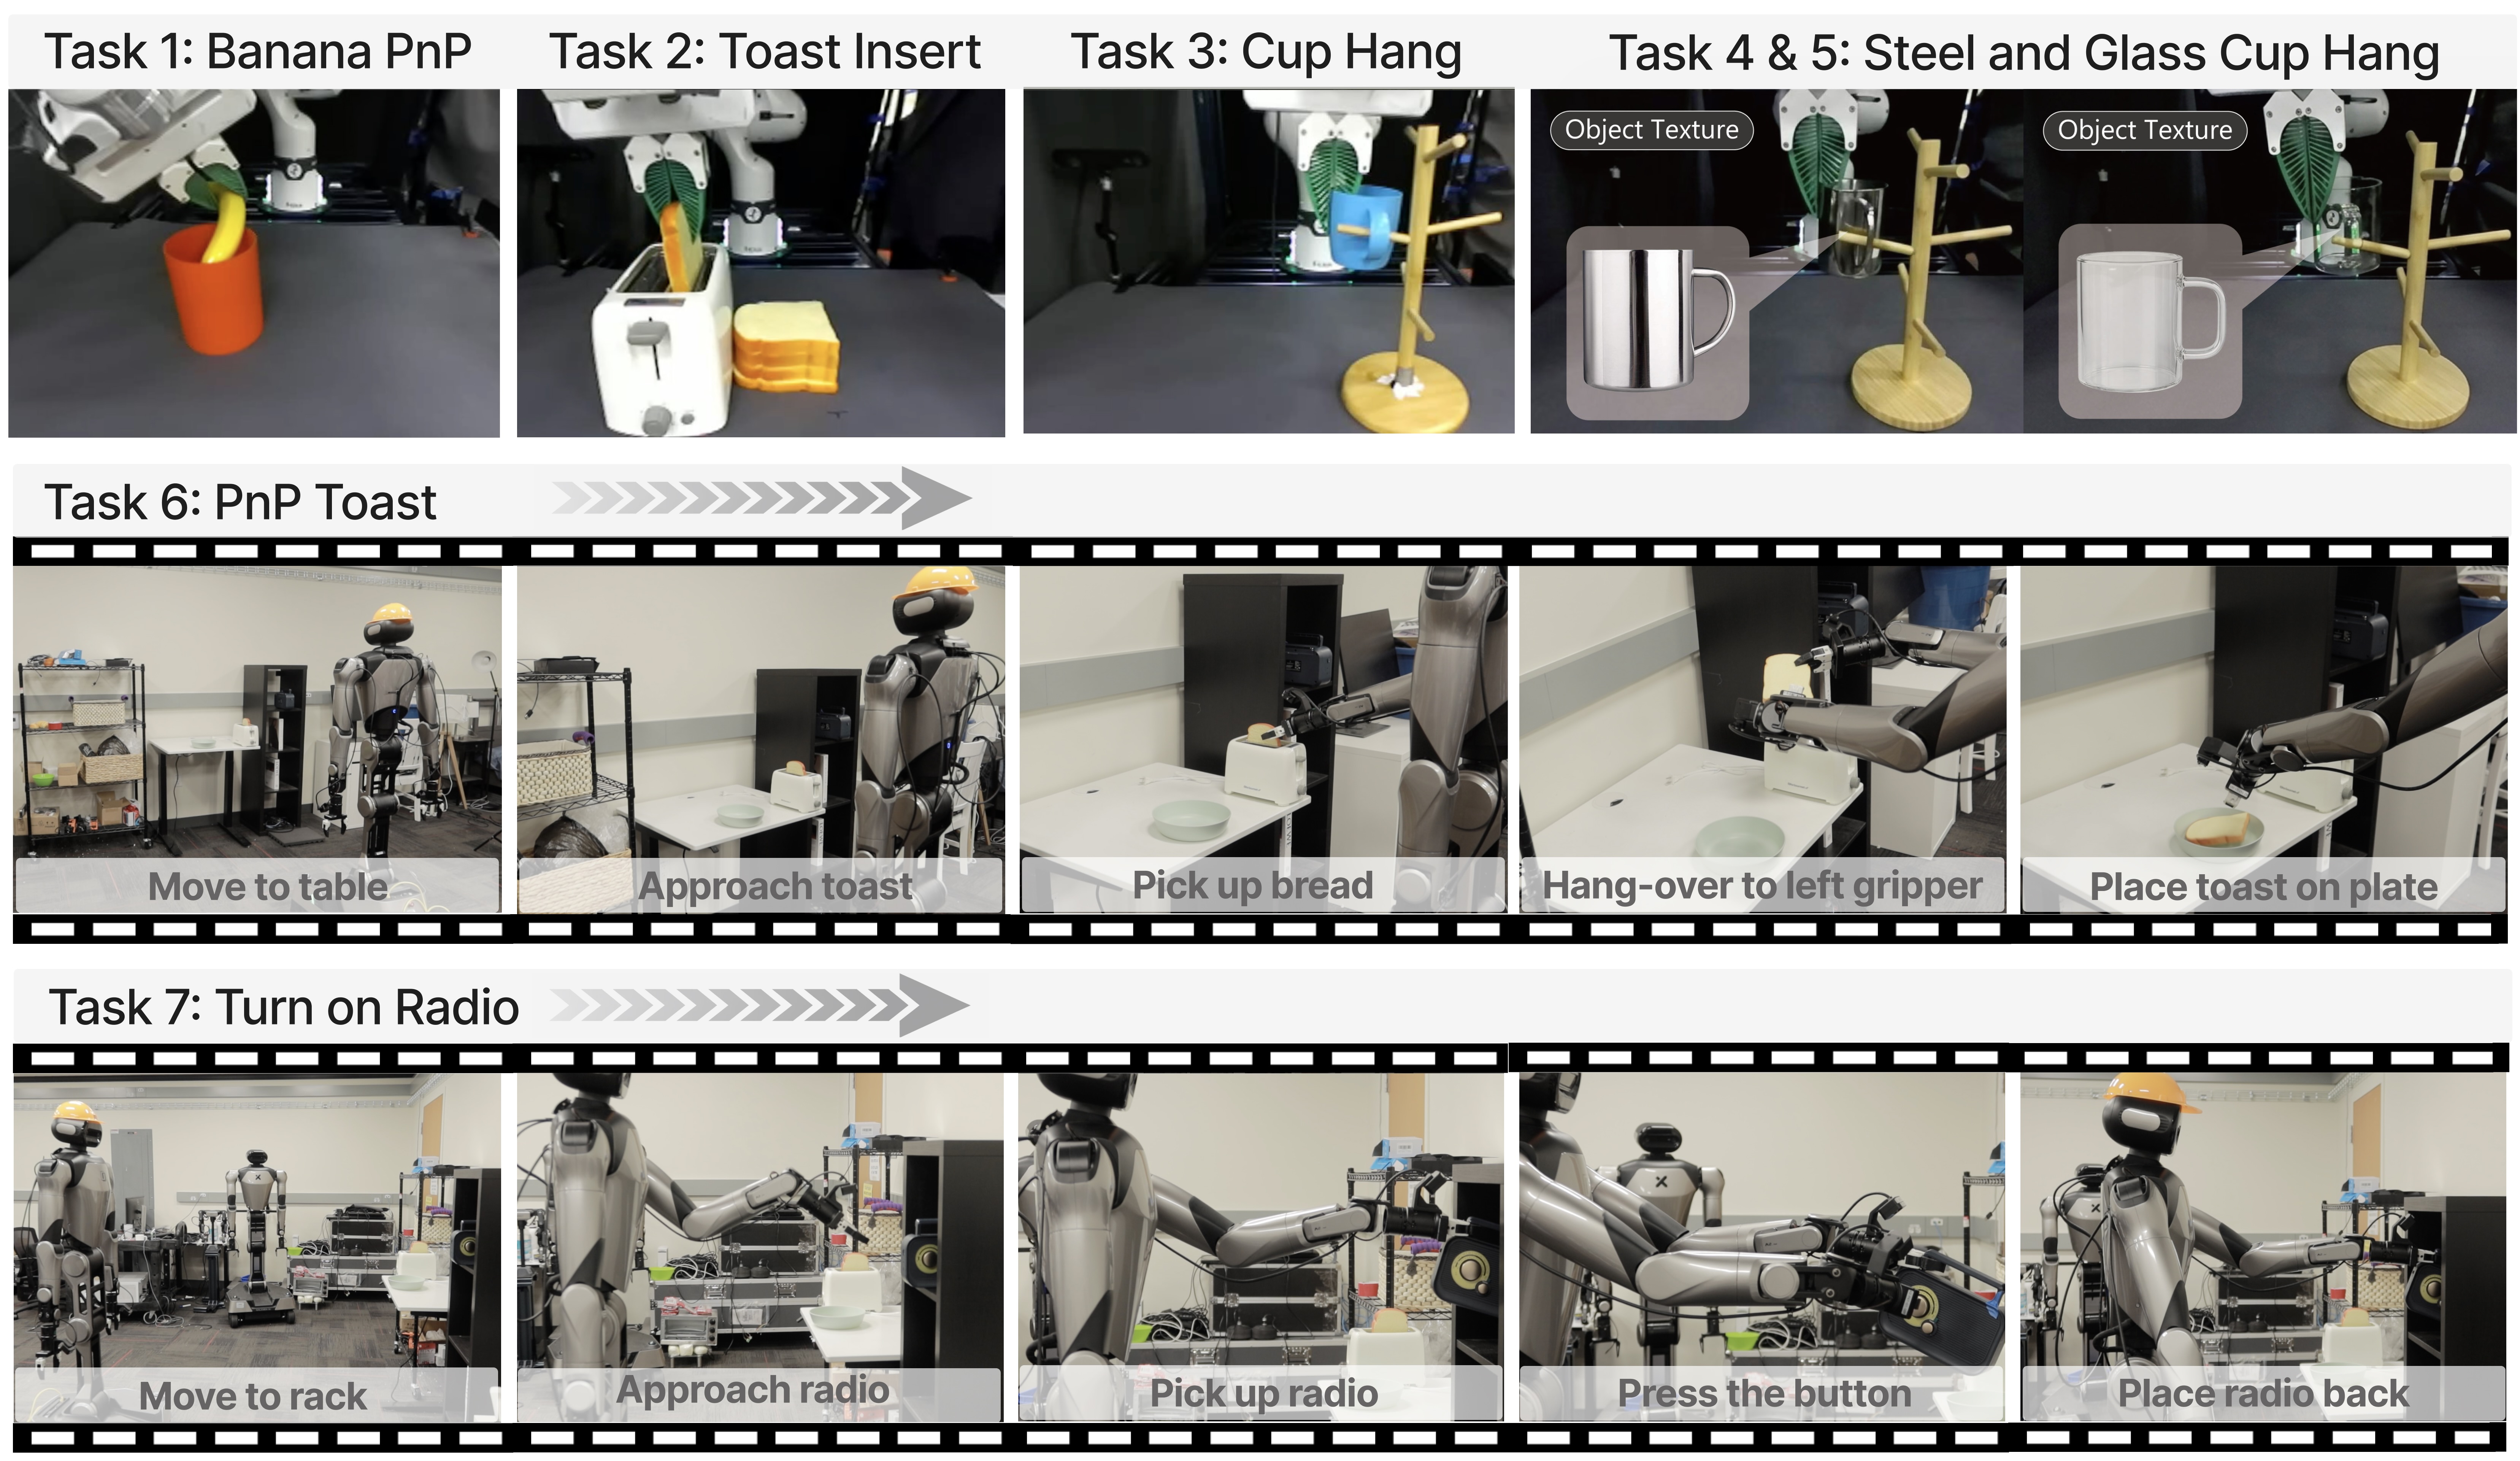
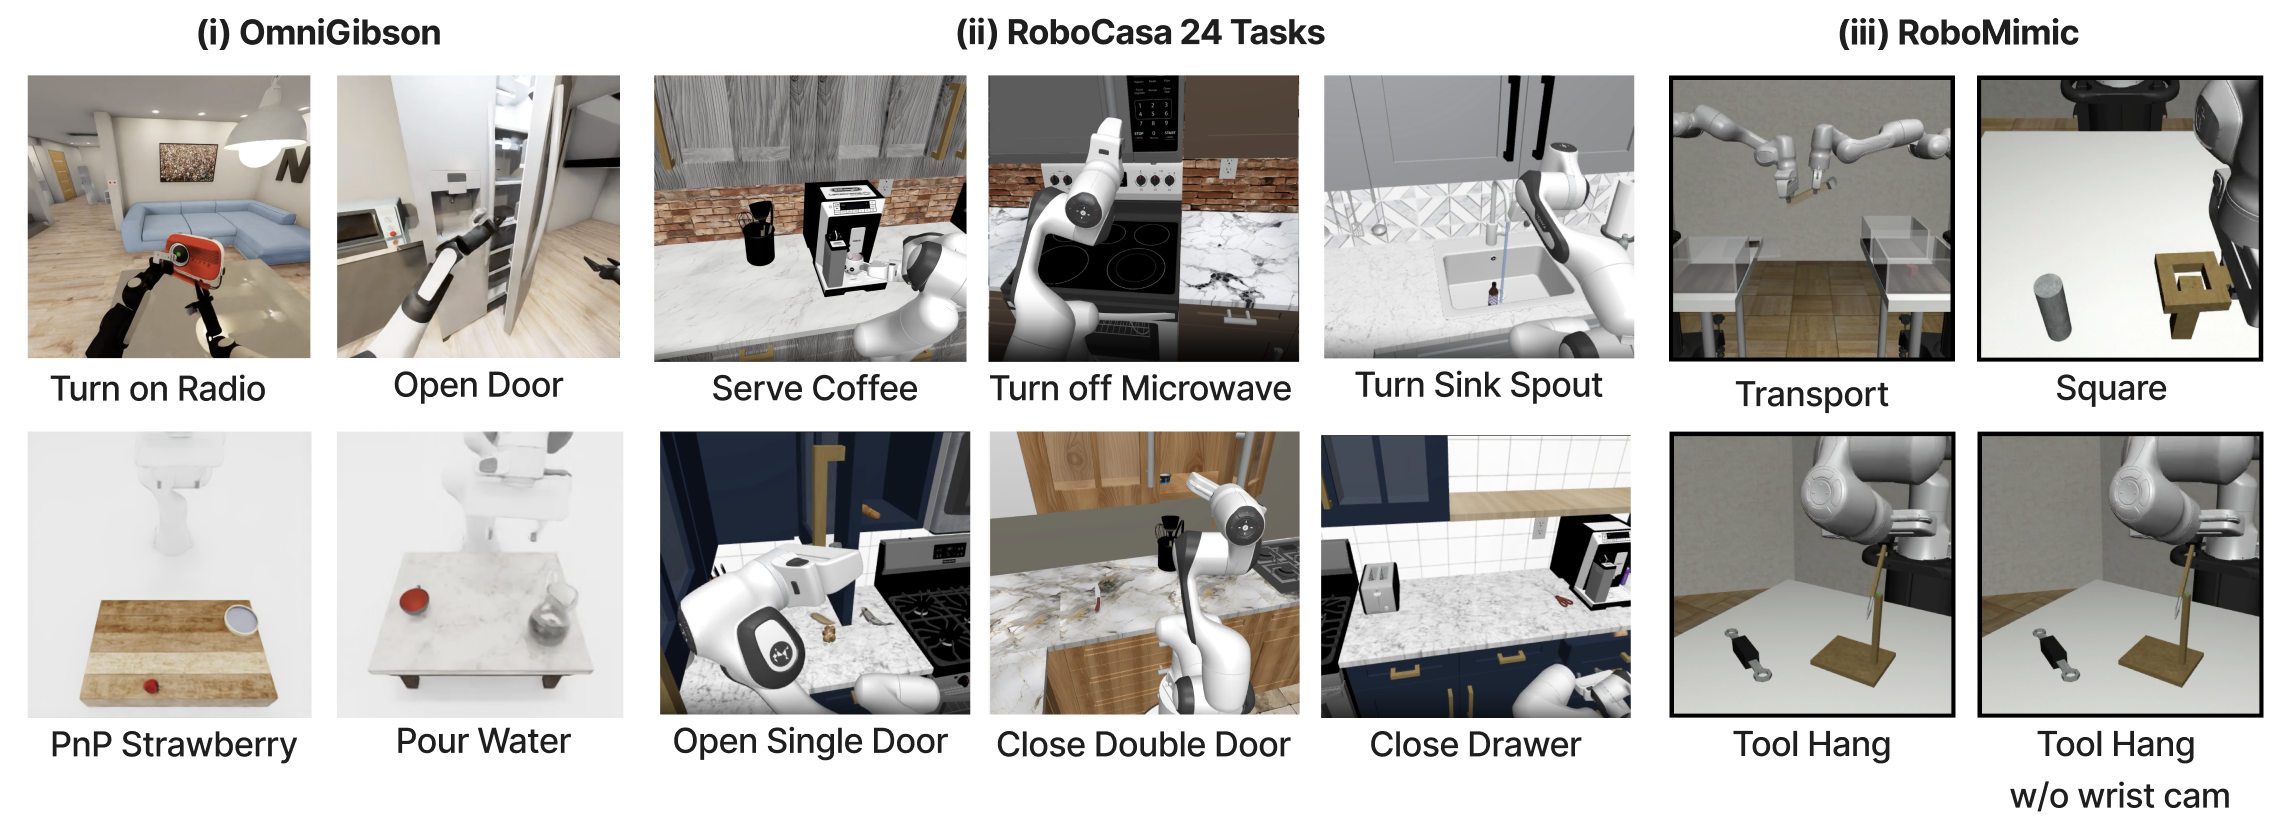
Hardware comprises a seven-joint Franka tabletop arm and a twenty-four-degree-of-freedom Galaxea R1 Pro mobile bimanual robot. The study uses five tabletop and two mobile real tasks, three Robomimic tasks, twenty-four RoboCasa tasks, and four custom OmniGibson tasks.
3.2 Implementation Details
Training and comparisons keep action backbones, data, image resolution, optimization, and budgets matched where applicable. The appendix gives modality-specific preprocessing and additional parameter-matched controls.
Baselines
Controls include monocular RGB, concatenated two-view RGB, RGB-D, PointNet point clouds, 3D Diffuser Actor, and DP3. The monocular control uses the same external DINO features and adjusted attention capacity. The multi-view control receives the same left/right images as StereoPolicy but concatenates features through a capacity-matched projection, helping distinguish stereo fusion from merely adding a second image.
4 Results and Analysis
Results combine task success, VLA transfer, camera sweeps, representation substitutions, and ablations. The appendix specifies that simulated scores select the highest success over periodic checkpoint evaluations; these are not simply final-checkpoint estimates.
4.1 Experimental Results
StereoPolicy improves the main tested baselines across many conditions, with important scope limits in low absolute glass success, modest VLA gains, and configuration-specific geometric studies.
| Method | Banana PnP | Toast Insert | Plastic Cup Hang | Steel Cup Hang | Glass Cup Hang | AVG SR (%) |
|---|---|---|---|---|---|---|
| RGB | 12/20 | 8/20 | 12/20 | 10/20 | 1/20 | 43.0% |
| RGB-D | 14/20 | 8/20 | 11/20 | 8/20 | 0/20 | 41.0% |
| RGBD-3DDA | 13/20 | 9/20 | 13/20 | 10/20 | 0/20 | 45.0% |
| PCD-PointNet | 7/20 | 0/20 | 5/20 | 2/20 | 0/20 | 14.0% |
| PCD-DP3 | 11/20 | 3/20 | 8/20 | 5/20 | 0/20 | 27.0% |
| Multi-View | 13/20 | 9/20 | 13/20 | 9/20 | 1/20 | 45.0% |
| StereoPolicy-DP | 16/20 | 12/20 | 15/20 | 13/20 | 3/20 | 59.0% |
| Benchmark | OmniGibson | Robomimic | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Task | Strawberry | PourWater | OpenDoor | TurnOnRadio | ToolHang | Square | Transport | |||||||
| # Demos | 100 | 200 | 100 | 200 | 200 | 300 | 200 | 300 | 100 | 200 | 100 | 200 | 100 | 200 |
| RGB | ||||||||||||||
| RGB-D | ||||||||||||||
| RGBD-3DDA | ||||||||||||||
| PCD-DP3 | ||||||||||||||
| Multi-View | ||||||||||||||
| StereoPolicy-DP | ||||||||||||||
( 𝒬 𝟏 ) StereoPolicy-DP consistently outperforms monocular RGB, RGB-D, point cloud, and multi-view-based policies.
Across five physical tabletop tasks, StereoPolicy succeeds in 59% of the pooled equal-sized trials, versus 43% RGB, 41% RGB-D, 45% 3DDA, 14% PointNet, 27% DP3, and 45% matched multi-view RGB. Individual StereoPolicy counts are 16/20 banana, 12/20 toast, 15/20 plastic cup, 13/20 steel cup, and only 3/20 glass cup. In simulation, examples include ToolHang with one hundred demos improving from 53±3.4% RGB to 94±1.9%, and PourWater with two hundred demos improving from 50% to 70%. Some strong depth baselines tie stereo in particular settings; the evidence supports this task suite rather than universal dominance.
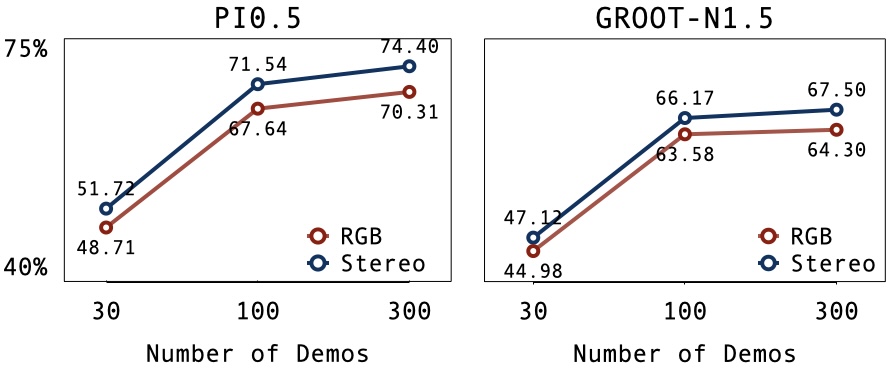
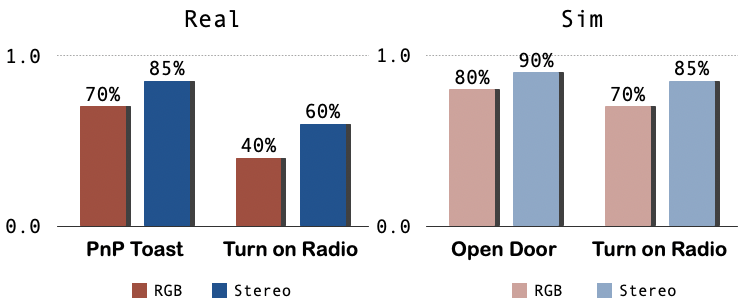
( 𝒬 𝟐 ) StereoPolicy enhances pretrained VLA models, although these models are trained on monocular data.
Stereo fusion improves π0.5 and GR00T-N1.5 across thirty, one hundred, and three hundred demonstrations per RoboCasa task. At three hundred demos, π0.5 rises from 70.31% monocular to 74.40%, and GR00T from 64.30% to 67.50%. Native two-image controls recover some gains, so the appendix separately measures fusion’s added benefit. On mobile π0.5 tasks, real toast pick/place improves 70%→85% and radio 40%→60%; simulated door/radio improve 80%→90% and 70%→85%. These finite task results do not establish unrestricted mobile autonomy.
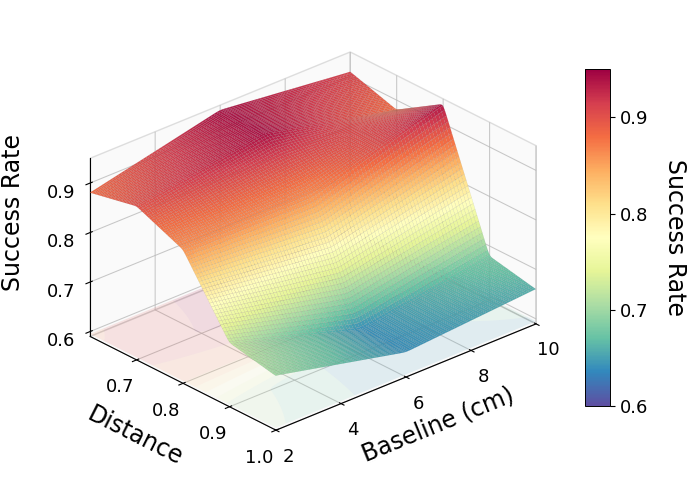
( 𝒬 𝟑 ) StereoPolicy-DP is most effective when the baseline is approximately 10% of the target object distance.
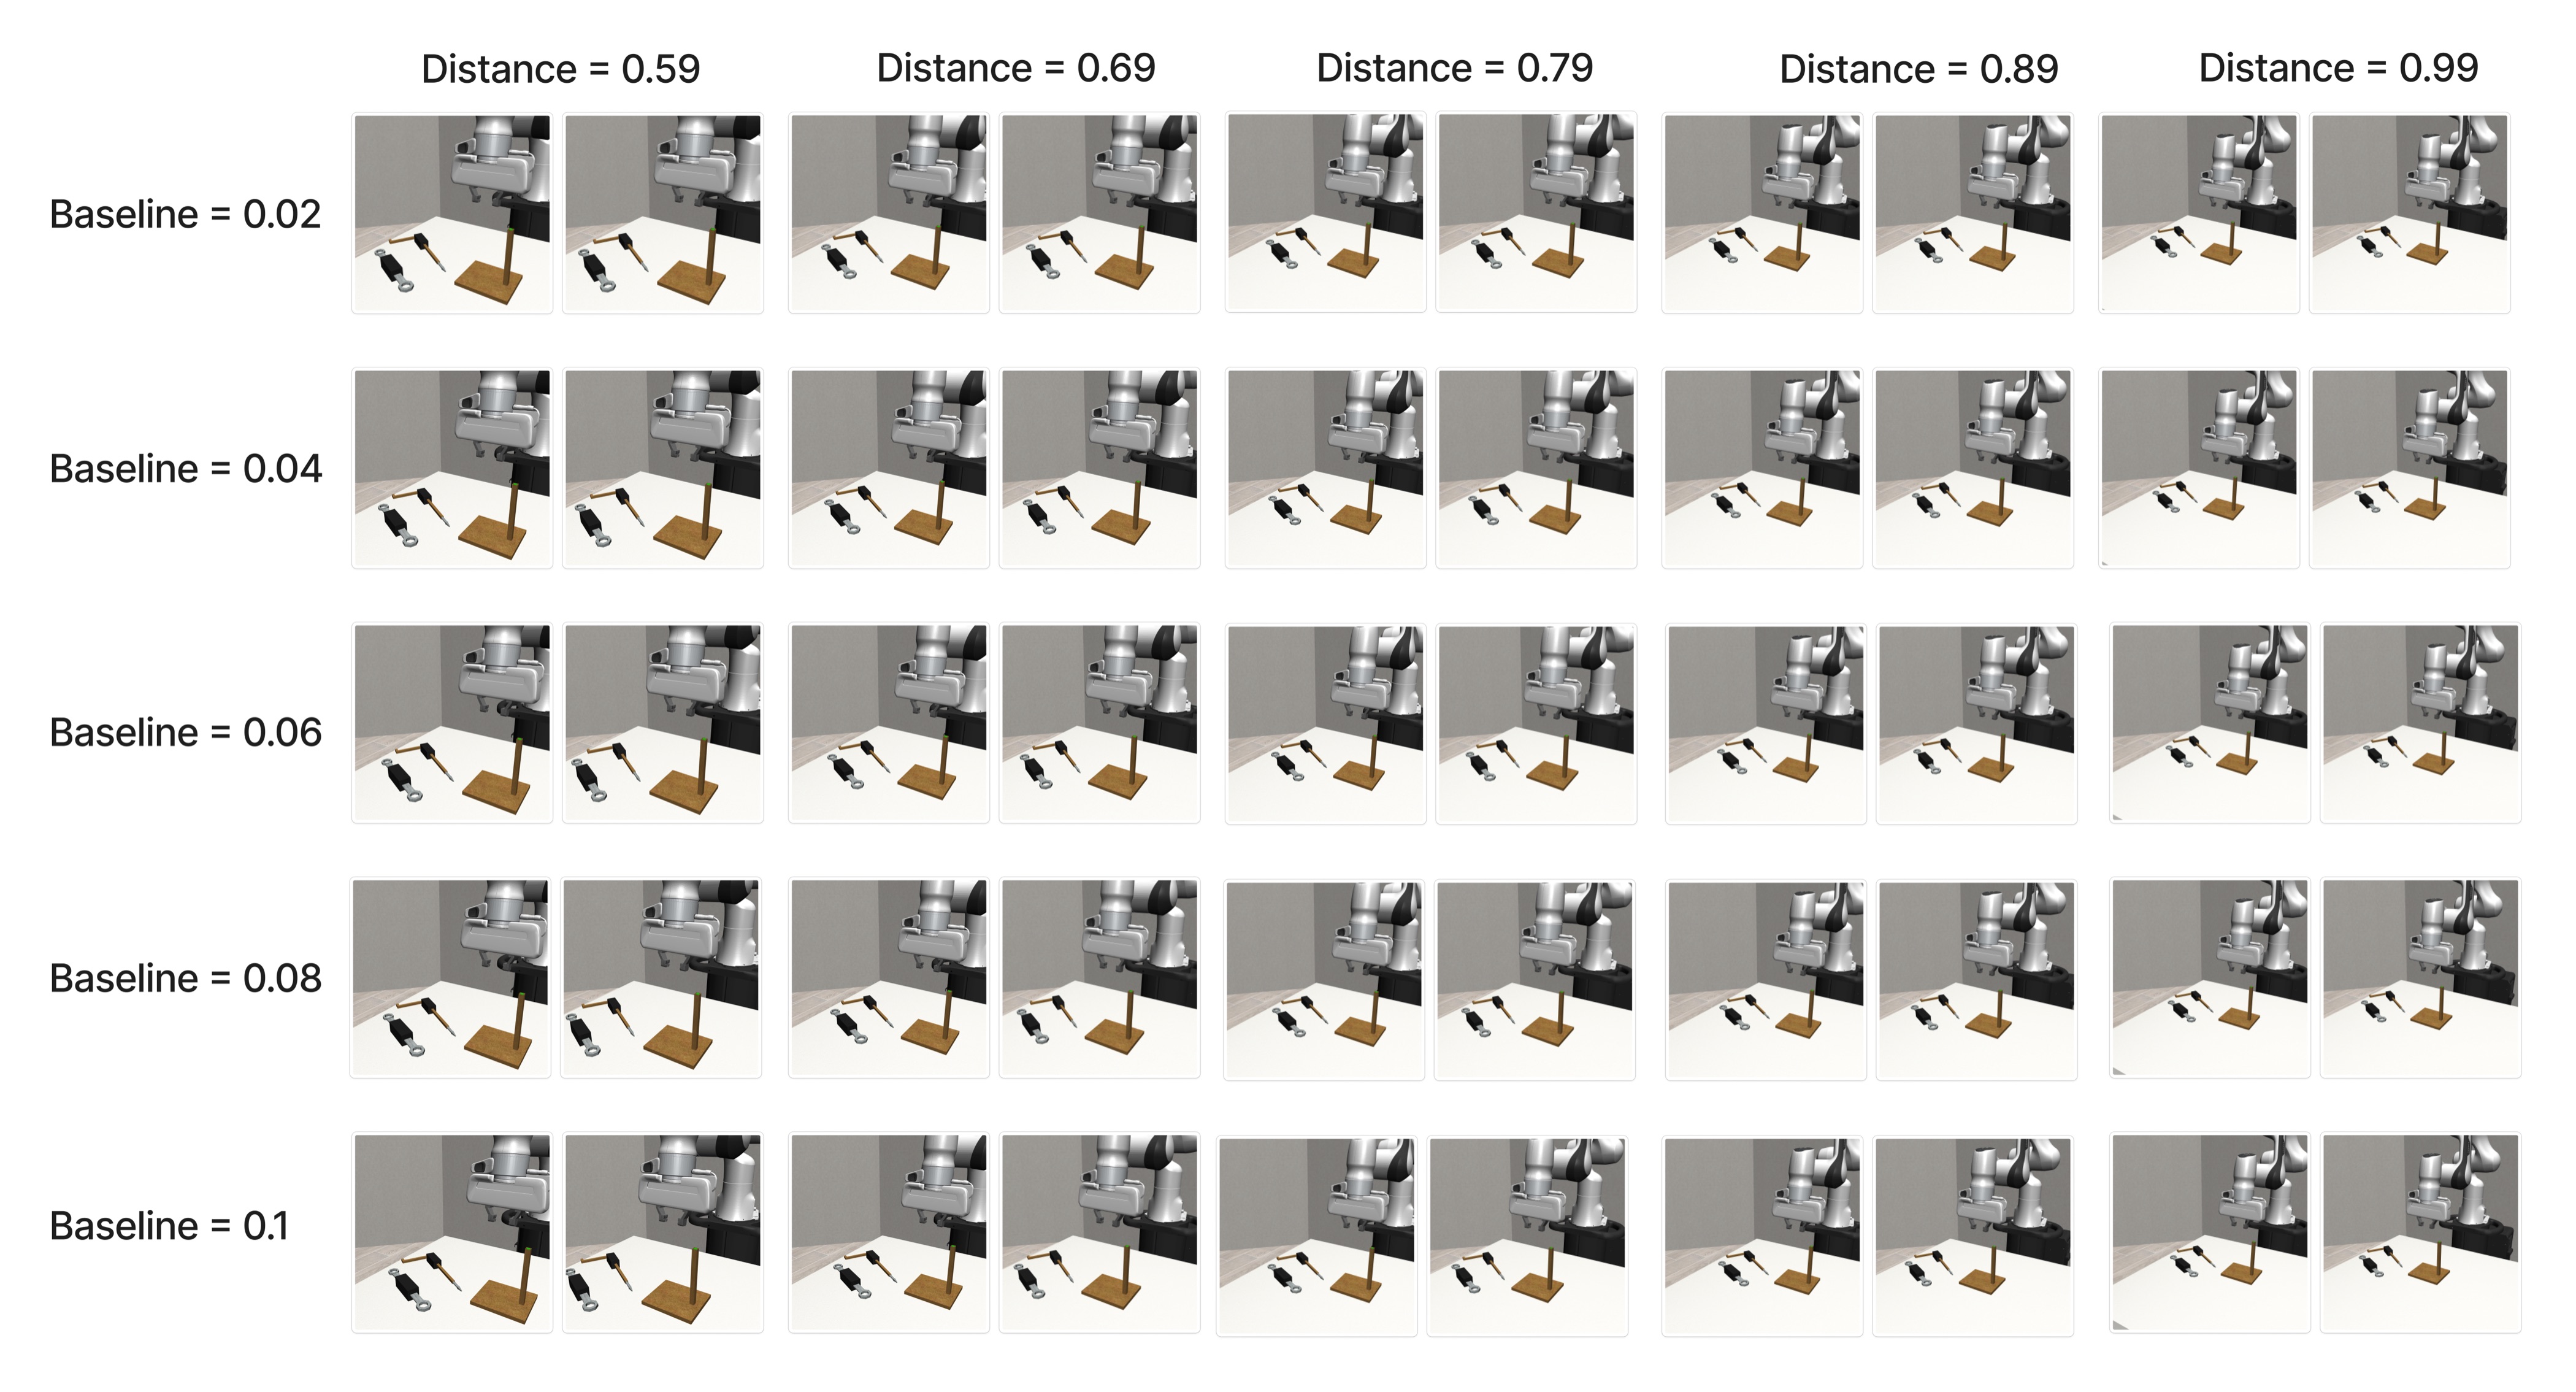
The ToolHang sweep varies baselines from two to ten centimetres and camera distance roughly 0.6–1.0 metres. The reported best region is a baseline/distance ratio around 0.09–0.13, balancing disparity and overlap; this is an empirical guideline for the tested optics, task, and training configurations rather than a universal camera constant. Stereo improves all ten tested views, with larger gains for frontal views (+18 points, or +14 elevated) and smaller gains for occluded side views. A separate fixed-policy test evaluates actual baseline transfer.
Equation 6
| (6) |
| Method | SR (%) | Latency (ms) |
|---|---|---|
| StereoPolicy-DP | 698 | |
| A. Pretrained stereo features | ||
| Frozen FS features | 740 | |
| B. Stereo-derived geometry | ||
| FS depth + RGB-D | 995 | |
| FastFS depth + RGB-D | 792 | |
| FS depth + 3DDA | 1008 | |
| FastFS depth + 3DDA | 777 | |
( 𝒬 𝟒 ) Pre-trained Stereo features cannot replace task-adapted stereo fusion.
Replacing task-trained features with frozen FoundationStereo features in a StereoVLA-style control reduces ToolHang success from 94% to 76%. Estimated-depth pipelines also perform worse and take longer here: FoundationStereo+RGB-D reaches 44% at 995 ms, and FoundationStereo+3DDA 28% at 1,008 ms, versus StereoPolicy at 698 ms. Fast variants reduce latency but do not close the task gap. These tests concern the frozen representation and complete pipelines used, not every possible finetuned stereo foundation model.
4.2 Ablations
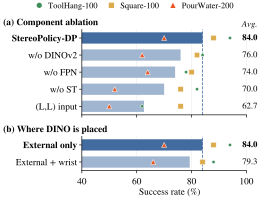
Across three ablation tasks, full StereoPolicy averages 84%. Duplicating the left image lowers this to 62.7%; removing stereo attention gives 70%, removing FPN 74%, and removing external DINO 76%. Adding DINO to wrist views gives 79.3%. The results support both binocular information and the fusion design, while the duplicated-input attention comparison shows some task-specific architecture benefit even without binocular disparity.
5 Related Work
Explicit 3D methods reconstruct depth/point clouds or lift image features using calibration. StereoVLA uses pretrained stereo features and auxiliary geometric supervision. StereoPolicy instead learns within-rig binocular features from action supervision on generic image encoders. This differs from cross-camera or multi-agent scene aggregation and could be combined with those methods; rectified synchronized pairs and suitable camera geometry are still part of its input setup.
6 Conclusion
Direct action-trained binocular fusion is effective across the evaluated diffusion and VLA policies. Remaining limits include poor transparent-object performance, sensitivity to camera geometry, small physical test counts, checkpoint-selected simulation scores, and substantial full-policy denoising latency. Linear probes demonstrate accessible depth information, not that this representation is a complete geometric reconstruction or the sole causal source of success.
Appendix A Task and Data Collection Details
The task and data appendix specifies benchmark selection, physical demonstration counts, and camera/robot configurations.
Simulation Tasks
Robomimic evaluation uses ToolHang, Square, and Transport, excluding already saturated Lift and Can. RoboCasa contributes twenty-four kitchen tasks for VLA evaluation. Four custom OmniGibson tasks—strawberry manipulation, water pouring, door opening, and radio operation—use cuRobo-assisted demonstration collection.
Real Robot Tasks.
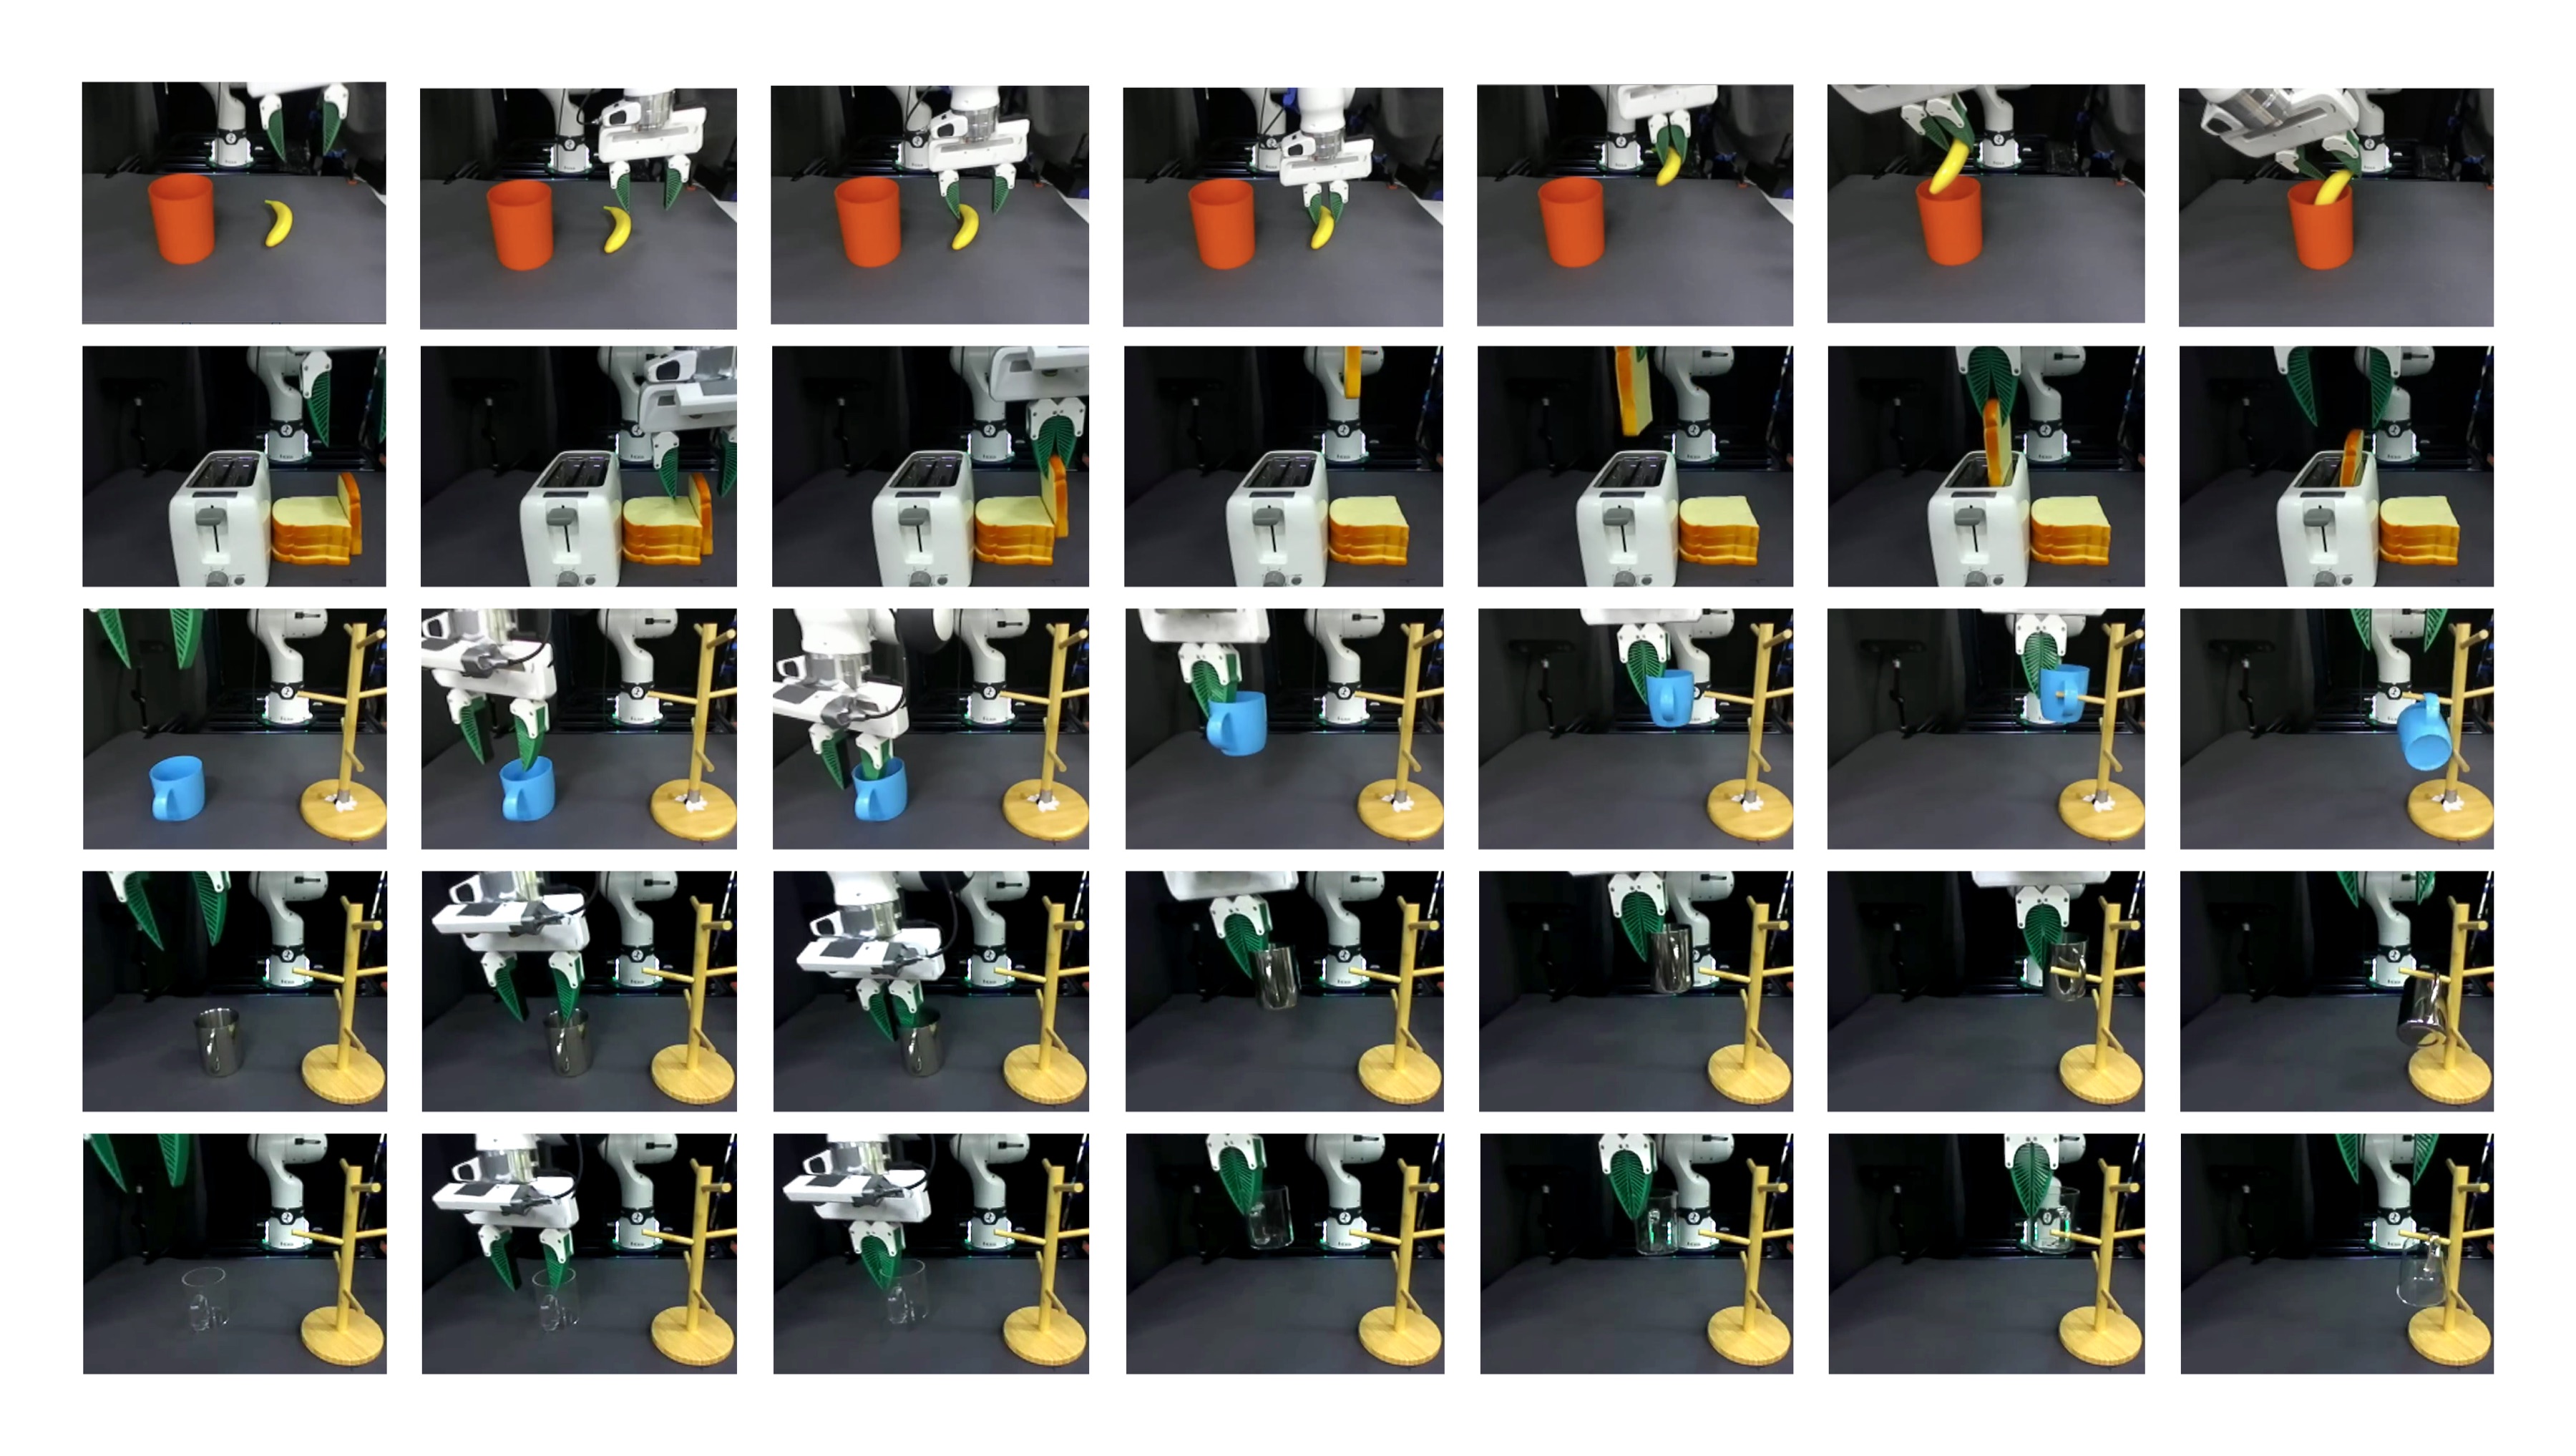
Each of five tabletop tasks has two hundred demonstrations: banana-to-container, toast-to-toaster, and hanging plastic, steel, or glass cups. The mobile robot has seventy-five demonstrations each for picking/operating/replacing a radio and transferring toast between hands before shelving it. These datasets and robot-specific tasks bound the reported transfer evidence.
A.1 Real-Robot Hardware Setup
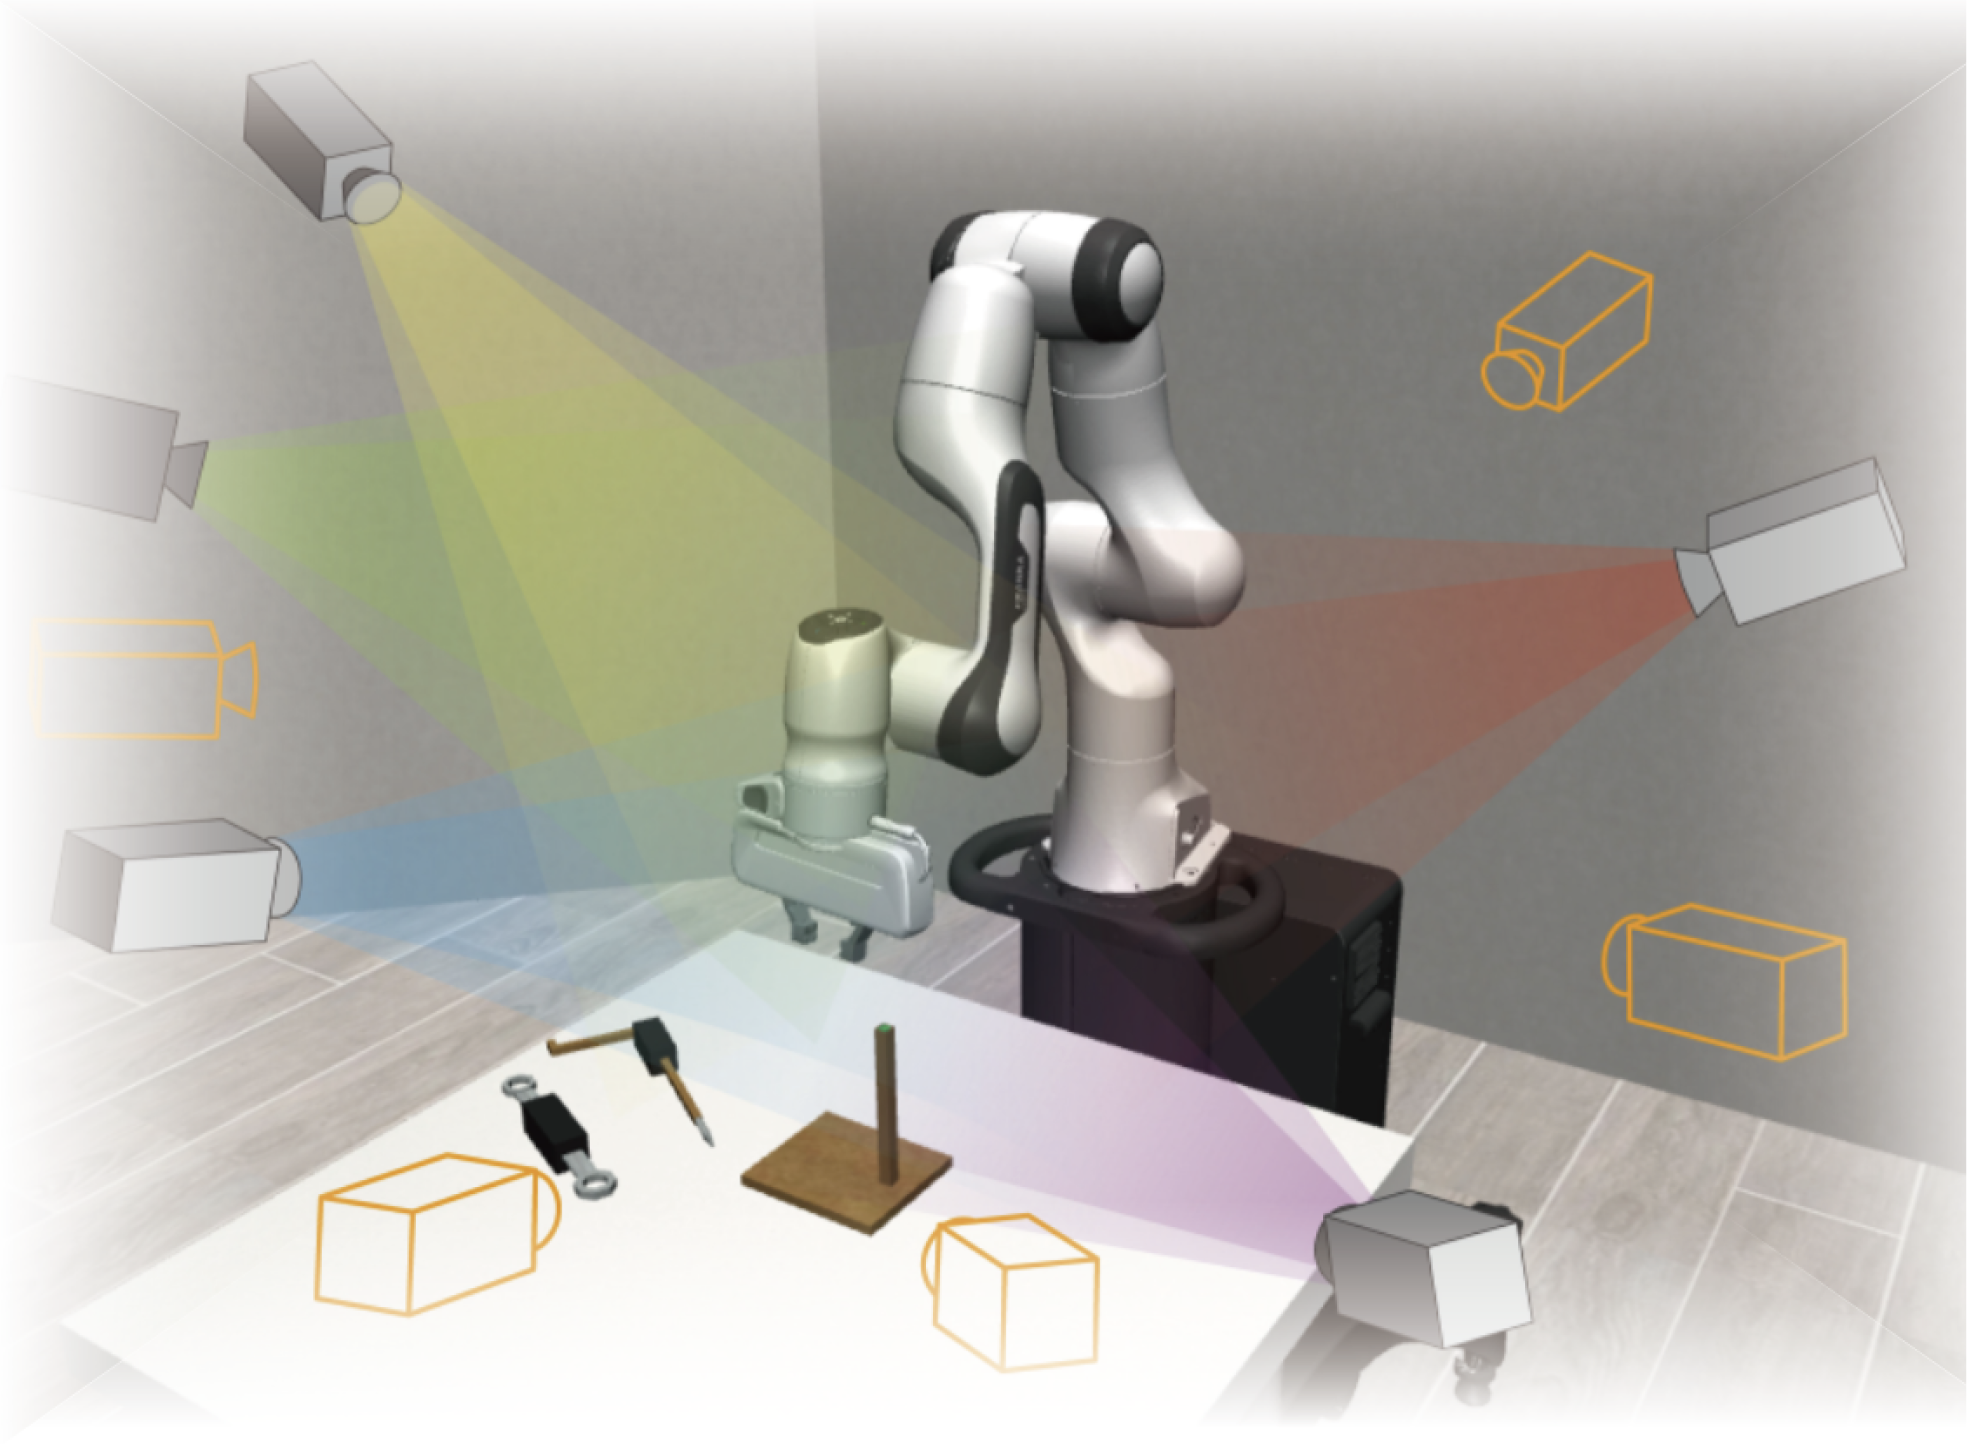
The Franka uses an external ZED Mini and a wrist-mounted ZED Mini. The R1 Pro has stereo cameras at both wrists. These physical rigs supply synchronized binocular observations rather than synthetic depth-free monocular inputs.
Appendix B Stereo Hardware Configurations
Camera studies separate training across configurations from applying a fixed trained policy at a changed baseline.
B.1 Stereo Baselines
Default simulated baselines are six centimetres externally and two at the wrist. Physical ZED Mini rigs have a fixed 6.3-centimetre baseline.
B.2 Test-Time Baseline Transfer
A policy trained at a six-centimetre baseline reaches 94% at that configuration, 86% at four centimetres, and 88% at eight, with camera-object distance fixed. This demonstrates moderate baseline tolerance, with best results at the training geometry; it does not establish arbitrary uncalibrated-camera transfer.
| Test baseline | 4 cm | 6 cm | 8 cm |
|---|---|---|---|
| Success rate (%) |
B.3 Stereo Views across Different Baselines and Distances
The retained image grid shows all tested baselines from 0.02 to 0.10 metres and distances from 0.59 to 0.99 metres. It makes visible the changes in disparity, overlap, and apparent object scale underlying the configuration sweep.
B.4 Camera Angle Mappings
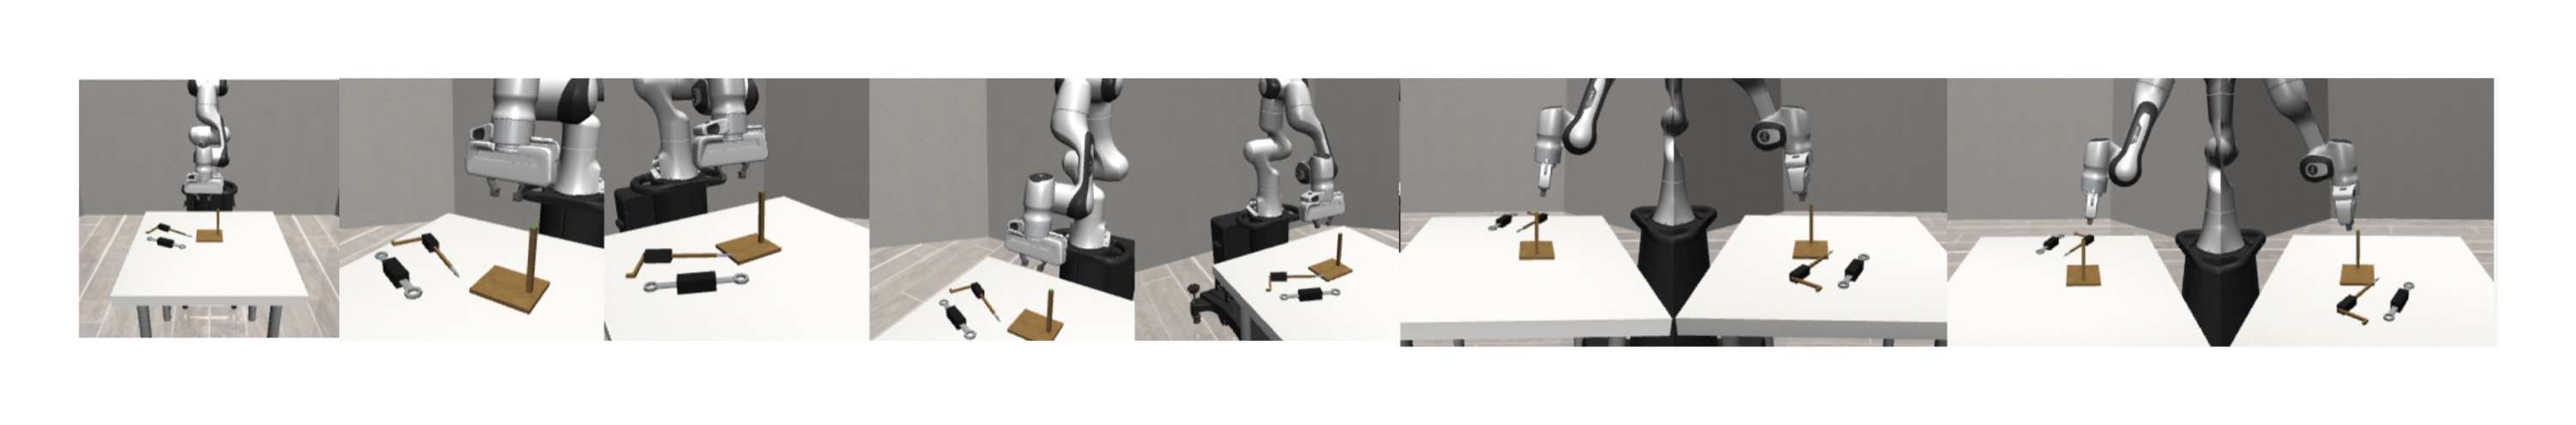
Ten named views cover frontal, oblique agent, and side positions at ordinary and elevated heights. The original view mapping is retained so the reported success differences can be tied to actual visibility and occlusion.
Appendix C Implementation Details
Implementation details specify stereo encoders, diffusion/VLA training, baseline preprocessing, and evaluation selection.
C.1 StereoPolicy-DP Training
Left/right images share ResNet18 and FPN weights. Frozen external DINO features are downsampled by a stride-four convolution, concatenated with CNN features, and projected into tokens. Two stereo layers with eight heads produce a 128-dimensional embedding per view; wrist encoders omit DINO. A GroupNorm UNet is trained from scratch with batch sixty-four and learning rate 10⁻⁴, two observation steps and sixteen predicted actions. Training runs five hundred Robomimic epochs or one thousand OmniGibson epochs.
C.2 StereoPolicy-VLA Training
GR00T-N1.5 finetuning runs sixty thousand steps at 10⁻⁴ learning rate. π0.5 runs eighty thousand steps with global batch 128, one thousand warmup steps, and cosine decay from 2.5×10⁻⁵ to 2.5×10⁻⁶. Both use eight H100 GPUs. At inference, all sixteen predicted actions execute before replanning, which is relevant to responsiveness.
C.3 Baseline Implementations
The matched monocular policy receives left-camera images, the same external DINO features, and capacity-adjusted attention. The matched multi-view policy separately encodes the identical stereo pair and concatenates features without token-level left/right attention. RGB-D repeats depth across three channels for a separate encoder. 3DDA lifts multi-scale RGB features into reconstructed geometry.
PointNet and DP3 fuse calibrated RGB-D point clouds in a common frame, crop the workspace, and farthest-point sample 4,096 points. FoundationStereo-feature controls replace trainable fusion with frozen pretrained features; estimated-depth controls replace the depth source while retaining their downstream RGB-D/3DDA pipelines. These are different interventions and should not be interpreted as one identical depth experiment.
C.4 Evaluation
Simulation evaluates one hundred rollouts every fifty Robomimic epochs or 250 OmniGibson epochs, reporting the highest success achieved over training across three seeds. Physical tasks use twenty trials with randomized starts. Selecting the best evaluated checkpoint can yield more optimistic estimates than a separately chosen final model evaluated once.
Appendix D Additional Ablations
Further ablations examine encoders, attention, foundation-model deployment, geometric probes, point-cloud quality, VLA two-image controls, latency, and wrist-camera removal.
D.1 Vision Encoder
Without DINO, ToolHang with one hundred demonstrations reaches 64% using ResNet alone, 78% CLIP, 80% SigLIP, 82% EdgeNext, and 84% ResNet/FPN. This favors multiscale FPN features in the tested setting, not a universal ranking of pretrained encoders.
| Benchmark | Robomimic | OmniGibson | ||
|---|---|---|---|---|
| Task | ToolHang-100 | Square-100 | PourWater-200 | Avg. SR |
| StereoPolicy-DP | 84.0 | |||
| with (L,L) input | 62.7 | |||
| w/o StereoTransformer | 70.0 | |||
| w/o FPN | 74.0 | |||
| w/o DINO | 76.0 | |||
| with DINO on both view | 79.3 | |||
D.2 Attention Design
With duplicated left images, joint and stereo attention give similar ToolHang/Square results (64/78 versus 62/76%), while PourWater already favors stereo attention 50% versus 42%. With genuine left/right images, stereo attention reaches 94/88/70%, versus joint attention 82/82/60%. Thus binocular inputs matter, but some PourWater benefit is architectural even without a second viewpoint.
| Fusion | Views | ToolHang-100 | Square-100 | PourWater-200 |
|---|---|---|---|---|
| Joint attention | ||||
| Joint attention | ||||
| Stereo Transformer | ||||
| Stereo Transformer |
D.3 Pre-trained Stereo Foundation Models on Real Robot
The physical foundation-model comparison measures the entire perception/control pipeline, including its timing.
Real robot with FoundationStereo
FoundationStereo+RGB-D succeeds on banana pick/place in only 1/20 physical trials, versus 16/20 for StereoPolicy. Observations become stale and actions delayed in the depth pipeline. The result combines estimation errors and execution latency; it does not isolate the causal contribution of either.
D.4 Geometric Information
Equal-capacity linear probes predict gripper-to-target camera-frame relative depth from frozen visual features, holding out complete trajectories and layouts. Action-trained stereo features improve errors from 3.1→1.1 cm on ToolHang and 4.0→1.5 on PourWater. Joint-attention stereo errors are 1.9/2.5 cm, and duplicated-input stereo errors 2.7/3.5. These probes show accessible geometric information under the tested probe, without proving depth information alone causes control gains.
D.5 Discussion on Point Clouds Policy Performance
Point clouds use the same views, calibrated common-frame fusion, workspace cropping, and 4,096-point sampling. Increasing to ten thousand points does not improve the tested result and increases cost. Missing/deformed geometry, especially around reflective/transparent cups and narrow toast slots, is a plausible bottleneck. This finding does not rule out better sensors, reconstruction, or other point-cloud policies.
D.6 StereoPolicy-VLA Performance
The VLA comparison averages all twenty-four RoboCasa tasks equally, with three seeds and one hundred episodes per task/seed. At thirty/one hundred/three hundred demos, π0.5 native two-image scores are 49.01/68.24/70.81%, versus StereoPolicy 51.72/71.54/74.40. GR00T native scores are 45.67/65.24/65.31%, versus stereo 47.12/66.17/67.50. Fusion therefore adds modest gains beyond merely supplying the second image.
| # Demos | ||||
|---|---|---|---|---|
| Backbone | Input | 30 | 100 | 300 |
| Monocular | ||||
| Two-image | ||||
| StereoPolicy-VLA | ||||
| GR00T-N1.5 | Monocular | |||
| GR00T-N1.5 | Two-image | |||
| GR00T-N1.5 | StereoPolicy-VLA | |||
D.7 Overhead, computational cost
StereoPolicy has 112 million parameters, including ten million in fusion, with reported 128 GFLOPs and 1.4G peak memory. H100 profiling uses batch one, two observations, sixteen actions, seven action dimensions, and one hundred denoising steps, after one hundred warmups and across one thousand synchronized calls. Median/95th-percentile latency is 698/736 ms, versus 695/731 for joint attention and 632/674 for RGB. The quoted three-millisecond overhead is relative to joint attention; the full pipeline adds sixty-six milliseconds over RGB and is not a three-millisecond controller.
D.8 Removing Wrist Observations
On ToolHang with two hundred demonstrations, removing wrist views changes stereo success 96→94%, RGB 90→86%, RGB-D 88→84%, and DP3 76→62%. External stereo is useful in this one-task test; this is not evidence that wrist cameras can always be removed without cost.
| Setting | RGB | RGB-D | PCD | RGB-D | Multi-View | StereoPolicy-DP | ||
|---|---|---|---|---|---|---|---|---|
| PointNet | PointNet++ | DP3 | 3DDA | |||||
| Default (w/ wrist camera) | ||||||||
| w/o wrist camera | ||||||||
Appendix E Qualitative Failure Cases
Qualitative examples connect failures to geometry and highlight remaining stereo limitations.
Baseline modality failures in tabletop manipulation.
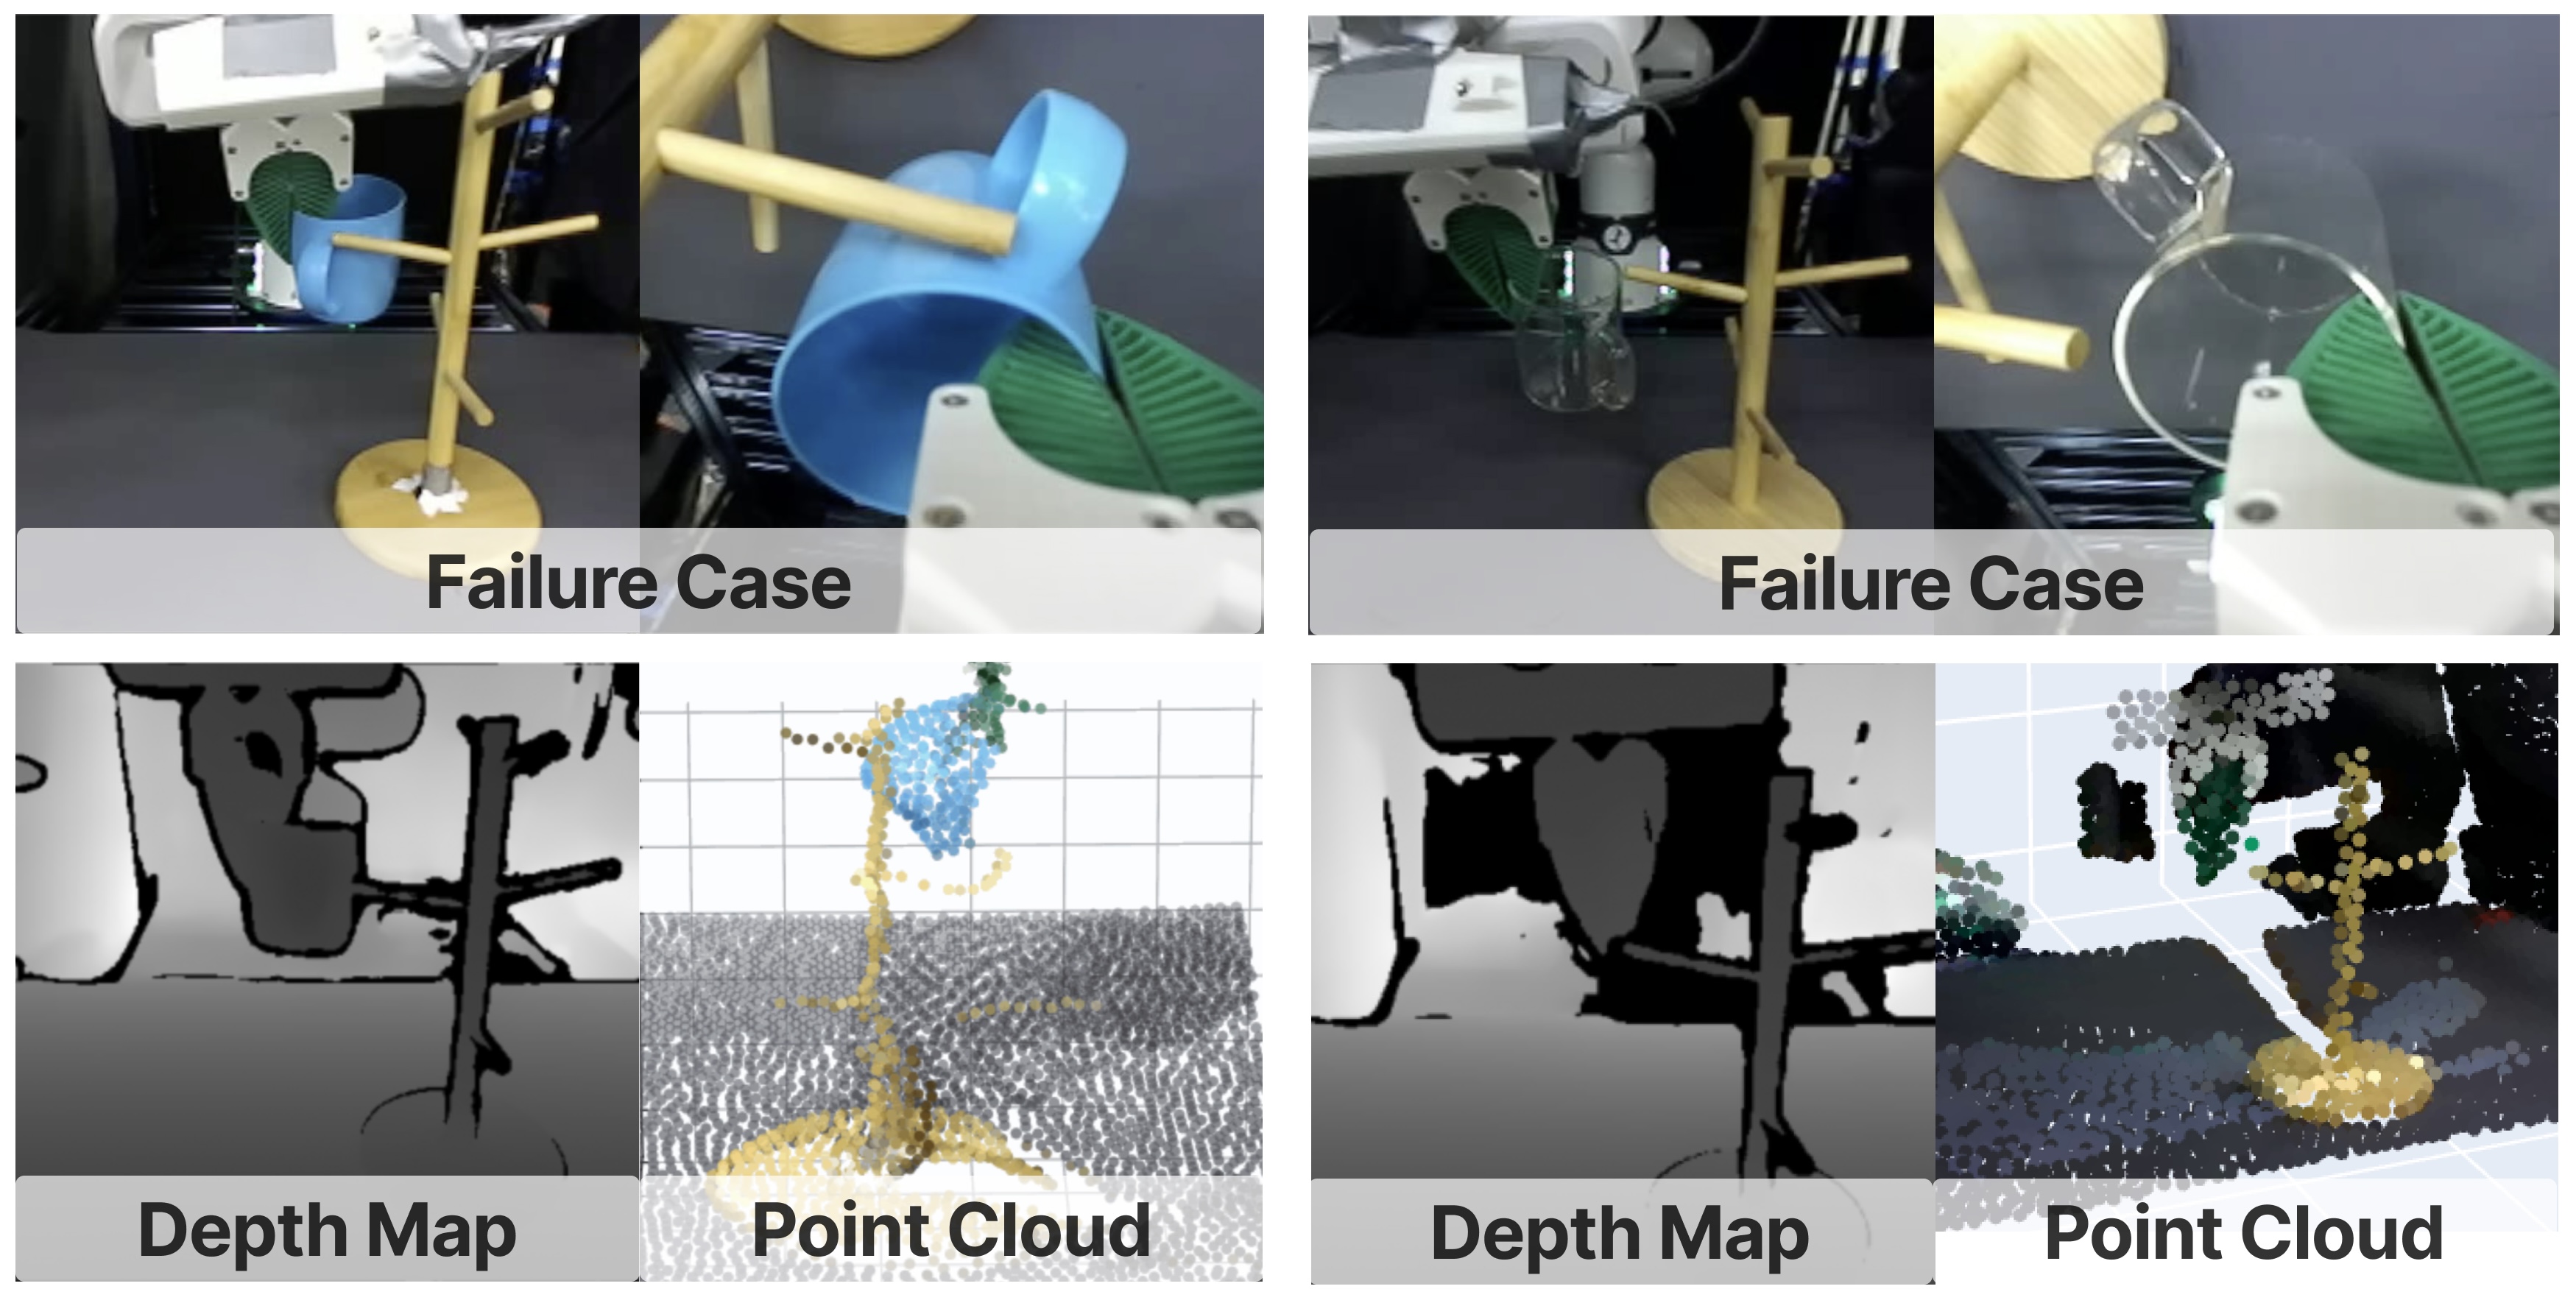
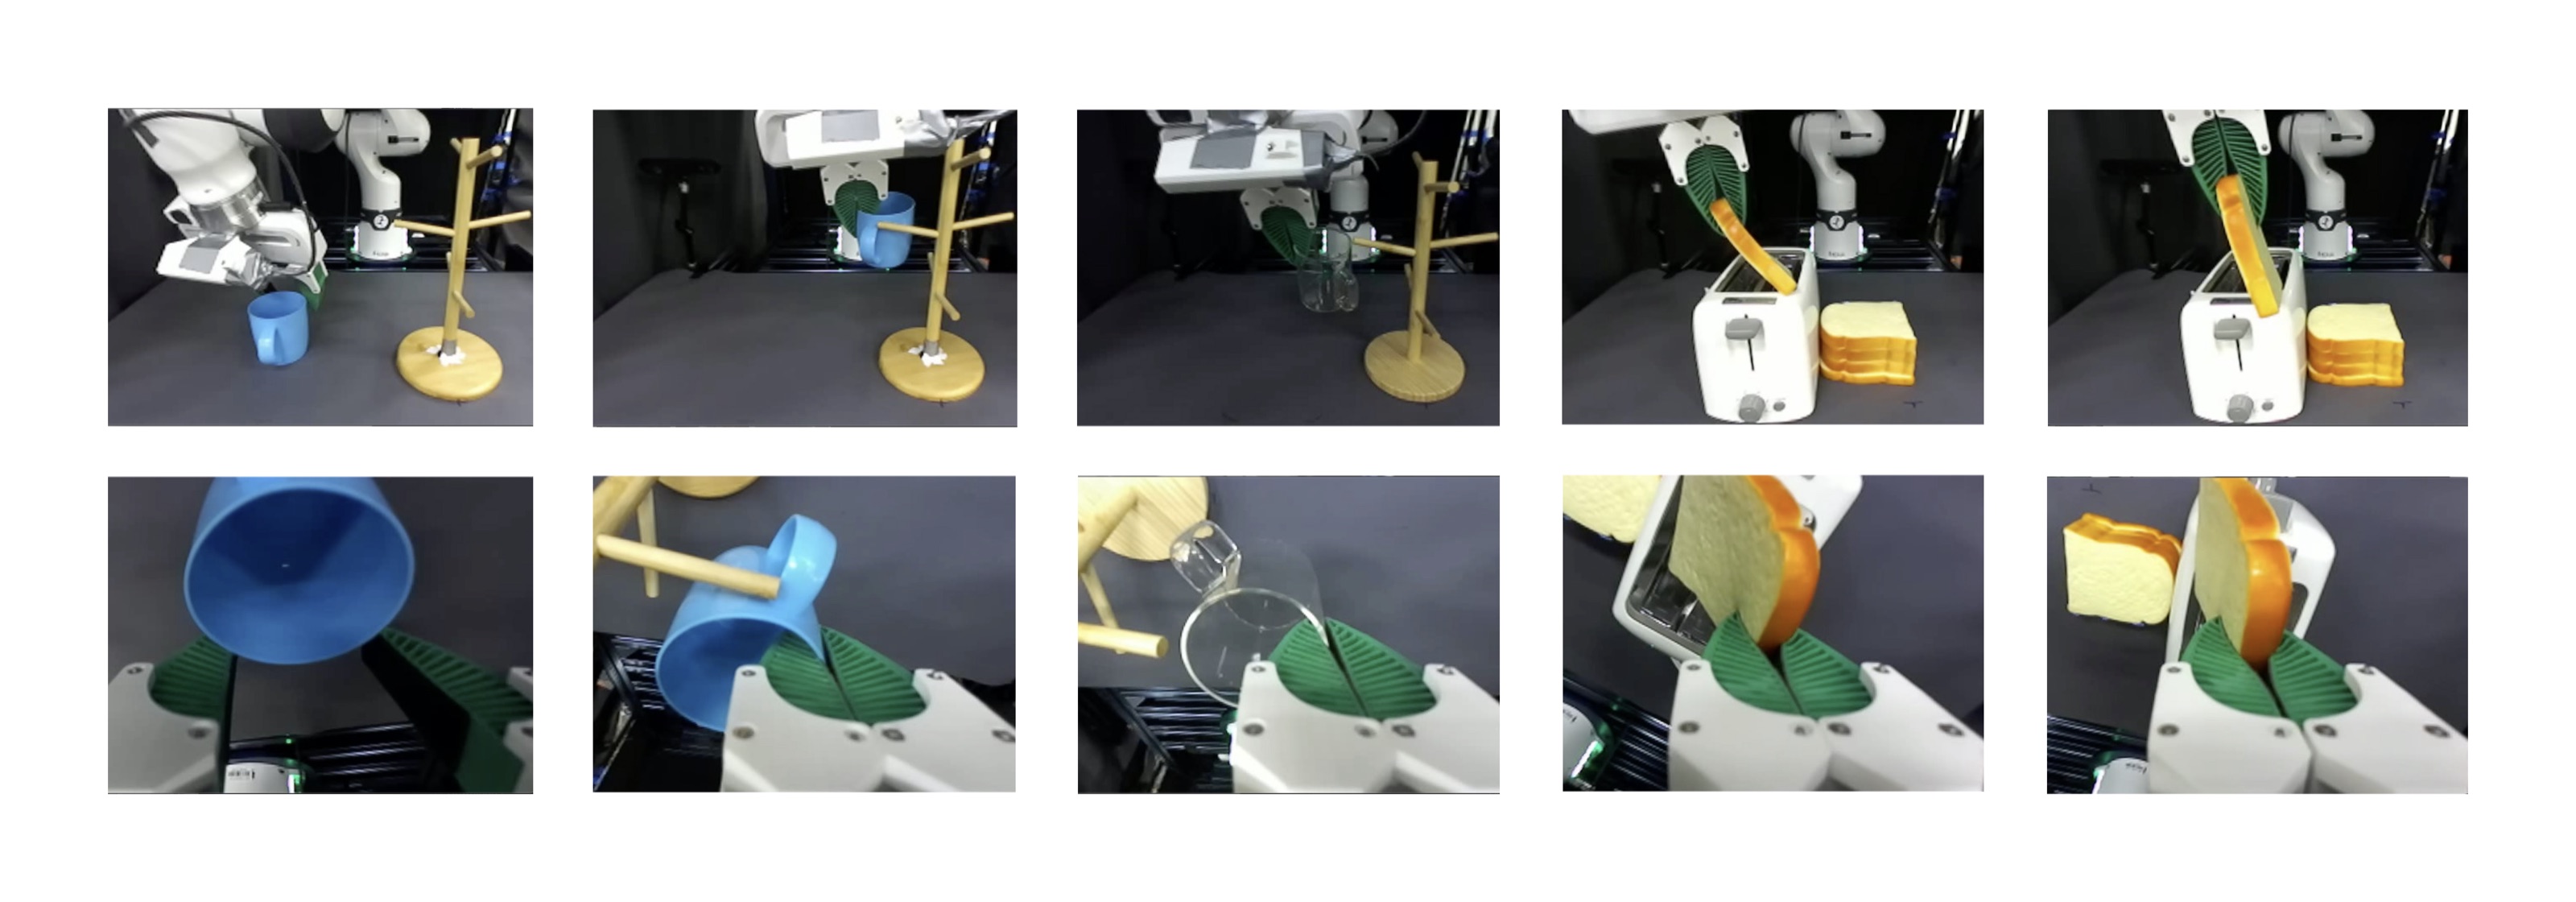
Weak cup boundaries lead to localization/grasp errors, noisy depth misaligns handles with pegs, and transparent glass can disappear from depth/point clouds. Toast failures include vertical or lateral slot misalignment. These examples illustrate plausible failure mechanisms rather than separately controlled causal measurements.
Remaining difficulty on transparent objects.
Glass success remains only 3/20. Refraction, thin rims/handles, and weak boundaries also make RGB correspondence and localization ambiguous. Avoiding depth reconstruction therefore does not solve transparent-object manipulation.
Monocular RGB failures in mobile manipulation.
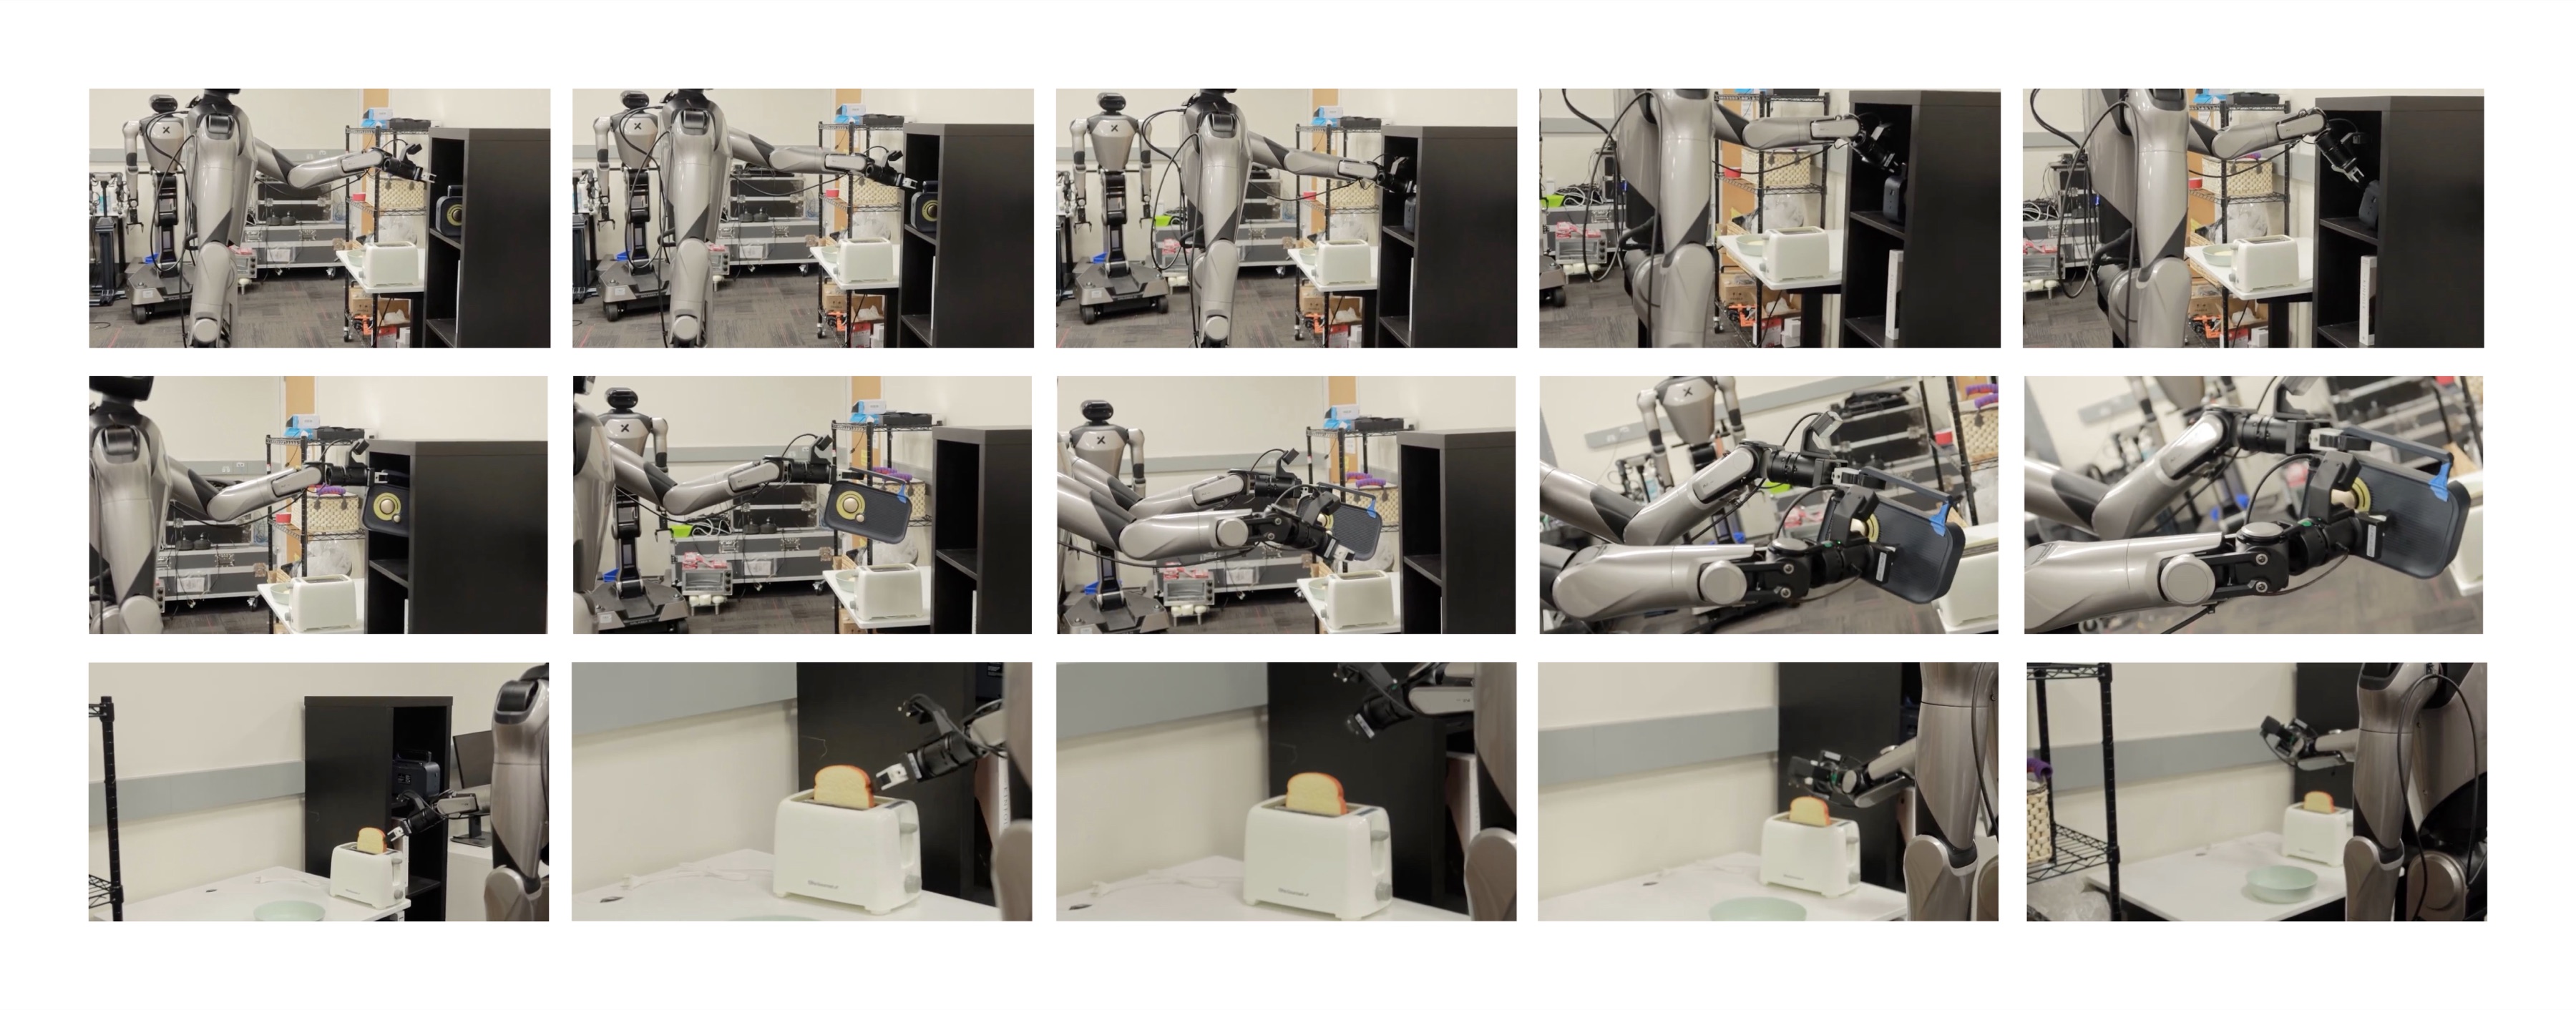
Monocular mobile policies can approach a radio yet miss its handle or button, and can locate toast yet fail grasp or placement alignment. Stereo improves these tested alignment behaviors, with the original trajectories retained to show both scene context and the specific failure stage.