Literature
Display
← All papers

Rectified LpJEPA: Joint-Embedding Predictive Architectures with Sparse and Maximum-Entropy Representations

Yilun Kuang · Yash Dagade · Tim G. J. Rudner · Randall Balestriero · Yann LeCun

Preprint posted · ICML 2026 (accepted) ↗

Learning theory10 min text · CondensedOriginal paper ↗
Contents

Overview

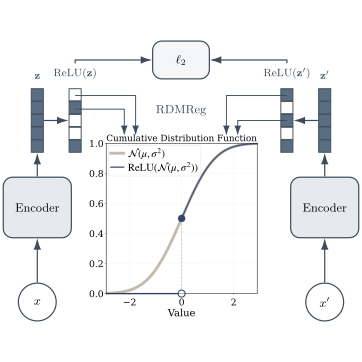
The opening diagram compares dense Gaussian regularization with a sparse, rectified target. Applying ReLU creates exact zeros. After that change, a random linear projection no longer has the same simple Gaussian target law, which motivates matching projected samples from both the learned and target distributions.

Original figureOriginal figure

1 Introduction

The paper changes JEPA’s anti-collapse target rather than only adding a penalty to a pretrained dense representation. Its aim is to retain task information while controlling the fraction of zero coordinates. Distribution matching connects the desired sparse statistics to a trainable objective; empirical accuracy and sparsity are measured separately.
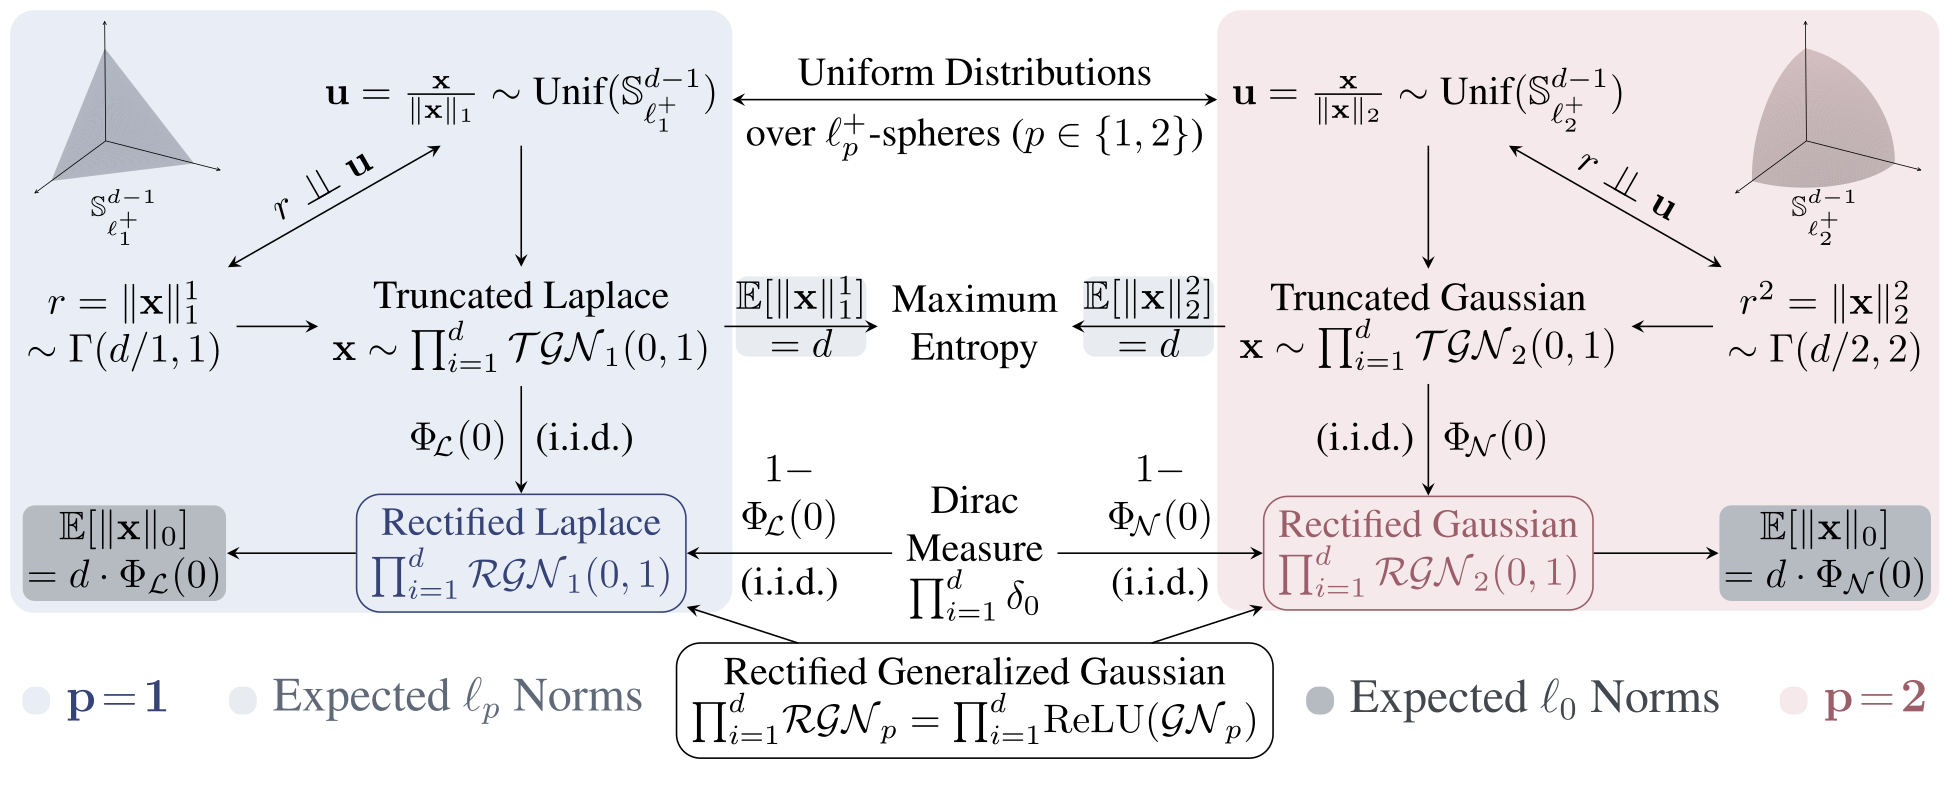
Complete original Figure 2 schematic from the exact-version PDF, retaining all panels, mathematical labels and vector artwork.
Figure 2: Rectified Laplace (p=1p=1) and Rectified Gaussian (p=2p=2) as special cases of Rectified Generalized Gaussian distributions. Assume μ=0\mu=0 and σ=1\sigma=1. For any p>0p>0, the Truncated Generalized Gaussian ∏i=1d𝒯​𝒢​𝒩p\prod_{i=1}^{d}\mathcal{TGN}_{p} over the product support (0,∞)d(0,\infty)^{d} is the maximum differential entropy distribution under a fixed expected ℓp\ell_{p}-norm constraint. For p∈{1,2}p\in\{1,2\}, ∏i=1d𝒯​𝒢​𝒩p\prod_{i=1}^{d}\mathcal{TGN}_{p} further admits a radial–angular decomposition 𝐱=r⋅𝐮\mathbf{x}=r\cdot\mathbf{u} with r⟂⟂𝐮r\perp\!\!\!\perp\mathbf{u}, where 𝐮\mathbf{u} is uniformly distributed with respect to the surface measure on the unit ℓp\ell_{p}-sphere confined to the positive orthant and rpr^{p} follows a Gamma distribution. Rectified Laplace and Rectified Gaussian arise via coordinate-wise mixing of the corresponding truncated distributions with a Dirac measure at zero, yielding a distribution with expected ℓ0\ell_{0}-norm guarantees, where Φℒ\Phi_{\mathcal{L}} and Φ𝒩\Phi_{\mathcal{N}} denote the cumulative distribution functions of the standard Laplace and standard Gaussian distributions respectively.

2 Background

Two sparsity notions are distinguished: exact zeros, counted by the zero-norm notation, and concentration of magnitude, estimated from one- and two-norm ratios. ReLU maps negative activations to zero, creating a point mass at zero. Nonnegative or sparse features can be useful, but the measured sparsity does not itself establish semantic interpretability.

3 Sparse and Maximum-Entropy Distributions

The target family combines continuous positive values with a controllable probability of exact zero. Maximum-entropy claims are made under specified support and expected-moment constraints; changing those constraints changes the optimum.

3.1 Generalized Gaussian Distributions

The generalized Gaussian family varies shape through a positive parameter p. It includes a Laplace distribution at p=1 and an ordinary Gaussian at p=2, with location and scale controlling the distribution’s placement and spread.

Definition 3.1 (Generalized Gaussian Distribution ).

The Generalized Gaussian distribution 𝒢​𝒩p​(μ,σ)\mathcal{GN}_{p}(\mu,\sigma) over the support (−∞,∞)(-\infty,\infty) has the probability density function

Equation 1
f𝒢​𝒩p​(μ,σ)​(x)=p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)\displaystyle f_{\mathcal{GN}_{p}(\mu,\sigma)}(x)=\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg) (1)

where Γ⁡(s):=∫0∞ts−1​e−t​𝑑t\Gamma(s):=\int^{\infty}_{0}t^{s-1}e^{-t}dt is the gamma function.

3.2 Truncated Generalized Gaussian Distributions

Truncation keeps only values in an allowed region and renormalizes their probabilities. A positive truncated distribution has no negative values, but unlike rectification it does not transfer all negative probability to an exact zero.

Definition 3.2 (Truncated Generalized Gaussian Distribution).

Let S⊆ℝS\subseteq\mathbb{R} be a subset of ℝ\mathbb{R} with positive Lebesgue measure. The Truncated Generalized Gaussian distribution 𝒯​𝒢​𝒩p​(μ,σ,S)\mathcal{TGN}_{p}(\mu,\sigma,S) is the restriction of the Generalized Gaussian distribution 𝒢​𝒩p​(μ,σ)\mathcal{GN}_{p}(\mu,\sigma) to the support SS. The probability density function of 𝒯​𝒢​𝒩p​(μ,σ,S)\mathcal{TGN}_{p}(\mu,\sigma,S) is given by

Equation 2
f𝒯​𝒢​𝒩p​(μ,σ,S)​(x)=𝟙S​(x)ZS​(μ,σ,p)​exp⁡(−|x−μ|pp​σp)\displaystyle f_{\mathcal{TGN}_{p}(\mu,\sigma,S)}(x)=\frac{\mathbbm{1}_{S}(x)}{Z_{S}(\mu,\sigma,p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg) (2)

where 𝟙S​(x)\mathbbm{1}_{S}(x) is the indicator function that evaluates to 11 if x∈Sx\in S and 00 otherwise. The partition function is

Equation 3
ZS​(μ,σ,p)=∫Sexp⁡(−|x−μ|pp​σp)​𝑑𝐱\displaystyle Z_{S}(\mu,\sigma,p)=\int_{S}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)d\mathbf{x} (3)

3.3 Maximum Entropy under ℓ p Constraints

Under a fixed expected p-th-power magnitude and specified support, the derivation identifies the corresponding maximum-differential-entropy distribution. This is a constrained statistical statement, not a claim that maximum entropy guarantees the best representation for arbitrary labels.

Proposition 3.3 (Maximum Entropy Characterizations of Multivariate Truncated Generalized Gaussian Distributions).

The maximum entropy distribution over S⊆ℝdS\subseteq\mathbb{R}^{d}, where SS is a subset of ℝd\mathbb{R}^{d} with positive Lebesgue measure, under the constraints

Equation 4
∫Sp⁡(𝐱)​𝑑𝐱\displaystyle\int_{S}p(\mathbf{x})d\mathbf{x} =1,𝔼⁡[‖𝐱‖pp]=dd​λ1​log⁡ZS​(λ1)\displaystyle=1,\quad\mathbb{E}[\|\mathbf{x}\|_{p}^{p}]=\frac{d}{d\lambda_{1}}\log Z_{S}(\lambda_{1}) (4)

is the Multivariate Truncated Generalized Gaussian distribution ∏i=1d𝒯​𝒢​𝒩p​(0,σ,S)\prod_{i=1}^{d}\mathcal{TGN}_{p}(0,\sigma,S) with probability density function

Equation 5
p⁡(x)=1ZS​(λ1)​exp⁡(−‖𝐱‖ppp​σp)⋅𝟙S​(𝐱)\displaystyle p(x)=\frac{1}{Z_{S}(\lambda_{1})}\exp\bigg(-\frac{\|\mathbf{x}\|_{p}^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{S}(\mathbf{x}) (5)

where λ1=−1/pσp\lambda_{1}=-1/p\sigma^{p} and ZS​(λ1)Z_{S}(\lambda_{1}) is the partition function.

3.4 Rectified Generalized Gaussian Distributions

Rectification samples the underlying generalized Gaussian, keeps positive values and maps nonpositive values to zero. The result mixes a discrete spike at zero with a continuous positive distribution. That mixed nature distinguishes it from a merely truncated density.

Definition 3.4 (Rectified Generalized Gaussian).

The Rectified Generalized Gaussian distribution ℛ​𝒢​𝒩p​(μ,σ)\mathcal{RGN}_{p}(\mu,\sigma) is a mixture between a discrete Dirac measure δ0​(x)\delta_{0}(x) (Definition B.4) and a Truncated Generalized Gaussian distribution 𝒯​𝒢​𝒩p​(μ,σ,(0,∞))\mathcal{TGN}_{p}(\mu,\sigma,(0,\infty)) with probability density function

Equations 6–7
fℛ​𝒢​𝒩p​(μ,σ)​(x)=Φ𝒢​𝒩p​(0,1)​(−μσ)⋅𝟙{0}​(x)\displaystyle f_{\mathcal{RGN}_{p}(\mu,\sigma)}(x)=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbbm{1}_{\{0\}}(x) (6)
+p1−1/p2​σ​Γ​(1/p)exp(−|x−μ|pp​σp)⋅𝟙(0,∞)(x)\displaystyle+\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x) (7)

where Φ𝒢​𝒩p​(0,1)\Phi_{\mathcal{GN}_{p}(0,1)} is the cumulative distribution function for the standard Generalized Gaussian distribution 𝒢​𝒩p​(0,1)\mathcal{GN}_{p}(0,1).

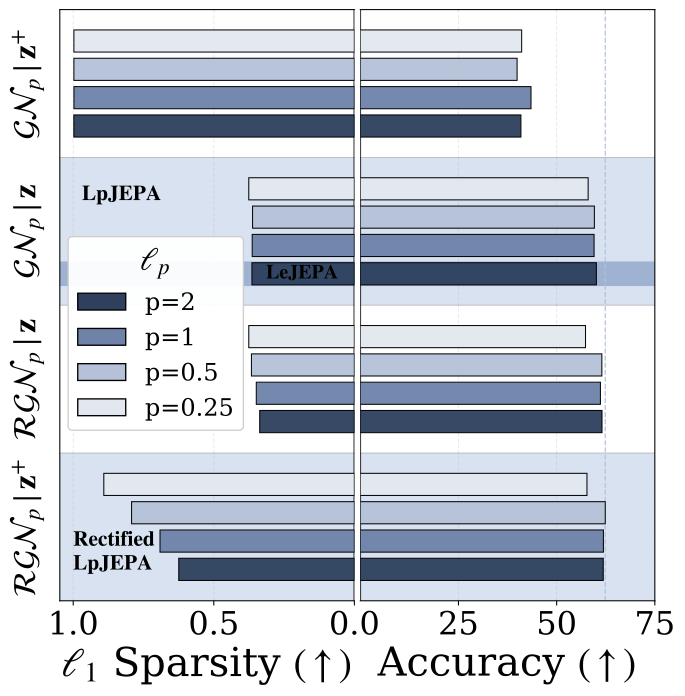
Original figure
(a) Necessity of Rectification.
Original figure
(b) Controllable Sparsity.
Original figure
(c) Sparsity and Performance Tradeoff.
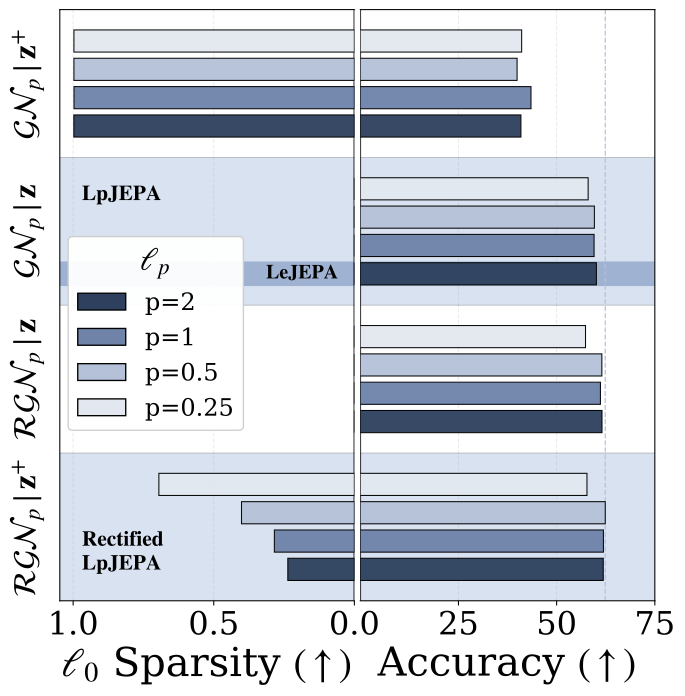
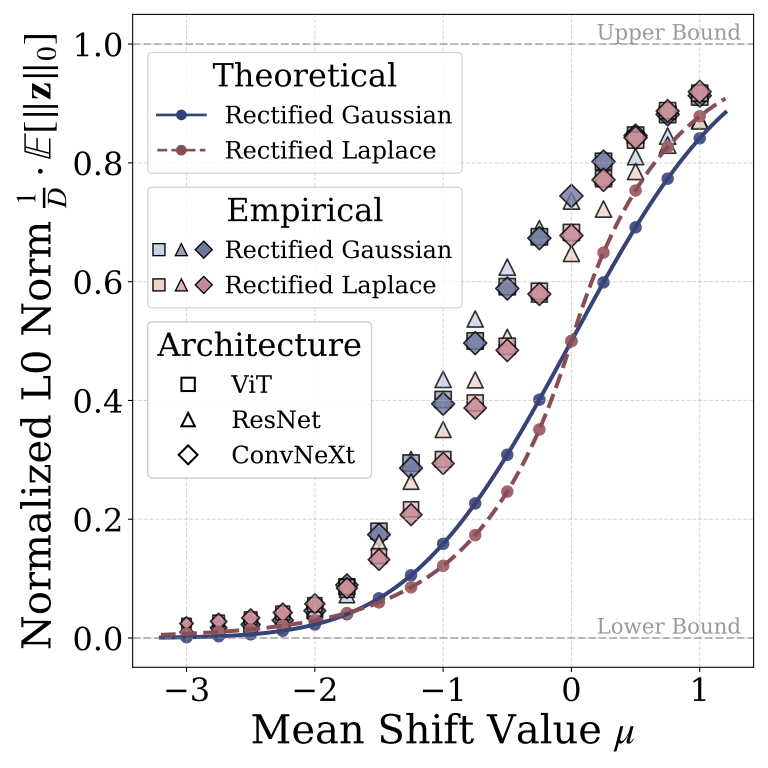
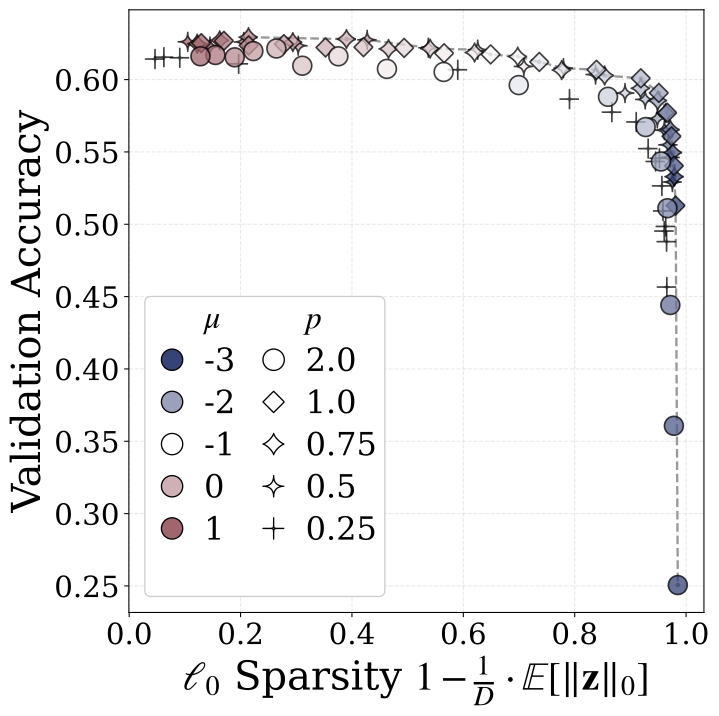
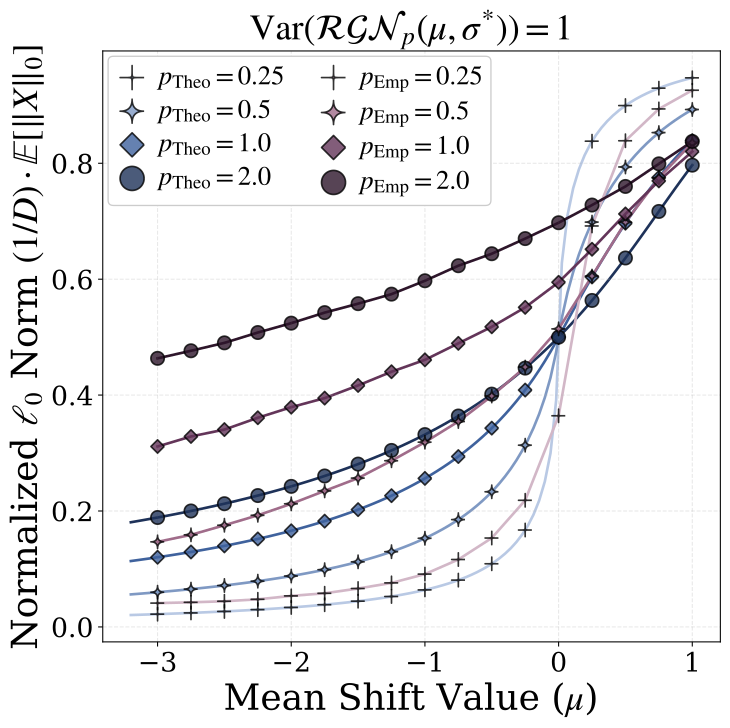
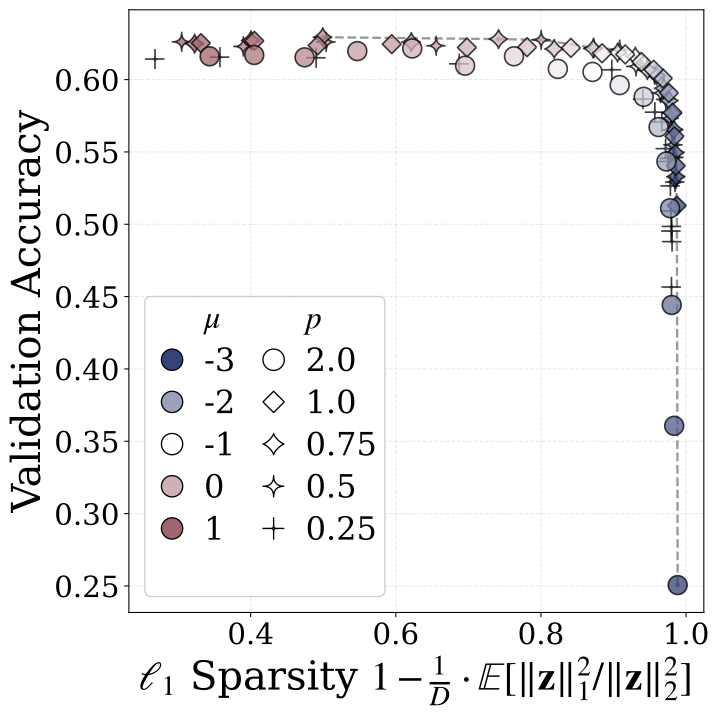
Figure 3: Rectified LpJEPA achieves controllable sparsity and favorable sparsity-performance tradeoffs under proper parameterizations. (a) We report CIFAR-100 validation accuracy and the ℓ0\ell_{0} sparsity metric 1−(1/d)⋅𝔼⁡[‖𝐱‖0]1-(1/d)\cdot\mathbb{E}[\|\mathbf{x}\|_{0}] for four settings where we match non-rectified features 𝐳\mathbf{z} or rectified features 𝐳+:=ReLU⁡(𝐳)\mathbf{z}^{+}:=\operatorname{ReLU}(\mathbf{z}) to either Rectified Generalized Gaussian ℛ​𝒢​𝒩p\mathcal{RGN}_{p} or conventional Generalized Gaussian 𝒢​𝒩p\mathcal{GN}_{p}. Rectified LpJEPA (ℛ​𝒢​𝒩p∣𝐳+)(\mathcal{RGN}_{p}\mid\mathbf{z}^{+}) achieves the best sparsity-performance tradeoffs compared to other settings. (b) We compare the normalized ℓ0\ell_{0} norm of pretrained Rectified LpJEPA features against the theoretical predictions of Proposition 3.5 as μ\mu varies. Empirical sparsity closely follows the predicted behavior across different values of μ\mu and pp. (c) We plot the Pareto frontier of sparsity versus accuracy across varying values of μ\mu and pp. Performance drops sharply only when more than ∼95%\sim\!95\% of entries are zero.

3.5 Sparsity and Entropy

For a symmetric zero-centered target, roughly half the coordinates are zero after rectification. Shifting the underlying distribution toward negative values increases that fraction. Because the target has both discrete and continuous parts, ordinary continuous differential entropy is not the right single measure; the paper uses Rényi information dimension and a related entropy characterization.

Proposition 3.5 (Sparsity).

Let 𝐱∼∏i=1dℛ​𝒢​𝒩p​(μ,σ)\mathbf{x}\sim\prod_{i=1}^{d}\mathcal{RGN}_{p}(\mu,\sigma) in dd dimension. Then

Equations 8–9
𝔼⁡[‖𝐱‖0]\displaystyle\mathbb{E}[\|\mathbf{x}\|_{0}] =d⋅Φ𝒢​𝒩p​(0,1)​(μσ)\displaystyle=d\cdot\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg) (8)
=d2​(1+sgn⁡(μσ)​P​(1p,|μ/σ|pp))\displaystyle=\frac{d}{2}\bigg(1+\operatorname{sgn}\bigg(\frac{\mu}{\sigma}\bigg)P\bigg(\frac{1}{p},\frac{|\mu/\sigma|^{p}}{p}\bigg)\bigg) (9)

where sgn⁡(⋅)\operatorname{sgn}(\cdot) is the sign function and P⁡(⋅,⋅)P(\cdot,\cdot) is the lower regularized gamma function.

Theorem 3.6 (Rényi Information Dimension Characterizations of Multivariate Rectified Generalized Gaussian Distributions).

Let 𝛏∼∏i=1Dℛ​𝒢​𝒩p​(μ,σ)\boldsymbol{\xi}\sim\prod_{i=1}^{D}\mathcal{RGN}_{p}(\mu,\sigma) be a Rectified Generalized Gaussian random vector. The Rényi information dimension of 𝛏\boldsymbol{\xi} is d⁡(𝛏)=D⋅Φ𝒢​𝒩p​(0,1)​(μ/σ)d(\boldsymbol{\xi})=D\cdot\Phi_{\mathcal{GN}_{p}(0,1)}(\mu/\sigma), and the d⁡(𝛏)d(\boldsymbol{\xi})-dimensional entropy of 𝛏\boldsymbol{\xi} is given by

Equations 10–12
ℍd⁡(𝝃i)​(𝝃i)\displaystyle\mathbb{H}_{d(\boldsymbol{\xi}_{i})}(\boldsymbol{\xi}_{i}) =Φ𝒢​𝒩p​(0,1)​(μσ)⋅ℍ1​(𝒯​𝒢​𝒩p​(μ,σ))\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg)\cdot\mathbb{H}_{1}(\mathcal{TGN}_{p}(\mu,\sigma)) (10)
+ℍ0​(𝟙(0,∞)​(𝝃i))\displaystyle+\mathbb{H}_{0}(\mathbbm{1}_{(0,\infty)}(\boldsymbol{\xi}_{i})) (11)
ℍd⁡(𝝃)​(𝝃)\displaystyle\mathbb{H}_{d(\boldsymbol{\xi})}(\boldsymbol{\xi}) =∑i=1Dℍd⁡(𝝃i)​(𝝃i)=D⋅ℍd⁡(𝝃i)​(𝝃i)\displaystyle=\sum_{i=1}^{D}\mathbb{H}_{d(\boldsymbol{\xi}_{i})}(\boldsymbol{\xi}_{i})=D\cdot\mathbb{H}_{d(\boldsymbol{\xi}_{i})}(\boldsymbol{\xi}_{i}) (12)

where ℍ0​(⋅)\mathbb{H}_{0}(\cdot) is the discrete Shannon entropy, ℍ1​(⋅)\mathbb{H}_{1}(\cdot) denotes the differential entropy, and 𝟙(0,∞)​(𝛏i)\mathbbm{1}_{(0,\infty)}(\boldsymbol{\xi}_{i}) is a Bernoulli random variable that equals 11 with probability Φ𝒢​𝒩p​(0,1)​(μ/σ)\Phi_{\mathcal{GN}_{p}(0,1)}(\mu/\sigma) and 00 with probability 1−Φ𝒢​𝒩p​(0,1)​(μ/σ)1-\Phi_{\mathcal{GN}_{p}(0,1)}(\mu/\sigma).

Proof.

See Section F.2. ∎

4 Rectified LpJEPA

Rectified LpJEPA aligns related rectified embeddings while matching their distribution to the selected sparse target. RDMReg implements the matching; mean, scale and shape control the target’s sparsity and spread.

4.1 Cramér–Wold Based Distribution Matching

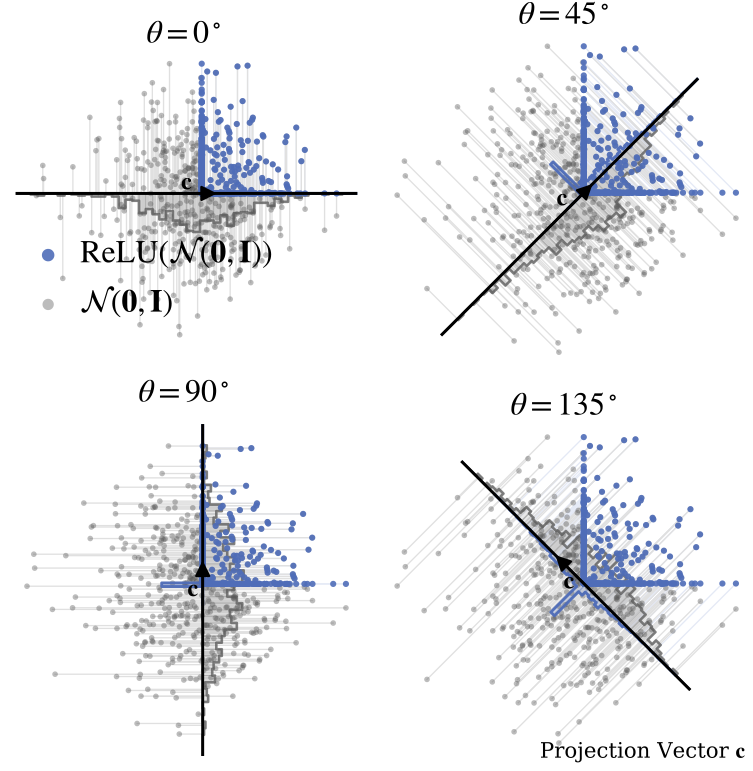
At the population level, two distributions agree exactly when all one-dimensional linear projections agree. In practice, a finite collection of projected sample comparisons approximates this criterion; it is not a proof of full joint-distribution equality.

Equation 13
𝐱=d𝐲⇔𝐜⊤​𝐱=d𝐜⊤​𝐲​ for all ​𝐜∈ℝd\displaystyle\mathbf{x}\stackrel{{\scriptstyle\operatorname{d}}}{{=}}\mathbf{y}\iff\mathbf{c}^{\top}\mathbf{x}\stackrel{{\scriptstyle\operatorname{d}}}{{=}}\mathbf{c}^{\top}\mathbf{y}\text{ for all }\mathbf{c}\in\mathbb{R}^{d} (13)

4.2 Rectified LpJEPA with RDMReg

The encoder/projector outputs pass through ReLU. Training balances agreement between paired views with a distance between learned features and samples drawn from the target distribution. This directly teaches the rectified representation, rather than hoping that sparsifying a separately trained dense representation preserves its information.

Equations 14–15
min𝜽\displaystyle\min_{\boldsymbol{\theta}}\, 𝔼𝐳,𝐳′​[‖𝐳−𝐳′‖22]\displaystyle\mathbb{E}_{\mathbf{z},\mathbf{z}^{\prime}}[\|\mathbf{z}-\mathbf{z}^{\prime}\|_{2}^{2}] (14)
+𝔼𝐜[ℒ(ℙ𝐜⊤​𝐳∥ℙ𝐜⊤​𝐲)]+𝔼𝐜[ℒ(ℙ𝐜⊤​𝐳′∥ℙ𝐜⊤​𝐲)]\displaystyle+\mathbb{E}_{\mathbf{c}}[\mathcal{L}(\mathbb{P}_{\mathbf{c}^{\top}\mathbf{z}}\|\mathbb{P}_{\mathbf{c}^{\top}\mathbf{y}})]+\mathbb{E}_{\mathbf{c}}[\mathcal{L}(\mathbb{P}_{\mathbf{c}^{\top}\mathbf{z}^{\prime}}\|\mathbb{P}_{\mathbf{c}^{\top}\mathbf{y}})] (15)

4.3 The Necessity of Two-Sample Hypothesis Testing

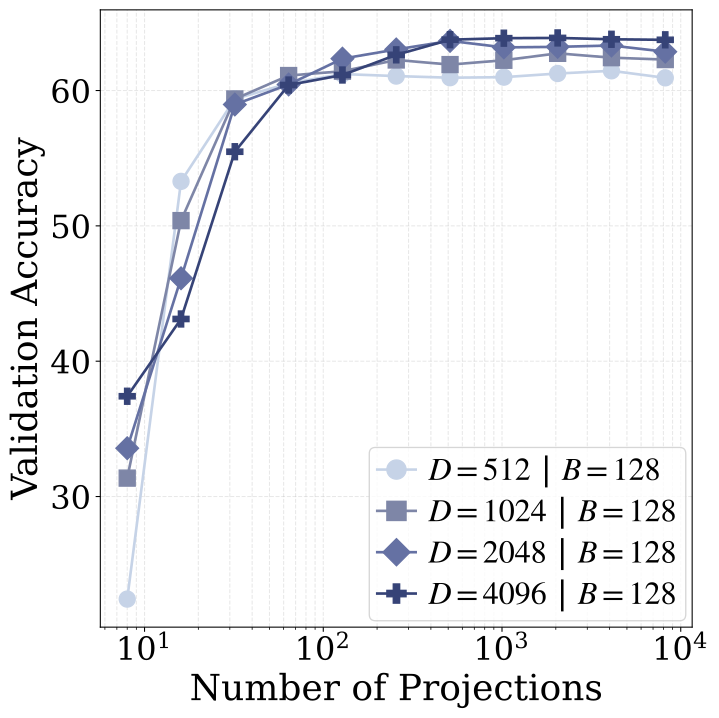
Unlike a Gaussian, a rectified target is not closed under arbitrary linear projections. The implementation therefore projects both learned and target samples and compares the two empirical sets. Its sliced Wasserstein objective sorts each projected sample set and matches corresponding values. The reported finite projection count works empirically under the tested settings.

Equation 16
ℒ(ℙ𝐜i⊤​𝐳∥ℙ𝐜i⊤​𝐲):=1B∥(𝐙𝐜i)↑−(𝐘𝐜i)↑∥22\displaystyle\mathcal{L}(\mathbb{P}_{\mathbf{c}_{i}^{\top}\mathbf{z}}\|\mathbb{P}_{\mathbf{c}_{i}^{\top}\mathbf{y}}):=\frac{1}{B}\|(\mathbf{Z}\mathbf{c}_{i})^{\uparrow}-(\mathbf{Y}\mathbf{c}_{i})^{\uparrow}\|_{2}^{2} (16)

4.4 Connection to Non-Negative VCReg

The connection to nonnegative variance–covariance regularization is conditional: matching projected marginals along covariance eigenvectors yields an isotropic centered covariance. This does not mean arbitrary finitely sampled directions exactly recover every covariance condition. Eigenvector-based projections are tested as an acceleration.

4.5 Hyperparameters of the Target Distributions

Location, scale and shape jointly control sparsity. Scale can normalize either the pre-rectification or post-rectification variance; these are different choices. A closed-form moment expression and bisection procedure support the latter. The default recipe normalizes the unrectified variance.

Table 1: Linear Probe Results on ImageNet-100. Acc1 (%) is higher-is-better (↑\uparrow); sparsity is lower-is-better (↓\downarrow). Bold denotes best and underline denotes second-best in each column (ties allowed).
Encoder Acc1 ↑\uparrow Projector Acc1 ↑\uparrow L1 Sparsity ↓\downarrow L0 Sparsity ↓\downarrow
Rectified LpJEPA ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 84.72 80.40 0.2726 0.6940
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 85.08 80.00 0.3412 0.7298
ℛ​𝒢​𝒩1.0​(0.25,σGN)\mathcal{RGN}_{1.0}(0.25,\sigma_{\operatorname{GN}}) 84.98 80.76 0.3745 0.7437
ℛ​𝒢​𝒩2.0​(1.0,σGN)\mathcal{RGN}_{2.0}(1.0,\sigma_{\operatorname{GN}}) 85.08 80.54 0.6278 0.8668
ℛ​𝒢​𝒩2.0​(−2.5,σGN)\mathcal{RGN}_{2.0}(-2.5,\sigma_{\operatorname{GN}}) 82.02 67.82 0.0137 0.0224
ℛ​𝒢​𝒩1.0​(−3.0,σGN)\mathcal{RGN}_{1.0}(-3.0,\sigma_{\operatorname{GN}}) 82.72 71.88 0.0058 0.0098
Sparse Baselines NVICReg-ReLU 84.48 77.74 0.5207 0.7117
NCL-ReLU 82.58 76.88 0.0037 0.0085
NVICReg-RepReLU 84.20 78.18 0.4965 0.7549
NCL-RepReLU 82.76 76.70 0.0024 0.0048
Dense Baselines VICReg 84.18 78.88 0.7954 1.0000
SimCLR 83.44 77.90 0.6338 1.0000
LeJEPA 84.80 79.52 0.6365 1.0000

5 Empirical Results

The experiments measure both task performance and representation statistics. A method with more zeros is not automatically better: useful sparsity must be evaluated together with accuracy, dependence and transfer.

5.1 Experimental Settings

Baselines include dense contrastive and variance-regularized methods and their nonnegative counterparts. Linear probes read either encoder features or rectified projector features, which are different representations. Both exact-zero and magnitude-based sparsity are reported to avoid confusing many small values with actual zeros.

Refer to caption
(a) d⁡(ξ)d(\xi)-dimensional Entropy
Original figure
(b) Hilbert-Schmidt independence Criterion (HSIC).
Original figure
(c) Dataset-Adaptive Sparsity
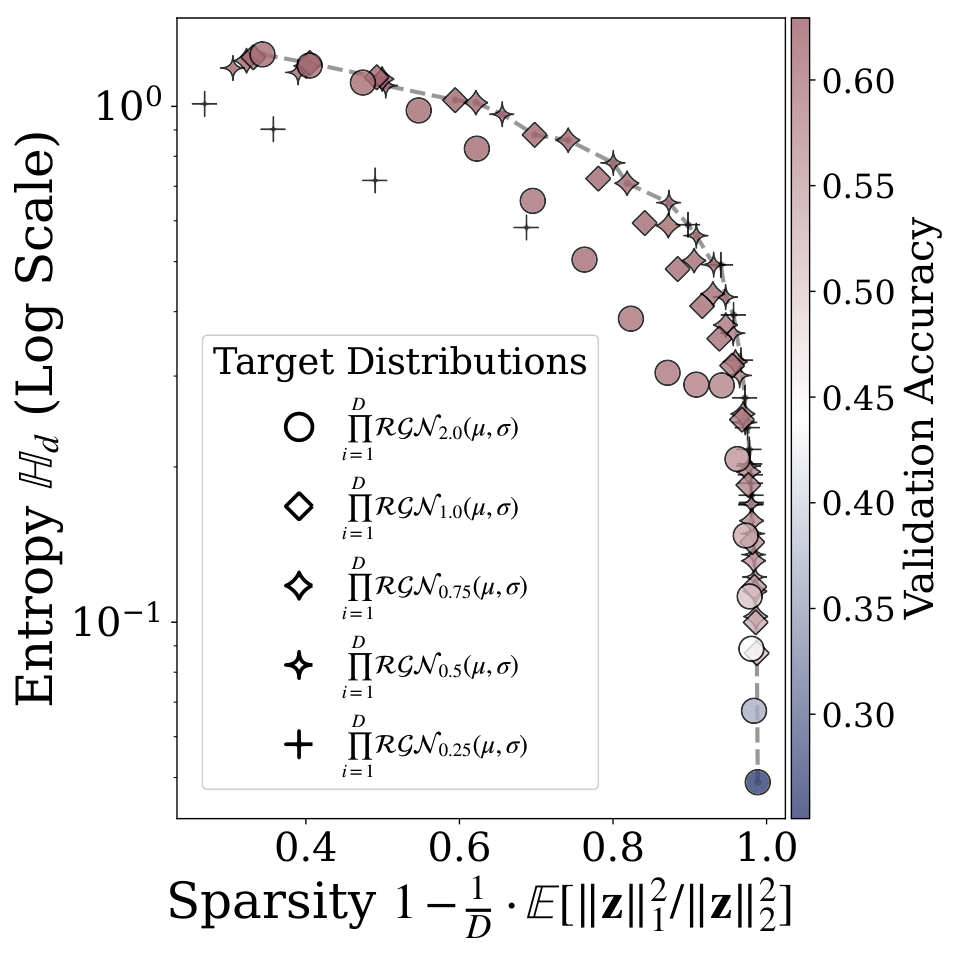
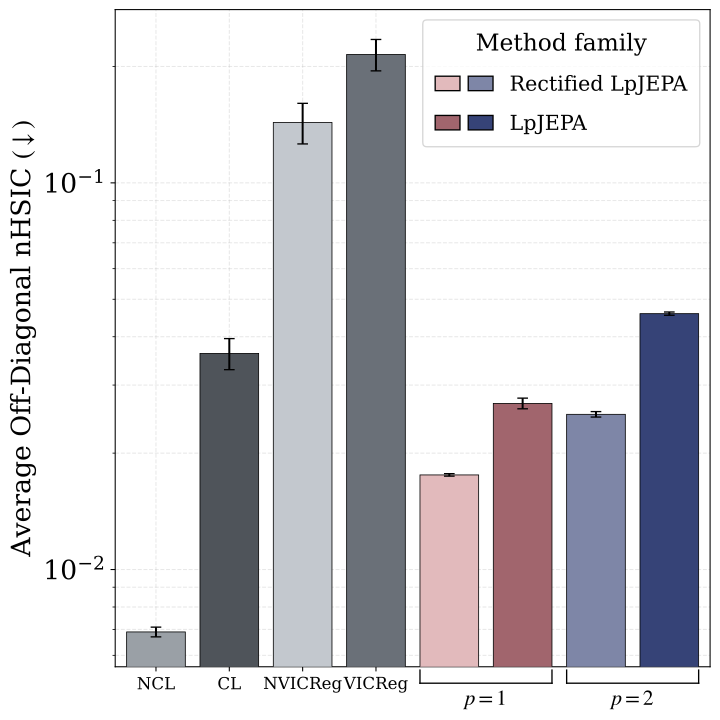
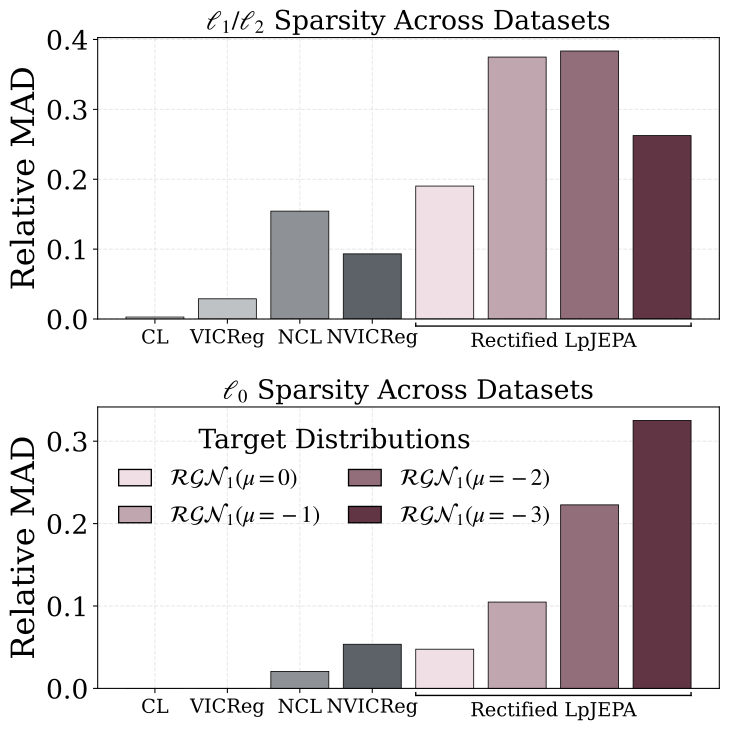
Figure 4: Rectified LpJEPA empirically achieves higher-entropy, more independent features with dataset-adaptive sparsity. (a) The averaged univariate d⁡(ξ)d(\xi)-dimensional entropy of the Rectified LpJEPA features are computed against the ℓ1\ell_{1} sparsity metric 1−(1/D)⋅𝔼⁡[‖𝐳‖12/‖𝐳‖22]1-(1/D)\cdot\mathbb{E}[\|\mathbf{z}\|_{1}^{2}/\|\mathbf{z}\|_{2}^{2}] across varying μ\mu and pp. Overall, we observe the expected behavior of sparsity-entropy tradeoff (b) We evaluate the normalized Hilbert-Schmidt independence Criterion (nHSIC) for LpJEPA, Rectified LpJEPA, and other baselines. Rectified LpJEPA achieves smaller nHSIC values compared to VICReg or NVICReg that only penalizes second-order statistics. (c) The relative mean absolute deviations (MAD) away from the median of the ℓ1\ell_{1} and ℓ0\ell_{0} sparsity metrics are computed over different methods. Rectified LpJEPA exhibits the highest variations of sparsity for different downstream dataset. Additional visualizations can be found in Figure 12.

5.2 Necessity of Rectifications

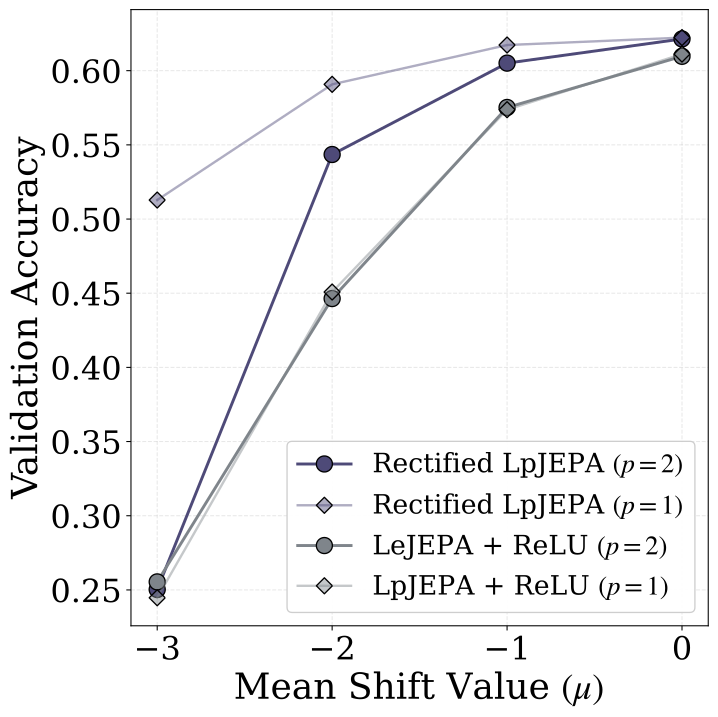
Rectifying both features and the target gives the best tested sparsity–accuracy tradeoff. Asking nonnegative features to follow an unrectified isotropic Gaussian creates an incompatible target and harms performance. Non-rectified variants can classify well while remaining dense.

5.3 Anti-Collapse via Continuous Mapping Theorems

A continuous-mapping argument explains how ReLU transforms a distribution. It does not imply that applying ReLU after dense pretraining preserves useful labels. The post-hoc probe ablation tests that difference and favors training directly for the rectified target.

5.4 Controllable Sparsity

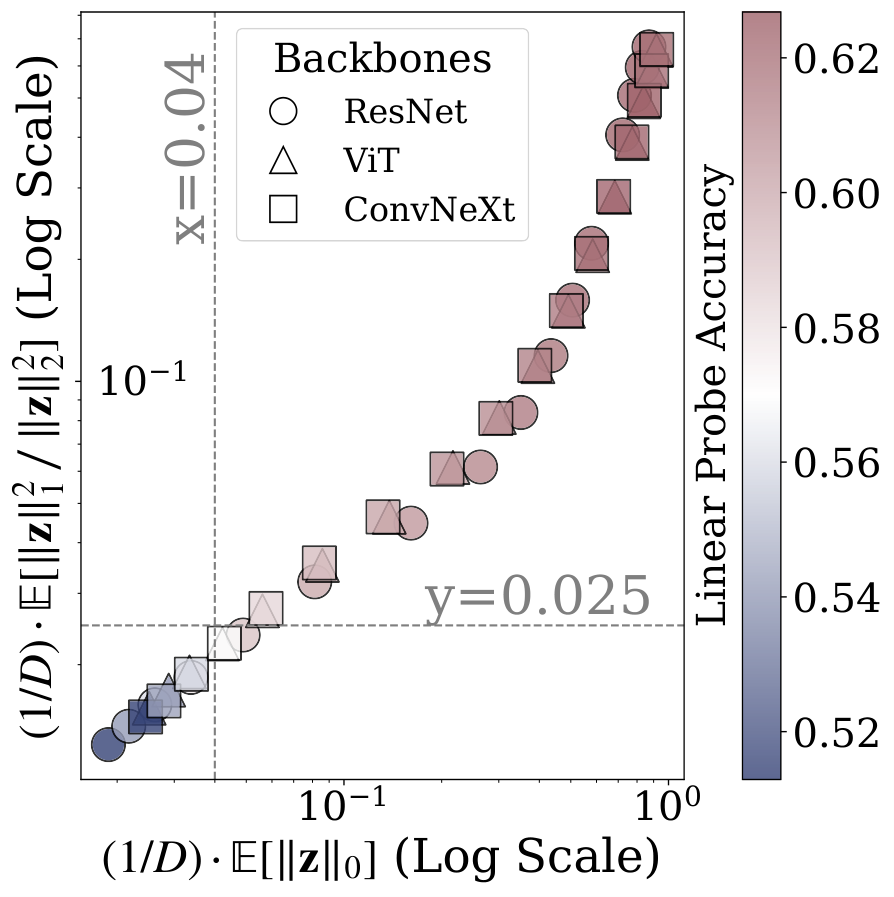
Observed nonzero fractions track the target-family prediction across tested means, shapes and architectures. This supports controllability of the statistic in these experiments, while label information still needs its own evaluation.

5.5 Sparsity and Performance Tradeoff

Accuracy declines gradually over part of the tested sparsity range, then drops sharply at very high sparsity, around95% zeros in the illustrated setting. That threshold belongs to this task and recipe; it is not a universal safe compression ratio.

5.6 Pair-wise Independence via HSIC

The paper uses pairwise Hilbert–Schmidt independence measurements as a tractable dependence diagnostic. Lower values indicate less measured pairwise dependence, beyond covariance alone. They do not by themselves prove that every coordinate is jointly independent or that a semantic factorization has been recovered.

5.7 Rényi Information Dimension and Entropy

The entropy analysis accounts for a mixture of zero and positive values. Summed marginal entropies upper-bound joint entropy, with dependencies determining the gap. Sparsity and entropy occupy a tradeoff curve; pairwise dependence diagnostics are evidence about that gap, not an exact high-dimensional joint-entropy estimate.

5.8 Pretraining and Transfer Evaluations

ImageNet pretraining and few/full-shot transfer compare task accuracy with sparsity across datasets. Out-of-distribution inputs can have different activation-sparsity patterns, suggesting a diagnostic. These examples do not establish a calibrated or universally reliable out-of-distribution detector.

6 Conclusion

The contribution is a target-distribution approach to learning sparse JEPA representations. Its practical value depends on retaining task performance while controlling zeros; a desired marginal distribution alone cannot determine which information a model should keep.

Acknowledgements

The authors acknowledge research funding, discussions and NYU computing support.

Impact Statement

The impact statement describes general representation-learning research and identifies no paper-specific societal consequence. It is not an application-level deployment evaluation.

Appendix

Appendix A Additional Backgrounds

The background compares contrastive, variance-based and distribution-matching objectives, plus post-hoc sparse autoencoders. This paper learns sparsity during pretraining instead of treating all sparsification procedures as equivalent.

Appendix B Properties of Univariate Generalized Gaussian, Truncated Generalized Gaussian, and Rectified Generalized Gaussian Distributions

B.1 Univariate Case - Generalized Gaussian

The appendix fixes the generalized Gaussian parameterization, moments and special cases. Its scale differs from some conventions, so formulas should not be copied without matching the parameterization.

Equations B.1–B.3
𝔼⁡[x]\displaystyle\mathbb{E}[x] =μ\displaystyle=\mu (B.1)
Var⁡[x]\displaystyle\operatorname{Var}[x] =σ2​p2/p​Γ⁡(3/p)Γ⁡(1/p)\displaystyle=\sigma^{2}p^{2/p}\frac{\Gamma(3/p)}{\Gamma(1/p)} (B.2)
Φ𝒢​𝒩p​(μ,σ)​(x)=12+sgn⁡(x−μ)​12​Γ​(1/p)​γ​(1p,|x−μ|pp​σp)\displaystyle\Phi_{\mathcal{GN}_{p}(\mu,\sigma)}(x)=\frac{1}{2}+\operatorname{sgn}(x-\mu)\frac{1}{2\Gamma(1/p)}\gamma\bigg(\frac{1}{p},\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg) (B.3)
Remark B.1.

The probability density function of the Generalized Gaussian distribution can also be written as

Equation B.4
f𝒢​𝒩p​(μ,σ)​(x)=p2​α​Γ​(1/p)​exp⁡(−|x−μ|pαp)\displaystyle f_{\mathcal{GN}_{p}(\mu,\sigma)}(x)=\frac{p}{2\alpha\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{\alpha^{p}}\bigg) (B.4)

where α:=p1/p​σ\alpha:=p^{1/p}\sigma. We choose the particular presentation in Definition 3.1 for its connection to the family of LpL_{p}-norm spherical distributions (Gupta and Song, 1997).

Remark B.2.

When p=1p=1, the Generalized Gaussian distribution reduces to the Laplace distribution ℒ⁡(μ,σ)\mathcal{L}(\mu,\sigma) with probability density function

Equation B.5
f𝒢​𝒩1​(μ,σ)​(x)=fℒ⁡(μ,σ)​(x)=12​σ​exp⁡(−|x−μ|σ)\displaystyle f_{\mathcal{GN}_{1}(\mu,\sigma)}(x)=f_{\mathcal{L}(\mu,\sigma)}(x)=\frac{1}{2\sigma}\exp\bigg(-\frac{|x-\mu|}{\sigma}\bigg) (B.5)

If p=2p=2, we recover the Gaussian distribution 𝒩⁡(μ,σ2)\mathcal{N}(\mu,\sigma^{2})

Equation B.6
f𝒢​𝒩2​(μ,σ)​(x)=f𝒩⁡(μ,σ2)​(x)=1σ​2​π​exp⁡(−|x−μ|22​σ2)\displaystyle f_{\mathcal{GN}_{2}(\mu,\sigma)}(x)=f_{\mathcal{N}(\mu,\sigma^{2})}(x)=\frac{1}{\sigma\sqrt{2\pi}}\exp\bigg(-\frac{|x-\mu|^{2}}{2\sigma^{2}}\bigg) (B.6)

B.2 Univariate Case - Truncated Generalized Gaussian

A truncated law is the conditional distribution restricted to positive values. The normalization depends on how much probability the original law assigned to that region.

Definition B.3 (Truncated Generalized Gaussian Probability Measure).

Let X∼ℙ𝒢​𝒩p​(μ,σ)X\sim\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)} be a Generalized Gaussian random variable with ℓp\ell_{p} parameter p>0p>0, location μ∈ℝ\mu\in\mathbb{R}, and scale σ>0\sigma>0. The Truncated Generalized Gaussian probability measure ℙ𝒯​𝒢​𝒩p​(μ,σ)\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)} on the measurable space (ℝ,ℬ⁡(ℝ))(\mathbb{R},\mathcal{B}(\mathbb{R})) is defined as the conditional distribution of XX given X>0X>0, i.e.,

Equation
ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)\displaystyle\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A) :=ℙ⁡(X∈A∣X>0)=ℙ𝒢​𝒩p​(μ,σ)​(A∩(0,∞))ℙ𝒢​𝒩p​(μ,σ)​((,,,))=ℙ𝒢​𝒩p​(μ,σ)​(A∩(0,∞))1−Φ𝒢​𝒩p​(0,1)(−μ/σ)\displaystyle:=\mathbb{P}\!\left(X\in A\mid X>0\right)=\frac{\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}(A\cap(0,\infty))}{\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}((0,\infty))}=\frac{\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}(A\cap(0,\infty))}{1-\Phi_{\mathcal{GN}_{p}(0,1)}(-\mu/\sigma)}

for any A∈ℬ⁡(ℝ)A\in\mathcal{B}(\mathbb{R}), where Φ𝒢​𝒩p​(0,1)\Phi_{\mathcal{GN}_{p}(0,1)} denotes the cumulative distribution function of the standardized Generalized Gaussian distribution.

B.3 Univariate Case - Rectified Generalized Gaussian

The rectified law combines a Dirac mass at zero and a continuous positive component. A mixed reference measure is needed to write its density precisely; ordinary Lebesgue-density language alone misses the atom at zero.

Original figure
(a) p=0.5p=0.5
Original figure
(b) p=1.0p=1.0
Original figure
(c) p=2.0p=2.0
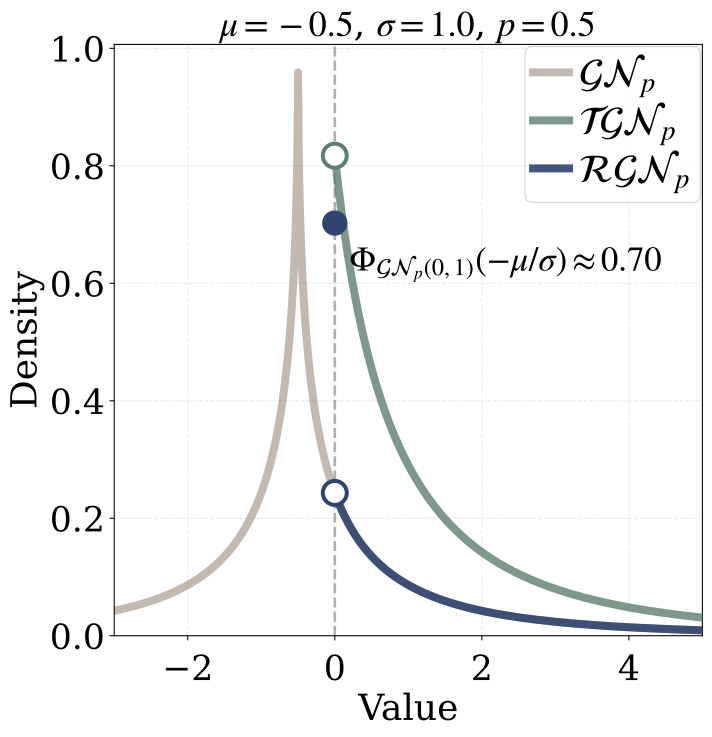
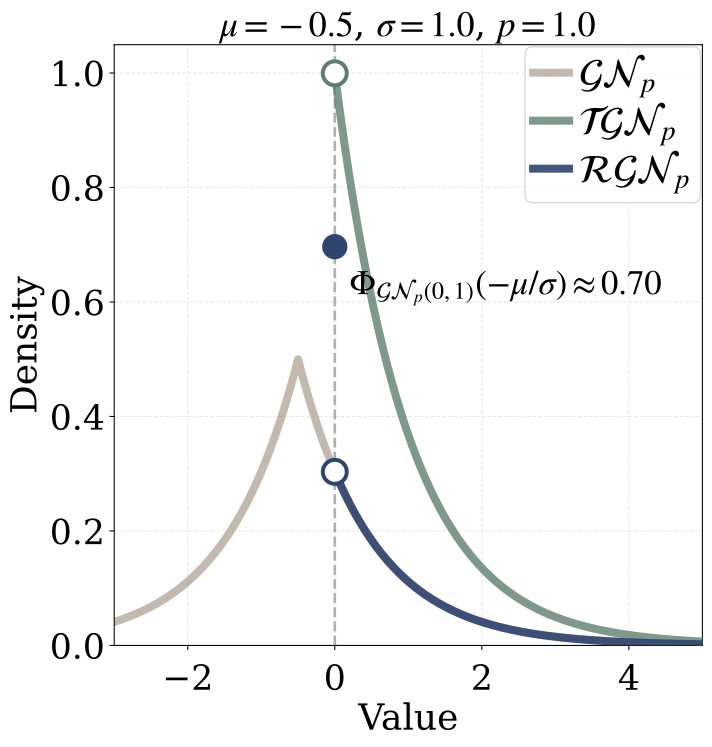
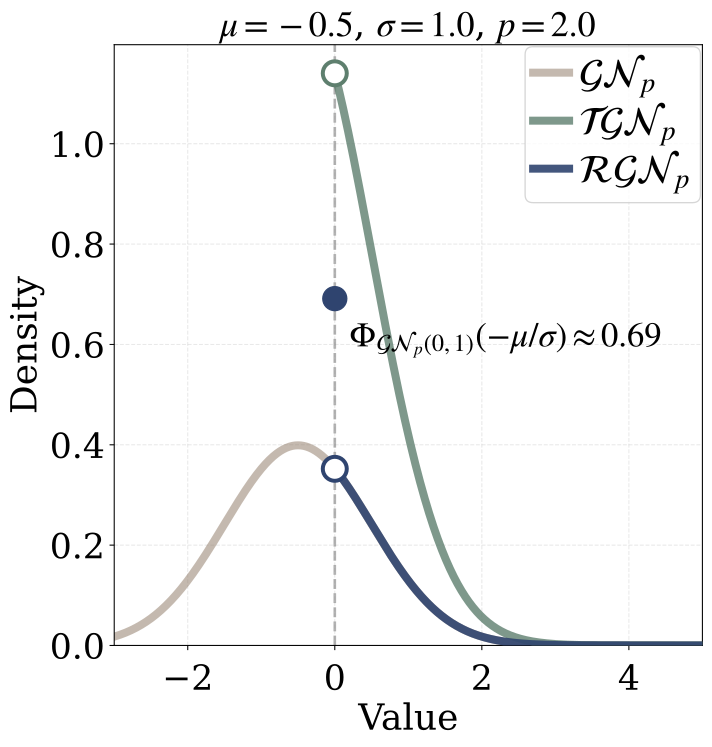
Figure 5: The Probability Density Function of Generalized Gaussian 𝒢​𝒩p\mathcal{GN}_{p}, Truncated Generalized Gaussian 𝒯​𝒢​𝒩p\mathcal{TGN}_{p}, and Rectified Generalized Gaussian ℛ​𝒢​𝒩p\mathcal{RGN}_{p} across varying pp with fixed μ=−0.5\mu=-0.5 and σ=1\sigma=1. Φ𝒢​𝒩p​(0,1)\Phi_{\mathcal{GN}_{p}(0,1)} is the CDF of the Generalized Gaussian 𝒢​𝒩p​(0,1)\mathcal{GN}_{p}(0,1). (a) The case when p=0.5p=0.5. (b) When p=1p=1, we obtain Laplace, Truncated Laplace, and Rectified Laplace. (c) For p=2p=2, we have Gaussian, Truncated Gaussian, and Rectified Gaussian.
Definition B.4 (Dirac Measure).

The Dirac measure δx\delta_{x} over a measurable space (X,Σ)(X,\Sigma) for a given x∈Xx\in X is defined as

Equation B.7
δx​(A)=𝟙A​(x)={0,x∉A1,x∈A\displaystyle\delta_{x}(A)=\mathbbm{1}_{A}(x)=\begin{cases}0,x\notin A\\ 1,x\in A\end{cases} (B.7)

for any measurable set A⊆XA\subseteq X.

Definition B.5 (Measure-Theoretical Definition of the Rectified Generalized Gaussian).

Fix parameters p>0p>0, μ∈ℝ\mu\in\mathbb{R}, and σ>0\sigma>0. We denote (ℝ,ℬ⁡(ℝ))(\mathbb{R},\mathcal{B}(\mathbb{R})) as the real line equipped with Borel σ\sigma-algebra. Let λ\lambda be the Lebesgue measure on ℬ⁡(ℝ)\mathcal{B}(\mathbb{R}) and let δ0\delta_{0} be the Dirac measure at 00 presented in Definition B.4. The probability measure ℙX\mathbb{P}_{X} of the Rectified Generalized Gaussian random variable XX is given by the mixture

Equation B.8
ℙX=Φ𝒢​𝒩p​(0,1)​(−μσ)⋅δ0+(1−Φ𝒢​𝒩p​(0,1)​(−μσ))⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)\displaystyle\mathbb{P}_{X}=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\delta_{0}+\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)} (B.8)

where ℙ𝒯​𝒢​𝒩p​(μ,σ)\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)} is the Truncated Generalized Gaussian probability measure in Definition B.3 and Φ𝒢​𝒩p​(0,1)\Phi_{\mathcal{GN}_{p}(0,1)} is the CDF of the standard Generalized Gaussian 𝒢​𝒩p​(0,1)\mathcal{GN}_{p}(0,1). Define the mixed measure ν:=λ+δ0\nu:=\lambda+\delta_{0}. By Lemma B.7, the Radon-Nikodym derivative of ℙX\mathbb{P}_{X} with respect to ν\nu exists and is given by

Equation B.9
d​ℙXd​ν​(x)=fℛ​𝒢​𝒩p​(μ,σ)​(x)\displaystyle\frac{d\mathbb{P}_{X}}{d\nu}(x)=f_{\mathcal{RGN}_{p}(\mu,\sigma)}(x) =Φ𝒢​𝒩p​(0,1)​(−μσ)⋅𝟙{0}​(x)+p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)⋅𝟙(0,∞)​(x)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbbm{1}_{\{0\}}(x)+\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x) (B.9)
Lemma B.6 (Absolute Continuity).

The Rectified Generalized Gaussian probability measure ℙX\mathbb{P}_{X} in Definition B.5 is absolutely continuous with respect to the mixed measure ν:=δ0+λ\nu:=\delta_{0}+\lambda, i.e. ℙX≪ν\mathbb{P}_{X}\ll\nu.

Proof.

According to Folland (1999), if ℙX\mathbb{P}_{X} is a signed measure and ν\nu is a positive measure on the same measurable space (ℝ,ℬ⁡(ℝ))(\mathbb{R},\mathcal{B}(\mathbb{R})), then ℙX≪ν\mathbb{P}_{X}\ll\nu if ν⁡(A)=0\nu(A)=0 for every A∈ℬ⁡(ℝ)A\in\mathcal{B}(\mathbb{R}) implies ℙX​(A)=0\mathbb{P}_{X}(A)=0.

Let’s consider the case of ν⁡(A)=0\nu(A)=0. By definition, ν⁡(A)=δ0​(A)+λ⁡(A)=0\nu(A)=\delta_{0}(A)+\lambda(A)=0. Since both δ0\delta_{0} and λ\lambda are non-negative measures, δ0​(A)=λ⁡(A)=0\delta_{0}(A)=\lambda(A)=0. We observe that δ0​(A)=0\delta_{0}(A)=0 implies 0∉A0\notin A by the definition of the Dirac measure. Thus

Equations B.10–B.11
ℙX​(A)\displaystyle\mathbb{P}_{X}(A) =Φ𝒢​𝒩p​(0,1)​(−μσ)⋅δ0​(A)+(1−Φ𝒢​𝒩p​(0,1)​(−μσ))⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\delta_{0}(A)+\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A) (B.10)
=(1−Φ𝒢​𝒩p​(0,1)​(−μσ))⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)\displaystyle=\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A) (B.11)

where the first term vanishes because 0∉A0\notin A. It’s trivial that ℙ𝒯​𝒢​𝒩p​(μ,σ)\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)} is absolutely continuous with respect to the Lebesgue measure. Since ν⁡(A)=0⟹λ⁡(A)=0\nu(A)=0\implies\lambda(A)=0, we have λ⁡(A)=0⟹ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)=0\lambda(A)=0\implies\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A)=0. Thus

Equation B.12
ℙX​(A)\displaystyle\mathbb{P}_{X}(A) =(1−Φ𝒢​𝒩p​(0,1)​(−μσ))⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)=0\displaystyle=\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A)=0 (B.12)

and we have proven the absolutely continuity result ℙX≪ν\mathbb{P}_{X}\ll\nu. ∎

Lemma B.7 (Radon–Nikodym Derivative).

The Radon–Nikodym derivative of the Rectified Generalized Gaussian probability measure ℙX\mathbb{P}_{X} with respect to the mixed measure ν:=δ0+λ\nu:=\delta_{0}+\lambda exists and is given by

Equation B.13
d​ℙXd​ν​(x)=fℛ​𝒢​𝒩p​(μ,σ)​(x)\displaystyle\frac{d\mathbb{P}_{X}}{d\nu}(x)=f_{\mathcal{RGN}_{p}(\mu,\sigma)}(x) =Φ𝒢​𝒩p​(0,1)​(−μσ)⋅𝟙{0}​(x)+p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)⋅𝟙(0,∞)​(x)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbbm{1}_{\{0\}}(x)+\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x) (B.13)
Proof.

By Lemma B.6, ℙX≪ν\mathbb{P}_{X}\ll\nu so the Radon–Nikodym derivative d​ℙX/d​νd\mathbb{P}_{X}/d\nu exists and it suffices to show that for any A⊆ℬ⁡(ℝ)A\subseteq\mathcal{B}(\mathbb{R}) we have

Equation B.14
ℙX​(A)=∫Ad​ℙXd​ν​𝑑ν\displaystyle\mathbb{P}_{X}(A)=\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\nu (B.14)

We start by expanding the integral with respect to a sum of measures

Equation B.15
∫Ad​ℙXd​ν​𝑑ν=∫Ad​ℙXd​ν​d​δ0+∫Ad​ℙXd​ν​𝑑λ\displaystyle\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\nu=\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\delta_{0}+\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\lambda (B.15)

By the property of the Dirac measure, we have

Equation B.16
∫Ad​ℙXd​ν​d​δ0=d​ℙXd​ν​(0)​δ0​(A)=fℛ​𝒢​𝒩p​(μ,σ)​(0)​δ0​(A)\displaystyle\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\delta_{0}=\frac{d\mathbb{P}_{X}}{d\nu}(0)\delta_{0}(A)=f_{\mathcal{RGN}_{p}(\mu,\sigma)}(0)\delta_{0}(A) (B.16)

We observe that 𝟙{0}​(x)=1\mathbbm{1}_{\{0\}}(x)=1 and 𝟙(0,∞)​(0)=0\mathbbm{1}_{(0,\infty)}(0)=0. So we have

Equation B.17
fℛ​𝒢​𝒩p​(μ,σ)​(0)​δ0​(A)=Φ𝒢​𝒩p​(0,1)​(−μσ)⋅δ0​(A)\displaystyle f_{\mathcal{RGN}_{p}(\mu,\sigma)}(0)\delta_{0}(A)=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\delta_{0}(A) (B.17)

Now the second term can be expanded as

Equations B.18–B.19
∫Ad​ℙXd​ν​𝑑λ\displaystyle\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\lambda =∫AΦ𝒢​𝒩p​(0,1)​(−μσ)⋅𝟙{0}​(x)​𝑑λ​(x)+∫Ap1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)⋅𝟙(0,∞)​(x)​𝑑λ​(x)\displaystyle=\int_{A}\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbbm{1}_{\{0\}}(x)d\lambda(x)+\int_{A}\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x)d\lambda(x) (B.18)
=Φ𝒢​𝒩p​(0,1)​(−μσ)⋅∫A𝟙{0}​(x)​𝑑λ​(x)+∫Ap1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)⋅𝟙(0,∞)​(x)​𝑑λ​(x)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\int_{A}\mathbbm{1}_{\{0\}}(x)d\lambda(x)+\int_{A}\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x)d\lambda(x) (B.19)

where the term

Equation B.20
∫A𝟙{0}​(x)​𝑑λ​(x)=λ⁡(A∩{0})=0\displaystyle\int_{A}\mathbbm{1}_{\{0\}}(x)d\lambda(x)=\lambda(A\cap\{0\})=0 (B.20)

simply vanishes. Thus we are left with

Equations B.21–B.24
∫Ad​ℙXd​ν​𝑑λ\displaystyle\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\lambda =∫Ap1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)⋅𝟙(0,∞)​(x)​𝑑λ​(x)\displaystyle=\int_{A}\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x)d\lambda(x) (B.21)
=∫A∩(0,∞)p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)​𝑑λ​(x)\displaystyle=\int_{A\cap(0,\infty)}\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)d\lambda(x) (B.22)
=∫A∩(0,∞)d​ℙ𝒢​𝒩p​(μ,σ)d​λ​(x)​𝑑λ​(x)\displaystyle=\int_{A\cap(0,\infty)}\frac{d\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}}{d\lambda}(x)d\lambda(x) (B.23)
=ℙ𝒢​𝒩p​(μ,σ)​(A∩(0,∞))\displaystyle=\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}(A\cap(0,\infty)) (B.24)

By Definition B.3, the Truncated Generalized Gaussian probability measure is given by

Equations B.25–B.26
ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)\displaystyle\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A) =ℙ𝒢​𝒩p​(μ,σ)​(A∩(0,∞))ℙ𝒢​𝒩p​(μ,σ)​((,,,))\displaystyle=\frac{\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}(A\cap(0,\infty))}{\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}((0,\infty))} (B.25)
=ℙ𝒢​𝒩p​(μ,σ)​(A∩(0,∞))1−Φ𝒢​𝒩p​(0,1)​(−μσ)\displaystyle=\frac{\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}(A\cap(0,\infty))}{1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)} (B.26)

Thus we have the identity

Equation B.28
ℙ𝒢​𝒩p​(μ,σ)​(A∩(0,∞))\displaystyle\mathbb{P}_{\mathcal{GN}_{p}(\mu,\sigma)}(A\cap(0,\infty)) =1−Φ𝒢​𝒩p​(0,1)​(−μσ)⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)\displaystyle=1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A) (B.28)

Putting everything together, we arrive at

Equations B.29–B.30
∫Ad​ℙXd​ν​𝑑ν\displaystyle\int_{A}\frac{d\mathbb{P}_{X}}{d\nu}d\nu =Φ𝒢​𝒩p​(0,1)​(−μσ)⋅δ0​(A)+(1−Φ𝒢​𝒩p​(0,1)​(−μσ))⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)​(A)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\delta_{0}(A)+\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(A) (B.29)
=ℙX​(A)\displaystyle=\mathbb{P}_{X}(A) (B.30)

Thus we have proven the form of the Radon–Nikodym Derivative. ∎

Equations B.31–B.33
ℙℛ​𝒢​𝒩p​(μ,σ)​(ℝ)\displaystyle\mathbb{P}_{\mathcal{RGN}_{p}(\mu,\sigma)}(\mathbb{R}) =Φ𝒢​𝒩p​(0,1)​(−μσ)⋅δ0​(ℝ)+(1−Φ𝒢​𝒩p​(0,1)​(−μσ))⋅ℙ𝒯​𝒢​𝒩p​(μ,σ)​(ℝ)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\delta_{0}(\mathbb{R})+\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\cdot\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}(\mathbb{R}) (B.31)
=Φ𝒢​𝒩p​(0,1)​(−μσ)+(1−Φ𝒢​𝒩p​(0,1)​(−μσ))=1\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)+\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)=1 (B.32)
fℛ​𝒢​𝒩p​(μ,σ)​(x)=Φ𝒢​𝒩p​(0,1)​(−μσ)⋅𝟙{0}​(x)+p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)⋅𝟙(0,∞)​(x)\displaystyle f_{\mathcal{RGN}_{p}(\mu,\sigma)}(x)=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbbm{1}_{\{0\}}(x)+\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x) (B.33)
Corollary B.8 (Equivalent Definition of Rectified Generalized Gaussian).

The probability density function of the Rectified Generalized Gaussian distribution ℛ​𝒢​𝒩p​(μ,σ)\mathcal{RGN}_{p}(\mu,\sigma) can also be written as

Equations B.34–B.35
fℛ​𝒢​𝒩p​(μ,σ)​(x)\displaystyle f_{\mathcal{RGN}_{p}(\mu,\sigma)}(x) =Φ𝒢​𝒩p​(0,1)​(−μσ)⋅𝟙{0}​(x)\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\cdot\mathbbm{1}_{\{0\}}(x) (B.34)
+(1−Φ𝒢​𝒩p​(0,1)(−μσ))1Z(0,∞)​(μ,σ,p)exp(−|x−μ|pp​σp)⋅𝟙(0,∞)(x)\displaystyle+\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\frac{1}{Z_{(0,\infty)}(\mu,\sigma,p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{(0,\infty)}(x) (B.35)

where Φ𝒢​𝒩p​(0,1)\Phi_{\mathcal{GN}_{p}(0,1)} is the cumulative distribution function for the standard Generalized Gaussian distribution 𝒢​𝒩p​(0,1)\mathcal{GN}_{p}(0,1).

Proof.

We can simplify the expression as

Equation B.36
1−Φ𝒢​𝒩p​(0,1)​(−μσ)=1−Φ𝒢​𝒩p​(μ,σ)​(0)=Φ𝒢​𝒩p​(μ,σ)​(0)=∫−∞0p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)​𝑑x\displaystyle 1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)=1-\Phi_{\mathcal{GN}_{p}(\mu,\sigma)}(0)=\Phi_{\mathcal{GN}_{p}(\mu,\sigma)}(0)=\int_{-\infty}^{0}\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)dx (B.36)

So we have

Equation B.37
(1−Φ𝒢​𝒩p​(0,1)​(−μσ))​1Z(0,∞)​(μ,σ,p)=∫−∞0p1−1/p2​σ​Γ​(1/p)​exp⁡(−|x−μ|pp​σp)​𝑑x∫0∞exp⁡(−|x−μ|pp​σp)​𝑑x=p1−1/p2​σ​Γ​(1/p)\displaystyle\bigg(1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)\bigg)\frac{1}{Z_{(0,\infty)}(\mu,\sigma,p)}=\frac{\int_{-\infty}^{0}\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)dx}{\int_{0}^{\infty}\exp\bigg(-\frac{|x-\mu|^{p}}{p\sigma^{p}}\bigg)dx}=\frac{p^{1-1/p}}{2\sigma\Gamma(1/p)} (B.37)

where the extra terms cancel out due to symmetry around 00. Thus we have recovered the forms in Definition 3.4. ∎

B.4 Expectation and Variance of the Rectified Generalized Gaussian Distribution

Closed-form first and second moments are derived with gamma-function integrals. They permit variance normalization after rectification, which is different from normalizing the underlying unrectified variable.

Proposition B.9.

Let X∼ℛ​𝒢​𝒩p​(μ,σ)X\sim\mathcal{RGN}_{p}(\mu,\sigma) and sgn⁡(μ)∈{−1,0,+1}\operatorname{sgn}(\mu)\in\{-1,0,+1\} be the sign function. Let γ⁡(s,t)\gamma(s,t) be the lower incomplete gamma function, Γ⁡(s,t)\Gamma(s,t) be the upper incomplete gamma function, Γ⁡(s)\Gamma(s) be the gamma function, and P⁡(s,t)=γ⁡(s,t)/Γ⁡(s)P(s,t)=\gamma(s,t)/\Gamma(s) be the lower regularized gamma function. Then

Equations B.38–B.41
𝔼⁡[X]\displaystyle\mathbb{E}[X] =12​[μ⁡(1+sgn⁡(μ)​P​(1p,|μ|pp​σp))+p1/p​σ​Γ⁡(2/p,|μ|p/(p​σp))Γ⁡(1/p)]\displaystyle=\frac{1}{2}\bigg[\mu\bigg(1+\operatorname{sgn}(\mu)P\bigg(\frac{1}{p},\frac{|\mu|^{p}}{p\sigma^{p}}\bigg)\bigg)+p^{1/p}\sigma\frac{\Gamma(2/p,|\mu|^{p}/(p\sigma^{p}))}{\Gamma(1/p)}\bigg] (B.38)
𝔼⁡[X2]\displaystyle\mathbb{E}[X^{2}] =12[μ2(1+sgn(μ)P(1p,|μ|pp​σp))+2μp1/pσΓ⁡(2/p,|μ|p/(p​σp))Γ⁡(1/p)\displaystyle=\frac{1}{2}\bigg[\mu^{2}\bigg(1+\operatorname{sgn}(\mu)\,P\bigg(\frac{1}{p},\frac{|\mu|^{p}}{p\sigma^{p}}\bigg)\bigg)+2\mu p^{1/p}\sigma\frac{\Gamma(2/p,|\mu|^{p}/(p\sigma^{p}))}{\Gamma(1/p)} (B.39)
+p2/pσ2Γ⁡(3/p)Γ⁡(1/p)(1+sgn(μ)P(3p,|μ|pp​σp))]\displaystyle+p^{2/p}\sigma^{2}\frac{\Gamma(3/p)}{\Gamma(1/p)}\bigg(1+\operatorname{sgn}(\mu)\,P\bigg(\frac{3}{p},\frac{|\mu|^{p}}{p\sigma^{p}}\bigg)\bigg)\bigg] (B.40)
Var⁡(X)\displaystyle\operatorname{Var}(X) =𝔼⁡[X2]−(𝔼⁡[X])2.\displaystyle=\mathbb{E}[X^{2}]-\big(\mathbb{E}[X]\big)^{2}. (B.41)
Equations B.42–B.65
fZ​(z)=p1−1p2​σ​Γ​(1/p)​exp⁡(−|z−μ|pp​σp).\displaystyle f_{Z}(z)=\frac{p^{1-\frac{1}{p}}}{2\sigma\Gamma(1/p)}\exp\!\Big(-\frac{|z-\mu|^{p}}{p\sigma^{p}}\Big). (B.42)
𝔼⁡[Xk]=𝔼⁡[Zk​𝟙(0,∞)​(Z)]=∫0∞zk​fZ​(z)​𝑑z.\displaystyle\mathbb{E}[X^{k}]=\mathbb{E}[Z^{k}\mathbbm{1}_{(0,\infty)}(Z)]=\int_{0}^{\infty}z^{k}f_{Z}(z)\,dz. (B.43)
𝔼⁡[Xk]=C​∫0∞zk​exp⁡(−a​|z−μ|p)​𝑑z.\displaystyle\mathbb{E}[X^{k}]=C\int_{0}^{\infty}z^{k}\exp\!\big(-a|z-\mu|^{p}\big)\,dz. (B.44)
𝔼⁡[Xk]=C​∫−μ∞(t+μ)k​exp⁡(−a​|t|p)​𝑑t.\displaystyle\mathbb{E}[X^{k}]=C\int_{-\mu}^{\infty}(t+\mu)^{k}\exp\!\big(-a|t|^{p}\big)\,dt. (B.45)
I0\displaystyle I_{0} :=∫−μ∞e−a​|t|p​𝑑t\displaystyle:=\int_{-\mu}^{\infty}e^{-a|t|^{p}}\,dt (B.46)
I1\displaystyle I_{1} :=∫−μ∞t​e−a​|t|p​𝑑t\displaystyle:=\int_{-\mu}^{\infty}t\,e^{-a|t|^{p}}\,dt (B.47)
I2\displaystyle I_{2} :=∫−μ∞t2​e−a​|t|p​𝑑t.\displaystyle:=\int_{-\mu}^{\infty}t^{2}\,e^{-a|t|^{p}}\,dt. (B.48)
𝔼⁡[X]\displaystyle\mathbb{E}[X] =C⁡(μ​I0+I1),\displaystyle=C(\mu I_{0}+I_{1}), (B.49)
𝔼⁡[X2]\displaystyle\mathbb{E}[X^{2}] =C⁡(μ2​I0+2​μ​I1+I2).\displaystyle=C(\mu^{2}I_{0}+2\mu I_{1}+I_{2}). (B.50)
I0\displaystyle I_{0} =1pa−1/pΓ(1p)(1+sgn(μ)P(1p,t0))\displaystyle=\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1+\operatorname{sgn}(\mu)\,P\!\Big(\frac{1}{p},t_{0}\Big)\Big) (B.51)
I1\displaystyle I_{1} =1pa−2/pΓ(2p,t0)\displaystyle=\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big) (B.52)
I2\displaystyle I_{2} =1pa−3/pΓ(3p)(1+sgn(μ)P(3p,t0)).\displaystyle=\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)\Big(1+\operatorname{sgn}(\mu)\,P\!\Big(\frac{3}{p},t_{0}\Big)\Big). (B.53)
𝔼⁡[X]\displaystyle\mathbb{E}[X] =C⁡(μ​I0+I1)\displaystyle=C(\mu I_{0}+I_{1}) (B.54)
=Cμ⋅1pa−1/pΓ(1p)(1+sgn(μ)P(1/p,t0))+C⋅1pa−2/pΓ(2p,t0)\displaystyle=C\mu\cdot\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1+\operatorname{sgn}(\mu)P(1/p,t_{0})\Big)+C\cdot\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big) (B.55)
=12​μ​(1+sgn⁡(μ)​P​(1p,t0))+12​p1/p​σ​Γ⁡(2/p,t0)Γ⁡(1/p)\displaystyle=\frac{1}{2}\mu\Big(1+\operatorname{sgn}(\mu)P\!\Big(\frac{1}{p},t_{0}\Big)\Big)+\frac{1}{2}p^{1/p}\sigma\,\frac{\Gamma(2/p,t_{0})}{\Gamma(1/p)} (B.56)
=12​[μ⁡(1+sgn⁡(μ)​P​(1p,|μ|pp​σp))+p1/p​σ​Γ⁡(2/p,|μ|p/(p​σp))Γ⁡(1/p)]\displaystyle=\frac{1}{2}\bigg[\mu\bigg(1+\operatorname{sgn}(\mu)P\bigg(\frac{1}{p},\frac{|\mu|^{p}}{p\sigma^{p}}\bigg)\bigg)+p^{1/p}\sigma\frac{\Gamma(2/p,|\mu|^{p}/(p\sigma^{p}))}{\Gamma(1/p)}\bigg] (B.57)
𝔼⁡[X2]\displaystyle\mathbb{E}[X^{2}] =C⁡(μ2​I0+2​μ​I1+I2)\displaystyle=C(\mu^{2}I_{0}+2\mu I_{1}+I_{2}) (B.58)
=C​μ2​I0+2​C​μ​I1+C​I2\displaystyle=C\mu^{2}I_{0}+2C\mu I_{1}+CI_{2} (B.59)
=Cμ2⋅1pa−1/pΓ(1p)(1+sgn(μ)P(1/p,t0))+2Cμ⋅1pa−2/pΓ(2p,t0)\displaystyle=C\mu^{2}\cdot\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1+\operatorname{sgn}(\mu)P(1/p,t_{0})\Big)+2C\mu\cdot\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big) (B.60)
+C⋅1pa−3/pΓ(3p)(1+sgn(μ)P(3/p,t0))\displaystyle+C\cdot\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)\Big(1+\operatorname{sgn}(\mu)P(3/p,t_{0})\Big) (B.61)
=12​μ2​(1+sgn⁡(μ)​P​(1p,t0))+12​(2​μ​p1/p​σ​Γ⁡(2/p,t0)Γ⁡(1/p))\displaystyle=\frac{1}{2}\mu^{2}\Big(1+\operatorname{sgn}(\mu)P\!\Big(\frac{1}{p},t_{0}\Big)\Big)+\frac{1}{2}\Big(2\mu\,p^{1/p}\sigma\,\frac{\Gamma(2/p,t_{0})}{\Gamma(1/p)}\Big) (B.62)
+12​p2/p​σ2​Γ⁡(3/p)Γ⁡(1/p)​(1+sgn⁡(μ)​P​(3p,t0))\displaystyle+\frac{1}{2}p^{2/p}\sigma^{2}\frac{\Gamma(3/p)}{\Gamma(1/p)}\Big(1+\operatorname{sgn}(\mu)P\!\Big(\frac{3}{p},t_{0}\Big)\Big) (B.63)
=12[μ2(1+sgn(μ)P(1p,|μ|pp​σp))+2μp1/pσΓ⁡(2/p,|μ|p/(p​σp))Γ⁡(1/p)\displaystyle=\frac{1}{2}\bigg[\mu^{2}\bigg(1+\operatorname{sgn}(\mu)\,P\bigg(\frac{1}{p},\frac{|\mu|^{p}}{p\sigma^{p}}\bigg)\bigg)+2\mu p^{1/p}\sigma\frac{\Gamma(2/p,|\mu|^{p}/(p\sigma^{p}))}{\Gamma(1/p)} (B.64)
+p2/pσ2Γ⁡(3/p)Γ⁡(1/p)(1+sgn(μ)P(3p,|μ|pp​σp))],\displaystyle+p^{2/p}\sigma^{2}\frac{\Gamma(3/p)}{\Gamma(1/p)}\bigg(1+\operatorname{sgn}(\mu)\,P\bigg(\frac{3}{p},\frac{|\mu|^{p}}{p\sigma^{p}}\bigg)\bigg)\bigg], (B.65)
Definition B.10 (Gamma Functions).

If u≥0u\geq 0 and b>−1b>-1, then

Equations B.67–B.68
∫0utb​e−a​tp​𝑑t\displaystyle\int_{0}^{u}t^{b}e^{-at^{p}}\,dt =1pa−(b+1)/pγ(b+1p,aup),\displaystyle=\frac{1}{p}\,a^{-(b+1)/p}\,\gamma\!\Big(\frac{b+1}{p},\,au^{p}\Big), (B.67)
∫u∞tb​e−a​tp​𝑑t\displaystyle\int_{u}^{\infty}t^{b}e^{-at^{p}}\,dt =1pa−(b+1)/pΓ(b+1p,aup),\displaystyle=\frac{1}{p}\,a^{-(b+1)/p}\,\Gamma\!\Big(\frac{b+1}{p},\,au^{p}\Big), (B.68)

where γ⁡(⋅,⋅)\gamma(\cdot,\cdot) and Γ⁡(⋅,⋅)\Gamma(\cdot,\cdot) are the lower and upper incomplete gamma functions. By definition, we also have

Equation B.69
P⁡(s,t):=γ⁡(s,t)Γ⁡(s),Γ⁡(s,t)=Γ⁡(s)−γ⁡(s,t)=Γ⁡(s)​(1−P⁡(s,t)).\displaystyle P(s,t):=\frac{\gamma(s,t)}{\Gamma(s)},\hskip 18.49988pt\Gamma(s,t)=\Gamma(s)-\gamma(s,t)=\Gamma(s)\big(1-P(s,t)\big). (B.69)
Lemma B.11 (I0I_{0} Integral).

The I0I_{0} integral in Proposition B.9 is given by

Equation B.70
I0=1pa−1/pΓ(1p)(1+sgn(μ)P(1p,t0)).\displaystyle I_{0}=\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1+\operatorname{sgn}(\mu)\,P\!\Big(\frac{1}{p},t_{0}\Big)\Big). (B.70)
Equations B.71–B.74
I0=∫−μ0e−a​|t|p​𝑑t+∫0∞e−a​tp​𝑑t=∫0μe−a​sp​𝑑s+∫0∞e−a​tp​𝑑t.\displaystyle I_{0}=\int_{-\mu}^{0}e^{-a|t|^{p}}\,dt+\int_{0}^{\infty}e^{-at^{p}}\,dt=\int_{0}^{\mu}e^{-as^{p}}\,ds+\int_{0}^{\infty}e^{-at^{p}}\,dt. (B.71)
I0=1pa−1/pγ(1p,t0)+1pa−1/pΓ(1p)=1pa−1/pΓ(1p)(1+P(1p,t0)).\displaystyle I_{0}=\frac{1}{p}a^{-1/p}\gamma\!\Big(\frac{1}{p},t_{0}\Big)+\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)=\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1+P\!\Big(\frac{1}{p},t_{0}\Big)\Big). (B.72)
I0=∫|μ|∞e−a​tpdt=1pa−1/pΓ(1p,t0)=1pa−1/pΓ(1p)(1−P(1p,t0)).\displaystyle I_{0}=\int_{|\mu|}^{\infty}e^{-at^{p}}\,dt=\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p},t_{0}\Big)=\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1-P\!\Big(\frac{1}{p},t_{0}\Big)\Big). (B.73)
I0=1pa−1/pΓ(1p)(1+sgn(μ)P(1p,t0)).\displaystyle I_{0}=\frac{1}{p}a^{-1/p}\Gamma\!\Big(\frac{1}{p}\Big)\Big(1+\operatorname{sgn}(\mu)\,P\!\Big(\frac{1}{p},t_{0}\Big)\Big). (B.74)
Lemma B.12 (I1I_{1} Integral).

The I1I_{1} integral in Proposition B.9 is given by

Equation B.75
I1=1pa−2/pΓ(2p,t0).\displaystyle I_{1}=\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big). (B.75)
Equations B.76–B.81
I1=∫−μ0t​e−a​|t|p​𝑑t+∫0∞t​e−a​tp​𝑑t.\displaystyle I_{1}=\int_{-\mu}^{0}te^{-a|t|^{p}}\,dt+\int_{0}^{\infty}te^{-at^{p}}\,dt. (B.76)
∫−μ0te−a​|t|pdt=−∫0μse−a​spds.\displaystyle\int_{-\mu}^{0}te^{-a|t|^{p}}\,dt=-\int_{0}^{\mu}se^{-as^{p}}\,ds. (B.77)
I1=−∫0μse−a​spds+∫0∞te−a​tpdt=∫μ∞te−a​tpdt.\displaystyle I_{1}=-\int_{0}^{\mu}se^{-as^{p}}\,ds+\int_{0}^{\infty}te^{-at^{p}}\,dt=\int_{\mu}^{\infty}te^{-at^{p}}\,dt. (B.78)
I1=1pa−2/pΓ(2p,t0).\displaystyle I_{1}=\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big). (B.79)
I1=∫|μ|∞te−a​tpdt=1pa−2/pΓ(2p,t0).\displaystyle I_{1}=\int_{|\mu|}^{\infty}te^{-at^{p}}\,dt=\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big). (B.80)
I1=1pa−2/pΓ(2p,t0).\displaystyle I_{1}=\frac{1}{p}a^{-2/p}\Gamma\!\Big(\frac{2}{p},t_{0}\Big). (B.81)
Lemma B.13 (I2I_{2} Integral).

The I2I_{2} integral in Proposition B.9 is given by

Equation B.82
I2=1pa−3/pΓ(3p)(1+sgn(μ)P(3p,t0)).\displaystyle I_{2}=\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)\Big(1+\operatorname{sgn}(\mu)\,P\!\Big(\frac{3}{p},t_{0}\Big)\Big). (B.82)
Equations B.83–B.86
I2=∫−μ0t2​e−a​|t|p​𝑑t+∫0∞t2​e−a​tp​𝑑t=∫0μs2​e−a​sp​𝑑s+∫0∞t2​e−a​tp​𝑑t.\displaystyle I_{2}=\int_{-\mu}^{0}t^{2}e^{-a|t|^{p}}\,dt+\int_{0}^{\infty}t^{2}e^{-at^{p}}\,dt=\int_{0}^{\mu}s^{2}e^{-as^{p}}\,ds+\int_{0}^{\infty}t^{2}e^{-at^{p}}\,dt. (B.83)
I2=1pa−3/pγ(3p,t0)+1pa−3/pΓ(3p)=1pa−3/pΓ(3p)(1+P(3p,t0)).\displaystyle I_{2}=\frac{1}{p}a^{-3/p}\gamma\!\Big(\frac{3}{p},t_{0}\Big)+\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)=\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)\Big(1+P\!\Big(\frac{3}{p},t_{0}\Big)\Big). (B.84)
I2=∫|μ|∞t2e−a​tpdt=1pa−3/pΓ(3p,t0)=1pa−3/pΓ(3p)(1−P(3p,t0)).\displaystyle I_{2}=\int_{|\mu|}^{\infty}t^{2}e^{-at^{p}}\,dt=\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p},t_{0}\Big)=\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)\Big(1-P\!\Big(\frac{3}{p},t_{0}\Big)\Big). (B.85)
I2=1pa−3/pΓ(3p)(1+sgn(μ)P(3p,t0)).\displaystyle I_{2}=\frac{1}{p}a^{-3/p}\Gamma\!\Big(\frac{3}{p}\Big)\Big(1+\operatorname{sgn}(\mu)\,P\!\Big(\frac{3}{p},t_{0}\Big)\Big). (B.86)

B.5 Simulation Techniques for Rectified Generalized Gaussian

The retained sampling algorithm draws from the underlying generalized Gaussian and rectifies the result. It preserves the intended probability of an exact zero.

Algorithm 1 Simulation of the Rectified Generalized Gaussian Random Variables ℛ​𝒢​𝒩p​(μ,σ)\mathcal{RGN}_{p}(\mu,\sigma)
 Input: ℓp\ell_{p} parameter p>0p>0, location μ∈ℝ\mu\in\mathbb{R}, scale σ>0\sigma>0
 Output: sample Y∼ℛ​𝒢​𝒩p​(μ,σ)Y\sim\mathcal{RGN}_{p}(\mu,\sigma)
 Sample S∼Unif​{−1,+1}S\sim\mathrm{Unif}\{-1,+1\}
 Sample G∼Gamma⁡(shape=1p,rate=1)G\sim\mathrm{Gamma}\!\left(\text{shape}=\frac{1}{p},\,\text{rate}=1\right)
 Set X←μ+σ​S⋅(p​G)1/pX\leftarrow\mu+\sigma\,S\cdot(pG)^{1/p}
 Set Y←max⁡(0,X)Y\leftarrow\max(0,X)
 return YY
Algorithm 2 Bisection Search for the Scale Parameter σ\sigma for Rectified Generalized Gaussian with Unit Variance
 Input: ℓp\ell_{p} parameter p>0p>0, location μ∈ℝ\mu\in\mathbb{R}, tolerance ε>0\varepsilon>0
 Output: scale σ⋆>0\sigma^{\star}>0 such that Var⁡(ℛ​𝒢​𝒩p​(μ,σ⋆))≈1\operatorname{Var}(\mathcal{RGN}_{p}(\mu,\sigma^{\star}))\approx 1 {Var⁡(ℛ​𝒢​𝒩p​(μ,σ⋆))\operatorname{Var}(\mathcal{RGN}_{p}(\mu,\sigma^{\star})) is defined in Proposition B.9.}
 Define V⁡(σ)≔Var⁡(ℛ​𝒢​𝒩p​(μ,σ))V(\sigma)\coloneqq\operatorname{Var}(\mathcal{RGN}_{p}(\mu,\sigma))
 Define f⁡(σ)≔V⁡(σ)−1f(\sigma)\coloneqq V(\sigma)-1
 Choose initial bounds σL>0\sigma_{L}>0 and σU>σL\sigma_{U}>\sigma_{L} such that f⁡(σL)​<0,f⁡(σU)>​0f(\sigma_{L})<0,f(\sigma_{U})>0
 repeat
  σM←(σL+σU)/2\sigma_{M}\leftarrow(\sigma_{L}+\sigma_{U})/2
  if f⁡(σM)>0f(\sigma_{M})>0 then
   σU←σM\sigma_{U}\leftarrow\sigma_{M}
  else
   σL←σM\sigma_{L}\leftarrow\sigma_{M}
  end if
 until |σU−σL|≤ε|\sigma_{U}-\sigma_{L}|\leq\varepsilon
 σ⋆←(σL+σU)/2\sigma^{\star}\leftarrow(\sigma_{L}+\sigma_{U})/2
 return σ⋆\sigma^{\star}

Appendix C Properties of Multivariate Generalized Gaussian, Truncated Generalized Gaussian, and Rectified Generalized Gaussian Distributions

C.1 Multivariate Case - Multivariate Generalized Gaussian

The multivariate target here is built from independent coordinate distributions. This product construction is an assumption of the target family, not a result automatically true of any trained feature matrix.

Equation C.87
f∏i=1d𝒢​𝒩p​(μ,σ)​(𝐱)=pd−d/p(2​σ)d​Γ​(1/p)d​exp⁡(−‖𝐱−𝝁‖ppp​σp)\displaystyle f_{\prod_{i=1}^{d}\mathcal{GN}_{p}(\mu,\sigma)}(\mathbf{x})=\frac{p^{d-d/p}}{(2\sigma)^{d}\Gamma(1/p)^{d}}\exp\bigg(-\frac{\|\mathbf{x}-\boldsymbol{\mu}\|_{p}^{p}}{p\sigma^{p}}\bigg) (C.87)

C.2 Multivariate Case - Multivariate Truncated Generalized Gaussian

Restricting the product law to the positive support produces the corresponding multivariate truncated target, with the appropriate normalization.

C.3 Multivariate Case - Multivariate Rectified Generalized Gaussian

Independent rectified coordinates produce mass on multiple lower-dimensional faces according to which coordinates are zero. This geometry explains the need for mixed discrete/continuous entropy tools.

C.4 Proof of Proposition 3.5 (Theoretical Expected ℓ 0 Sparsity)

The expected number of active coordinates follows by summing their nonzero probabilities. This gives a target statistic for the empirical sparsity comparisons.

Equations C.88–C.91
‖𝐱‖0=∑i=1d𝟙𝐱i>0=∑i=1d𝟙𝐳i>0\displaystyle\|\mathbf{x}\|_{0}=\sum_{i=1}^{d}\mathbbm{1}_{\mathbf{x}_{i}>0}=\sum_{i=1}^{d}\mathbbm{1}_{\mathbf{z}_{i}>0} (C.88)
𝔼⁡[‖𝐱‖0]=∑i=1d𝔼⁡[𝟙𝐳i>0]=∑i=1dℙ⁡(𝐳i>0)=∑i=1dΦ𝒢​𝒩p​(0,1)​(μσ)=d⋅Φ𝒢​𝒩p​(0,1)​(μσ)\displaystyle\mathbb{E}[\|\mathbf{x}\|_{0}]=\sum_{i=1}^{d}\mathbb{E}[\mathbbm{1}_{\mathbf{z}_{i}>0}]=\sum_{i=1}^{d}\mathbb{P}(\mathbf{z}_{i}>0)=\sum_{i=1}^{d}\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg)=d\cdot\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg) (C.89)
Φ𝒢​𝒩p​(0,1)​(μσ)=12​(1+sgn⁡(μσ)​P​(1p,|μ/σ|pp))\displaystyle\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg)=\frac{1}{2}\bigg(1+\operatorname{sgn}\bigg(\frac{\mu}{\sigma}\bigg)P\bigg(\frac{1}{p},\frac{|\mu/\sigma|^{p}}{p}\bigg)\bigg) (C.90)
𝔼⁡[‖𝐱‖0]=d2​(1+sgn⁡(μσ)​P​(1p,|μ/σ|pp))\displaystyle\mathbb{E}[\|\mathbf{x}\|_{0}]=\frac{d}{2}\bigg(1+\operatorname{sgn}\bigg(\frac{\mu}{\sigma}\bigg)P\bigg(\frac{1}{p},\frac{|\mu/\sigma|^{p}}{p}\bigg)\bigg) (C.91)
Refer to caption
(a) Empirical Variance of Generalized Gaussian.
Refer to caption
(b) Theoretical Variance of Generalized Gaussian.
Refer to caption
(c) Empirical Variance of Rectified Generalized Gaussian.
Refer to caption
(d) Theoretical Variance of Rectified Generalized Gaussian.
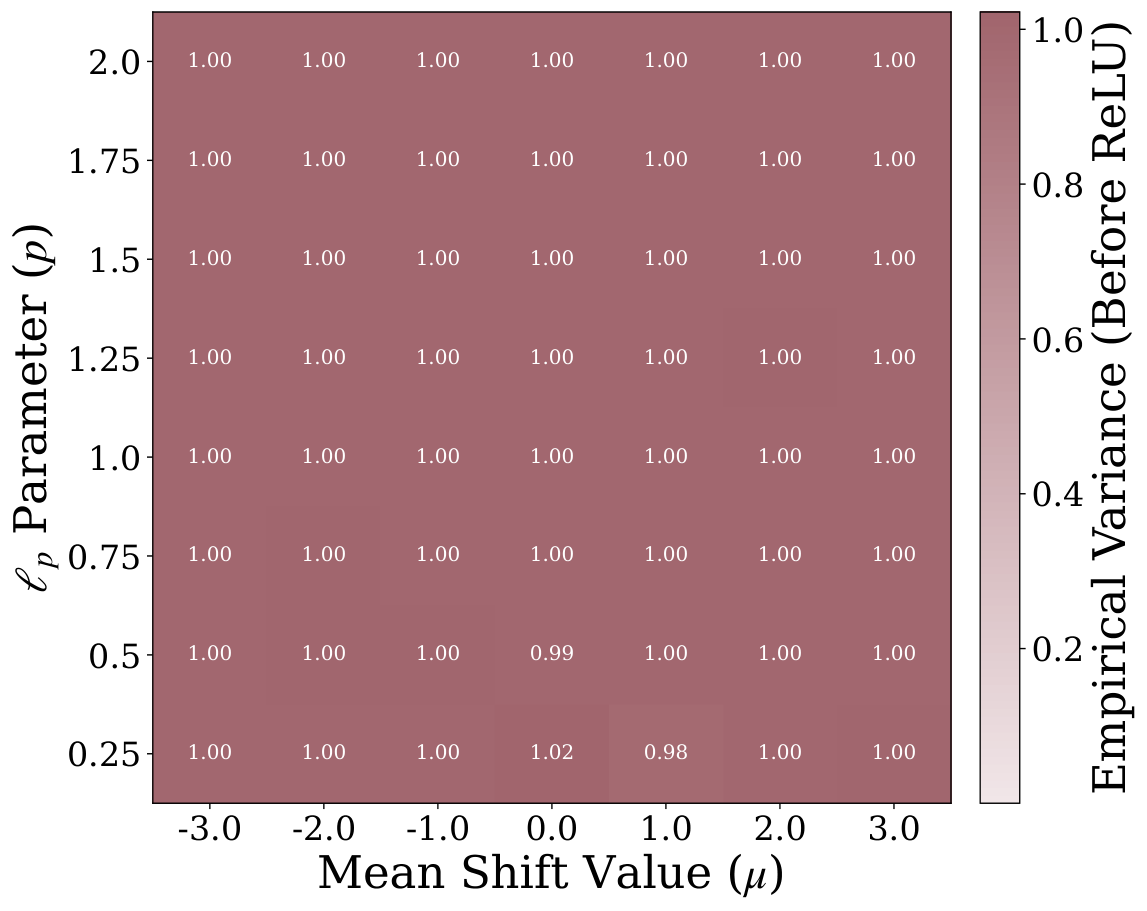
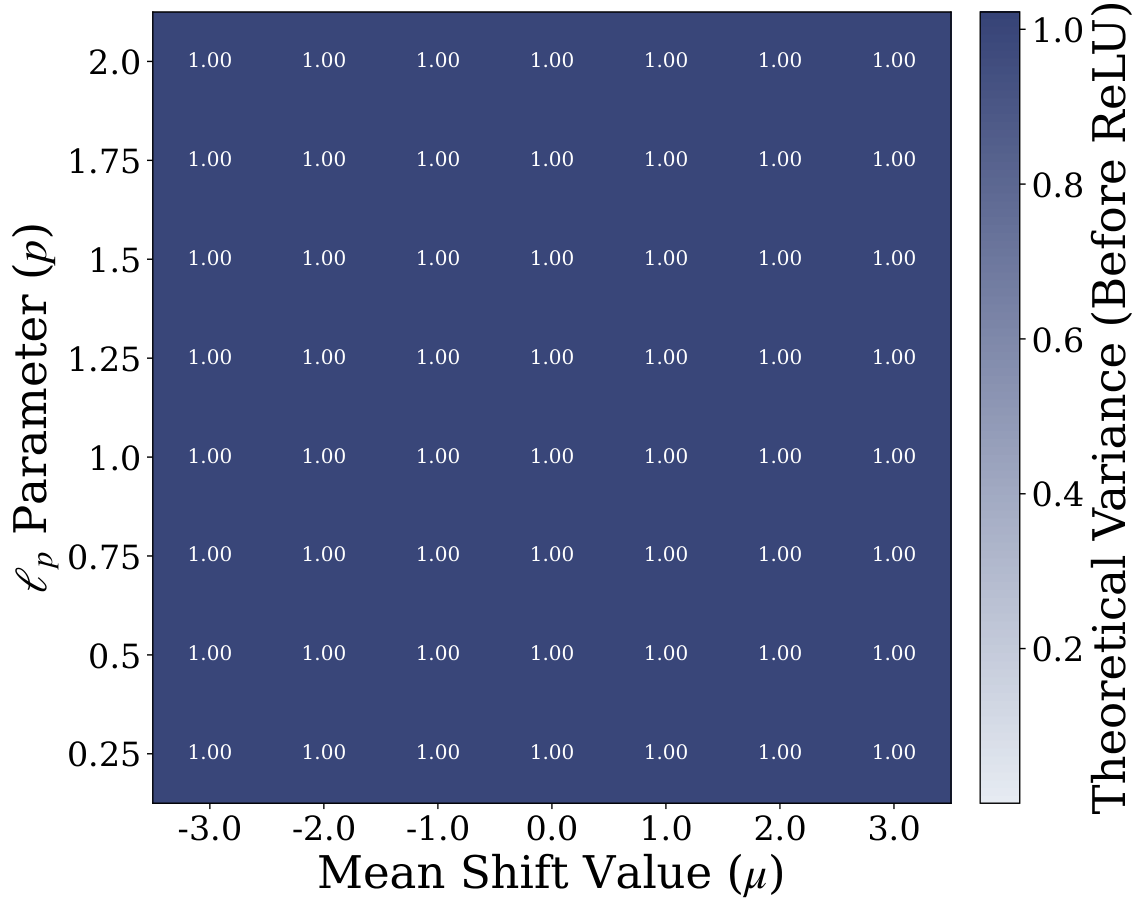
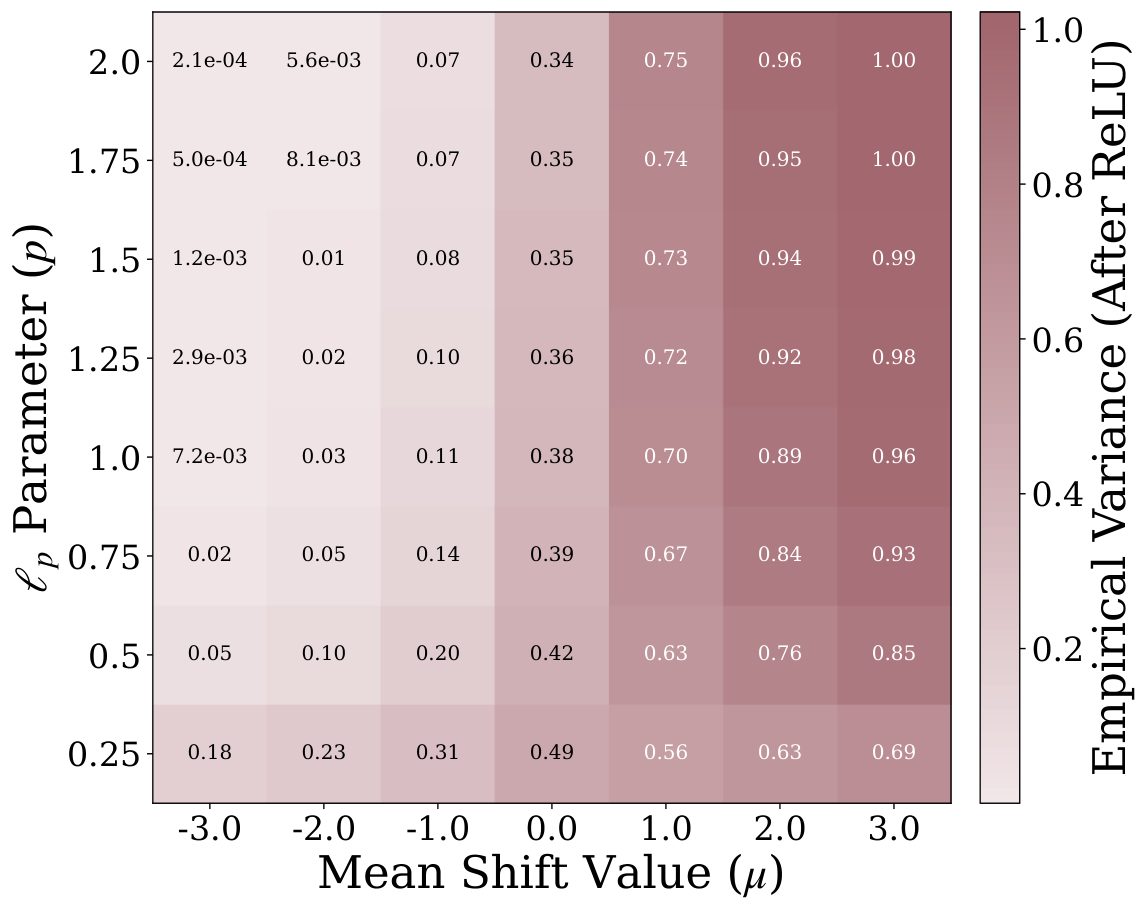
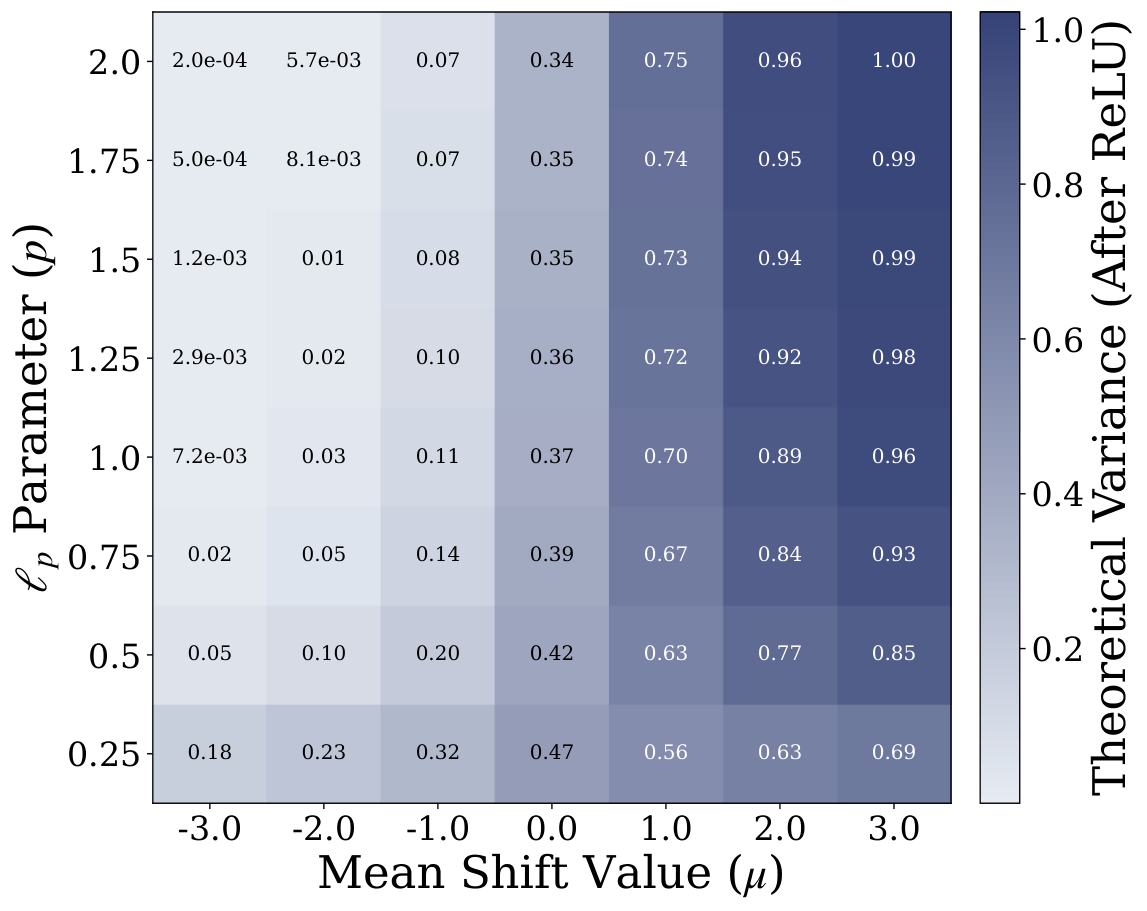
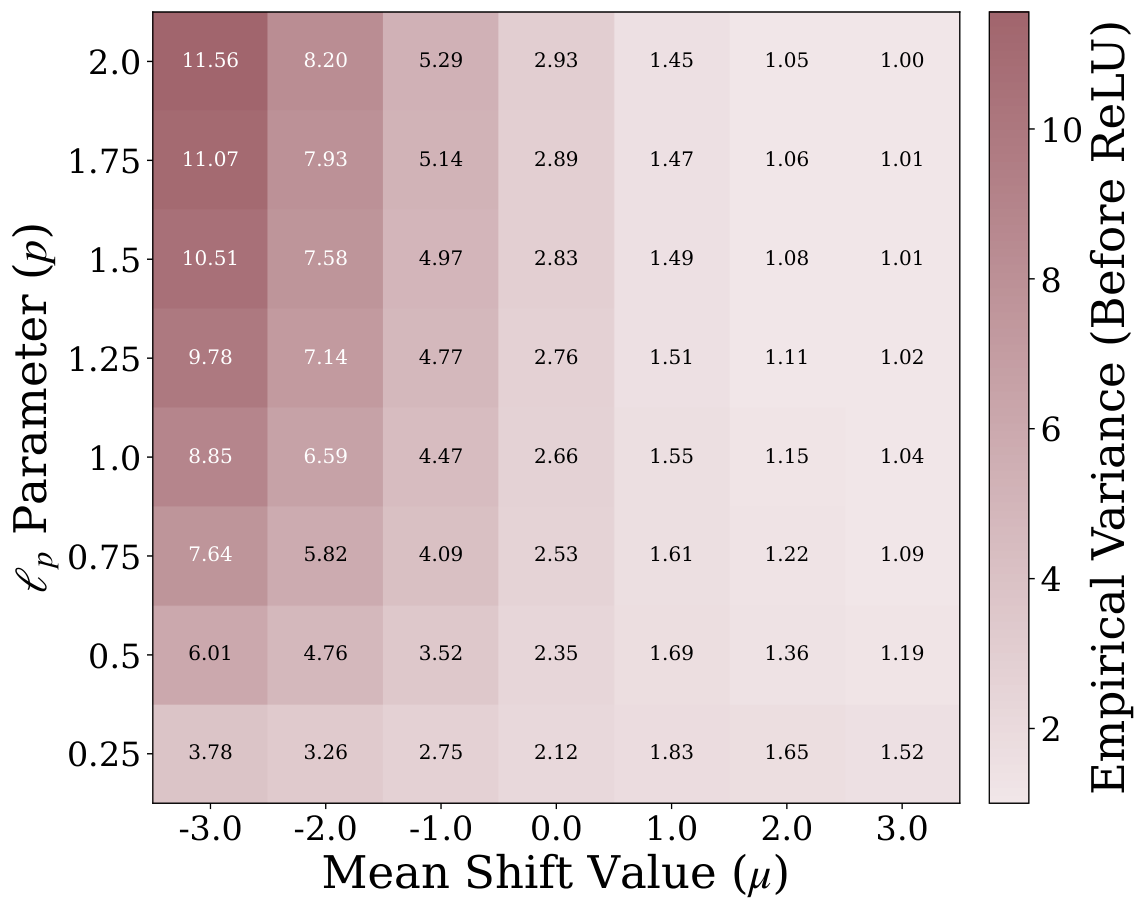
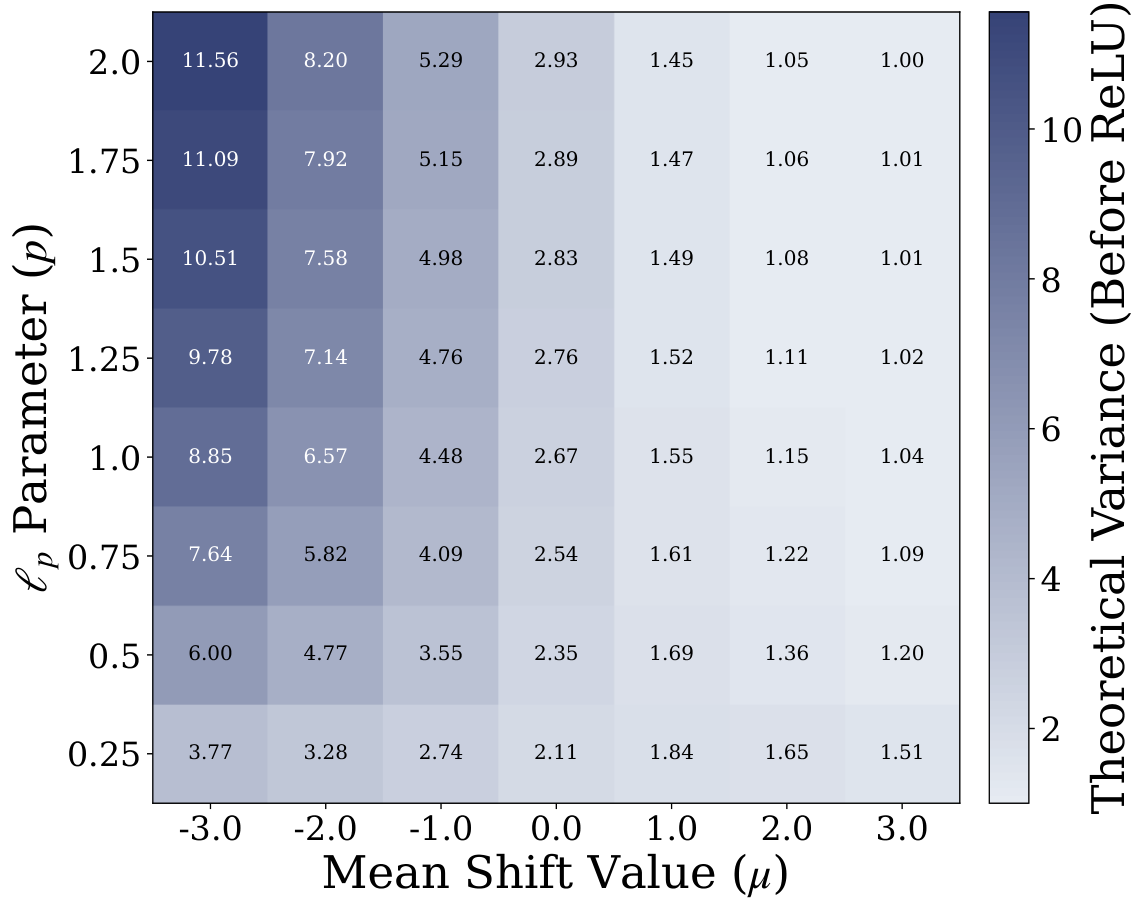
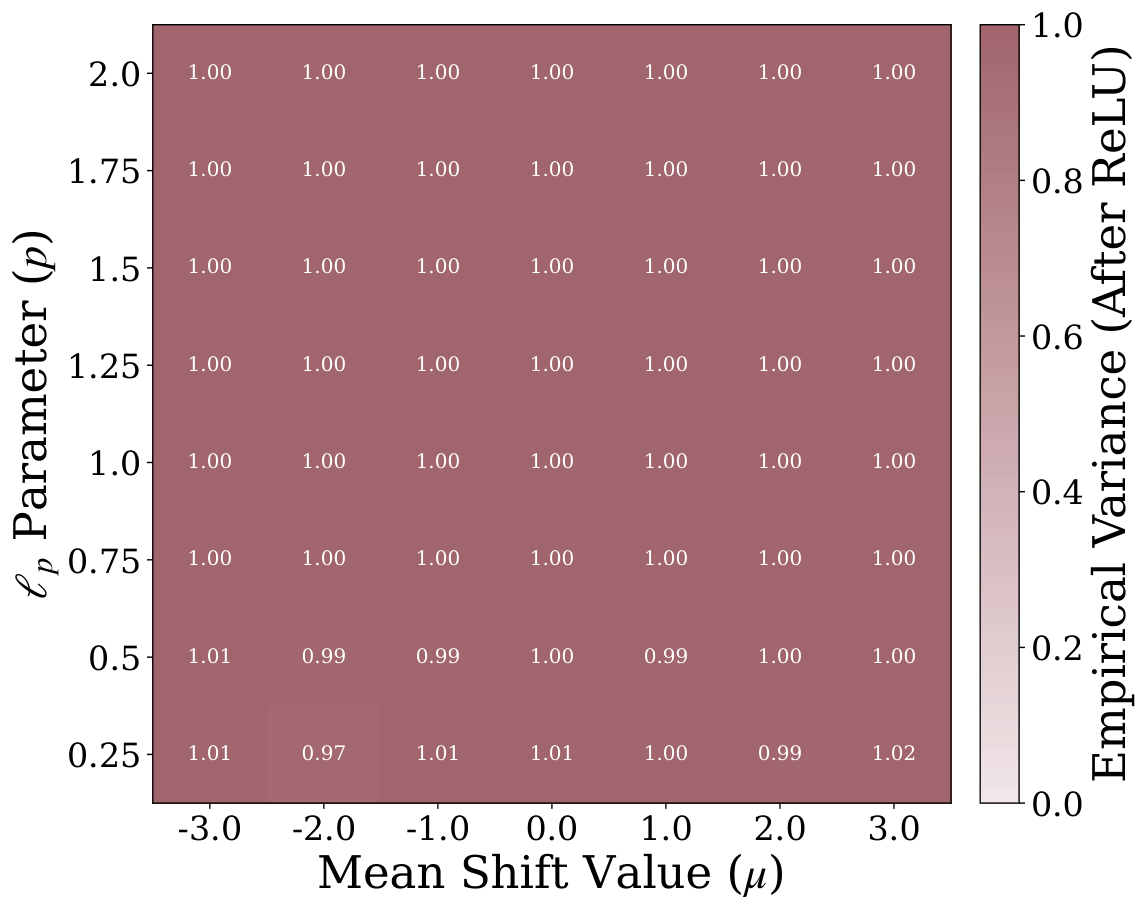
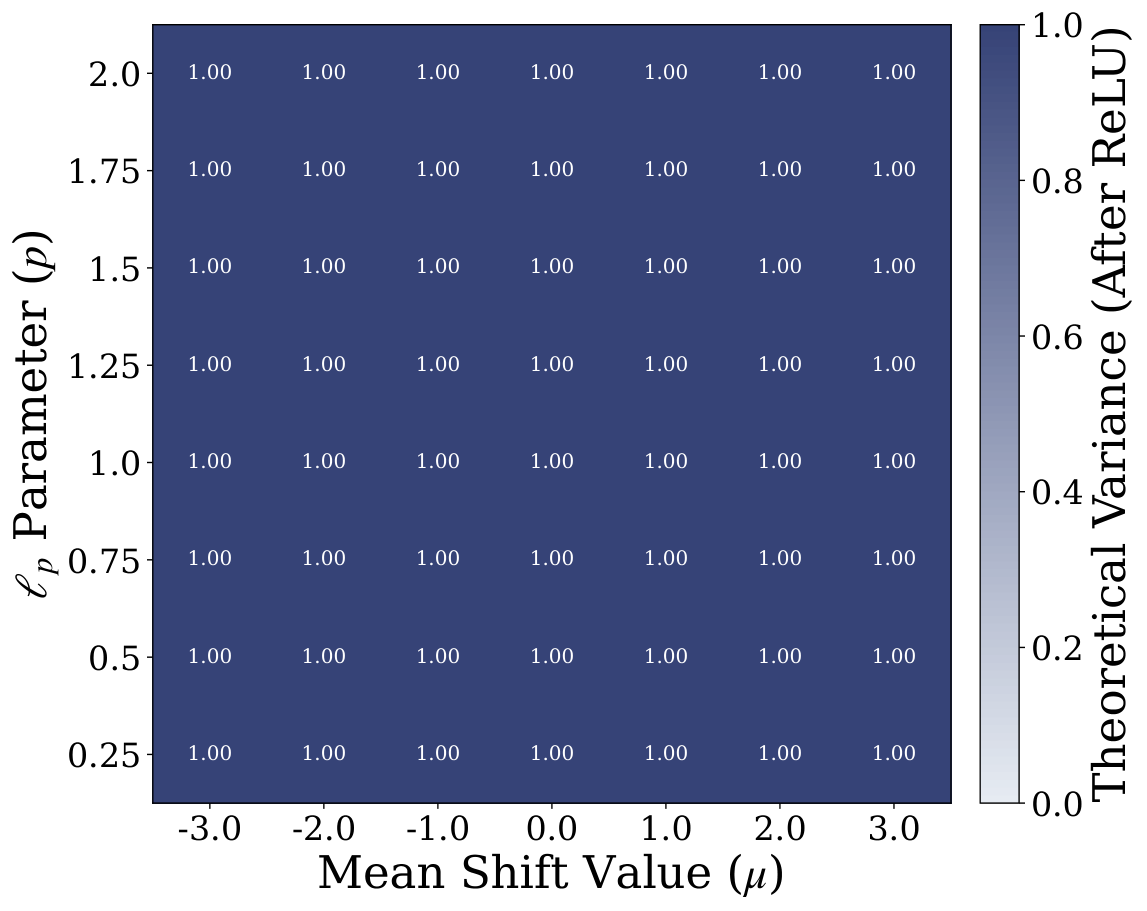
Figure 6: Variance of Generalized Gaussian Distribution and Rectified Generalized Gaussian distributions under the choice of σ=σGN\sigma=\sigma_{\operatorname{GN}}. Top row: Variance of x∼𝒢​𝒩p​(μ,σGN)x\sim\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{GN}}). (a) The empirical variance of 𝒢​𝒩p​(μ,σGN)\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{GN}}). (b) The theoretical variance of 𝒢​𝒩p​(μ,σGN)\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{GN}}) by evaluating Equation B.2. Bottom row: Variance of x∼ℛ​𝒢​𝒩p​(μ,σGN)x\sim\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{GN}}). (c) The empirical variance of ℛ​𝒢​𝒩p​(μ,σGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{GN}}). (d) The theoretical variance of ℛ​𝒢​𝒩p​(μ,σGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{GN}}) by evaluating Equation B.41. The empirical variance in (a) and (c) are computed by i.i.d sampling 100000100000 samples from 32 dimensions from either 𝒢​𝒩p​(μ,σGN)\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{GN}}) or ℛ​𝒢​𝒩p​(μ,σGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{GN}}). The per-dimension variance is estimated and we report the average variance across dimensions as a function of the mean shift value μ\mu and the parameter pp.
Refer to caption
(a) Empirical Variance of Generalized Gaussian.
Refer to caption
(b) Theoretical Variance of Generalized Gaussian.
Refer to caption
(c) Empirical Variance of Rectified Generalized Gaussian.
Refer to caption
(d) Theoretical Variance of Rectified Generalized Gaussian.
Figure 7: Variance of Generalized Gaussian Distribution and Rectified Generalized Gaussian distributions under the choice of σ=σRGN\sigma=\sigma_{\operatorname{RGN}}. Top row: Variance of x∼𝒢​𝒩p​(μ,σRGN)x\sim\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{RGN}}). (a) The empirical variance of 𝒢​𝒩p​(μ,σRGN)\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{RGN}}). (b) The theoretical variance of 𝒢​𝒩p​(μ,σRGN)\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{RGN}}) by evaluating Equation B.2. Bottom row: Variance of x∼ℛ​𝒢​𝒩p​(μ,σRGN)x\sim\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{RGN}}). (c) The empirical variance of ℛ​𝒢​𝒩p​(μ,σRGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{RGN}}). (d) The theoretical variance of ℛ​𝒢​𝒩p​(μ,σRGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{RGN}}) by evaluating Equation B.41. The empirical variance in (a) and (c) are computed by i.i.d sampling 100000100000 samples from 32 dimensions from either 𝒢​𝒩p​(μ,σRGN)\mathcal{GN}_{p}(\mu,\sigma_{\operatorname{RGN}}) or ℛ​𝒢​𝒩p​(μ,σRGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{RGN}}). The per-dimension variance is estimated and we report the average variance across dimensions as a function of the mean shift value μ\mu and the parameter pp.
Refer to caption
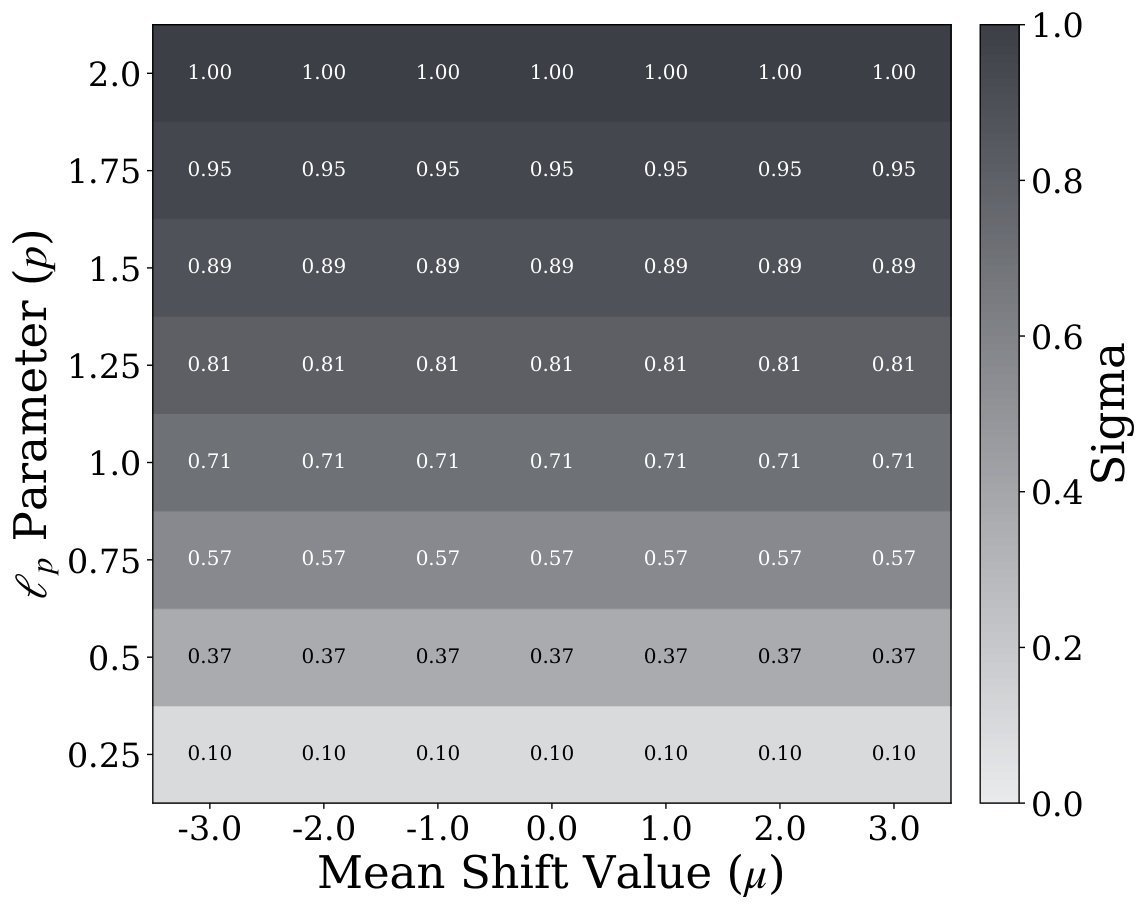
(a) Values of σGN\sigma_{\operatorname{GN}} across varying μ\mu and pp.
Refer to caption
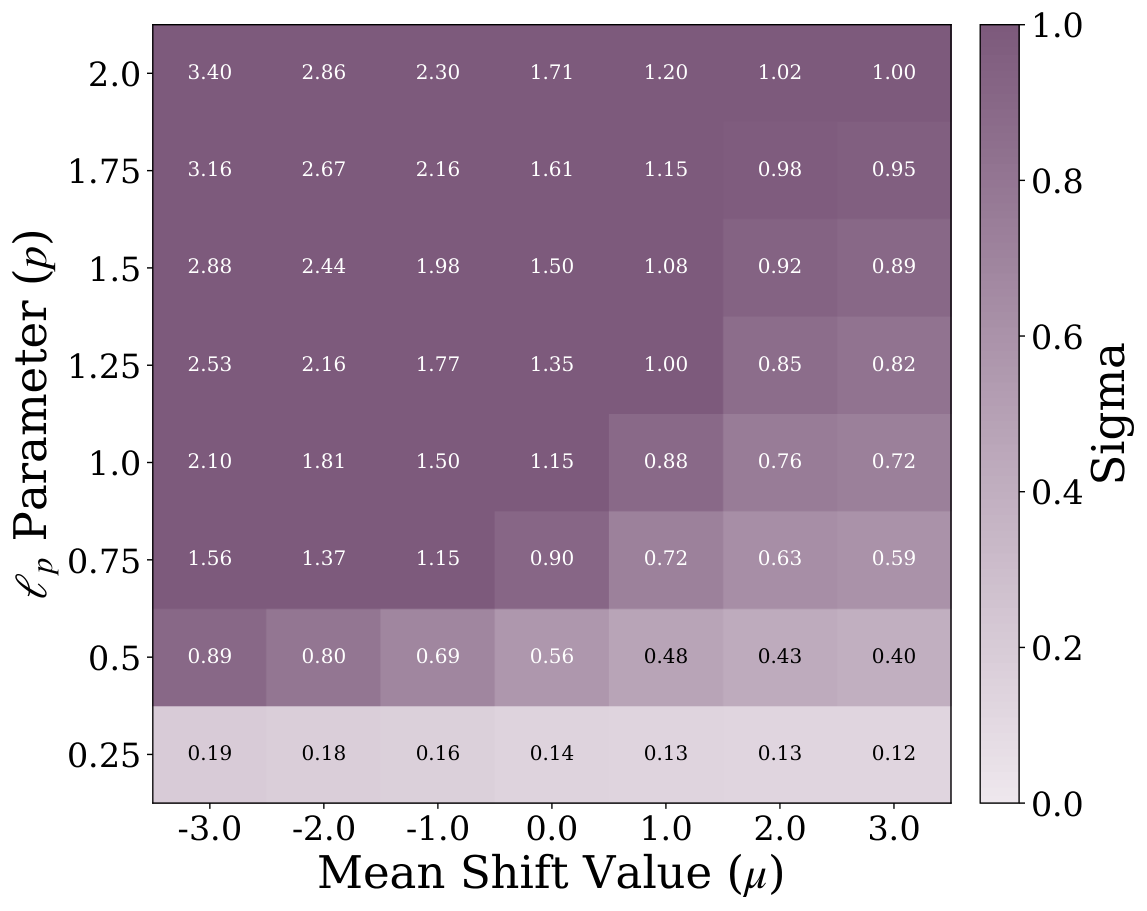
(b) Values of σRGN\sigma_{\operatorname{RGN}} across varying μ\mu and pp.
Figure 8: Values of σGN\sigma_{\operatorname{GN}} and σRGN\sigma_{\operatorname{RGN}} under Different Choices of μ\mu and pp. (a) The values of σGN\sigma_{\operatorname{GN}} are invariant to the mean shift value μ\mu. (b) σRGN\sigma_{\operatorname{RGN}} changes as a function of both μ\mu and pp.

Appendix D Choice of σ for Rectified Generalized Gaussian

D.1 How does σ affect the variance?

Changing scale changes how much variance remains after rectification. The appendix compares the chosen normalization rules using the derived moment formulas.

D.2 How does σ affect the sparsity?

Scale interacts with location in determining the zero probability. Keeping one parameter fixed while changing another need not preserve the same sparsity.

D.3 How does σ affect performance?

The normalization comparison measures downstream accuracy as well as the desired feature statistics. Its favored choice is an empirical recipe for the reported experiments.

Original figure
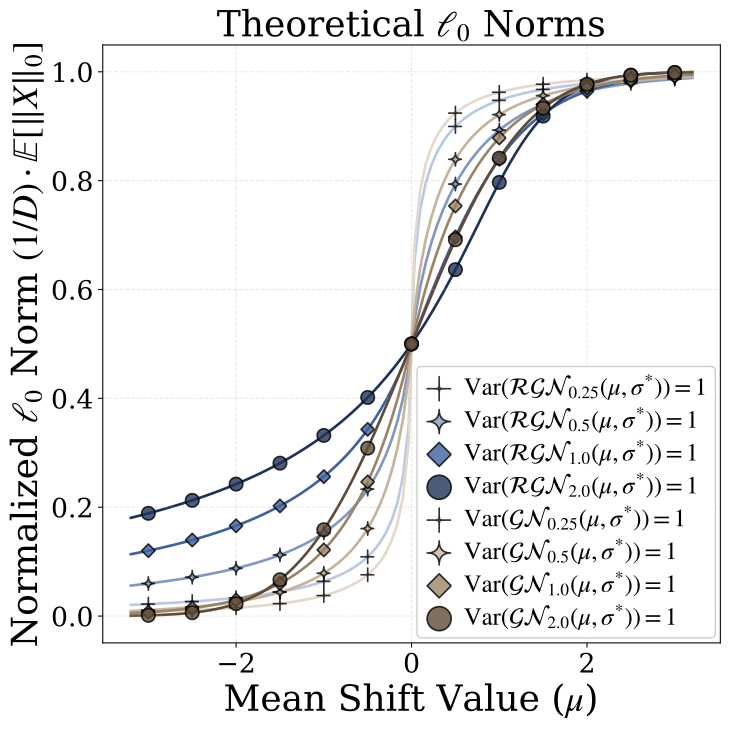
(a) Theoretical ℓ0\ell_{0} Norms Under Different Choices of σ∗\sigma^{*}
Original figure
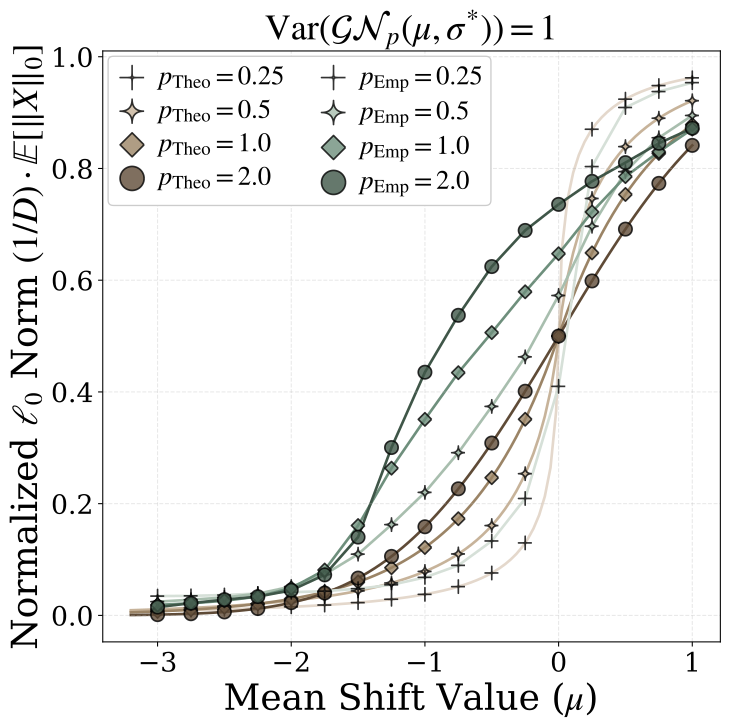
(b) Theoretical and Empirical of ℓ0\ell_{0} Norms under the Choice of σGN\sigma_{\operatorname{GN}}
Original figure
(c) Theoretical and Empirical of ℓ0\ell_{0} Norms under the Choice of σRGN\sigma_{\operatorname{RGN}}
Figure 9: The theoretical and empirical normalized ℓ0\ell_{0} norms under Different Choices of σ∗\sigma^{*}. (a) We report the theoretical ℓ0\ell_{0} norms based on Proposition 3.5 for σ∗∈{σGN,σRGN}\sigma^{*}\in\{\sigma_{\operatorname{GN}},\sigma_{\operatorname{RGN}}\} for varying μ\mu and pp. (b) The empirical ℓ0\ell_{0} norms of pretrained Rectified LpJEPA features are measured against the theoretical ℓ0\ell_{0} norms of the target Rectified Generalized Gaussian distribution ℛ​𝒢​𝒩p​(μ,σGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{GN}}) for varying μ\mu and pp. (c) We plot the empirical ℓ0\ell_{0} norms of pretrained Rectified LpJEPA features against the theoretical ℓ0\ell_{0} norms of the target Rectified Generalized Gaussian distribution ℛ​𝒢​𝒩p​(μ,σRGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{RGN}}) for varying μ\mu and pp.
Original figure
(a) Accuracy versus Mean Shift Value μ\mu
Original figure
(b) Accuracy versus ℓ1\ell_{1} Sparsity Metric
Original figure
(c) Accuracy versus ℓ0\ell_{0} Sparsity Metric
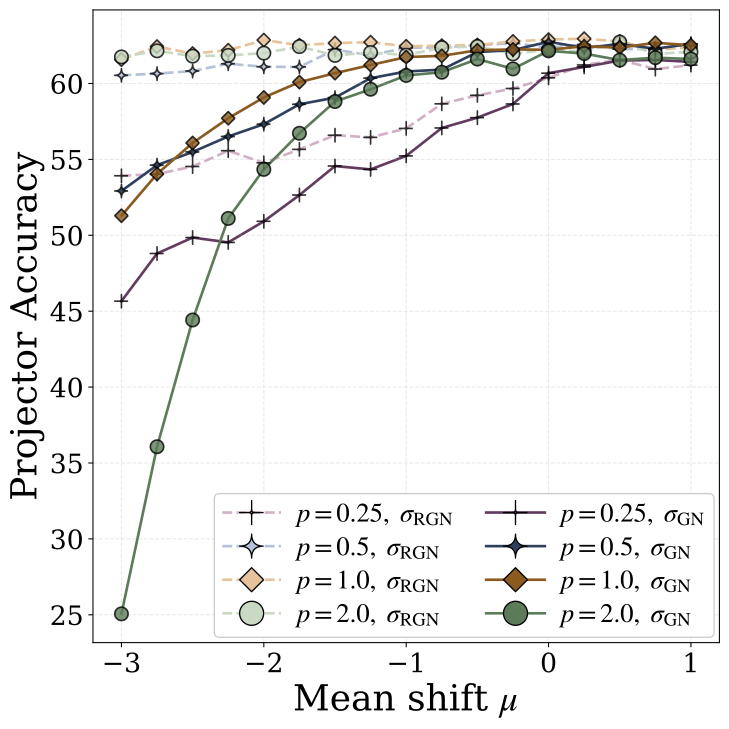
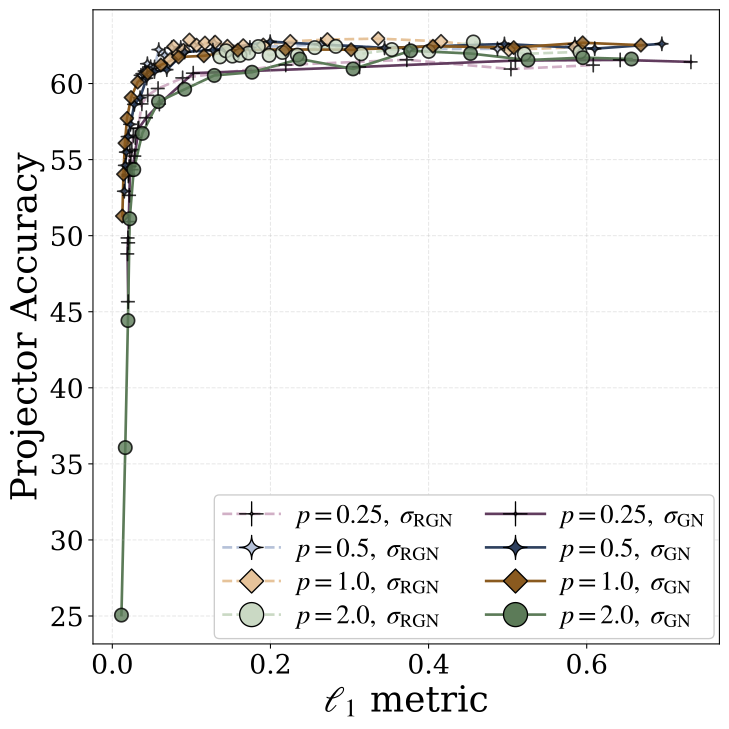
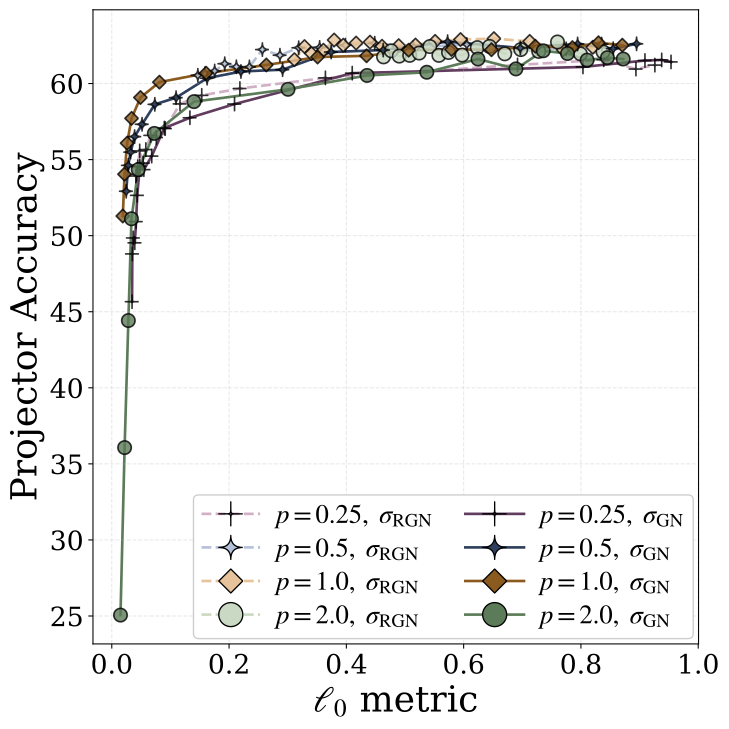
Figure 10: The Sparsity-Performance Tradeoffs under Different Chocies of σ∗∈{σGN,σRGN}\sigma^{*}\in\{\sigma_{\operatorname{GN}},\sigma_{\operatorname{RGN}}\}. (a) We report CIFAR-100 validation accuracy for pretrained Rectified LpJEPA projector representations under varying {μ,σ,p}\{\mu,\sigma,p\}. Under the same mean shift value μ\mu, choosing σRGN\sigma_{\operatorname{RGN}} leads to better performance compared to σGN\sigma_{\operatorname{GN}} if μ\mu is more negative. (b) Projector accuracy is plotted against the ℓ1\ell_{1} sparsity metrics measured over the pretrained Rectified LpJEPA projector representations. The gaps between σGN\sigma_{\operatorname{GN}} and σRGN\sigma_{\operatorname{RGN}} are negligible. (c) Switching from ℓ1\ell_{1} to ℓ0\ell_{0} sparsity metrics, we observe the same behavior. In fact, σGN\sigma_{\operatorname{GN}} attains minor advantages in the sparsity-performance tradeoffs, especially when p=1p=1 or p=0.5p=0.5.
Original figure
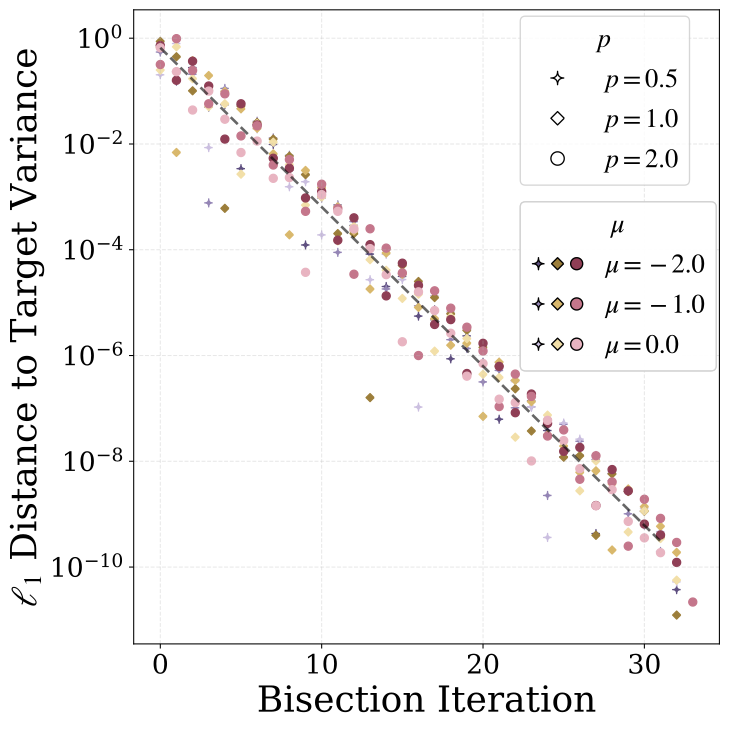
(a) Bisection Convergence of σ∗\sigma^{*} for |Var⁡(ℛ​𝒢​𝒩p​(μ,σ∗))−1|<ϵ|\operatorname{Var}(\mathcal{RGN}_{p}(\mu,\sigma^{*}))-1|<\epsilon.
Original figure
(b) Continuous Mapping Theorem
Original figure
(c) Necessity of Rectifications.
Figure 11: Additional Results on the Choices of σ\sigma, the Location of ReLU⁡(⋅)\operatorname{ReLU}(\cdot), and the Ablations of ReLU⁡(⋅)\operatorname{ReLU}(\cdot) for Rectified LpJEPA. (a) We report the bisection convergence error as a function of optimization iterations for finding the optimal σRGN\sigma_{\operatorname{RGN}} (see Appendix D). (b) We compared Rectified LpJEPA versus a version of distribution matching towards the Rectified Generalizd Gaussian distribution via the continuous mapping theorem (see Section 5.3). Rectified LpJEPA is the better design. (c) We show that Rectified LpJEPA attains the best sparsity-performance tradeoffs across various ablations of ReLU⁡(⋅)\operatorname{ReLU}(\cdot) under the ℓ1\ell_{1} sparsity metrics (1/D)⋅𝔼⁡[‖𝐳‖12/‖𝐳‖22](1/D)\cdot\mathbb{E}[\|\mathbf{z}\|_{1}^{2}/\|\mathbf{z}\|_{2}^{2}]. See Section 5.2 for details.
Original figure
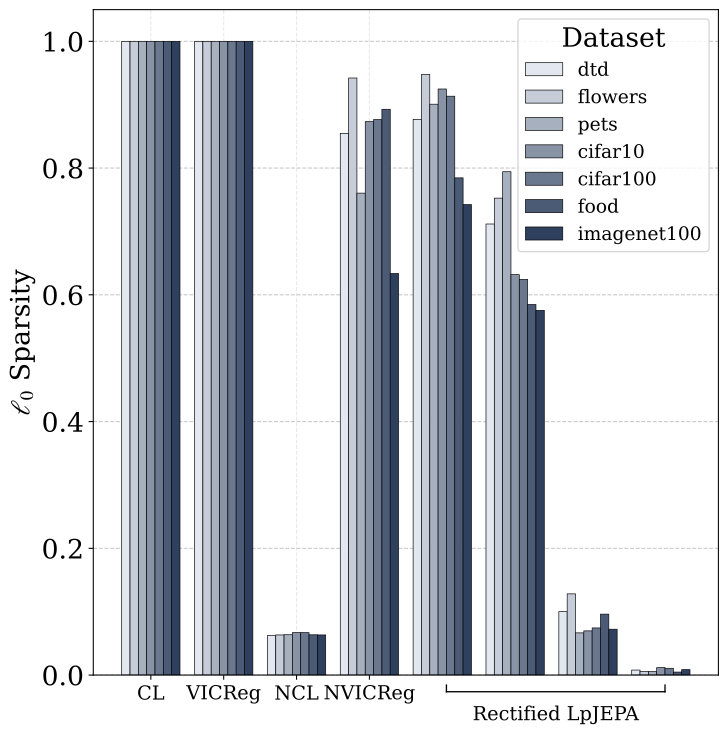
(a) ℓ0\ell_{0} Sparsity Across Transfer Tasks
Original figure
(b) ℓ1\ell_{1} Sparsity Across Transfer Tasks
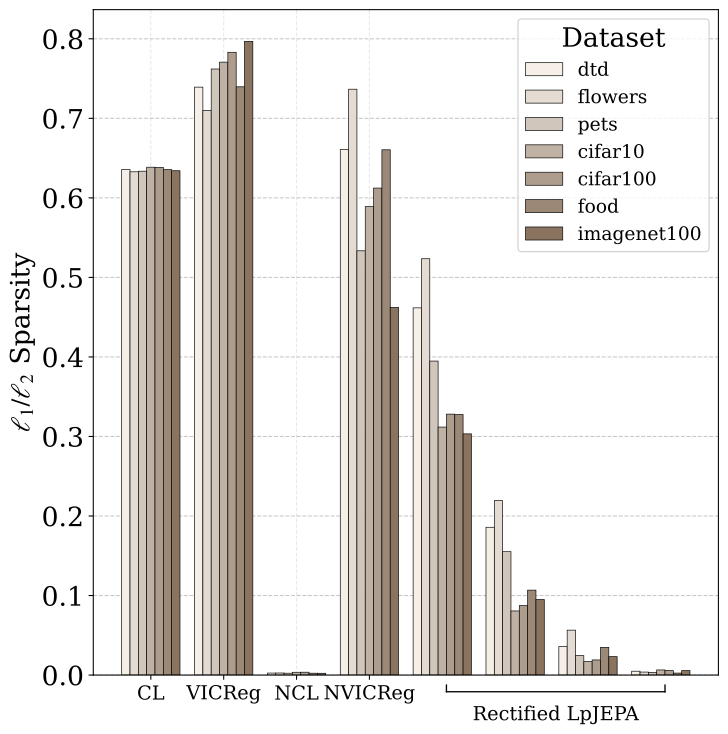
Figure 12: Pretrained dense and sparse representations exhibits varying level of sparsity across different downstream tasks. We compare the ℓ0\ell_{0} and ℓ1\ell_{1} sparsity metrics for Rectified LpJEPA versus other baselines (see Appendix H) pretrained over ImageNet-100 across a variety of downstream tasks. (a) Rectified LpJEPA has varying ℓ0\ell_{0} sparsity (1/D)⋅𝔼⁡[‖𝐳‖0](1/D)\cdot\mathbb{E}[\|\mathbf{z}\|_{0}] over different datasets as we vary the mean shift value μ∈{0,−1,−2,−3}\mu\in\{0,-1,-2,-3\}. CL and VICReg always have all entries being non-zero due to the lack of explicit rectifications. (b) Under ℓ1\ell_{1} sparsity metric (1/D)⋅𝔼⁡[‖𝐳‖12/‖𝐳‖22](1/D)\cdot\mathbb{E}[\|\mathbf{z}\|_{1}^{2}/\|\mathbf{z}\|_{2}^{2}], we observe varying sparsity for Rectified LpJEPA over different datasets for mean shift values ℓ0\ell_{0} sparsity (1/D)⋅𝔼⁡[‖𝐳‖0](1/D)\cdot\mathbb{E}[\|\mathbf{z}\|_{0}]. We observe that NCL in fact achieves the lowest ℓ1\ell_{1} metric, but as we show in Figure 3(c) the most amount of variations is attained by Rectified LpJEPA.

Appendix E Maximum Differential Entropy Distributions

E.1 Derivation of Maximum Entropy Continuous Multivariate Probability Distributions under Support Constraints

A constrained maximum-entropy derivation uses normalization, support and expected magnitude. The Lagrange multipliers encode these constraints; without them there is no identical optimization problem.

Lemma E.1 (Maximum Entropy Continuous Multivaraite Probability Distributions).

Let S⊆ℝdS\subseteq\mathbb{R}^{d} be a measurable set with positive Lebesgue measure. We define r1,⋯,rm:S→ℝr_{1},\cdots,r_{m}:S\to\mathbb{R} as measurable functions and let α1,⋯,αm∈ℝ\alpha_{1},\cdots,\alpha_{m}\in\mathbb{R}. Consider the optimization problem

Equations E.92–E.95
maxp−\displaystyle\max_{p}\hskip 9.24994pt- ∫Sp⁡(𝐱)​ln⁡p⁡(𝐱)​𝑑𝐱\displaystyle\int_{S}p(\mathbf{x})\ln p(\mathbf{x})d\mathbf{x} (E.92)
s.t.    ∫Sp⁡(𝐱)​𝑑𝐱=1,\displaystyle\int_{S}p(\mathbf{x})d\mathbf{x}=1, (E.93)
∫Sri(𝐱)p(𝐱)d𝐱=αi,i=1,⋯,m,\displaystyle\int_{S}r_{i}(\mathbf{x})p(\mathbf{x})d\mathbf{x}=\alpha_{i},\hskip 9.24994pti=1,\cdots,m, (E.94)
p⁡(𝐱)≥0​a.e. on ​S.\displaystyle p(\mathbf{x})\geq 0\hskip 9.24994pt\text{a.e. on }S. (E.95)

We denote the set of functions that satisfies the given constraints as

Equation E.96
𝒫:={p:→[0,∞)|∫Sp(𝐱)d𝐱=1,∫Sri(𝐱)p(𝐱)d𝐱=αi∀i}\displaystyle\mathcal{P}:=\bigg\{p:\to[0,\infty)\bigg|\int_{S}p(\mathbf{x})\,d\mathbf{x}=1,\int_{S}r_{i}(\mathbf{x})p(\mathbf{x})\,d\mathbf{x}=\alpha_{i}\,\forall i\bigg\} (E.96)

Assume the set 𝒫\mathcal{P} is nonempty and that there exists 𝛌=(λ1,…,λm)∈ℝm\boldsymbol{\lambda}=(\lambda_{1},\dots,\lambda_{m})\in\mathbb{R}^{m} such that

Equation E.97
ZS​(𝝀)\displaystyle Z_{S}(\boldsymbol{\lambda}) =∫Sexp⁡(∑i=1mλi​ri​(𝐱))​𝑑𝐱<∞.\displaystyle=\int_{S}\exp\bigg(\sum_{i=1}^{m}\lambda_{i}r_{i}(\mathbf{x})\bigg)\,d\mathbf{x}\;<\;\infty. (E.97)

Then any maximizer p⋆p^{\star} of the optimization problem has the form

Equation E.98
p⋆​(𝐱)\displaystyle p^{\star}(\mathbf{x}) =1ZS​(𝝀)​exp⁡(∑i=1mλi​ri​(𝐱))⋅𝟙S​(𝐱),\displaystyle=\frac{1}{Z_{S}(\boldsymbol{\lambda})}\exp\bigg(\sum_{i=1}^{m}\lambda_{i}r_{i}(\mathbf{x})\bigg)\cdot\mathbbm{1}_{S}(\mathbf{x}), (E.98)

where {λi}i=1m\{\lambda_{i}\}_{i=1}^{m} are chosen to satisfy the constraints {αi}i=1m\{\alpha_{i}\}_{i=1}^{m}.

Proof.

We can form the Lagrangian functional of the constrained optimization problem as

Equation E.99
𝒥[p]=−∫Sp(𝐱)lnp(𝐱)d𝐱+λ0(∫Sp(𝐱)d𝐱−1)+∑i=1mλi(∫Sri(𝐱)p(𝐱)d𝐱−αi)\displaystyle\mathcal{J}[p]=-\int_{S}p(\mathbf{x})\ln p(\mathbf{x})d\mathbf{x}+\lambda_{0}\bigg(\int_{S}p(\mathbf{x})d\mathbf{x}-1\bigg)+\sum_{i=1}^{m}\lambda_{i}\bigg(\int_{S}r_{i}(\mathbf{x})p(\mathbf{x})d\mathbf{x}-\alpha_{i}\bigg) (E.99)

where λ0,λ1,…,λm∈ℝ\lambda_{0},\lambda_{1},\dots,\lambda_{m}\in\mathbb{R} are Lagrange multipliers. Let pp be a maximizer that is strictly positive almost everywhere (a.e.) over SS. We denote δ​p\delta p as an arbitrary integrable perturbation supported on SS such that p+ϵ​δ​p≥0p+\epsilon\delta p\geq 0 for sufficiently small |ϵ||\epsilon|. Thus the Gateaux derivative of 𝒥\mathcal{J} in the direction of δ​p\delta p is given by

Equations E.100–E.104
dd​ϵ​𝒥​[p+ϵ​δ​p]|ϵ=0\displaystyle\left.\frac{d}{d\epsilon}\mathcal{J}[p+\epsilon\delta p]\right|_{\epsilon=0} =−∫Sdd​ϵ[(p(𝐱)+ϵδp(𝐱))ln(p(𝐱)+ϵδp(𝐱))]d𝐱|ϵ=0+λ0(∫Sdd​ϵ[p(𝐱)+ϵδp(𝐱)]d𝐱|ϵ=0)\displaystyle=-\int_{S}\left.\frac{d}{d\epsilon}\bigg[(p(\mathbf{x})+\epsilon\delta p(\mathbf{x}))\ln(p(\mathbf{x})+\epsilon\delta p(\mathbf{x}))\bigg]d\mathbf{x}\right|_{\epsilon=0}+\lambda_{0}\bigg(\int_{S}\left.\frac{d}{d\epsilon}\bigg[p(\mathbf{x})+\epsilon\delta p(\mathbf{x})\bigg]d\mathbf{x}\right|_{\epsilon=0}\bigg) (E.100)
+∑i=1mλi(∫Sdd​ϵ[ri(𝐱)(p(𝐱)+ϵδp(𝐱)))d𝐱]|ϵ=0)\displaystyle+\sum_{i=1}^{m}\lambda_{i}\bigg(\int_{S}\left.\frac{d}{d\epsilon}\bigg[r_{i}(\mathbf{x})(p(\mathbf{x})+\epsilon\delta p(\mathbf{x})))d\mathbf{x}\bigg]\right|_{\epsilon=0}\bigg) (E.101)
=−∫S[δp(𝐱)ln(p(𝐱)+ϵδp(𝐱))+δp(𝐱)]d𝐱|ϵ=0+λ0(∫S1⋅δp(𝐱)d𝐱)\displaystyle=-\int_{S}\left.\bigg[\delta p(\mathbf{x})\ln(p(\mathbf{x})+\epsilon\delta p(\mathbf{x}))+\delta p(\mathbf{x})\bigg]d\mathbf{x}\right|_{\epsilon=0}+\lambda_{0}\bigg(\int_{S}1\cdot\delta p(\mathbf{x})d\mathbf{x}\bigg) (E.102)
+∑i=1mλi(∫Sri(𝐱)δp(𝐱)d𝐱)\displaystyle+\sum_{i=1}^{m}\lambda_{i}\bigg(\int_{S}r_{i}(\mathbf{x})\delta p(\mathbf{x})d\mathbf{x}\bigg) (E.103)
=−∫S[lnp(𝐱)+1]δp(𝐱)d𝐱+(∫Sλ0⋅δp(𝐱)d𝐱)+(∫S∑i=1mλiri(𝐱)δp(𝐱)d𝐱)\displaystyle=-\int_{S}\bigg[\ln p(\mathbf{x})+1\bigg]\delta p(\mathbf{x})d\mathbf{x}+\bigg(\int_{S}\lambda_{0}\cdot\delta p(\mathbf{x})d\mathbf{x}\bigg)+\bigg(\int_{S}\sum_{i=1}^{m}\lambda_{i}r_{i}(\mathbf{x})\delta p(\mathbf{x})d\mathbf{x}\bigg) (E.104)

Thus the functional derivative is

Equation E.106
δ​𝒥δ​p\displaystyle\frac{\delta\mathcal{J}}{\delta p} =−ln⁡p⁡(𝐱)−1+λ0+∑i=1mλi​ri​(𝐱)\displaystyle=-\ln p(\mathbf{x})-1+\lambda_{0}+\sum_{i=1}^{m}\lambda_{i}r_{i}(\mathbf{x}) (E.106)

Since this expression must vanish for all admissible perturbations δ​p\delta p, we get δ​𝒥δ​p=0\frac{\delta\mathcal{J}}{\delta p}=0 almost everywhere on SS. Solving for pp yields

Equation E.107
p⁡(𝐱)\displaystyle p(\mathbf{x}) =exp⁡(λ0−1+∑i=1mλi​ri​(𝐱))\displaystyle=\exp\bigg(\lambda_{0}-1+\sum_{i=1}^{m}\lambda_{i}r_{i}(\mathbf{x})\bigg) (E.107)

Absorbing the constant terms into ZS​(𝝀)Z_{S}(\boldsymbol{\lambda}), we end up with

Equation E.108
p⁡(𝐱)\displaystyle p(\mathbf{x}) =1ZS​(𝝀)​exp⁡(∑i=1mλi​ri​(𝐱))⋅𝟙S​(𝐱)\displaystyle=\frac{1}{Z_{S}(\boldsymbol{\lambda})}\exp\bigg(\sum_{i=1}^{m}\lambda_{i}r_{i}(\mathbf{x})\bigg)\cdot\mathbbm{1}_{S}(\mathbf{x}) (E.108)

∎

E.2 Proof of Proposition 3.3 (Maximum Entropy Distribution Under the ℓ p Norm and Support Constraint)

The proof specializes the constrained calculation to the expected p-th-power magnitude and stated support, producing the generalized Gaussian form.

Equations E.109–E.115
p⁡(𝐱)\displaystyle p(\mathbf{x}) =1ZS​(λ1)​exp⁡(λ1​‖𝐱‖pp)⋅𝟙S​(𝐱)\displaystyle=\frac{1}{Z_{S}(\lambda_{1})}\exp(\lambda_{1}\|\mathbf{x}\|_{p}^{p})\cdot\mathbbm{1}_{S}(\mathbf{x}) (E.109)
=1ZS​(λ1)​exp⁡(−‖𝐱‖ppp​σp)⋅𝟙S​(𝐱)\displaystyle=\frac{1}{Z_{S}(\lambda_{1})}\exp\bigg(-\frac{\|\mathbf{x}\|_{p}^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{S}(\mathbf{x}) (E.110)
dd​λ1​log⁡ZS​(λ1)\displaystyle\frac{d}{d\lambda_{1}}\log Z_{S}(\lambda_{1}) =1ZS​(λ1)​dd​λ1​ZS​(λ1)\displaystyle=\frac{1}{Z_{S}(\lambda_{1})}\frac{d}{d\lambda_{1}}Z_{S}(\lambda_{1}) (E.111)
=1ZS​(λ1)​∫Sdd​λ1​exp⁡(λ1​‖𝐱‖pp)​𝑑𝐱\displaystyle=\frac{1}{Z_{S}(\lambda_{1})}\int_{S}\frac{d}{d\lambda_{1}}\exp(\lambda_{1}\|\mathbf{x}\|_{p}^{p})d\mathbf{x} (E.112)
=1ZS​(λ1)​∫S‖𝐱‖pp​exp⁡(λ1​‖𝐱‖pp)​𝑑𝐱\displaystyle=\frac{1}{Z_{S}(\lambda_{1})}\int_{S}\|\mathbf{x}\|_{p}^{p}\exp(\lambda_{1}\|\mathbf{x}\|_{p}^{p})d\mathbf{x} (E.113)
=∫S‖𝐱‖pp​1ZS​(λ1)​exp⁡(−‖𝐱‖ppp​σp)⋅𝟙S​(𝐱)​𝑑𝐱\displaystyle=\int_{S}\|\mathbf{x}\|_{p}^{p}\frac{1}{Z_{S}(\lambda_{1})}\exp\bigg(-\frac{\|\mathbf{x}\|_{p}^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{S}(\mathbf{x})d\mathbf{x} (E.114)
=𝔼⁡[‖𝐱‖pp]\displaystyle=\mathbb{E}[\|\mathbf{x}\|_{p}^{p}] (E.115)

E.3 Maximum Entropy Distribution Under the ℓ p Norm with Full Support

Removing the support restriction recovers the full-support generalized Gaussian case and its moment relationship.

Corollary E.2.

If S=ℝdS=\mathbb{R}^{d} in Proposition 3.3, then the constraint

Equation E.116
𝔼⁡[‖𝐱‖pp]=dd​λ1​log⁡ZS​(λ1)=d​σp\displaystyle\mathbb{E}[\|\mathbf{x}\|_{p}^{p}]=\frac{d}{d\lambda_{1}}\log Z_{S}(\lambda_{1})=d\sigma^{p} (E.116)

and we recover the Generalized Gaussian distribution with zero mean and scale parameter σ\sigma.

Equation E.117
p⁡(x)=pd−d/p(2​σ)d​Γ​(1/p)d​exp⁡(−‖𝐱‖ppp​σp)\displaystyle p(x)=\frac{p^{d-d/p}}{(2\sigma)^{d}\Gamma(1/p)^{d}}\exp\bigg(-\frac{\|\mathbf{x}\|_{p}^{p}}{p\sigma^{p}}\bigg) (E.117)
Equations E.118–E.120
p⁡(x)=1ZS​(λ1)​exp⁡(−‖𝐱‖ppp​σp)⋅𝟙S​(𝐱)\displaystyle p(x)=\frac{1}{Z_{S}(\lambda_{1})}\exp\bigg(-\frac{\|\mathbf{x}\|_{p}^{p}}{p\sigma^{p}}\bigg)\cdot\mathbbm{1}_{S}(\mathbf{x}) (E.118)
1ZS​(λ1)=1Zℝd​(λ1)=pd−d/p(2​σ)d​Γ​(1/p)d\displaystyle\frac{1}{Z_{S}(\lambda_{1})}=\frac{1}{Z_{\mathbb{R}^{d}}(\lambda_{1})}=\frac{p^{d-d/p}}{(2\sigma)^{d}\Gamma(1/p)^{d}} (E.119)
𝔼⁡[‖𝐱‖pp]=dd​λ1​log⁡ZS​(λ1)=d​σp\displaystyle\mathbb{E}[\|\mathbf{x}\|_{p}^{p}]=\frac{d}{d\lambda_{1}}\log Z_{S}(\lambda_{1})=d\sigma^{p} (E.120)

E.4 Maximum Entropy Distribution Under the ℓ 1 Norm Constraint

The first-power constraint yields the Laplace-family special case under the specified support.

Corollary E.3.

The maximum entropy distribution over ℝd\mathbb{R}^{d} under the constraints

Equation E.121
∫ℝdp⁡(𝐱)​𝑑𝐱\displaystyle\int_{\mathbb{R}^{d}}p(\mathbf{x})d\mathbf{x} =1,𝔼⁡[‖𝐱‖1]=d​b\displaystyle=1,\hskip 9.24994pt\mathbb{E}[\|\mathbf{x}\|_{1}]=db (E.121)

is the product of independent univariate symmetric Laplace distributions with zero mean and scale parameter bb

Equation E.122
p⁡(𝐱)=(12​b)d​exp⁡(−‖𝐱‖1b)\displaystyle p(\mathbf{x})=\bigg(\frac{1}{2b}\bigg)^{d}\exp\bigg(-\frac{\|\mathbf{x}\|_{1}}{b}\bigg) (E.122)
Equations E.123–E.125
p⁡(𝐱)∝exp⁡(λ1​‖𝐱‖1)\displaystyle p(\mathbf{x})\propto\exp(\lambda_{1}\|\mathbf{x}\|_{1}) (E.123)
p⁡(𝐱)=(−λ12)d​exp⁡(λ1​‖𝐱‖1)\displaystyle p(\mathbf{x})=\bigg(-\frac{\lambda_{1}}{2}\bigg)^{d}\exp(\lambda_{1}\|\mathbf{x}\|_{1}) (E.124)
p⁡(𝐱)=(12​b)d​exp⁡(−‖𝐱‖1b)\displaystyle p(\mathbf{x})=\bigg(\frac{1}{2b}\bigg)^{d}\exp\bigg(-\frac{\|\mathbf{x}\|_{1}}{b}\bigg) (E.125)

E.5 Maximum Entropy Distribution under the ℓ 2 Norm Constraint

The second-power constraint yields the Gaussian-family special case under the specified support.

Corollary E.4.

The maximum entropy distribution over ℝd\mathbb{R}^{d} under the constraints

Equation E.126
∫ℝdp⁡(𝐱)​𝑑𝐱\displaystyle\int_{\mathbb{R}^{d}}p(\mathbf{x})d\mathbf{x} =1,𝔼⁡[𝐱]=𝝁,𝔼⁡[(𝐱−𝝁)​(𝐱−𝝁)⊤]=𝚺\displaystyle=1,\hskip 9.24994pt\mathbb{E}[\mathbf{x}]=\boldsymbol{\mu},\hskip 9.24994pt\mathbb{E}[(\mathbf{x}-\boldsymbol{\mu})(\mathbf{x}-\boldsymbol{\mu})^{\top}]=\mathbf{\Sigma} (E.126)

is the multivariate Gaussian distribution with mean 𝛍\boldsymbol{\mu} and covariance 𝚺\mathbf{\Sigma}

Equation E.127
p⁡(𝐱)∝exp⁡(−12​(𝐱−𝝁)⊤​𝚺−1​(𝐱−𝝁))\displaystyle p(\mathbf{x})\propto\exp\bigg(-\frac{1}{2}(\mathbf{x}-\boldsymbol{\mu})^{\top}\mathbf{\Sigma}^{-1}(\mathbf{x}-\boldsymbol{\mu})\bigg) (E.127)

When 𝛍=0\boldsymbol{\mu}=0 and 𝚺=𝐈\mathbf{\Sigma}=\mathbf{I}, the density function takes the form of

Equation E.128
p⁡(𝐱)∝exp⁡(−12​‖𝐱‖22)\displaystyle p(\mathbf{x})\propto\exp\bigg(-\frac{1}{2}\|\mathbf{x}\|_{2}^{2}\bigg) (E.128)
Proof.

Notice that the vector-valued mean constraint and matrix-valued covariance constraint can be factorized as a collection of scalar-valued constraints

Equation E.129
𝔼[𝐱i]=𝝁i,𝔼[𝐱i𝐱j]=𝚺i​j+𝝁i𝝁j,∀i,j∈{1,⋯,d}\displaystyle\mathbb{E}[\mathbf{x}_{i}]=\boldsymbol{\mu}_{i},\hskip 9.24994pt\mathbb{E}[\mathbf{x}_{i}\mathbf{x}_{j}]=\mathbf{\Sigma}_{ij}+\boldsymbol{\mu}_{i}\boldsymbol{\mu}_{j},\hskip 9.24994pt\forall i,j\in\{1,\cdots,d\} (E.129)

By Lemma E.1, the maximum entropy distribution has the form

Equations E.130–E.132
p⁡(𝐱)\displaystyle p(\mathbf{x}) ∝exp⁡(∑i=1d𝝀i​𝐱i+∑i=1d∑j=1d𝚲i​j​𝐱i​𝐱j)\displaystyle\propto\exp\bigg(\sum_{i=1}^{d}\boldsymbol{\lambda}_{i}\mathbf{x}_{i}+\sum_{i=1}^{d}\sum_{j=1}^{d}\mathbf{\Lambda}_{ij}\mathbf{x}_{i}\mathbf{x}_{j}\bigg) (E.130)
=exp⁡(𝝀⊤​𝐱+𝐱⊤​𝚲​𝐱)\displaystyle=\exp\bigg(\boldsymbol{\lambda}^{\top}\mathbf{x}+\mathbf{x}^{\top}\mathbf{\Lambda}\mathbf{x}\bigg) (E.131)
∝exp⁡(−12​(𝐱−𝝁)⊤​𝚺−1​(𝐱−𝝁))\displaystyle\propto\exp\bigg(-\frac{1}{2}(\mathbf{x}-\boldsymbol{\mu})^{\top}\mathbf{\Sigma}^{-1}(\mathbf{x}-\boldsymbol{\mu})\bigg) (E.132)

for 𝝀=𝚺−1​𝝁\boldsymbol{\lambda}=\mathbf{\Sigma}^{-1}\boldsymbol{\mu} and 𝚲=−12​𝚺−1\mathbf{\Lambda}=-\frac{1}{2}\mathbf{\Sigma}^{-1}, which is the multivariate Gaussian distribution up to normalizations. When 𝝁=0\boldsymbol{\mu}=0 and 𝚺=𝐈\mathbf{\Sigma}=\mathbf{I}, the density function trivially evaluates to

Equation E.133
p⁡(𝐱)\displaystyle p(\mathbf{x}) ∝exp⁡(−12​‖𝐱‖22)\displaystyle\propto\exp\bigg(-\frac{1}{2}\|\mathbf{x}\|_{2}^{2}\bigg) (E.133)

which is the maximum-entropy distribution under the expected ℓ2\ell_{2} norm constraints based on Lemma E.1. ∎

Appendix F Rényi Information Dimension and Entropy

F.1 Definition of the d ⁡ ( ξ ) -dimensional Entropy

Rényi information dimension describes how quantized entropy grows as the resolution becomes finer. It distinguishes discrete, continuous and mixed distributions.

Equation F.134
ℍ(X)=−∫d​ℙXd​λlog(d​ℙXd​λ)dλ\displaystyle\mathbb{H}(X)=-\int\frac{d\mathbb{P}_{X}}{d\lambda}\log\bigg(\frac{d\mathbb{P}_{X}}{d\lambda}\bigg)d\lambda (F.134)
Definition F.1 (Information Dimension (Rényi, 1959)).

Consider a real-valued random variable ξ∈ℝ\xi\in\mathbb{R} and the discretization ξn=(1/n)⋅[n​ξ]\xi_{n}=(1/n)\cdot[n\xi], where [x][x] preserves only the integral part of xx. For example, [3.42]=3[3.42]=3. Under suitable conditions, the information dimension d⁡(ξ)d(\xi) exists and is given by

Equation F.135
d⁡(ξ)=limn→∞ℍ0​(ξn)log⁡n\displaystyle d(\xi)=\lim_{n\to\infty}\frac{\mathbb{H}_{0}(\xi_{n})}{\log n} (F.135)

where

Equation F.136
ℍ0​(η):=∑k=1∞qk​log⁡1qk\displaystyle\mathbb{H}_{0}(\eta):=\sum_{k=1}^{\infty}q_{k}\log\frac{1}{q_{k}} (F.136)

is the Shannon entropy for a discrete random variable η\eta with probabilities qkq_{k} for k=1,2,…k=1,2,\dots.

Definition F.2 (d⁡(ξ)d(\xi)-dimensional Entropy (Rényi, 1959)).

If the information dimension d⁡(ξ)d(\xi) exists, the d⁡(ξ)d(\xi)-dimensional entropy is defined as

Equation F.137
ℍd⁡(ξ)=limn→∞(ℍ0​(ξn)−d⁡(ξ)​log⁡n)\displaystyle\mathbb{H}_{d(\xi)}=\lim_{n\to\infty}(\mathbb{H}_{0}(\xi_{n})-d(\xi)\log n) (F.137)
Definition F.3 (d⁡(ξ)d(\xi)-dimensional Entropy for Mixed Measures (Rényi, 1959)).

Let ξ\xi be a random variable with probability measure

Equation F.138
ℙξ=(1−d)⋅ℙ0+d⋅ℙ1\displaystyle\mathbb{P}_{\xi}=(1-d)\cdot\mathbb{P}_{0}+d\cdot\mathbb{P}_{1} (F.138)

where ℙ0\mathbb{P}_{0} is discrete and ℙ1\mathbb{P}_{1} is absolutely continuous with respect to the Lebesgue measure. Then the information dimension d⁡(ξ)=dd(\xi)=d, and the d⁡(ξ)d(\xi)-dimensional entropy is given by

Equation F.139
ℍd⁡(ξ)​(ξ)=(1−d)⋅∑k=1∞pk​log​1pk−d⋅∫ℝd​ℙ1d​λ​(x)​log⁡(d​ℙ1d​λ​(x))​𝑑λ​(x)+d​log​1d+(1−d)​log​11−d\displaystyle\mathbb{H}_{d(\xi)}(\xi)=(1-d)\cdot\sum_{k=1}^{\infty}p_{k}\log\frac{1}{p_{k}}-d\cdot\int_{\mathbb{R}}\frac{d\mathbb{P}_{1}}{d\lambda}(x)\log\bigg(\frac{d\mathbb{P}_{1}}{d\lambda}(x)\bigg)d\lambda(x)+d\log\frac{1}{d}+(1-d)\log\frac{1}{1-d} (F.139)

where λ\lambda is the Lebesgue measure.

F.2 Proof of Theorem 3.6 (The d ⁡ ( ξ ) -dimensional Entropy of the Rectified Generalized Gaussian Distribution)

The theorem splits the rectified law into zero/nonzero indicators and continuous active coordinates. Their contributions characterize its information dimension and associated entropy.

Equations F.140–F.147
d⁡(𝝃)\displaystyle d(\boldsymbol{\xi}) =D⋅d⁡(𝝃i)\displaystyle=D\cdot d(\boldsymbol{\xi}_{i}) (F.140)
ℍd⁡(𝝃)​(𝝃)\displaystyle\mathbb{H}_{d(\boldsymbol{\xi})}(\boldsymbol{\xi}) =∑i=1Dℍd⁡(𝝃i)​(𝝃i)=D⋅ℍd⁡(𝝃i)​(𝝃i)\displaystyle=\sum_{i=1}^{D}\mathbb{H}_{d(\boldsymbol{\xi}_{i})}(\boldsymbol{\xi}_{i})=D\cdot\mathbb{H}_{d(\boldsymbol{\xi}_{i})}(\boldsymbol{\xi}_{i}) (F.141)
d⁡(𝝃i)=1−Φ𝒢​𝒩p​(0,1)​(−μσ)=Φ𝒢​𝒩p​(0,1)​(μσ)\displaystyle d(\boldsymbol{\xi}_{i})=1-\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(-\frac{\mu}{\sigma}\bigg)=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg) (F.142)
(1−d⁡(𝝃i))⋅∑k=1∞pk​log​1pk=(1−d⁡(𝝃i))⋅(1​log​1)=0\displaystyle(1-d(\boldsymbol{\xi}_{i}))\cdot\sum_{k=1}^{\infty}p_{k}\log\frac{1}{p_{k}}=(1-d(\boldsymbol{\xi}_{i}))\cdot(1\log 1)=0 (F.143)
𝟙(0,∞)​(𝝃i)={1,if ​𝝃i∈(0,∞)⟹with probability ​d​(𝝃i)0,if ​𝝃i∉(0,∞)⟹with probability ​1−d⁡(𝝃i)\displaystyle\mathbbm{1}_{(0,\infty)}(\boldsymbol{\xi}_{i})=\begin{cases}1,\text{if }\boldsymbol{\xi}_{i}\in(0,\infty)\implies\text{with probability }d(\boldsymbol{\xi}_{i})\\ 0,\text{if }\boldsymbol{\xi}_{i}\notin(0,\infty)\implies\text{with probability }1-d(\boldsymbol{\xi}_{i})\end{cases} (F.144)
ℍ0​(𝟙(0,∞)​(𝝃i))\displaystyle\mathbb{H}_{0}(\mathbbm{1}_{(0,\infty)}(\boldsymbol{\xi}_{i})) =d⁡(𝝃i)​log​1d⁡(𝝃i)+(1−d⁡(𝝃i))​log​11−d⁡(𝝃i)\displaystyle=d(\boldsymbol{\xi}_{i})\log\frac{1}{d(\boldsymbol{\xi}_{i})}+(1-d(\boldsymbol{\xi}_{i}))\log\frac{1}{1-d(\boldsymbol{\xi}_{i})} (F.145)
ℍd⁡(𝝃i)​(𝝃i)\displaystyle\mathbb{H}_{d(\boldsymbol{\xi}_{i})}(\boldsymbol{\xi}_{i}) =0−d⁡(𝝃i)⋅∫ℝd​ℙ𝒯​𝒢​𝒩p​(μ,σ)d​λ​(x)​log⁡(d​ℙ𝒯​𝒢​𝒩p​(μ,σ)d​λ​(x))​𝑑λ​(x)+ℍ0​(𝟙(0,∞)​(𝝃i))\displaystyle=0-d(\boldsymbol{\xi}_{i})\cdot\int_{\mathbb{R}}\frac{d\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}}{d\lambda}(x)\log\bigg(\frac{d\mathbb{P}_{\mathcal{TGN}_{p}(\mu,\sigma)}}{d\lambda}(x)\bigg)d\lambda(x)+\mathbb{H}_{0}(\mathbbm{1}_{(0,\infty)}(\boldsymbol{\xi}_{i})) (F.146)
=Φ𝒢​𝒩p​(0,1)​(μσ)⋅ℍ1​(𝒯​𝒢​𝒩p​(μ,σ))+ℍ0​(𝟙(0,∞)​(𝝃i))\displaystyle=\Phi_{\mathcal{GN}_{p}(0,1)}\bigg(\frac{\mu}{\sigma}\bigg)\cdot\mathbb{H}_{1}(\mathcal{TGN}_{p}(\mu,\sigma))+\mathbb{H}_{0}(\mathbbm{1}_{(0,\infty)}(\boldsymbol{\xi}_{i})) (F.147)

F.3 Empirical Estimators of the d ⁡ ( ξ ) -dimensional entropy

The appendix specifies empirical estimators rather than assuming ordinary differential-entropy estimators apply unchanged to data with exact zeros.

Lemma F.4 (Probability Measure Under Rectification).

Let X∼ℙXX\sim\mathbb{P}_{X} be a real-valued random variable where ℙX\mathbb{P}_{X} is absolutely continuous with respect to the Lebesgue measure λ\lambda, i.e. ℙX≪λ\mathbb{P}_{X}\ll\lambda. Then the probability measure of Z:=max⁡(0,X)Z:=\max(0,X) over ([0,∞),ℬ⁡([0,∞)))([0,\infty),\mathcal{B}([0,\infty))) is

Equation F.148
ℙZ=(1−d)⋅δ0+d⋅ℙX|(0,∞)\displaystyle\mathbb{P}_{Z}=(1-d)\cdot\delta_{0}+d\cdot\mathbb{P}_{X\mid(0,\infty)} (F.148)

where δ0\delta_{0} is the Dirac measure and 1−d:=ℙ⁡(Z=0)=ℙ⁡(X≤0)1-d:=\mathbb{P}(Z=0)=\mathbb{P}(X\leq 0) and

Equation F.149
ℙX|(0,∞)​(A):=ℙX​(A∩(0,∞))ℙX​((,,,))=ℙX​(A)d\displaystyle\mathbb{P}_{X\mid(0,\infty)}(A):=\frac{\mathbb{P}_{X}(A\cap(0,\infty))}{\mathbb{P}_{X}((0,\infty))}=\frac{\mathbb{P}_{X}(A)}{d} (F.149)

for any Borel A⊂(0,∞)A\subset(0,\infty).

Equations F.150–F.156
ℙZ​(B)=ℙX​(φ−1​(B)).\displaystyle\mathbb{P}_{Z}(B)=\mathbb{P}_{X}(\varphi^{-1}(B)). (F.150)
φ−1(B)=(φ−1(B)∩(−∞,0])∪(φ−1(B)∩(0,∞)),\displaystyle\varphi^{-1}(B)=\big(\varphi^{-1}(B)\cap(-\infty,0]\big)\;\cup\;\big(\varphi^{-1}(B)\cap(0,\infty)\big), (F.151)
φ−1(B)∩(−∞,0]={(−∞,0],0∈B,∅,0∉B.\displaystyle\varphi^{-1}(B)\cap(-\infty,0]=\begin{cases}(-\infty,0],&0\in B,\\ \emptyset,&0\notin B.\end{cases} (F.152)
φ−1​(B)∩(0,∞)=B∩(0,∞).\displaystyle\varphi^{-1}(B)\cap(0,\infty)=B\cap(0,\infty). (F.153)
ℙZ(B)=ℙX(φ−1(B))=ℙX(B∩(0,∞))+ℙX((−∞,0])⋅δ0(B)\displaystyle\mathbb{P}_{Z}(B)=\mathbb{P}_{X}(\varphi^{-1}(B))=\mathbb{P}_{X}(B\cap(0,\infty))+\mathbb{P}_{X}((-\infty,0])\cdot\delta_{0}(B) (F.154)
ℙX|(0,∞)​(A):=ℙX​(A∩(0,∞))ℙX​((,,,))=ℙX​(A∩(0,∞))d,A∈ℬ⁡(ℝ).\displaystyle\mathbb{P}_{X\mid(0,\infty)}(A):=\frac{\mathbb{P}_{X}(A\cap(0,\infty))}{\mathbb{P}_{X}((0,\infty))}=\frac{\mathbb{P}_{X}(A\cap(0,\infty))}{d},\hskip 18.49988ptA\in\mathcal{B}(\mathbb{R}). (F.155)
ℙZ​(B)=d​ℙX|(0,∞)​(B)+(1−d)​δ0​(B)\displaystyle\mathbb{P}_{Z}(B)=d\,\mathbb{P}_{X\mid(0,\infty)}(B)+(1-d)\,\delta_{0}(B) (F.156)
Lemma F.5 (Radon–Nikodym Derivative Under Rectifications).

Let X∼ℙXX\sim\mathbb{P}_{X} be a real-valued random variable where ℙX\mathbb{P}_{X} is absolutely continuous with respect to the Lebesgue measure λ\lambda, i.e. ℙX≪λ\mathbb{P}_{X}\ll\lambda. Consider Z:=max⁡(0,X)∼ℙZZ:=\max(0,X)\sim\mathbb{P}_{Z} and let δ0\delta_{0} be the Dirac measure in Definition B.4. Then the Radon–Nikodym derivative of ℙZ\mathbb{P}_{Z} with respect to ν=δ0+λ\nu=\delta_{0}+\lambda is given by

Equation F.157
d​ℙZd​ν​(x)=(1−d)⋅𝟙{0}​(x)+d⋅d​ℙX|(0,∞)d​λ​(x)⋅𝟙(0,∞)​(x)\displaystyle\frac{d\mathbb{P}_{Z}}{d\nu}(x)=(1-d)\cdot\mathbbm{1}_{\{0\}}(x)+d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x) (F.157)
Equations F.158–F.171
∫Ad​ℙZd​ν​𝑑ν\displaystyle\int_{A}\frac{d\mathbb{P}_{Z}}{d\nu}d\nu =∫Ad​ℙZd​ν​d​δ0+∫Ad​ℙZd​ν​𝑑λ\displaystyle=\int_{A}\frac{d\mathbb{P}_{Z}}{d\nu}d\delta_{0}+\int_{A}\frac{d\mathbb{P}_{Z}}{d\nu}d\lambda (F.158)
∫Ad​ℙZd​ν​d​δ0=d​ℙZd​ν​(0)​δ0​(A)=(1−d)⋅δ0​(A)\displaystyle\int_{A}\frac{d\mathbb{P}_{Z}}{d\nu}d\delta_{0}=\frac{d\mathbb{P}_{Z}}{d\nu}(0)\delta_{0}(A)=(1-d)\cdot\delta_{0}(A) (F.159)
∫Ad​ℙZd​ν​𝑑λ\displaystyle\int_{A}\frac{d\mathbb{P}_{Z}}{d\nu}d\lambda =∫A(1−d)⋅𝟙{0}​(x)​𝑑λ​(x)+∫Ad⋅d​ℙX|(0,∞)d​λ​(x)⋅𝟙(0,∞)​(x)​𝑑λ​(x)\displaystyle=\int_{A}(1-d)\cdot\mathbbm{1}_{\{0\}}(x)d\lambda(x)+\int_{A}d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x)d\lambda(x) (F.160)
=(1−d)⋅∫A𝟙{0}​(x)​𝑑λ​(x)+∫A∩(0,∞)d⋅d​ℙX|(0,∞)d​λ​(x)⋅d​λ​(x)\displaystyle=(1-d)\cdot\int_{A}\mathbbm{1}_{\{0\}}(x)d\lambda(x)+\int_{A\cap(0,\infty)}d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot d\lambda(x) (F.161)
=0+d⋅∫A∩(0,∞)d​ℙX|(0,∞)​(x)\displaystyle=0+d\cdot\int_{A\cap(0,\infty)}d\mathbb{P}_{X|(0,\infty)}(x) (F.162)
=d⋅ℙX|(0,∞)​(A)\displaystyle=d\cdot\mathbb{P}_{X|(0,\infty)}(A) (F.163)
∫Ad​ℙZd​ν​𝑑ν\displaystyle\int_{A}\frac{d\mathbb{P}_{Z}}{d\nu}d\nu =(1−d)⋅δ0​(A)+d⋅ℙX|(0,∞)​(A)=ℙZ​(A)\displaystyle=(1-d)\cdot\delta_{0}(A)+d\cdot\mathbb{P}_{X|(0,\infty)}(A)=\mathbb{P}_{Z}(A) (F.164)
ℙZ=(1−d)⋅δ0+d⋅ℙX|(0,∞)\displaystyle\mathbb{P}_{Z}=(1-d)\cdot\delta_{0}+d\cdot\mathbb{P}_{X\mid(0,\infty)} (F.165)
ℙX|(0,∞)​(A)=ℙX​(A)ℙX​((,,,))\displaystyle\mathbb{P}_{X\mid(0,\infty)}(A)=\frac{\mathbb{P}_{X}(A)}{\mathbb{P}_{X}((0,\infty))} (F.166)
ℍd⁡(Z)​(Z)=d⁡(Z)⋅ℍ1​(ℙX|(0,∞))+ℍ0​(𝟙(0,∞)​(Z))\displaystyle\mathbb{H}_{d(Z)}(Z)=d(Z)\cdot\mathbb{H}_{1}(\mathbb{P}_{X\mid(0,\infty)})+\mathbb{H}_{0}(\mathbbm{1}_{(0,\infty)}(Z)) (F.167)
d^​(Z)=1B​∑i=1B𝟙(0,∞)​(zi)\displaystyle\hat{d}(Z)=\frac{1}{B}\sum_{i=1}^{B}\mathbbm{1}_{(0,\infty)}(z_{i}) (F.168)
ℍ^1​(ℙX|(0,∞))=1B′−m​∑i=1B′−mlog⁡(B′+1m​(z(i+m)−z(i)))\displaystyle\hat{\mathbb{H}}_{1}(\mathbb{P}_{X\mid(0,\infty)})=\frac{1}{B^{\prime}-m}\sum_{i=1}^{B^{\prime}-m}\log\bigg(\frac{B^{\prime}+1}{m}\bigg(z_{(i+m)}-z_{(i)}\bigg)\bigg) (F.169)
ℍ^d⁡(Z)​(Z)=d^​(Z)⋅ℍ^1​(ℙX|(0,∞))+d^​(Z)​log⁡1d^​(Z)+(1−d^​(Z))​log⁡11−d^​(Z)\displaystyle\hat{\mathbb{H}}_{d(Z)}(Z)=\hat{d}(Z)\cdot\hat{\mathbb{H}}_{1}(\mathbb{P}_{X\mid(0,\infty)})+\hat{d}(Z)\log\frac{1}{\hat{d}(Z)}+(1-\hat{d}(Z))\log\frac{1}{1-\hat{d}(Z)} (F.170)
ℍd⁡(𝐳)​(𝐳)≤∑i=1Dℍd⁡(𝐳i)​(𝐳i)\displaystyle\mathbb{H}_{d(\mathbf{z})}(\mathbf{z})\leq\sum_{i=1}^{D}\mathbb{H}_{d(\mathbf{z}_{i})}(\mathbf{z}_{i}) (F.171)

F.4 Alternative Interpretation of the d ⁡ ( ξ ) -dimensional Entropy

An alternative interpretation relates the mixed entropy to uncertainty about activation patterns and uncertainty in positive magnitudes.

Equations F.172–F.174
ℍλ(X)=−∫d​ℙXd​λlog(d​ℙXd​λ)dλ\displaystyle\mathbb{H}_{\lambda}(X)=-\int\frac{d\mathbb{P}_{X}}{d\lambda}\log\bigg(\frac{d\mathbb{P}_{X}}{d\lambda}\bigg)d\lambda (F.172)
ℙZ=(1−d)⋅δ0+d⋅ℙX|(0,∞)\displaystyle\mathbb{P}_{Z}=(1-d)\cdot\delta_{0}+d\cdot\mathbb{P}_{X\mid(0,\infty)} (F.173)
ℍν(Z)=−∫d​ℙZd​νlog(d​ℙZd​ν)dν\displaystyle\mathbb{H}_{\nu}(Z)=-\int\frac{d\mathbb{P}_{Z}}{d\nu}\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}\bigg)d\nu (F.174)
Lemma F.6.

The entropy ℍν​(Z)\mathbb{H}_{\nu}(Z) is equivalent to the d⁡(Z)d(Z)-dimensional entropy

Equation F.175
ℍν​(Z)=Hd⁡(Z)​(Z)\displaystyle\mathbb{H}_{\nu}(Z)=H_{d(Z)}(Z) (F.175)
Equations F.176–F.186
ℍν​(Z)\displaystyle\mathbb{H}_{\nu}(Z) =−∫d​ℙZd​νlog(d​ℙZd​ν)dν\displaystyle=-\int\frac{d\mathbb{P}_{Z}}{d\nu}\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}\bigg)d\nu (F.176)
=−∫d​ℙZd​νlog(d​ℙZd​ν)dδ0−∫d​ℙZd​νlog(d​ℙZd​ν)dλ\displaystyle=-\int\frac{d\mathbb{P}_{Z}}{d\nu}\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}\bigg)d\delta_{0}-\int\frac{d\mathbb{P}_{Z}}{d\nu}\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}\bigg)d\lambda (F.177)
−∫d​ℙZd​ν(x)log(d​ℙZd​ν(x))dδ0(x)=−d​ℙZd​ν(0)log(d​ℙZd​ν(0))=−(1−d)log(1−d)\displaystyle-\int\frac{d\mathbb{P}_{Z}}{d\nu}(x)\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}(x)\bigg)d\delta_{0}(x)=-\frac{d\mathbb{P}_{Z}}{d\nu}(0)\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}(0)\bigg)=-(1-d)\log(1-d) (F.178)
d​ℙZd​ν​(x)=(1−d)⋅𝟙{0}​(x)+d⋅d​ℙX|(0,∞)d​λ​(x)⋅𝟙(0,∞)​(x)\displaystyle\frac{d\mathbb{P}_{Z}}{d\nu}(x)=(1-d)\cdot\mathbbm{1}_{\{0\}}(x)+d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x) (F.179)
−∫d​ℙZd​νlog(d​ℙZd​ν)dλ\displaystyle-\int\frac{d\mathbb{P}_{Z}}{d\nu}\log\bigg(\frac{d\mathbb{P}_{Z}}{d\nu}\bigg)d\lambda =−∫d⋅d​ℙX|(0,∞)d​λ(x)⋅𝟙(0,∞)(x)log(d⋅d​ℙX|(0,∞)d​λ(x)⋅𝟙(0,∞)(x))dλ(x)\displaystyle=-\int d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x)\log(d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x))d\lambda(x) (F.180)
=−∫d⋅d​ℙX|(0,∞)d​λ(x)⋅𝟙(0,∞)(x)log(d​ℙX|(0,∞)d​λ(x)⋅𝟙(0,∞)(x))dλ(x)\displaystyle=-\int d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x)\log(\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x))d\lambda(x) (F.181)
−∫d⋅d​ℙX|(0,∞)d​λ(x)⋅𝟙(0,∞)(x)log(d)dλ(x)\displaystyle-\int d\cdot\frac{d\mathbb{P}_{X|(0,\infty)}}{d\lambda}(x)\cdot\mathbbm{1}_{(0,\infty)}(x)\log(d)d\lambda(x) (F.182)
=d⋅ℍ1​(ℙX|(0,∞))−d​log⁡(d)\displaystyle=d\cdot\mathbb{H}_{1}(\mathbb{P}_{X|(0,\infty)})-d\log(d) (F.183)
ℍν​(Z)\displaystyle\mathbb{H}_{\nu}(Z) =d⋅ℍ1​(ℙX|(0,∞))−d​log⁡(d)−(1−d)​log⁡(1−d)\displaystyle=d\cdot\mathbb{H}_{1}(\mathbb{P}_{X|(0,\infty)})-d\log(d)-(1-d)\log(1-d) (F.184)
=d⋅ℍ1​(ℙX|(0,∞))+d​log⁡(1d)+(1−d)​log⁡(1d−1)\displaystyle=d\cdot\mathbb{H}_{1}(\mathbb{P}_{X|(0,\infty)})+d\log\bigg(\frac{1}{d}\bigg)+(1-d)\log\bigg(\frac{1}{d-1}\bigg) (F.185)
ℍν​(Z)\displaystyle\mathbb{H}_{\nu}(Z) =d⁡(Z)⋅ℍ1​(ℙX|(0,∞))+d⁡(Z)​log⁡(1d⁡(Z))+(1−d⁡(Z))​log⁡(1d⁡(Z)−1)=Hd⁡(Z)​(Z).\displaystyle=d(Z)\cdot\mathbb{H}_{1}(\mathbb{P}_{X|(0,\infty)})+d(Z)\log\bigg(\frac{1}{d(Z)}\bigg)+(1-d(Z))\log\bigg(\frac{1}{d(Z)-1}\bigg)=H_{d(Z)}(Z). (F.186)

F.5 Generalization of the Entropy Decomposition of Total Correlation

The total-correlation decomposition is extended to the stated mixed-entropy framework. Marginal entropies alone still do not reveal all joint dependencies.

Equations F.187–F.190
TC(𝐱)=DKL(ℙ𝐱∥∏i=1Dℙ𝐱i)=∫log(d​ℙ𝐱∏i=1Dℙ𝐱i)dℙ𝐱\displaystyle\operatorname{TC}(\mathbf{x})=D_{\operatorname{KL}}\bigg(\mathbb{P}_{\mathbf{x}}\bigg\|\prod_{i=1}^{D}\mathbb{P}_{\mathbf{x}_{i}}\bigg)=\int\log\bigg(\frac{d\mathbb{P}_{\mathbf{x}}}{\prod_{i=1}^{D}\mathbb{P}_{\mathbf{x}_{i}}}\bigg)d\mathbb{P}_{\mathbf{x}} (F.187)
TC⁡(𝐱)=∑i=1Dℍλ​(𝐱i)−ℍλ⊗D​(𝐱)\displaystyle\operatorname{TC}(\mathbf{x})=\sum_{i=1}^{D}\mathbb{H}_{\lambda}(\mathbf{x}_{i})-\mathbb{H}_{\lambda^{\otimes D}}(\mathbf{x}) (F.188)
TC⁡(𝐱)=∑i=1Dℍν​(𝐱i)−ℍν⊗D​(𝐱)\displaystyle\operatorname{TC}(\mathbf{x})=\sum_{i=1}^{D}\mathbb{H}_{\nu}(\mathbf{x}_{i})-\mathbb{H}_{\nu^{\otimes D}}(\mathbf{x}) (F.189)
TC⁡(𝐱)=∑i=1Dℍd⁡(𝐱i)​(𝐱i)−ℍd⁡(𝐱)​(𝐱)\displaystyle\operatorname{TC}(\mathbf{x})=\sum_{i=1}^{D}\mathbb{H}_{d(\mathbf{x}_{i})}(\mathbf{x}_{i})-\mathbb{H}_{d(\mathbf{x})}(\mathbf{x}) (F.190)

Appendix G Hilbert-Schmidt Independence Criterion

The dependence statistic uses kernel comparisons of coordinate pairs. Its normalization and finite-sample implementation determine the reported values; pairwise tests are not a universal certificate of full factorial independence.

Equations G.191–G.192
HSIC⁡(X,Y)=1(B−1)2​Tr⁡(𝐊𝐇𝐋𝐇)\displaystyle\operatorname{HSIC}(X,Y)=\frac{1}{(B-1)^{2}}\operatorname{Tr}(\mathbf{KHLH}) (G.191)
nHSIC⁡(X,Y)=HSIC⁡(X,Y)HSIC⁡(X,X)⋅HSIC⁡(Y,Y)\displaystyle\operatorname{nHSIC}(X,Y)=\frac{\operatorname{HSIC}(X,Y)}{\sqrt{\operatorname{HSIC}(X,X)\cdot\operatorname{HSIC}(Y,Y)}} (G.192)

Appendix H Baseline Designs

The baseline definitions fix which features are rectified and which invariance, contrastive or covariance terms are optimized. These choices are necessary to interpret the sparse-versus-dense comparison.

Equation H.193
RepReLU⁡(z):=ReLU⁡(z).detach⁡()+GeLU⁡(z)−GeLU⁡(z).detach⁡()\displaystyle\operatorname{RepReLU}(z):=\operatorname{ReLU}(z).\operatorname{detach}()+\operatorname{GeLU}(z)-\operatorname{GeLU}(z).\operatorname{detach}() (H.193)

Appendix I Connection to Non-Negative VCReg

The covariance connection requires matching target projections along empirical covariance eigenvectors. It is more specific than asserting exact covariance recovery from any small random set.

Proposition I.1 (Implicit Regularization of Second-Order Statistics).

Let 𝐳∈ℝd\mathbf{z}\in\mathbb{R}^{d} be a neural network feature random vector with covariance matrix Cov⁡[𝐳]=𝚺\operatorname{Cov}[\mathbf{z}]=\mathbf{\Sigma}. We denote the eigendecomposition as 𝚺=𝐔​𝚲​𝐔⊤\mathbf{\Sigma}=\mathbf{U}\mathbf{\Lambda}\mathbf{U}^{\top} with the set of eigenvectors being {𝐮i}i=1d\{\mathbf{u}_{i}\}_{i=1}^{d}. Let 𝐲∼∏i=1dℛ​𝒢​𝒩p​(μ,σ)\mathbf{y}\sim\prod_{i=1}^{d}\mathcal{RGN}_{p}(\mu,\sigma) be the Rectified Generalized Gaussian random vector and define γ:=Var⁡[ℛ​𝒢​𝒩p​(μ,σ)]∈(0,∞)\gamma:=\operatorname{Var}[\mathcal{RGN}_{p}(\mu,\sigma)]\in(0,\infty). If 𝐮i⊤​𝐳=d𝐮i⊤​𝐲\mathbf{u}_{i}^{\top}\mathbf{z}\stackrel{{\scriptstyle d}}{{=}}\mathbf{u}_{i}^{\top}\mathbf{y} for all i∈{1,…,d}i\in\{1,\dots,d\}, then 𝚺=γ⋅𝐈d\mathbf{\Sigma}=\gamma\cdot\mathbf{I}_{d}.

Equations I.194–I.198
Var⁡(𝐮i⊤​𝐲)=𝐮i⊤​(γ​𝐈d)​𝐮i=γ⋅‖𝐮i‖22=γ.\displaystyle\operatorname{Var}(\mathbf{u}_{i}^{\top}\mathbf{y})=\mathbf{u}_{i}^{\top}(\gamma\mathbf{I}_{d})\mathbf{u}_{i}=\gamma\cdot\|\mathbf{u}_{i}\|_{2}^{2}=\gamma. (I.194)
Var⁡(𝐮i⊤​𝐳)=Var⁡(𝐮i⊤​𝐲)=γ∀i.\displaystyle\operatorname{Var}(\mathbf{u}_{i}^{\top}\mathbf{z})=\operatorname{Var}(\mathbf{u}_{i}^{\top}\mathbf{y})=\gamma\hskip 18.49988pt\forall i. (I.195)
Var⁡(𝐮i⊤​𝐳)=𝐮i⊤​𝚺​𝐮i=λi⋅‖𝐮i‖22=λi,\displaystyle\mathrm{Var}(\mathbf{u}_{i}^{\top}\mathbf{z})=\mathbf{u}_{i}^{\top}\mathbf{\Sigma}\mathbf{u}_{i}=\lambda_{i}\cdot\|\mathbf{u}_{i}\|_{2}^{2}=\lambda_{i}, (I.196)
𝚺=𝐔​𝚲​𝐔⊤=𝐔⁡(γ​𝐈d)​𝐔⊤=γ​𝐈d,\displaystyle\mathbf{\Sigma}=\mathbf{U}\mathbf{\Lambda}\mathbf{U}^{\top}=\mathbf{U}(\gamma\mathbf{I}_{d})\mathbf{U}^{\top}=\gamma\mathbf{I}_{d}, (I.197)
‖γ⋅𝐈d−𝐙~⊤​𝐙~‖F2,\displaystyle\|\gamma\cdot\mathbf{I}_{d}-\tilde{\mathbf{Z}}^{\top}\tilde{\mathbf{Z}}\|_{F}^{2}, (I.198)

Appendix J Additional Experimental Results

J.1 Linear Probe over CIFAR-100

Additional CIFAR-100 probes retain separate measurements for representation quality and zero fraction.

J.2 Ablations on Projector Dimensions

Projector-width ablations show how the dimension of the regularized representation affects the result; the encoder representation is evaluated separately.

J.3 Rectified LpJEPA with ViT Backbones

Transformer experiments test whether the recipe transfers beyond convolutional backbones under the stated training settings.

J.4 ImageNet-1K Experiments

ImageNet-1K results extend the scale comparison. Data, architecture and schedule remain part of the performance claim.

Table 2: ImageNet-1K Linear Probe Results after 100 Epochs. We report encoder and projector top-1 accuracy (%). Rectified LpJEPA uses ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) as the target distribution.
Method Encoder Acc1 ↑\uparrow Projector Acc1 ↑\uparrow
VICReg 60.52 46.23
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 57.95 46.07
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) + Eigenvector Proj. 60.63 48.84

J.5 Batch Size Dependency of RDMReg

Batch-size ablations test how well the finite-sample distribution comparison works with different amounts of data per update.

Table 3: Batch Size Dependency of RDMReg on CIFAR-100. We report mean ±\pm standard deviation of encoder and projector top-1 accuracy (%).
Batch Size 24 32 48 64 128 256 512
Enc Acc1 ↑\uparrow 64.88±0.1764.88{\pm}0.17 66.01±0.4466.01{\pm}0.44 67.47±0.1767.47{\pm}0.17 67.59±0.4967.59{\pm}0.49 67.69±0.5567.69{\pm}0.55 68.29±0.3068.29{\pm}0.30 67.88±0.1067.88{\pm}0.10
Proj Acc1 ↑\uparrow 56.19±0.0756.19{\pm}0.07 58.77±0.5958.77{\pm}0.59 61.11±0.2261.11{\pm}0.22 62.24±0.1062.24{\pm}0.10 63.54±0.1063.54{\pm}0.10 64.41±0.2264.41{\pm}0.22 64.16±0.1264.16{\pm}0.12

J.6 Runtime Comparison between SIGReg and RDMReg

Runtime measurements compare the chosen sliced two-sample implementation with SIGReg under a specified hardware and problem-size setup.

Table 4: Runtime Comparison between SIGReg and RDMReg. Both methods are trained for 100 epochs on CIFAR-100.
Method Training Time (min) ↓\downarrow Avg. GPU Util. (%) ↑\uparrow GPU Memory
SIGReg 19.02 46.59 2.65 GB
RDMReg 19.27 45.04 2.63 GB

J.7 Big-O Efficiency Analysis

The asymptotic analysis separates projection computation, sorting and representation dimensions. Big-O notation does not by itself determine the practical crossover in runtime.

Equations J.199–J.201
𝒪⁡(B​D)+𝒪⁡(B​D​P)+𝒪⁡(P​B​log⁡B)+𝒪⁡(B​P),\displaystyle\mathcal{O}(BD)+\mathcal{O}(BDP)+\mathcal{O}(PB\log B)+\mathcal{O}(BP), (J.199)
𝒪⁡(B​D​P+P​B​log⁡B).\displaystyle\mathcal{O}(BDP+PB\log B). (J.200)
𝒪⁡(B​D​P+B​P​K),\displaystyle\mathcal{O}(BDP+BPK), (J.201)
Table 5: Linear Probe Results on CIFAR-100. Acc1 (%) is higher-is-better (↑\uparrow); sparsity is lower-is-better (↓\downarrow). Bold denotes best and underline denotes second-best in each column (ties allowed).
Encoder Acc1 ↑\uparrow Projector Acc1 ↑\uparrow L1 Sparsity ↓\downarrow L0 Sparsity ↓\downarrow
Rectified LpJEPA ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 66.29¯\underline{66.29} 62.1562.15 0.37730.3773 0.73570.7357
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 65.9765.97 62.2262.22 0.30190.3019 0.64740.6474
ℛ​𝒢​𝒩0.75​(0,σGN)\mathcal{RGN}_{0.75}(0,\sigma_{\operatorname{GN}}) 65.7865.78 62.80\mathbf{62.80} 0.25830.2583 0.60990.6099
ℛ​𝒢​𝒩0.50​(0,σGN)\mathcal{RGN}_{0.50}(0,\sigma_{\operatorname{GN}}) 66.1066.10 62.74¯\underline{62.74} 0.19960.1996 0.57270.5727
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 64.7564.75 59.0859.08 0.02360.0236 0.0489¯\underline{0.0489}
Sparse Baselines NCL-ReLU 66.2366.23 61.8861.88 0.0228¯\underline{0.0228} 0.05030.0503
NVICReg-ReLU 63.7663.76 58.8258.82 0.74150.7415 0.89350.8935
NCL-RepReLU 66.32 61.4061.40 0.0202 0.0426
NVICReg-RepReLU 63.8363.83 58.5358.53 0.15510.1551 0.26570.2657
Dense Baselines SimCLR 66.0066.00 61.9561.95 0.63640.6364 1.00001.0000
VICReg 63.7863.78 58.8258.82 0.86600.8660 1.00001.0000
LeJEPA 65.6565.65 62.6962.69 0.63790.6379 1.00001.0000
Original figure
(a) The Pareto frontier of performance against ℓ1\ell_{1} sparsity
Refer to caption
(b) Correlation between ℓ1\ell_{1} and ℓ0\ell_{0} Sparsity Metrics
Original figure
(c) The Effect of Number of Random Projections
Figure 13: Additional results on the sparsity-performance tradeoffs, the correlation between different sparsity metrics, and the effect of numbers of random projections on performance. (a) We present another version of Figure 2(c) where the sparsity metric is switched from ℓ0\ell_{0} to ℓ1\ell_{1}. Again, we observe the same Pareto frontier with a sharp drop in performance under extreme sparsity. (b) Across different backbones, Rectified LpJEPAs with the target distribution being the Rectified Laplace distributions learn sparser representations as we decrease the mean shift value μ\mu. Specifically, we observe that the ℓ0\ell_{0} and ℓ1\ell_{1} metrics are quite correlated. Thus both metrics are effective in measuring sparsity. (c) We test Rectified LpJEPA models with batch size B=128B=128 and varying feature dimension DD as long as numbers of projections. As we increase the dimensions DD, we observe that the number of random projections required for good performance do not grow and are small relative to DD. Hence Rectified LpJEPA maintains stable sampling efficiency as the feature dimension grows in these experiments.

J.8 Additional Results on Eigenvectors

Eigenvector projection experiments investigate faster covariance alignment. They supplement rather than replace the assumptions of the theoretical connection.

J.9 Additional Results on Transfer Sparsity

Transfer datasets produce different sparsity profiles. These are exploratory signals for distribution shift, not a complete detection evaluation.

Original figure
(a) Variance Loss when μ=−1\mu=-1
Original figure
(b) Covariance Loss when μ=−1\mu=-1
Original figure
(c) Accuracy when μ=−1\mu=-1
Original figure
(d) Variance Loss when μ=0\mu=0
Original figure
(e) Covariance Loss when μ=0\mu=0
Original figure
(f) Accuracy when μ=0\mu=0
Original figure
(g) Variance Loss when μ=1\mu=1
Original figure
(h) Covariance Loss when μ=1\mu=1
Original figure
(i) Accuracy when μ=1\mu=1
Figure 14: Incorporating eigenvectors into random projections accelerates implicit VCReg loss minimization and speed-up convergence. We pretrain Rectified LpJEPA over CIFAR-100 with target distributions ℛ​𝒢​𝒩1​(μ,σGN)\mathcal{RGN}_{1}(\mu,\sigma_{\operatorname{GN}}) where the mean shift value μ∈{−1,0,1}\mu\in\{-1,0,1\}. We consider three settings of selecting the projection vectors {ci}i=1N\{c_{i}\}_{i=1}^{N} where we set N=8192N=8192. We denote the setting as ”Rand” if all 𝐜i\mathbf{c}_{i} are uniformly sampled from the unit ℓ2\ell_{2} sphere. Since in our setting the batch size is always smaller than the feature dimension, i.e. B<DB<D, we call the setting ”Rand + Full Eig” if we select the top-BB eigenvectors and mix them with N−BN-B random projection vectors. We also consider ”Rand + Bottom Eig” by sampling the bottom half B/2B/2 eigenvectors and mixing with N−B/2N-B/2 random projections. (a) (d) (g) We evaluate the variance loss between the three settings across varying μ\mu. Incorporating all eigenvectors puts overly strong constraints, whereas penalizing the bottom half eigenvectors gives us good performances. (b) (e) (h) the covariance losses are evaluated during training and plotted for different projection vector settings across μ\mu. Regularizing all top-BB eigenvector projections leads to significant implicit covariance loss minimization, where the covariance loss is the average of the off-diagonal of the empirical covariance matrix. (c) (f) (i) We report the projector accuracy against epoch for different projection settings. Using eigenvectors leads to both faster convergence and ultimately better performance.
Table 6: 1-shot linear probe accuracy (%) using encoder features. All results are in the 1-shot setting. Avg. denotes the mean across datasets.
model DTD cifar10 cifar100 flowers food pets avg.
Non-negative VICReg 11.86 65.62 24.95 5.09 24.82 29.74 27.01
Non-negative SimCLR 11.17 67.67 24.23 5.59 24.44 19.71 25.47
Our methods
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 9.89 68.31 26.27 4.21 25.98 17.66 25.39
ℛ​𝒢​𝒩1.0​(−1,σGN)\mathcal{RGN}_{1.0}(-1,\sigma_{\operatorname{GN}}) 9.47 67.19 23.58 4.85 24.93 16.60 24.44
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 12.66 66.36 23.91 10.18 24.88 25.18 27.20
ℛ​𝒢​𝒩1.0​(−3,σGN)\mathcal{RGN}_{1.0}(-3,\sigma_{\operatorname{GN}}) 9.31 50.39 8.35 6.13 10.63 21.72 17.76
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 14.04 69.47 24.09 4.86 25.68 24.34 27.08
ℛ​𝒢​𝒩2.0​(−1,σGN)\mathcal{RGN}_{2.0}(-1,\sigma_{\operatorname{GN}}) 12.82 65.97 24.12 4.91 24.44 20.20 25.41
ℛ​𝒢​𝒩2.0​(−2,σGN)\mathcal{RGN}_{2.0}(-2,\sigma_{\operatorname{GN}}) 13.88 59.62 15.88 7.84 16.21 24.97 23.07
ℛ​𝒢​𝒩2.0​(−3,σGN)\mathcal{RGN}_{2.0}(-3,\sigma_{\operatorname{GN}}) 11.06 55.71 11.42 8.18 12.92 12.13 18.57
Dense baselines
VICReg 10.85 63.98 21.52 6.23 25.29 23.33 25.20
SimCLR 12.82 66.90 23.93 10.60 24.99 24.12 27.23
LeJEPA 15.85 68.07 24.57 5.79 23.72 24.34 27.06
Table 7: 1-shot linear probe accuracy (%) using projector features. All results are in the 1-shot setting. Avg. denotes the mean across datasets.
model DTD cifar10 cifar100 flowers food pets avg.
Non-negative VICReg 8.62 33.47 7.51 3.25 8.78 17.28 13.15
Non-negative SimCLR 6.70 41.71 9.24 2.91 9.17 15.37 14.18
Our methods
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 6.81 48.96 11.46 2.03 12.09 16.38 16.29
ℛ​𝒢​𝒩1.0​(−1,σGN)\mathcal{RGN}_{1.0}(-1,\sigma_{\operatorname{GN}}) 7.82 47.14 11.20 2.75 11.43 14.94 15.88
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 10.37 38.36 9.13 5.56 9.53 20.93 15.65
ℛ​𝒢​𝒩1.0​(−3,σGN)\mathcal{RGN}_{1.0}(-3,\sigma_{\operatorname{GN}}) 5.69 32.25 5.16 2.70 5.76 19.02 11.76
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 10.59 47.74 10.61 2.70 11.46 20.50 17.27
ℛ​𝒢​𝒩2.0​(−1,σGN)\mathcal{RGN}_{2.0}(-1,\sigma_{\operatorname{GN}}) 9.84 46.97 12.33 3.07 11.70 19.38 17.21
ℛ​𝒢​𝒩2.0​(−2,σGN)\mathcal{RGN}_{2.0}(-2,\sigma_{\operatorname{GN}}) 9.57 35.08 6.59 4.49 7.41 20.69 13.97
ℛ​𝒢​𝒩2.0​(−3,σGN)\mathcal{RGN}_{2.0}(-3,\sigma_{\operatorname{GN}}) 9.20 18.36 2.64 2.33 3.64 7.14 7.22
Dense baselines
VICReg 8.09 39.35 6.74 3.04 9.34 19.49 14.34
SimCLR 12.39 48.05 11.52 7.24 14.16 21.34 19.12
LeJEPA 8.30 48.17 11.27 4.47 11.84 18.32 17.06
Table 8: 10-shot linear probe accuracy (%) using encoder features. All results are in the 10-shot setting. Avg. denotes the mean across datasets.
model DTD cifar10 cifar100 flowers food pets avg.
Non-negative VICReg 37.23 77.88 47.32 31.16 48.33 55.49 49.57
Non-negative SimCLR 40.11 79.11 50.35 23.96 50.60 50.37 49.08
Our methods
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 41.91 79.58 49.67 24.93 49.97 55.63 50.28
ℛ​𝒢​𝒩1.0​(−1,σGN)\mathcal{RGN}_{1.0}(-1,\sigma_{\operatorname{GN}}) 38.19 78.98 48.76 32.87 48.51 55.41 50.45
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 40.32 79.25 45.86 22.72 46.51 56.91 48.60
ℛ​𝒢​𝒩1.0​(−3,σGN)\mathcal{RGN}_{1.0}(-3,\sigma_{\operatorname{GN}}) 19.63 66.93 24.45 8.25 26.12 32.76 29.69
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 40.90 80.15 50.69 29.76 50.34 53.07 50.82
ℛ​𝒢​𝒩2.0​(−1,σGN)\mathcal{RGN}_{2.0}(-1,\sigma_{\operatorname{GN}}) 39.63 79.00 47.51 26.85 47.39 55.60 49.33
ℛ​𝒢​𝒩2.0​(−2,σGN)\mathcal{RGN}_{2.0}(-2,\sigma_{\operatorname{GN}}) 30.80 73.88 34.61 12.03 35.56 44.92 38.63
ℛ​𝒢​𝒩2.0​(−3,σGN)\mathcal{RGN}_{2.0}(-3,\sigma_{\operatorname{GN}}) 15.27 68.30 24.84 7.64 29.79 26.63 28.74
Dense baselines
VICReg 38.35 76.25 45.63 26.52 48.30 52.19 47.88
SimCLR 41.70 77.88 46.87 31.66 49.27 49.74 49.52
LeJEPA 38.67 79.06 49.02 30.18 49.34 53.88 50.03
Table 9: 10-shot linear probe accuracy (%) using projector features. All results are in the 10-shot setting. Avg. denotes the mean across datasets.
model DTD cifar10 cifar100 flowers food pets avg.
Non-negative VICReg 22.50 43.24 10.56 12.86 12.65 32.92 22.46
Non-negative SimCLR 23.09 48.38 17.73 8.72 14.97 32.87 24.29
Our methods
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 24.47 58.06 22.40 9.97 19.73 40.17 29.13
ℛ​𝒢​𝒩1.0​(−1,σGN)\mathcal{RGN}_{1.0}(-1,\sigma_{\operatorname{GN}}) 25.90 57.61 22.39 11.40 21.24 38.18 29.45
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 23.83 44.69 15.32 9.19 14.65 33.31 23.50
ℛ​𝒢​𝒩1.0​(−3,σGN)\mathcal{RGN}_{1.0}(-3,\sigma_{\operatorname{GN}}) 18.19 36.39 9.03 7.46 8.67 26.17 17.65
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 22.82 57.93 21.26 12.07 19.03 36.90 28.33
ℛ​𝒢​𝒩2.0​(−1,σGN)\mathcal{RGN}_{2.0}(-1,\sigma_{\operatorname{GN}}) 27.39 57.32 24.07 13.06 21.54 40.01 30.57
ℛ​𝒢​𝒩2.0​(−2,σGN)\mathcal{RGN}_{2.0}(-2,\sigma_{\operatorname{GN}}) 22.23 40.83 12.58 8.93 12.01 29.38 20.99
ℛ​𝒢​𝒩2.0​(−3,σGN)\mathcal{RGN}_{2.0}(-3,\sigma_{\operatorname{GN}}) 9.89 23.81 5.03 6.02 6.15 10.08 10.16
Dense baselines
VICReg 23.09 41.20 10.24 10.60 13.55 32.49 21.86
SimCLR 33.09 59.56 25.91 15.68 28.61 42.00 34.14
LeJEPA 24.95 55.76 19.55 10.72 17.17 38.98 27.85
Table 10: All-shot linear probe accuracy (%) using encoder features. All-shot uses the full training set. Avg. denotes the mean across datasets.
model DTD cifar10 cifar100 flowers food pets avg.
Non-negative VICReg 63.56 82.68 60.40 82.55 60.39 78.63 71.37
Non-negative SimCLR 64.68 84.41 62.95 84.97 63.32 76.56 72.82
Our methods
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 65.05 84.50 62.73 83.75 62.65 78.00 72.78
ℛ​𝒢​𝒩1.0​(−1,σGN)\mathcal{RGN}_{1.0}(-1,\sigma_{\operatorname{GN}}) 64.68 83.97 60.75 81.77 60.25 77.68 71.52
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 63.67 85.31 58.11 81.62 58.39 77.38 70.75
ℛ​𝒢​𝒩1.0​(−3,σGN)\mathcal{RGN}_{1.0}(-3,\sigma_{\operatorname{GN}}) 49.04 79.11 43.94 44.72 46.22 61.30 54.06
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 64.52 85.06 64.51 84.09 62.35 78.25 73.13
ℛ​𝒢​𝒩2.0​(−1,σGN)\mathcal{RGN}_{2.0}(-1,\sigma_{\operatorname{GN}}) 64.26 84.21 59.90 81.59 59.47 77.65 71.18
ℛ​𝒢​𝒩2.0​(−2,σGN)\mathcal{RGN}_{2.0}(-2,\sigma_{\operatorname{GN}}) 57.87 82.19 49.81 69.38 51.90 68.93 63.35
ℛ​𝒢​𝒩2.0​(−3,σGN)\mathcal{RGN}_{2.0}(-3,\sigma_{\operatorname{GN}}) 53.35 78.95 45.32 57.47 46.32 52.22 55.61
Dense baselines
VICReg 62.77 81.47 59.23 80.96 60.44 77.11 70.33
SimCLR 64.73 82.49 60.10 80.47 61.18 71.44 70.07
LeJEPA 63.19 83.54 62.38 83.07 61.14 78.30 71.94
Table 11: All-shot linear probe accuracy (%) using projector features. All-shot uses the full training set. Avg. denotes the mean across datasets.
model DTD cifar10 cifar100 flowers food pets avg.
Non-negative VICReg 35.80 47.70 14.90 32.04 15.74 44.84 31.83
Non-negative SimCLR 36.86 50.24 21.92 25.57 17.70 47.02 33.22
Our methods
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 41.49 63.14 29.46 39.96 26.70 52.55 42.22
ℛ​𝒢​𝒩1.0​(−1,σGN)\mathcal{RGN}_{1.0}(-1,\sigma_{\operatorname{GN}}) 42.82 63.05 32.96 39.68 28.98 55.08 43.76
ℛ​𝒢​𝒩1.0​(−2,σGN)\mathcal{RGN}_{1.0}(-2,\sigma_{\operatorname{GN}}) 39.84 48.69 19.47 29.65 18.21 44.51 33.39
ℛ​𝒢​𝒩1.0​(−3,σGN)\mathcal{RGN}_{1.0}(-3,\sigma_{\operatorname{GN}}) 28.72 37.47 11.13 12.65 9.61 36.09 22.61
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 41.81 62.82 29.31 37.32 24.80 53.18 41.54
ℛ​𝒢​𝒩2.0​(−1,σGN)\mathcal{RGN}_{2.0}(-1,\sigma_{\operatorname{GN}}) 45.00 63.85 34.13 42.72 30.30 56.09 45.35
ℛ​𝒢​𝒩2.0​(−2,σGN)\mathcal{RGN}_{2.0}(-2,\sigma_{\operatorname{GN}}) 34.52 43.39 15.19 23.34 14.44 40.39 28.55
ℛ​𝒢​𝒩2.0​(−3,σGN)\mathcal{RGN}_{2.0}(-3,\sigma_{\operatorname{GN}}) 21.38 24.92 6.58 7.94 7.20 16.63 14.11
Dense baselines
VICReg 37.55 44.84 13.37 34.23 17.03 43.45 31.75
SimCLR 51.65 63.71 35.10 45.73 36.06 57.78 48.34
LeJEPA 40.05 56.81 23.42 43.31 20.70 51.19 39.25
Table 12: Projector Dimension Ablation on ImageNet-100. For each method and projector dimension, we report the best linear probe accuracy (%) over learning rates {0.3,0.03}\{0.3,0.03\}. Encoder and projector accuracies are measured using frozen features. Bold indicates the best value within each projector-dimension block.
Method Encoder Acc1 ↑\uparrow Projector Acc1 ↑\uparrow
Projector Dim. = 512
VICReg 63.72 57.80
LeJEPA 65.53 59.18
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 67.56 61.34
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 68.31 61.74
Projector Dim. = 2048
VICReg 68.73 61.81
LeJEPA 67.18 60.12
ℛ​𝒢​𝒩1.0​(0,σGN)\mathcal{RGN}_{1.0}(0,\sigma_{\operatorname{GN}}) 69.33 64.90
ℛ​𝒢​𝒩2.0​(0,σGN)\mathcal{RGN}_{2.0}(0,\sigma_{\operatorname{GN}}) 69.54 64.85

Appendix K Qualitative Analysis of Rectified LpJEPA

K.1 k -Nearest Neighbors Visualizations

Nearest-neighbor examples inspect which images share learned sparse features. They are qualitative checks of representation behavior.

K.2 Visual Attribution Maps

Attribution visualizations show which image regions influence selected responses. Such maps suggest useful structure without uniquely identifying a causal semantic feature.

Appendix L Implementation Details

L.1 Pretraining data and setup

The implementation appendix records pretraining datasets and the training/evaluation split used by each experiment.

L.2 Architecture

Architectural settings identify encoder, projection head and rectification placement, which determine which representation receives the distribution loss.

L.3 Data augmentation

The augmentation recipe defines the related views and therefore the information encouraged to remain consistent.

L.4 Optimization

Optimization settings fix the learning rate, schedule and related training choices for reproducing the results.

L.5 Distribution matching objective

The distribution-matching recipe specifies target sampling, projection count and empirical comparison, making finite-sample approximations explicit.

L.6 Compute and runtime

Compute and runtime are reported for the stated experiment sizes and hardware; they should accompany efficiency comparisons.

L.7 Transfer evaluation protocol

Few-shot and full-shot transfer protocols define how labels and frozen or adapted features are used.

L.8 Reproducibility.

The reproducibility notes point to the code and settings needed to reconstruct the reported experiments.

L.9 Continuous mapping theorem evaluation (post-hoc ReLU probes).

The post-hoc ReLU protocol tests a different question from training with rectification. It keeps that distinction explicit in the comparisons.

L.10 Vision Transformer (ViT) experiments

The final settings specify the Transformer-backbone experiments, preventing an architecture change from being mistaken for an objective-only ablation.

Table 13: ℛ​𝒢​𝒩1.0​(μ,σGN)\mathcal{RGN}_{1.0}(\mu,\sigma_{\operatorname{GN}}) Mean-Shift Sweep (ViT) with Baselines. We report encoder Acc1 (val_acc1), projector Acc1 (val_proj_acc1), and sparsity metrics. Bold indicates best in a column; underline indicates second best. For sparsity columns, lower is better (more sparse).
Method Enc Acc1 ↑\uparrow Proj Acc1 ↑\uparrow ℓ1\ell_{1} Sparsity ↓\downarrow ℓ0\ell_{0} Sparsity ↓\downarrow
Ours: ℛ​𝒢​𝒩1.0​(μ,σGN)\mathcal{RGN}_{1.0}(\mu,\sigma_{\operatorname{GN}}) (Mean Shift Value, MSV)
ℛ​𝒢​𝒩1.0​(1.0,σGN)\mathcal{RGN}_{1.0}(1.0,\sigma_{\operatorname{GN}}) 74.34 65.60 0.6459 0.9359
ℛ​𝒢​𝒩1.0​(0.5,σGN)\mathcal{RGN}_{1.0}(0.5,\sigma_{\operatorname{GN}}) 74.58 66.42 0.4768 0.8825
ℛ​𝒢​𝒩1.0​(0.0,σGN)\mathcal{RGN}_{1.0}(0.0,\sigma_{\operatorname{GN}}) 75.44 67.16 0.2730 0.7721
ℛ​𝒢​𝒩1.0​(−0.5,σGN)\mathcal{RGN}_{1.0}(-0.5,\sigma_{\operatorname{GN}}) 74.80 66.86 0.1407 0.5526
ℛ​𝒢​𝒩1.0​(−1.0,σGN)\mathcal{RGN}_{1.0}(-1.0,\sigma_{\operatorname{GN}}) 74.18 65.14 0.0737 0.3067
ℛ​𝒢​𝒩1.0​(−1.5,σGN)\mathcal{RGN}_{1.0}(-1.5,\sigma_{\operatorname{GN}}) 74.88 63.70 0.0390 0.1227
ℛ​𝒢​𝒩1.0​(−2.0,σGN)\mathcal{RGN}_{1.0}(-2.0,\sigma_{\operatorname{GN}}) 73.54 60.70 0.0238 0.0523
ℛ​𝒢​𝒩1.0​(−2.5,σGN)\mathcal{RGN}_{1.0}(-2.5,\sigma_{\operatorname{GN}}) 72.06 57.96 0.0188 0.0357
ℛ​𝒢​𝒩1.0​(−3.0,σGN)\mathcal{RGN}_{1.0}(-3.0,\sigma_{\operatorname{GN}}) 71.64 57.46 0.0132 0.0220
Baselines (Dense)
LeJEPA 65.36 59.12 0.6369 1.0000
VICReg 72.06 63.56 0.7877 1.0000
SimCLR 74.18 66.86 0.6663 1.0000
Baselines (Sparse / NonNeg)
NonNeg-VICReg 71.64 65.42 0.5075 0.7066
NonNeg-SimCLR 74.48 63.76 0.0016 0.0023
Refer to caption
Figure 15: Nearest neighbors in feature space (ImageNet synset; unambiguous class). Top-kk cosine nearest neighbors in the projector space for a query labeled as pirate ship. Both dense and sparse methods retrieve pirate ships consistently, illustrating that even at high sparsity our models can preserve semantic consistency when the query is unambiguous.
Refer to caption
Figure 16: Nearest neighbors in feature space (ImageNet synset; full scene). Top-kk cosine nearest neighbors in the projector space for a query labeled as tabby cat (n02123045) that contains both the cat and a salient laptop/desk context. Dense methods (e.g., SimCLR) can return a mixture of cat and laptop/desk neighbors. In contrast, highly sparse ℛ​𝒢​𝒩1.0​(μ,σGN)\mathcal{RGN}_{1.0}(\mu,\sigma_{\operatorname{GN}}) variants tend to commit to a single factor: at MSV=−2=-2 neighbors are predominantly tabby cats, while at MSV=−3=-3 neighbors flip to predominantly laptop/desk images.
Refer to caption
Figure 17: Nearest neighbors in feature space (probe crop). Top-kk cosine nearest neighbors in the projector space for a zoomed-in query that isolates the cat from Figure 16 by removing the competing laptop/desk cues. In this less ambiguous setting, neighbors remain tabby cats across both dense and highly sparse methods, including the most sparse ℛ​𝒢​𝒩1.0​(μ,σGN)\mathcal{RGN}_{1.0}(\mu,\sigma_{\operatorname{GN}}) variants.
Refer to caption
Figure 18: Representation-focused attribution across methods. Grad-CAM-style attribution maps computed on the projector representation for two views of the same scene (a tabby cat lying on a laptop). Rows compare dense baselines (SimCLR, VICReg, LeJEPA), sparse baselines (RepReLU variants), and our ℛ​𝒢​𝒩p​(μ,σGN)\mathcal{RGN}_{p}(\mu,\sigma_{\operatorname{GN}}) family (where p=1.0p=1.0 corresponds to Laplace and μ\mu is the mean-shift value, MSV) at increasing mean-shift values, which induce increasing sparsity.
Refer to caption
Figure 19: Distribution of representation sparsity in the transfer setting. Violin plots showing the distribution of output-feature ℓ1\ell_{1} sparsity for correctly (green) and incorrectly (red) classified samples across datasets and methods. All models are pretrained on ImageNet-100 and evaluated using a full-shot linear-probe transfer setup, where a linear classifier is trained on frozen representations using 100%100\% of each downstream dataset. Sparsity is computed per sample from the frozen output features.

At a glance

Intuition. A dense Gaussian feature cloud almost never contains exact zeros. Rectifying a feature, with ReLU, maps negative values to zero and makes a sparse code possible. For a symmetric zero-centered target, about half the coordinates are active; shifting it toward negative values makes fewer active. The question is how to learn those statistics without losing information needed by a task.

Rectified LpJEPA aligns paired views and matches their rectified embeddings to a controllable sparse target. Its main distinction from LeJEPA is the target distribution and the resulting two-sample projection test. Experiments evaluate sparsity together with accuracy, dependence and transfer.

Concept demonstration

Open image ↗