At a glance
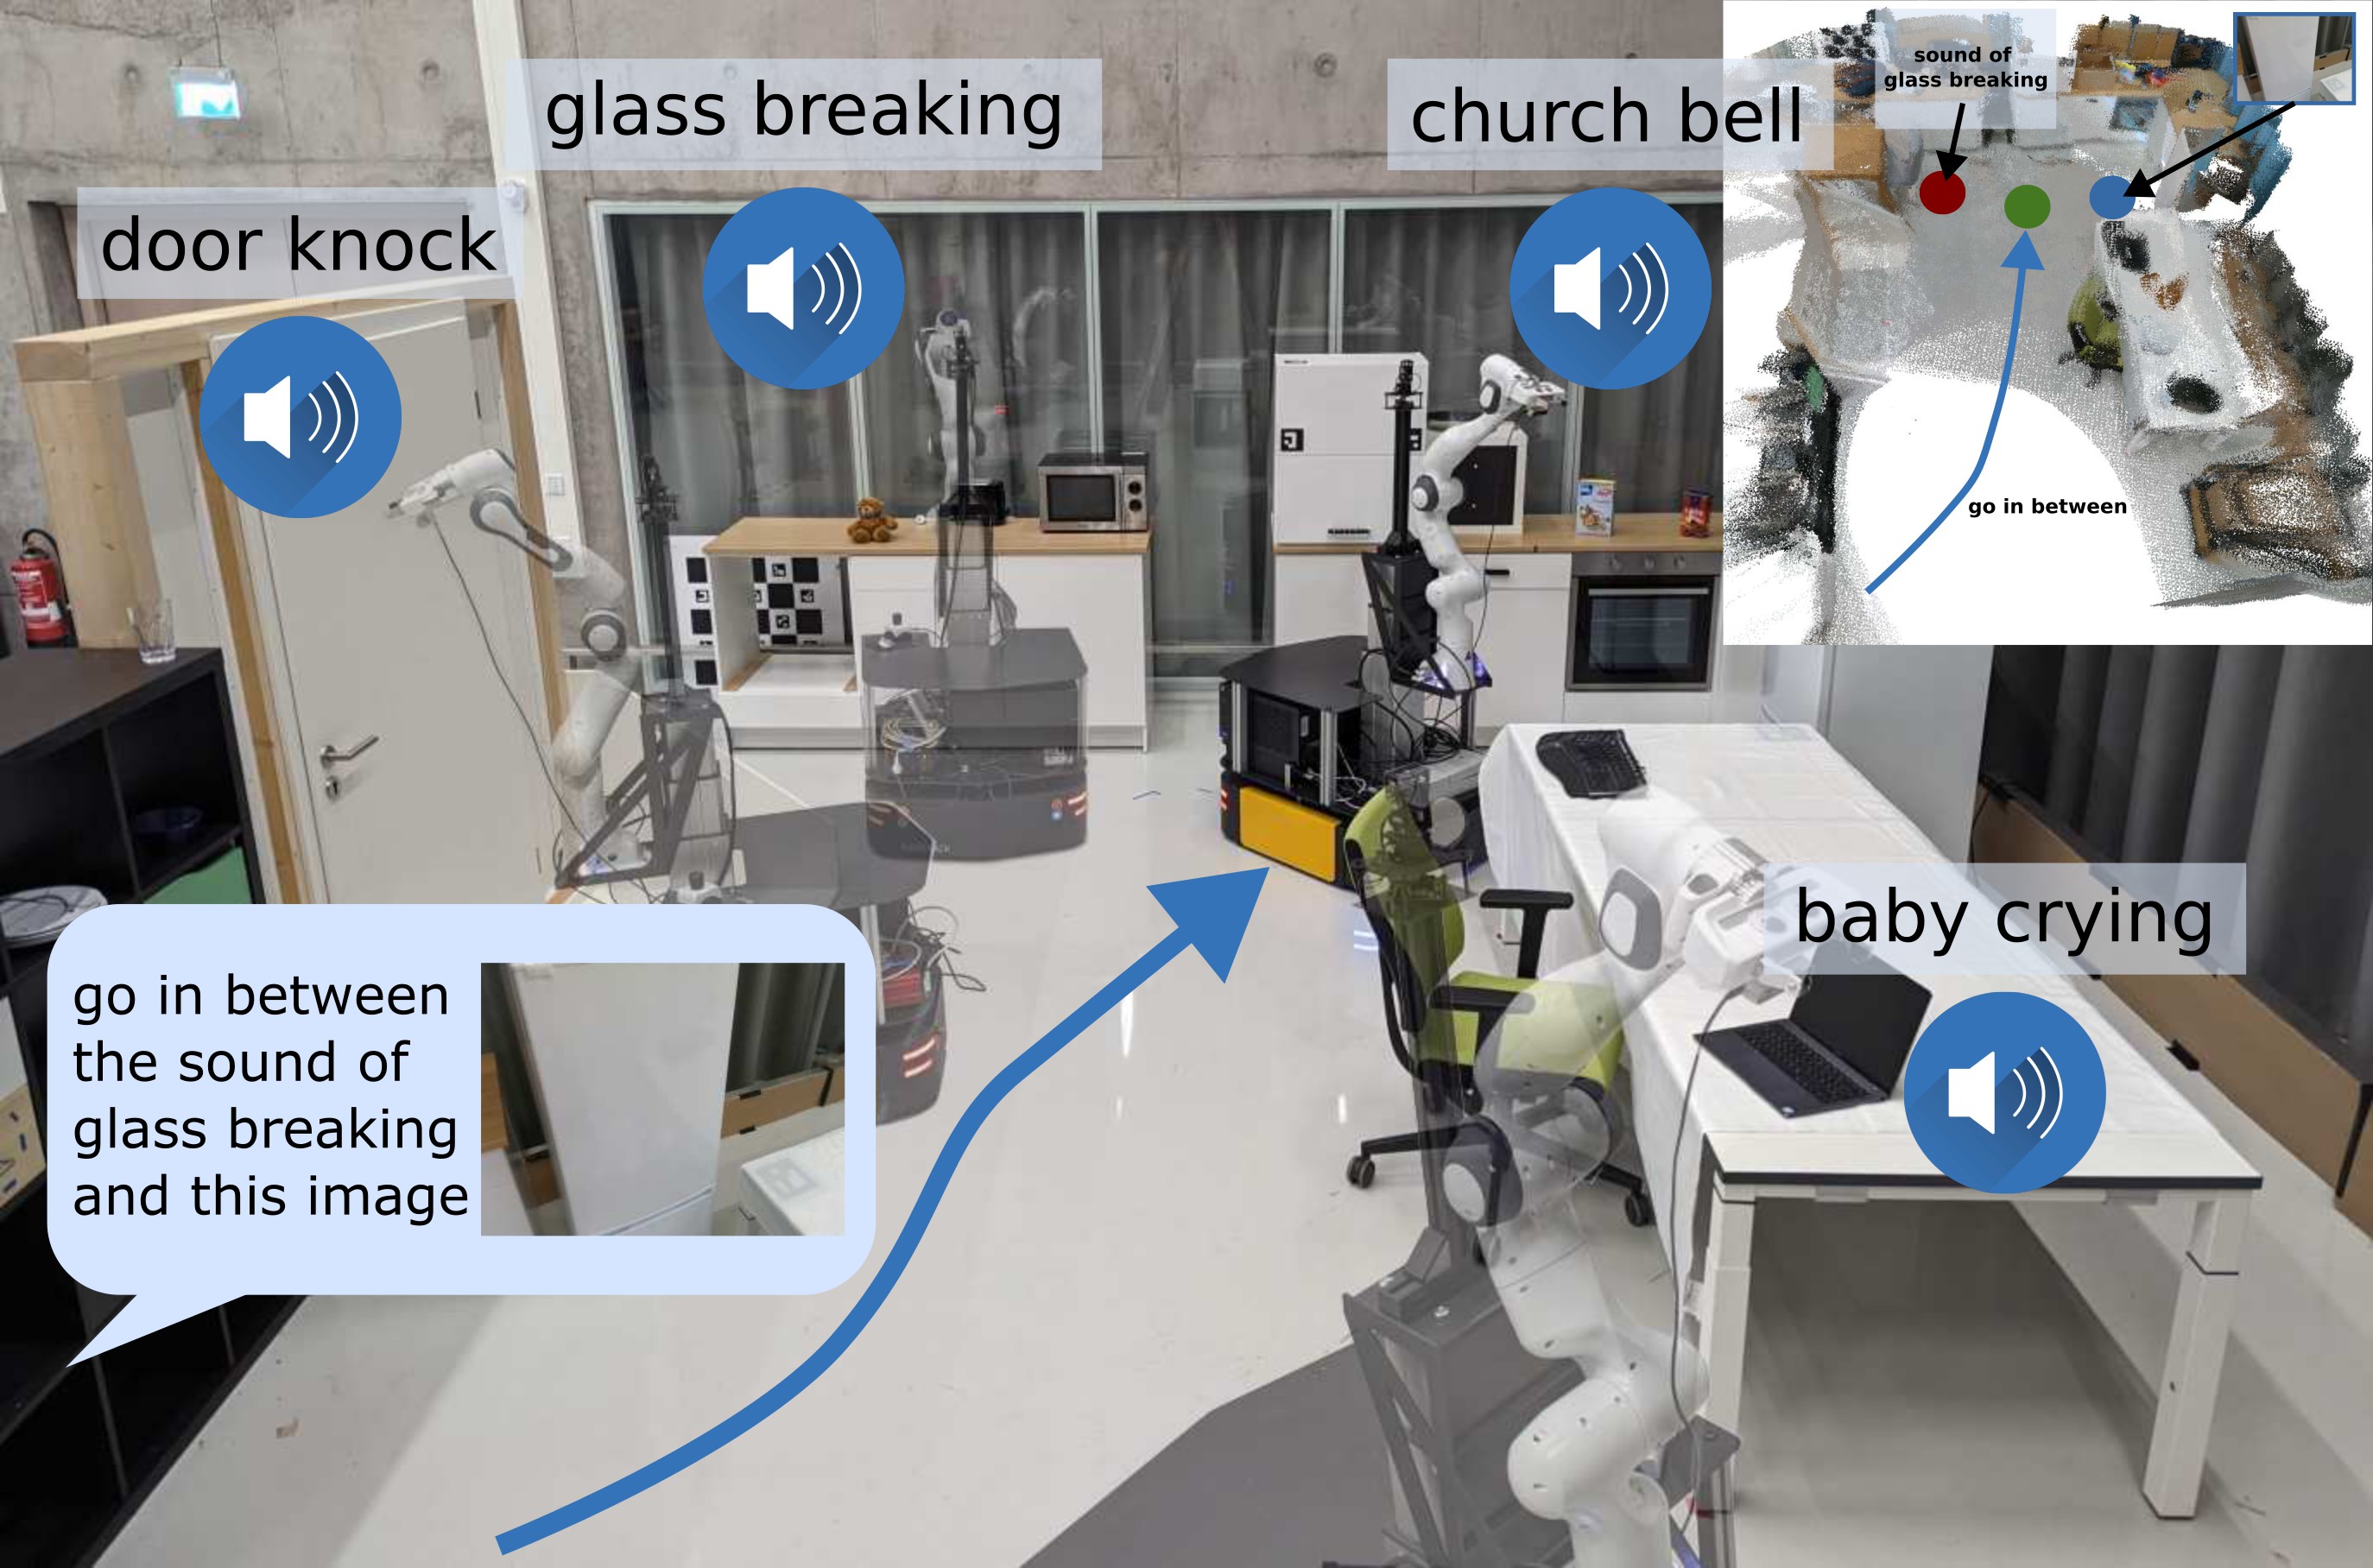
The framework stores pretrained visual, language, and audio features at mapped spatial locations. VLMaps support open-vocabulary object and spatial-goal navigation; AVLMaps add image localization, region recognition, and remembered audio, combining their spatial scores to resolve ambiguous goals. Language models generate calls to a fixed navigation library. Experiments demonstrate navigation and tabletop goal reaching without task-specific model fine-tuning, but require prior mapping and do not localize live sound sources.
1 Introduction
The central idea is persistent spatial memory: foundation-model descriptors become useful for navigation when attached to geometry rather than used only to score the current image. VLMaps attach visual-language features to a reconstructed map; AVLMaps add several complementary localization modules and expose them through a common heatmap interface. The same representation can support different obstacle definitions for different robot bodies.
This journal-style extension combines the earlier visual and audio-visual mapping work, tests alternative pretrained models, and adds tabletop reaching. “Zero-shot” refers to using the pretrained models without navigation-specific fine-tuning; it does not mean that the system operates without exploration, pose estimates, manually specified APIs, or prompting examples.
Related source: the original VLMaps paper.
2 Related Work
Earlier semantic maps often use fixed labels, while open-vocabulary visual maps inherit broader concepts from pretrained models. Language-navigation systems still vary in whether they learn direct actions or retrieve landmarks from maps. Audio-navigation research commonly follows an active sound without recognizing its semantic category. AVLMaps instead stores audio semantics at past observation poses and combines them with visual concepts. Its distinction from audio queries into a visual-only map is that audio observations themselves become part of the persistent representation.
3 Method
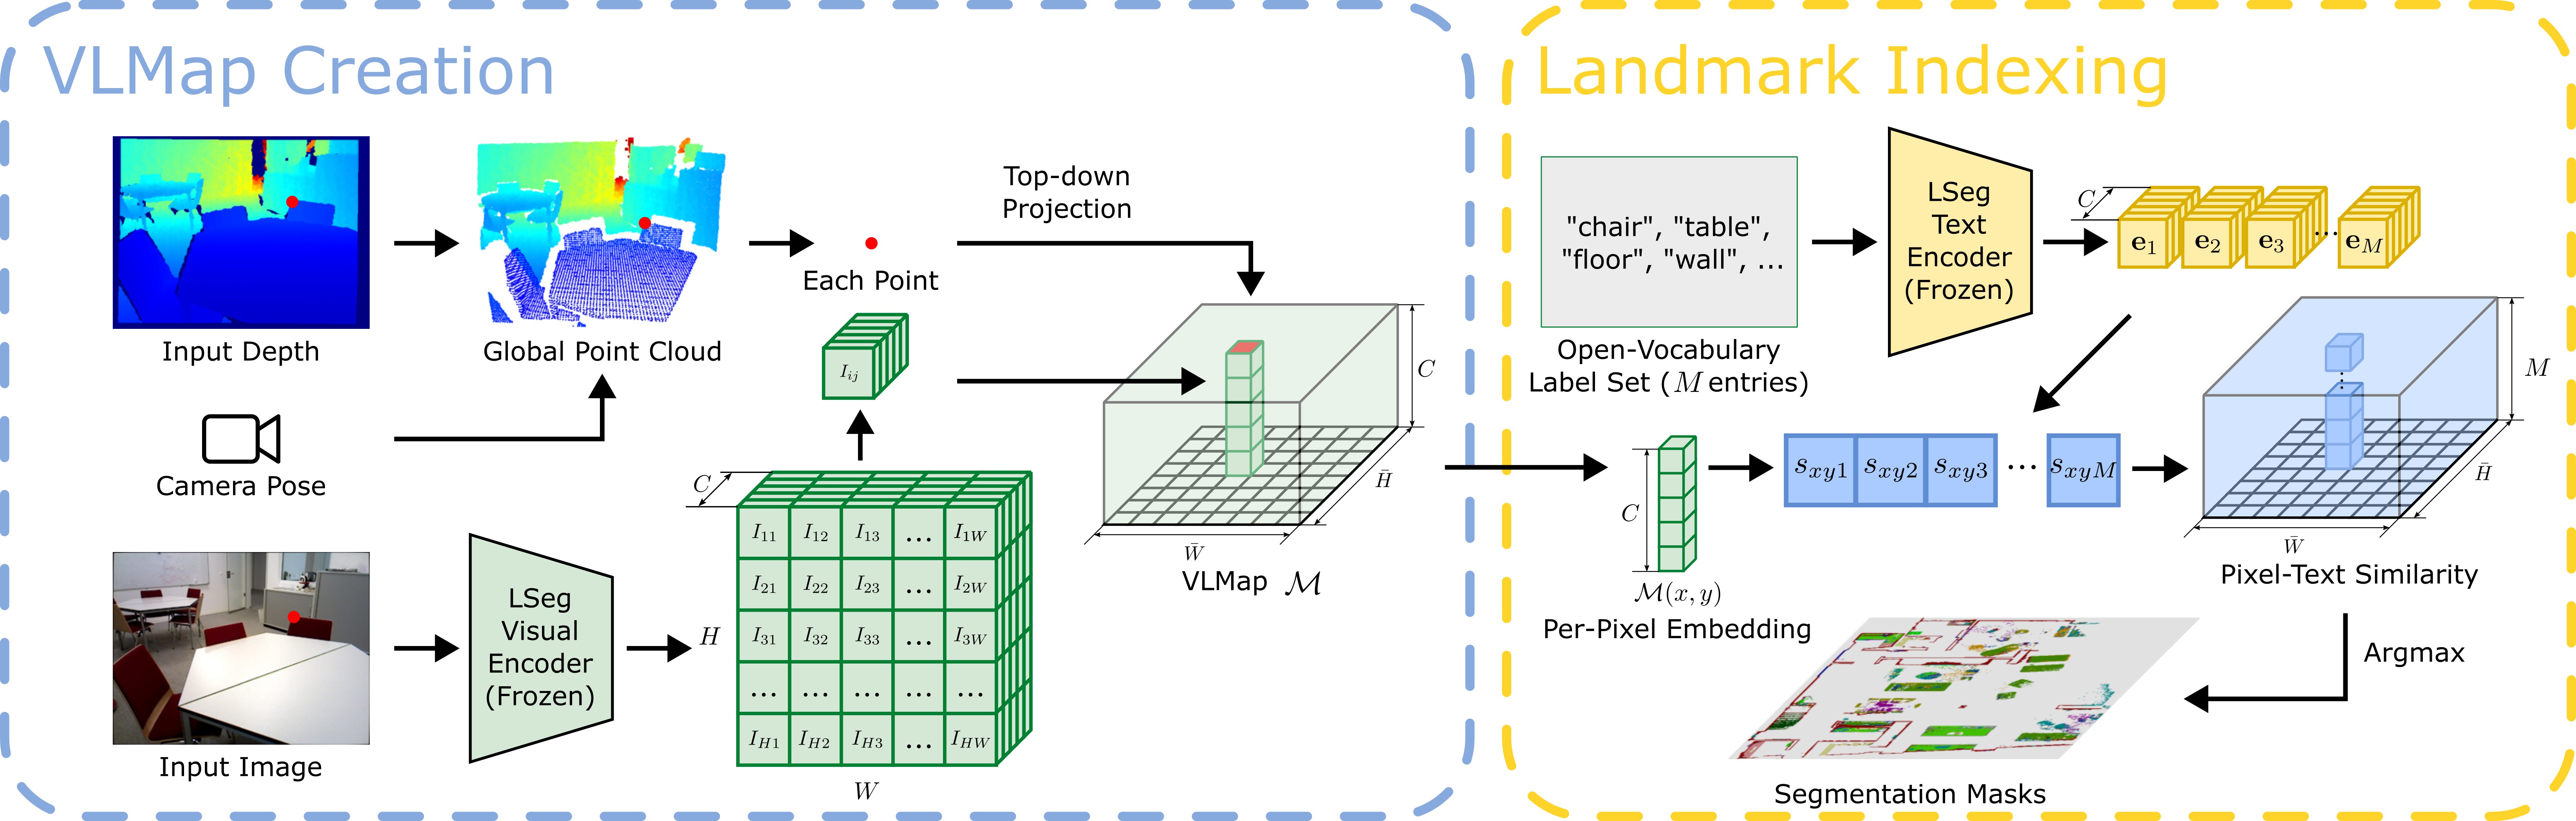
The method progresses from a visual-language map to a modular multimodal spatial memory. Geometry supports explicit spatial offsets and body-specific planning; separate image, object, region, and audio modules produce comparable spatial heatmaps. A language model selects and composes supplied operations rather than learning a new low-level controller.
3.1 Building a Visual-Language Map
Registered depth and camera poses back-project pixel features into a common frame. LSeg produces dense descriptors in CLIP space; descriptors from multiple observations are averaged at each map location. The initial VLMap formulation projects 3D points onto a top-down grid, so different heights can contribute to the same cell. AVLMaps later retains full 3D voxels. Reliable odometry and RGB-depth registration are prerequisites, and averaging does not itself handle moving objects.
Equation 1
| (1) |
3.2 Localizing Open-Vocabulary Landmarks
User-specified category descriptions are encoded with the CLIP text encoder and compared with stored map features. Each cell receives the highest-scoring category among that query list, producing open-vocabulary segmentation on demand. The “other” category helps define the comparison set, but these relative similarities are not calibrated probabilities or a guarantee of recognizing every unseen object.
3.3 Generating Open-Vocabulary Obstacle Maps
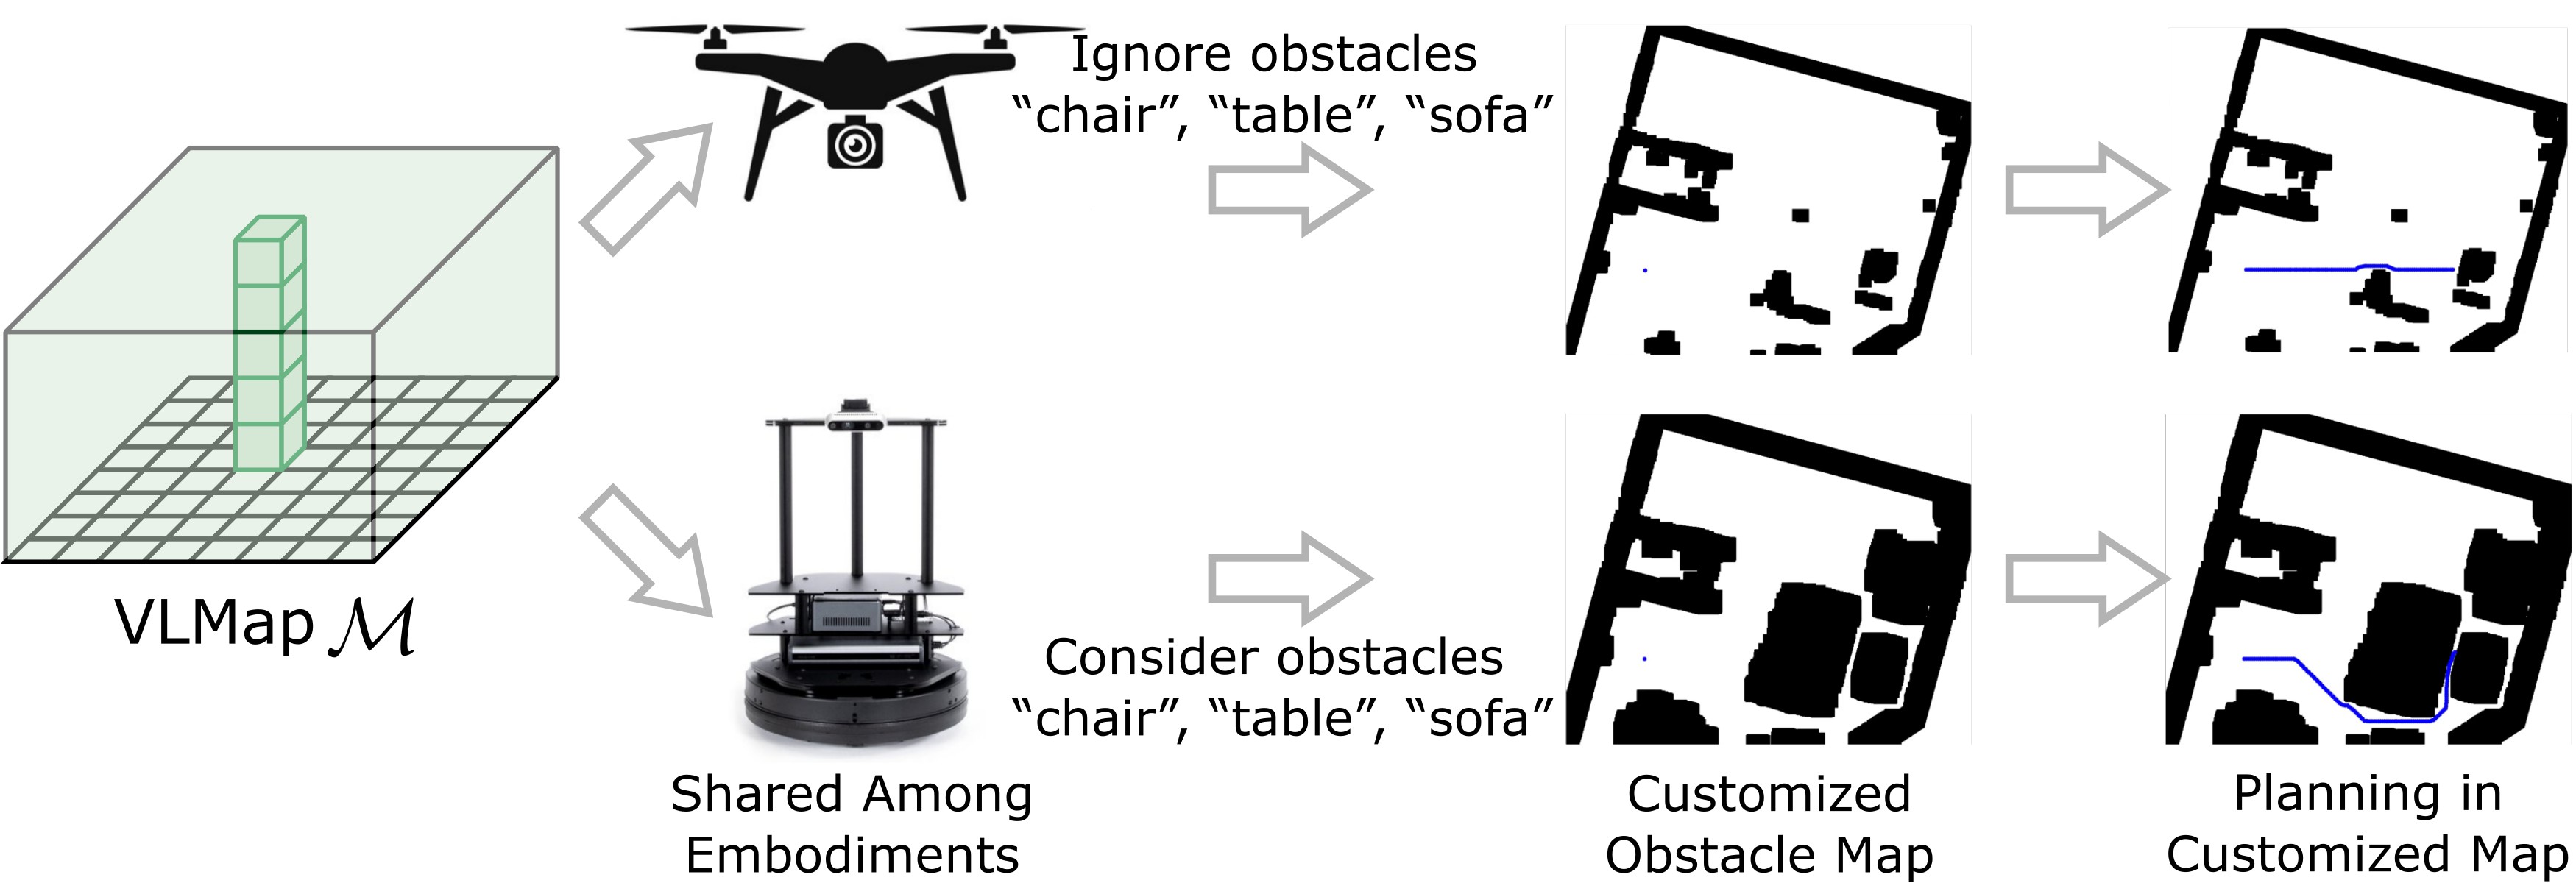
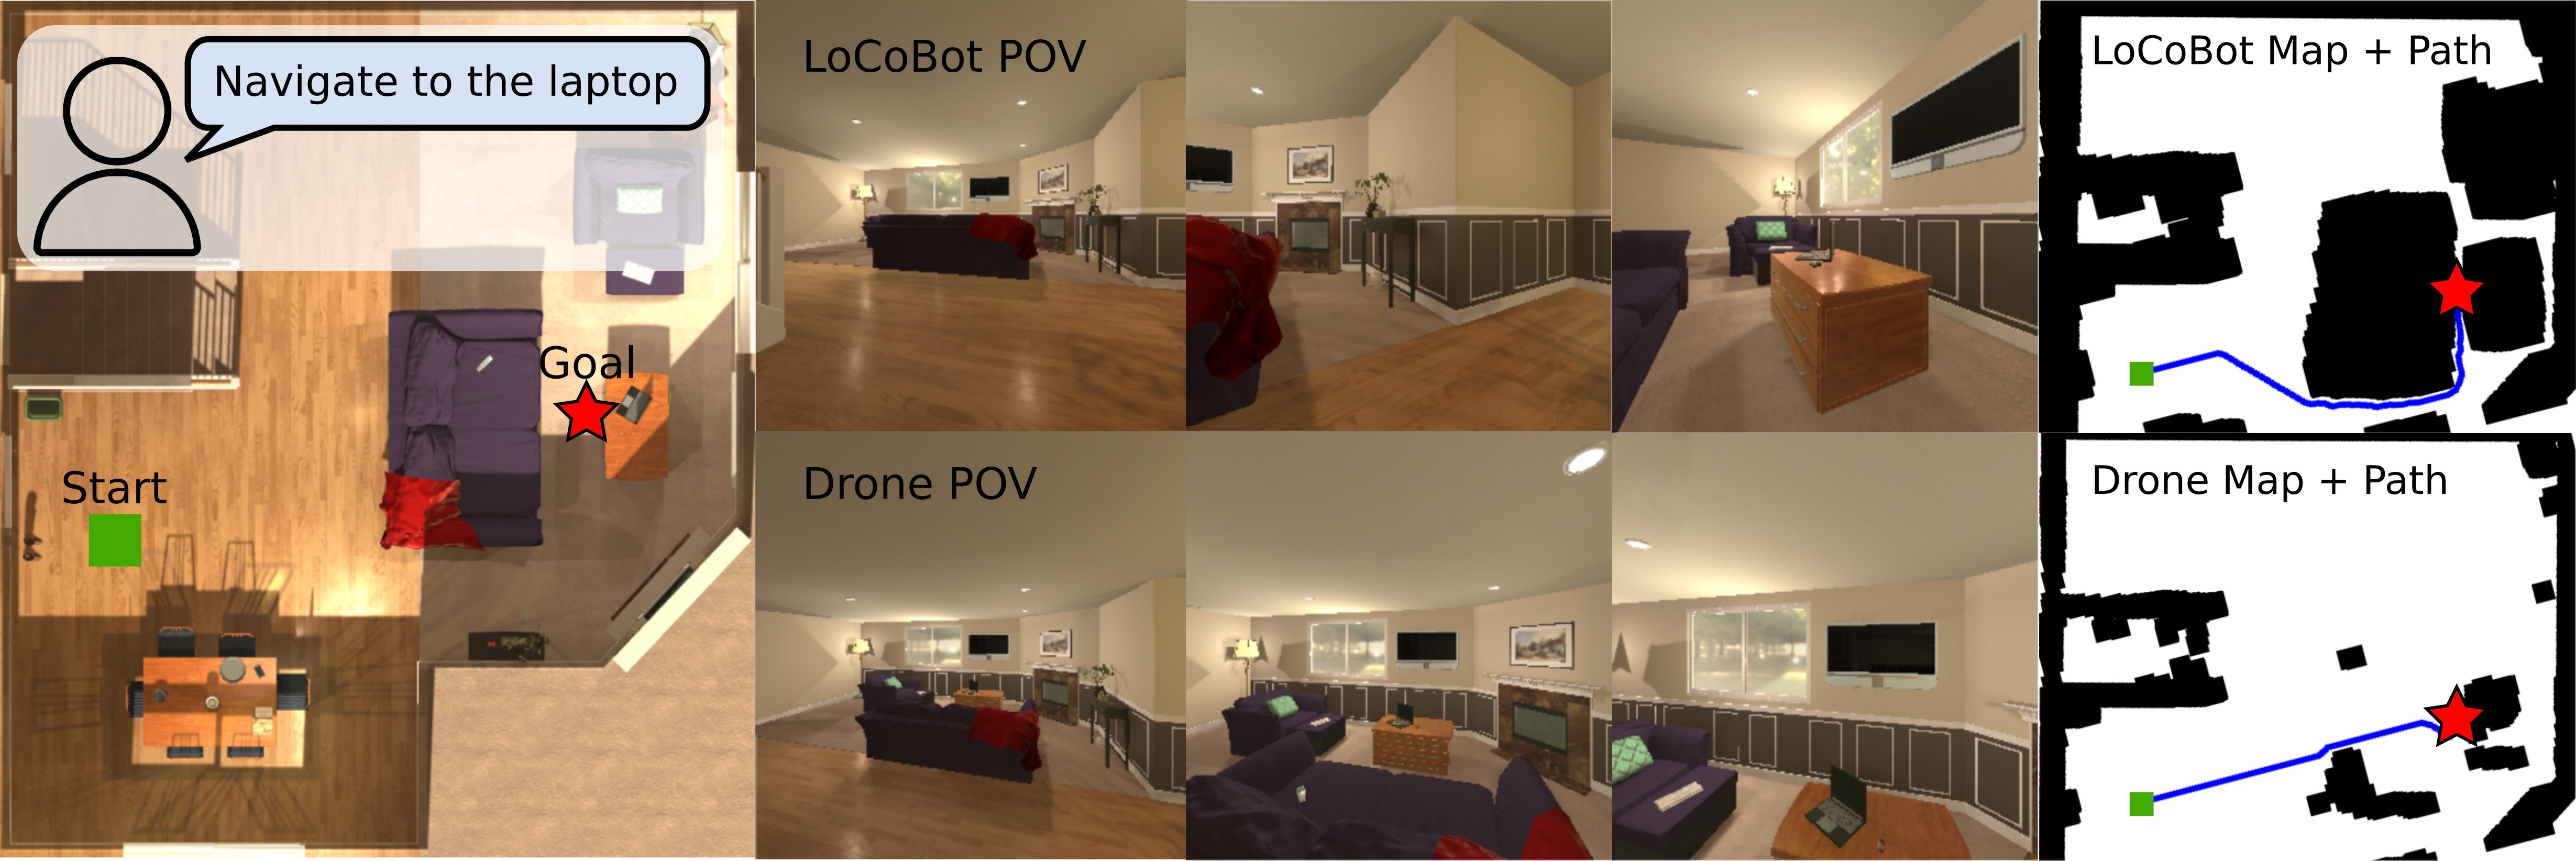
Height-filtered geometry gives a candidate obstacle mask; language-derived semantic masks select which categories matter for a particular robot. Their intersection suppresses predicted obstacles on geometric floor regions. A drone and ground robot can therefore share features but plan with different category lists. The demonstrated drone case uses a fixed flight-height map, not unrestricted 3D planning or a complete learned model of embodiment clearance.
Equation 2
| (2) |
3.4 Zero-Shot Spatial Goal Navigation from Language
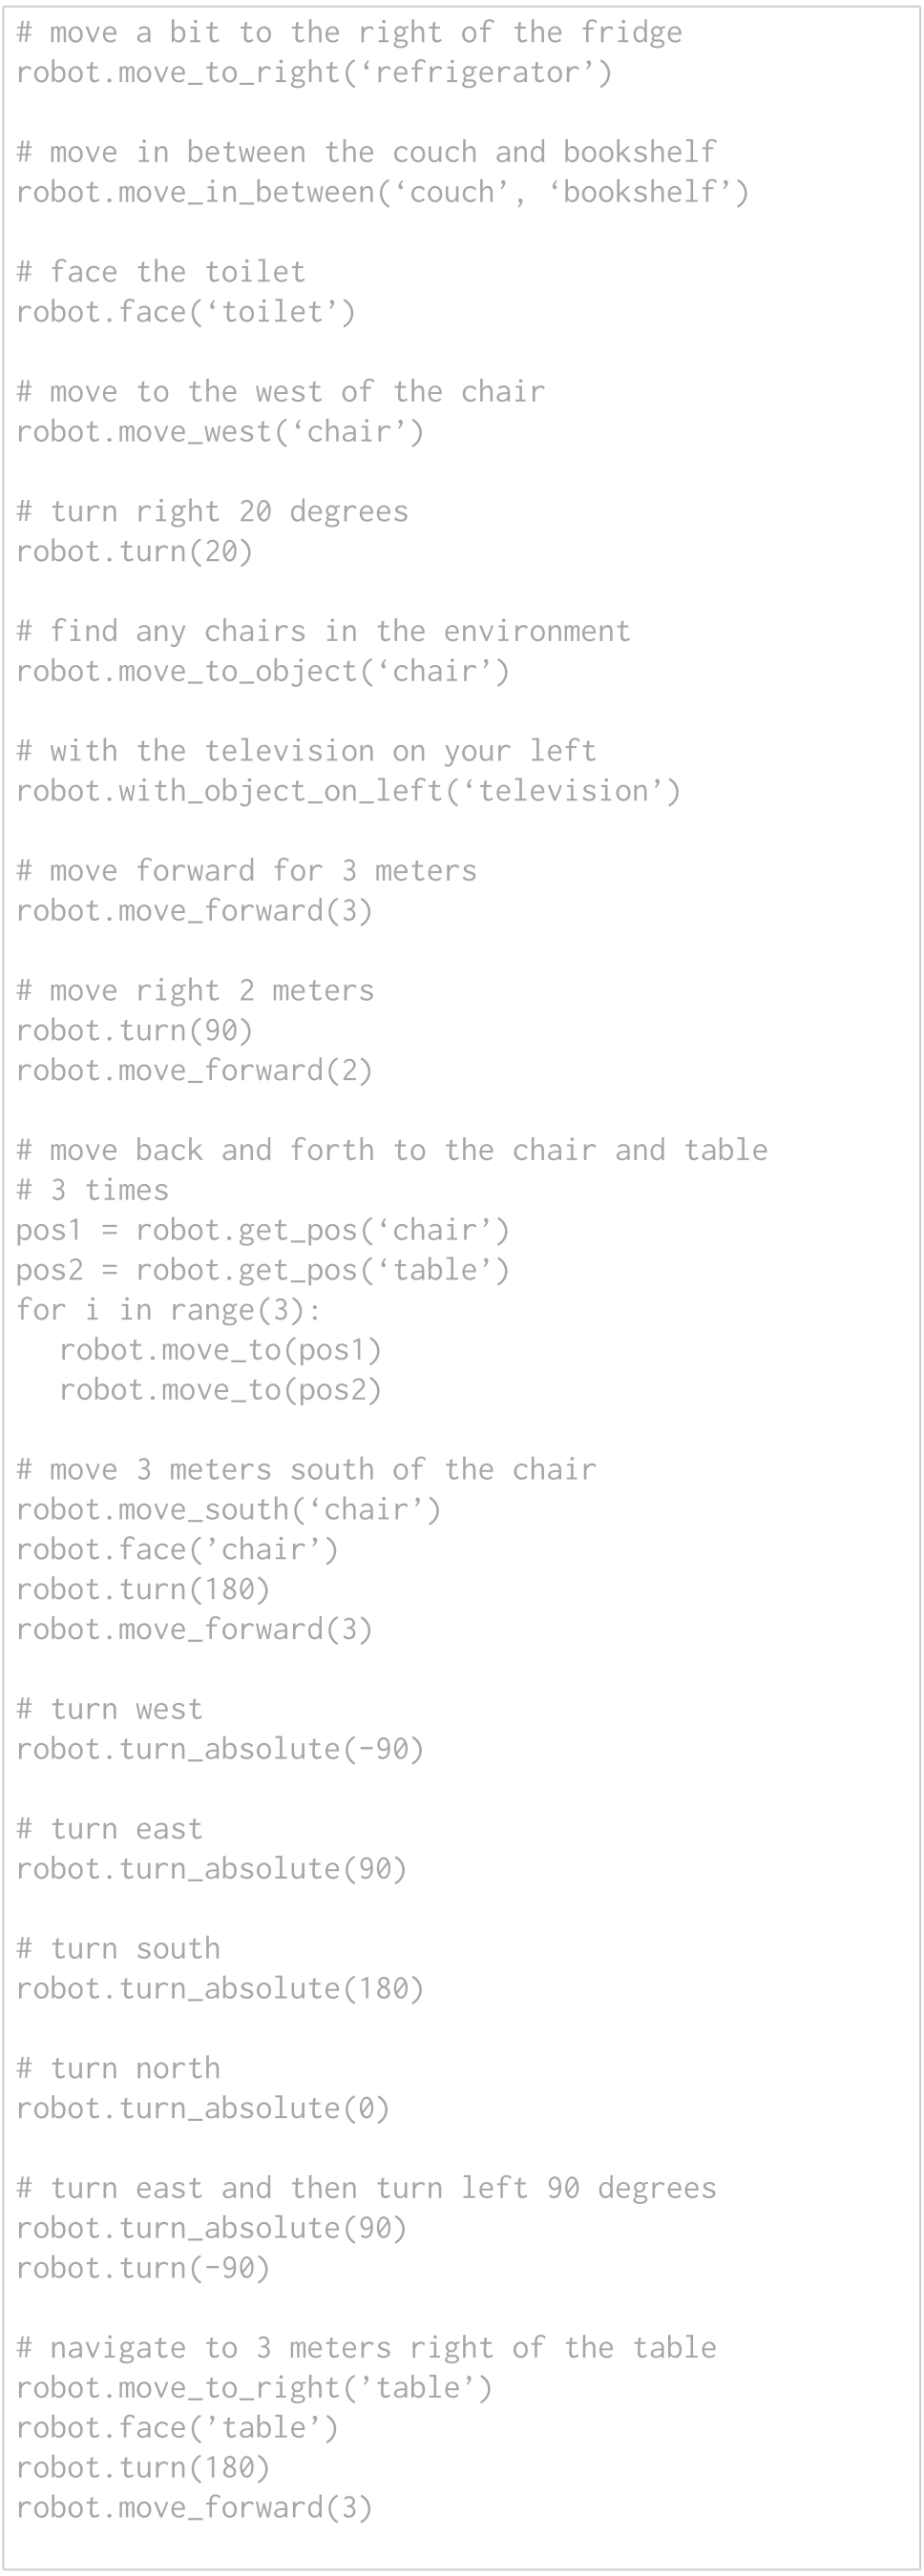
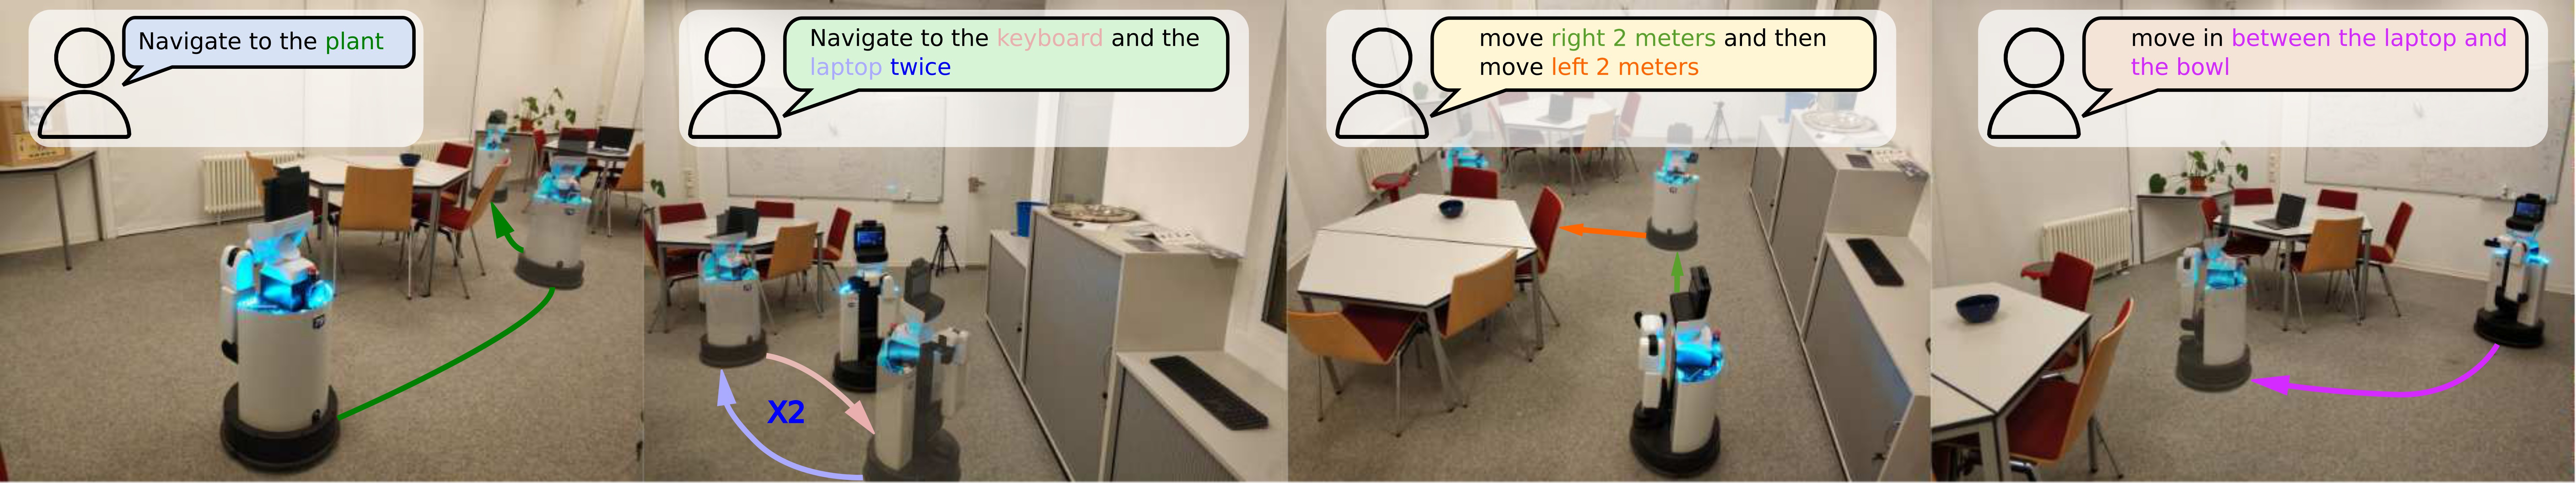
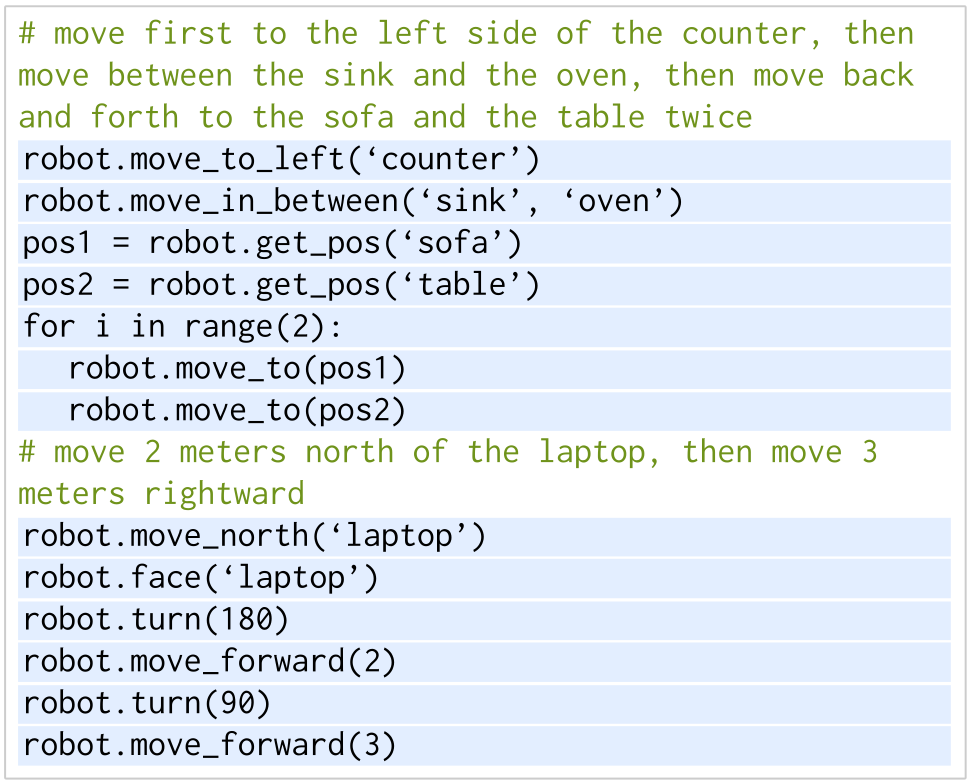
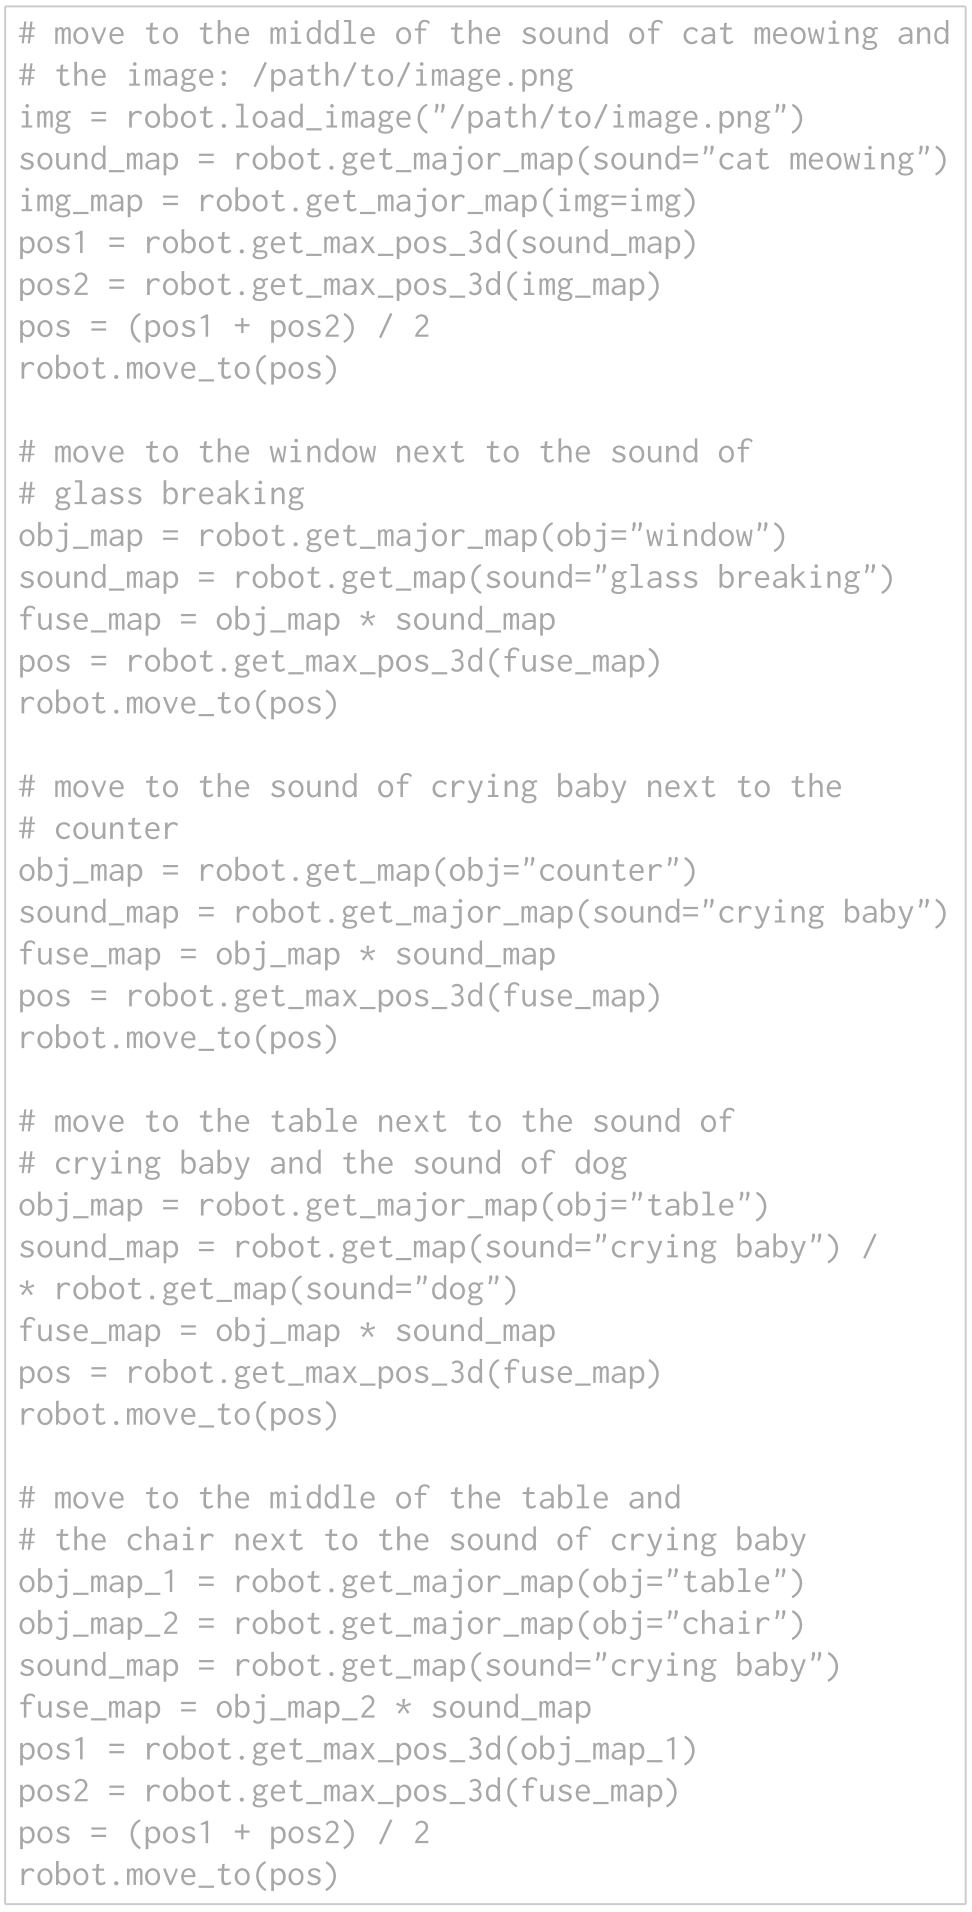
Few-shot instruction/code examples teach the language model to call navigation primitives, sequence subgoals, loop, and compute offsets. Functions such as moving left of an object first localize that object, then apply predefined geometric rules; a conventional planner executes the resulting goal. Spatial understanding is therefore shared between generated code and a manually implemented API. Figures 4 and 6 preserve the full prompt and example outputs, including indentation and highlighted code.
| APIs | Functions |
|---|---|
| move_to(pos) | move to a position on the map. |
| move_to_left(object_name) | move to the left side of the nearest front object. |
| move_to_right(object_name) | move to the right side of the nearest front object. |
| with_pos_on_left(object_name) | turn until the object is on the robot’s left side. |
| with_pos_on_right(object_name) | turn until the object is on the robot’s right side. |
| move_in_between(object_a, object_b) | move in between two objects. |
| face(object_name) | turn until the robot’s front is pointing to the object. |
| turn(angle) | turn right a certain angle. If the angle value is negative, turn left. |
| turn_absolute(angle) | turn to absolute angle. 0 is north, 90 is east, -90 is west, 180 is south. |
| move_north(object_name) | move to the north side of the object. |
| move_south(object_name) | move to the south side of the object. |
| move_east(object_name) | move to the east side of the object. |
| move_west(object_name) | move to the west side of the object. |
| move_forward(dist) | move forward “dist” meters. |
3.5 Building an Audio Visual Language Map
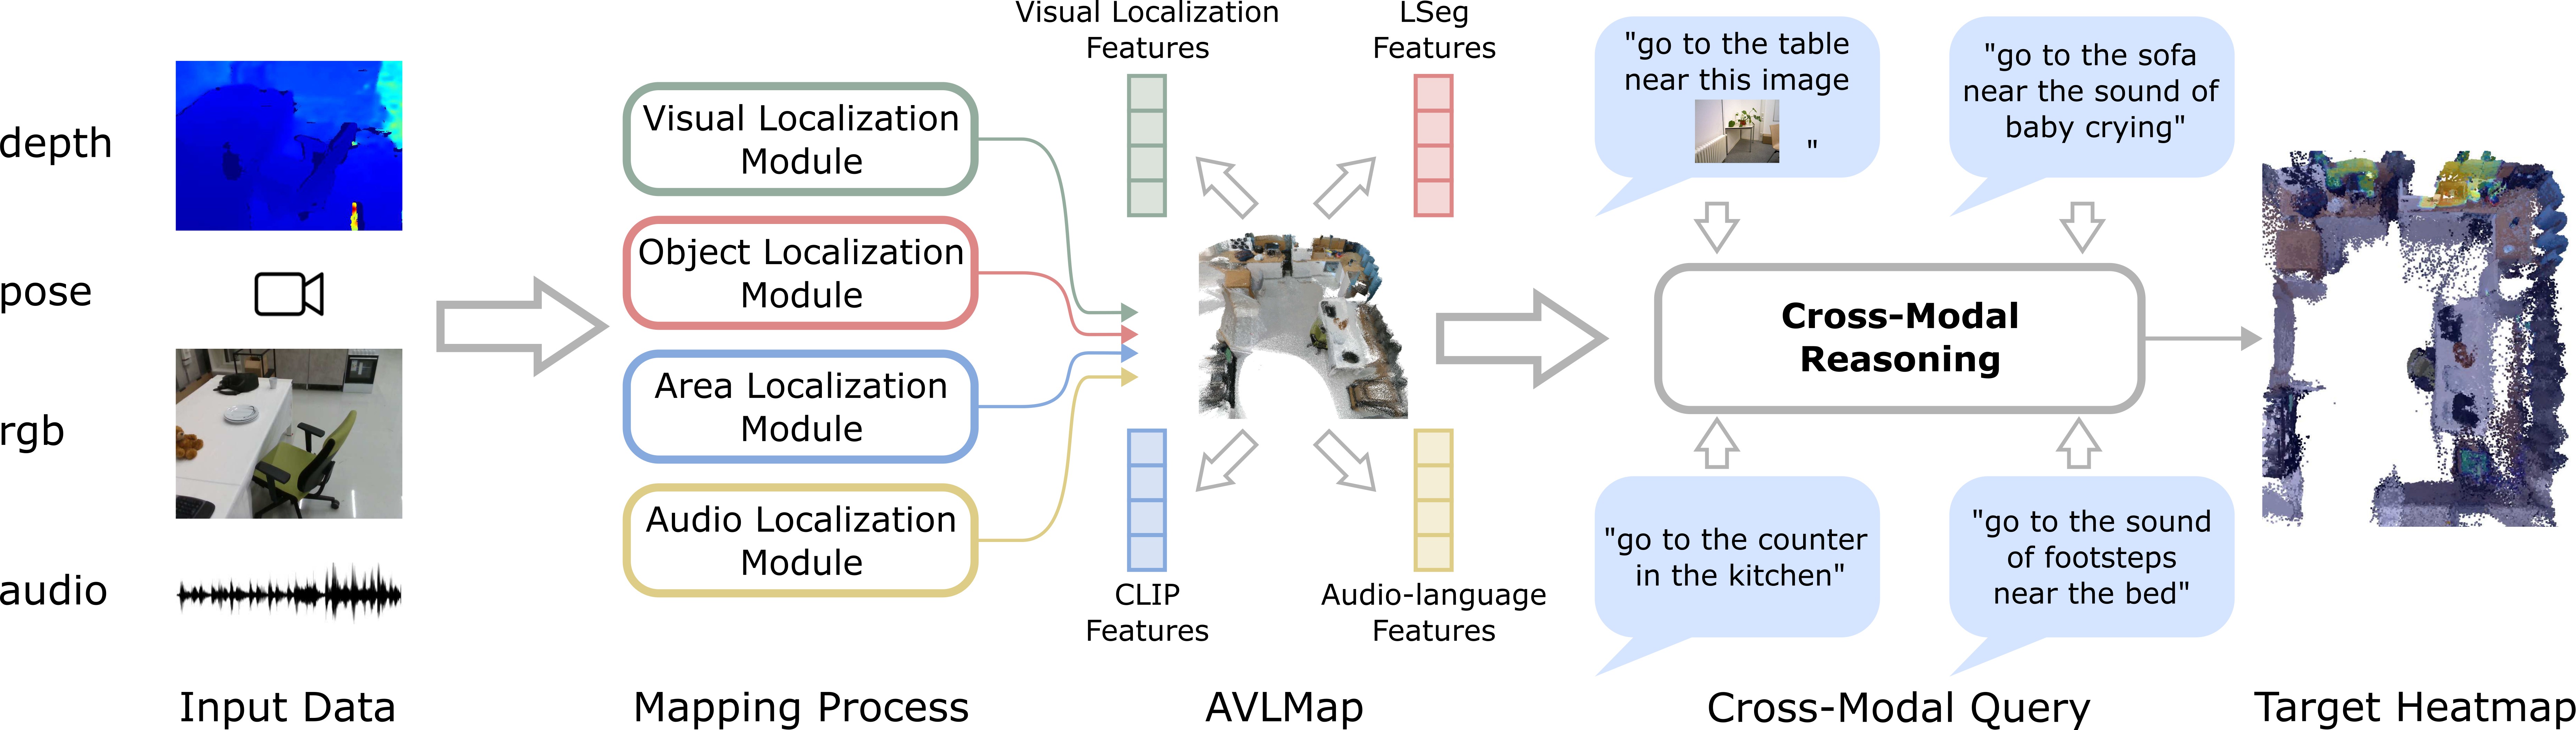
Four modules share a 3D heatmap interface. Image localization retrieves a reference using NetVLAD, matches SuperPoint features with SuperGLUE, and solves a 2D–3D pose problem. Object localization averages dense visual-language descriptors in 3D voxels. Region localization uses a separate sparse map of whole-image CLIP features, preserving broad concepts such as kitchen that segmentation-tuned encoders may represent poorly.
Audio is segmented by silence, embedded with an audio-language model, and stored alongside the robot poses during that segment. A text sound query retrieves these remembered observations. It predicts where the robot heard the sound, not the acoustic source location. Distance-decaying heatmaps spread the image, object, region, or audio scores spatially; audio/image heatmaps can also define forbidden areas. These scores are heuristic spatial relevancies despite the paper’s probability terminology. The original audio equations 9–10 repeat a distance term and leave an index ambiguous in equation 10; their notation is retained without silently changing the implementation specification.
Related source: SuperGLUE.
Equations 3–4
| (3) |
| (4) |
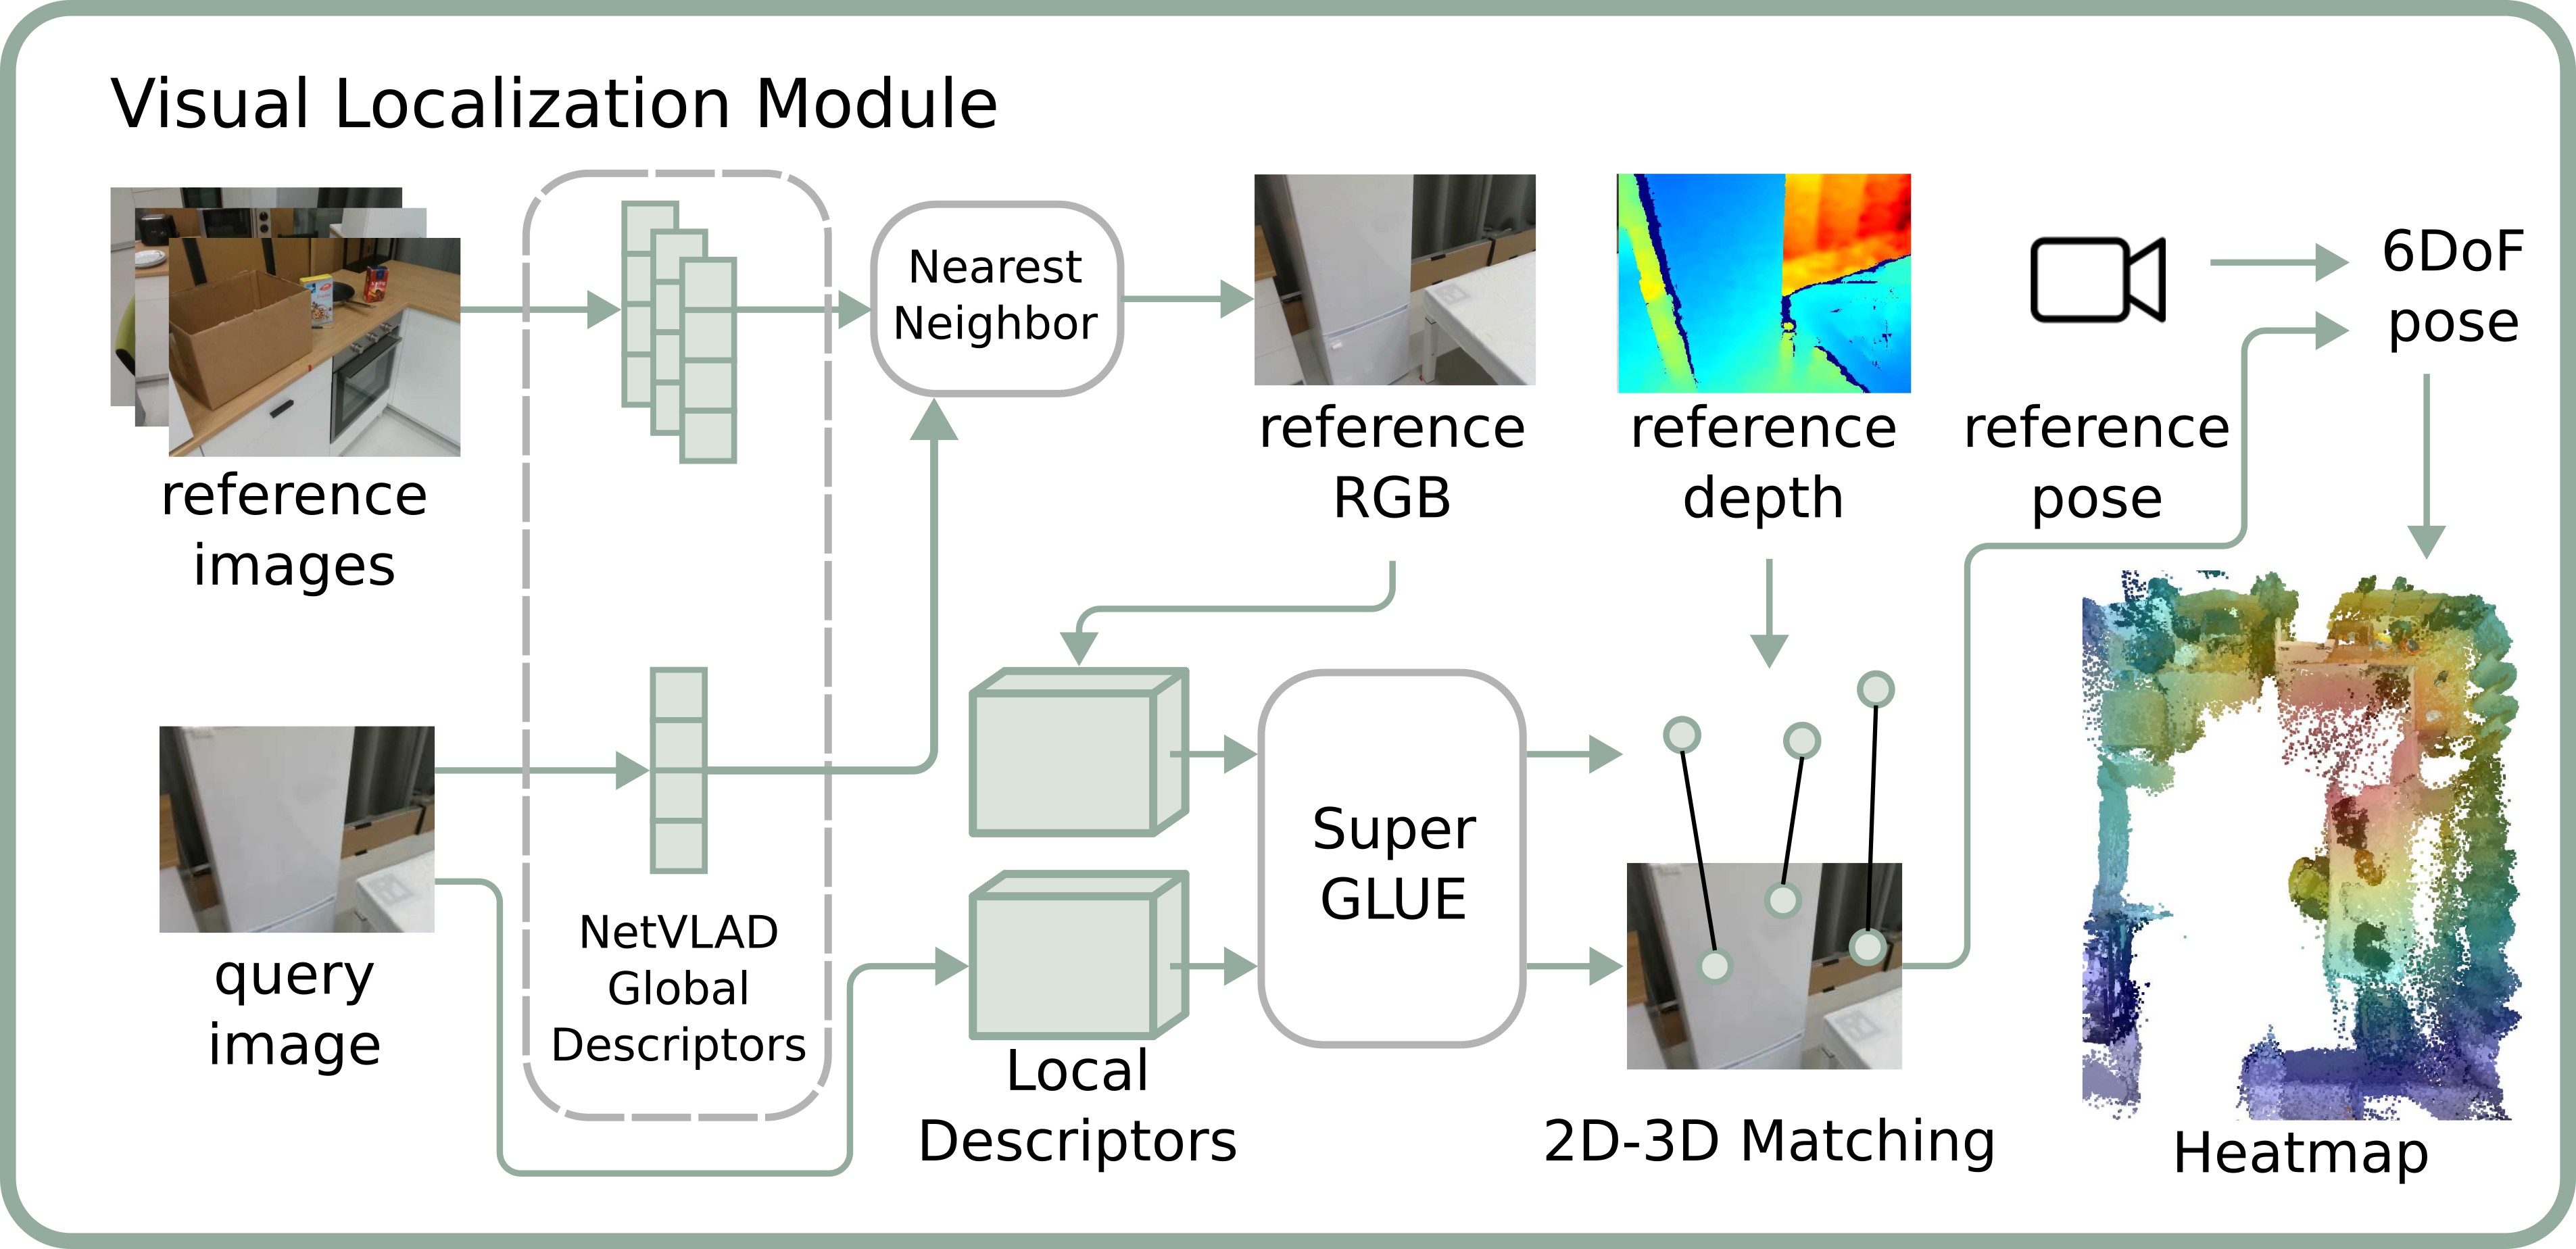
Equations 5–6
| (5) |
| (6) |
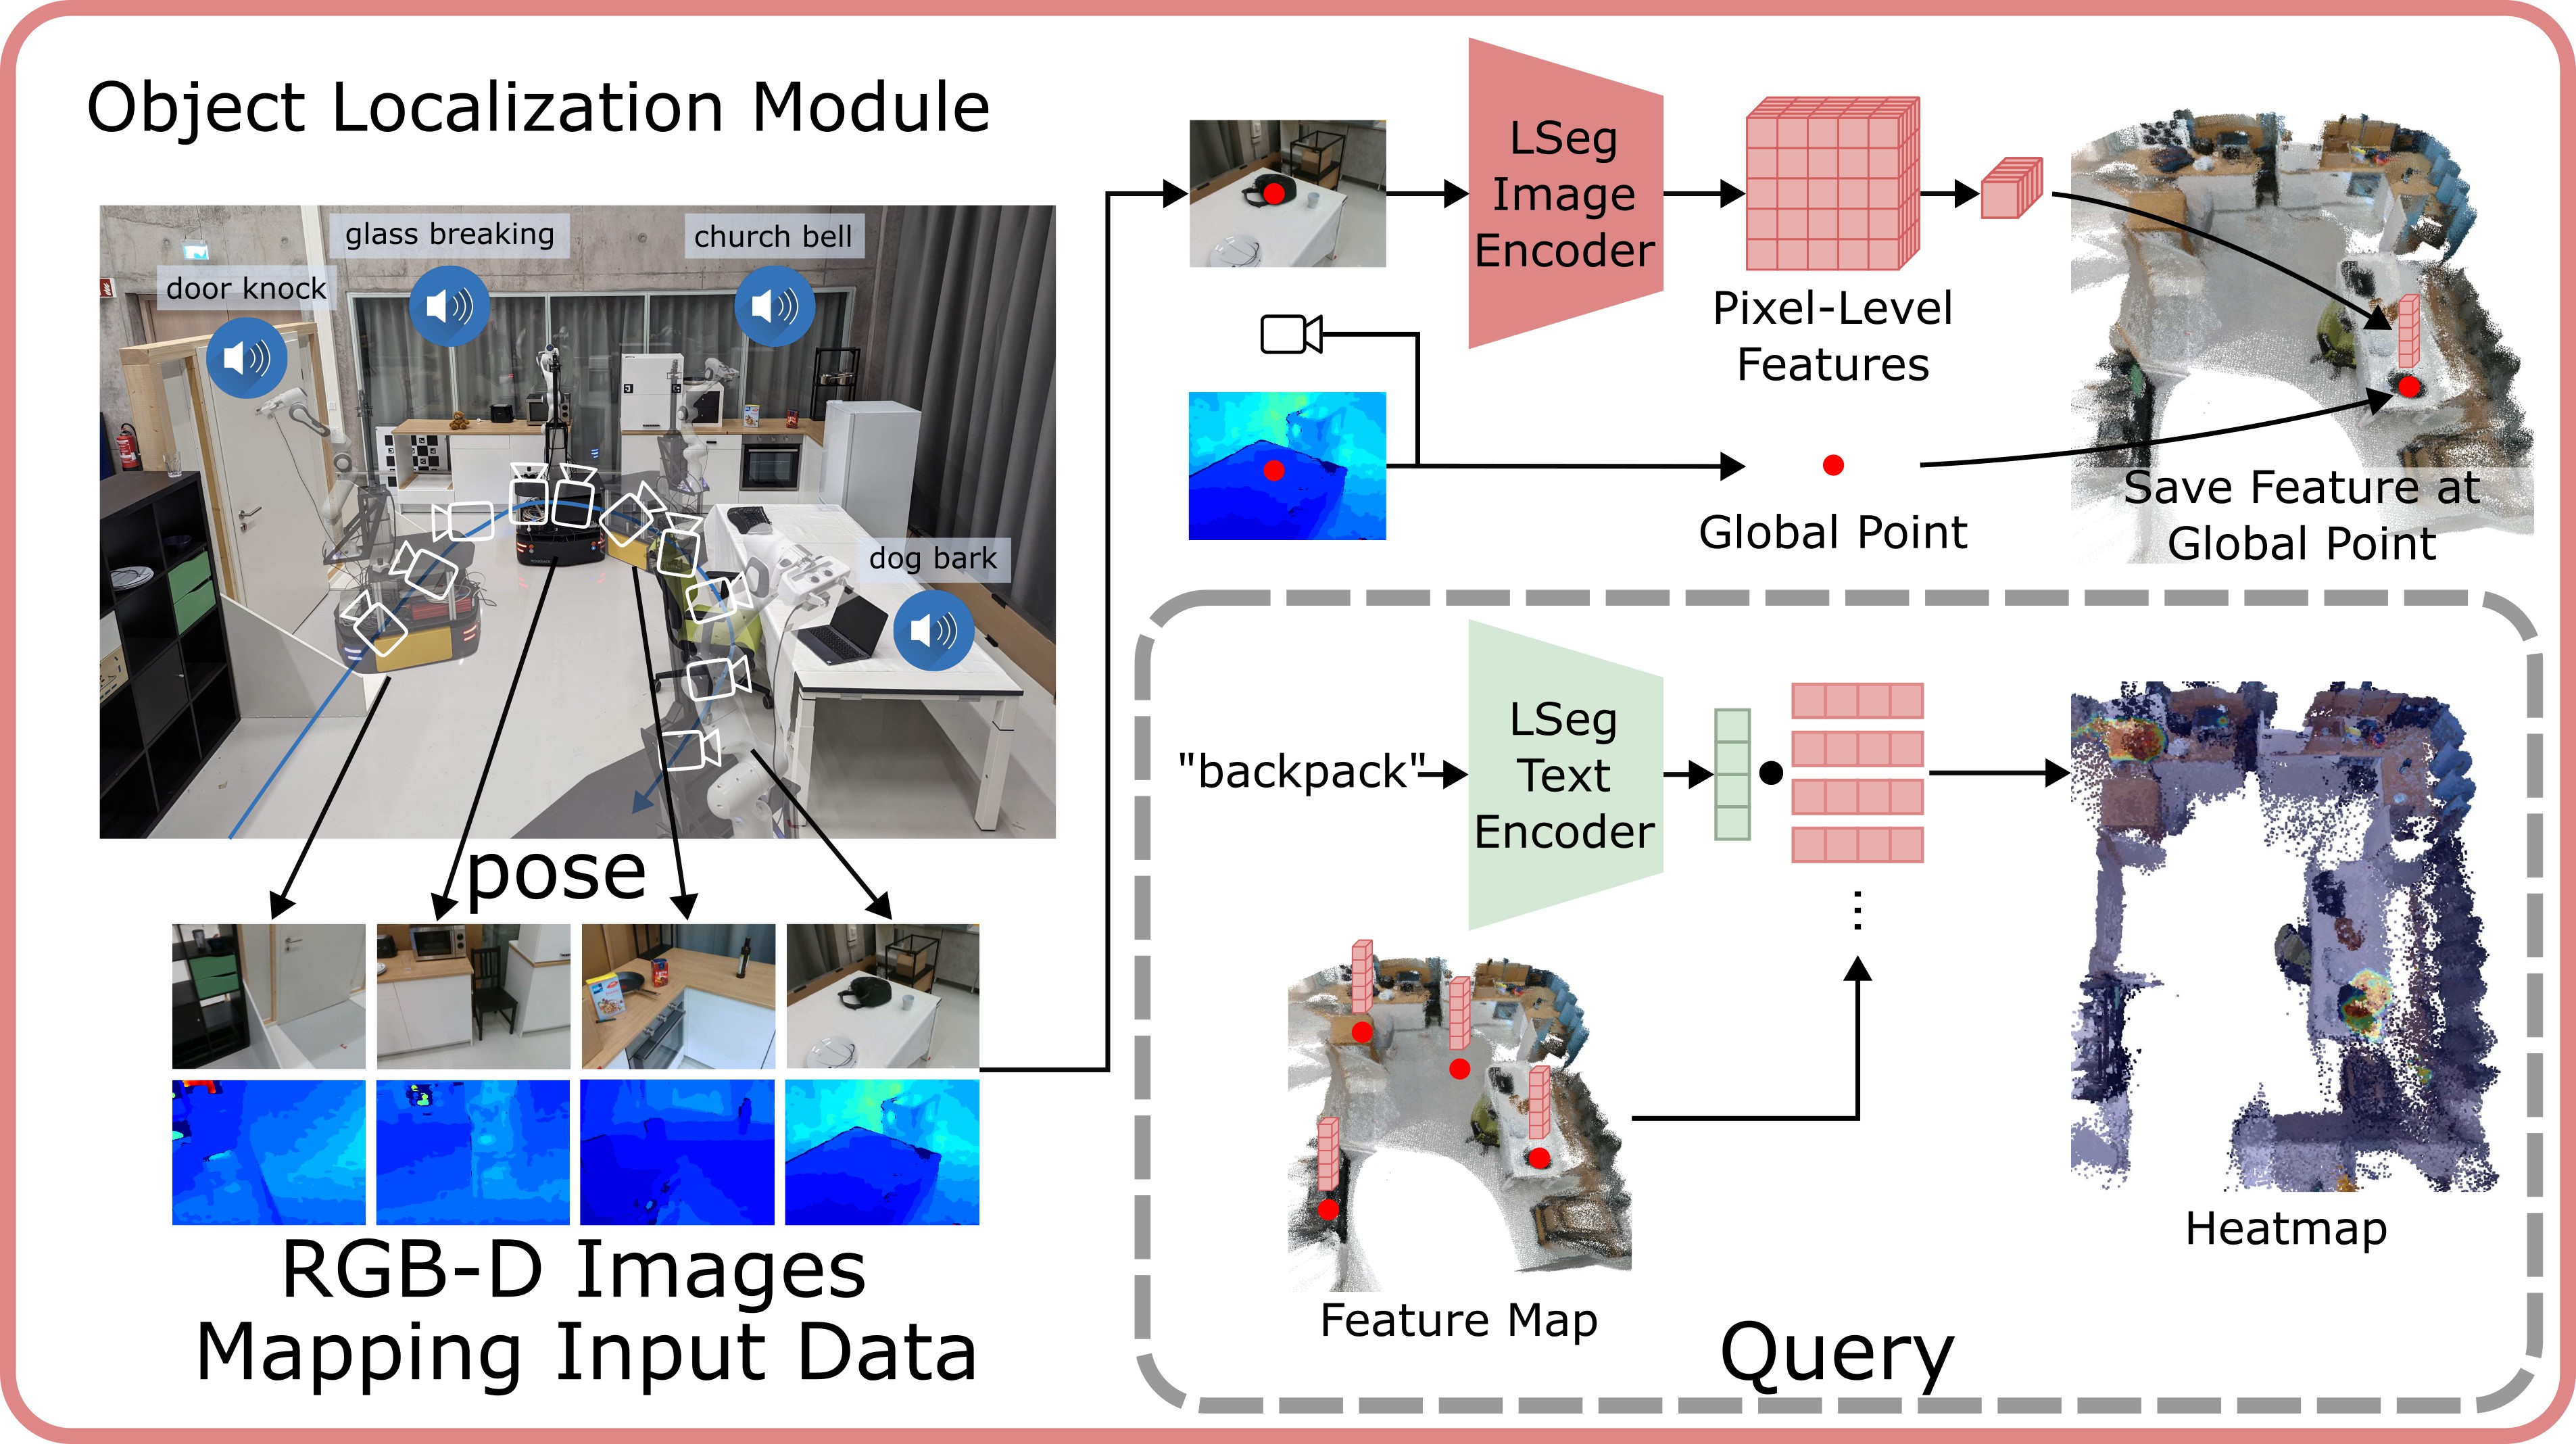
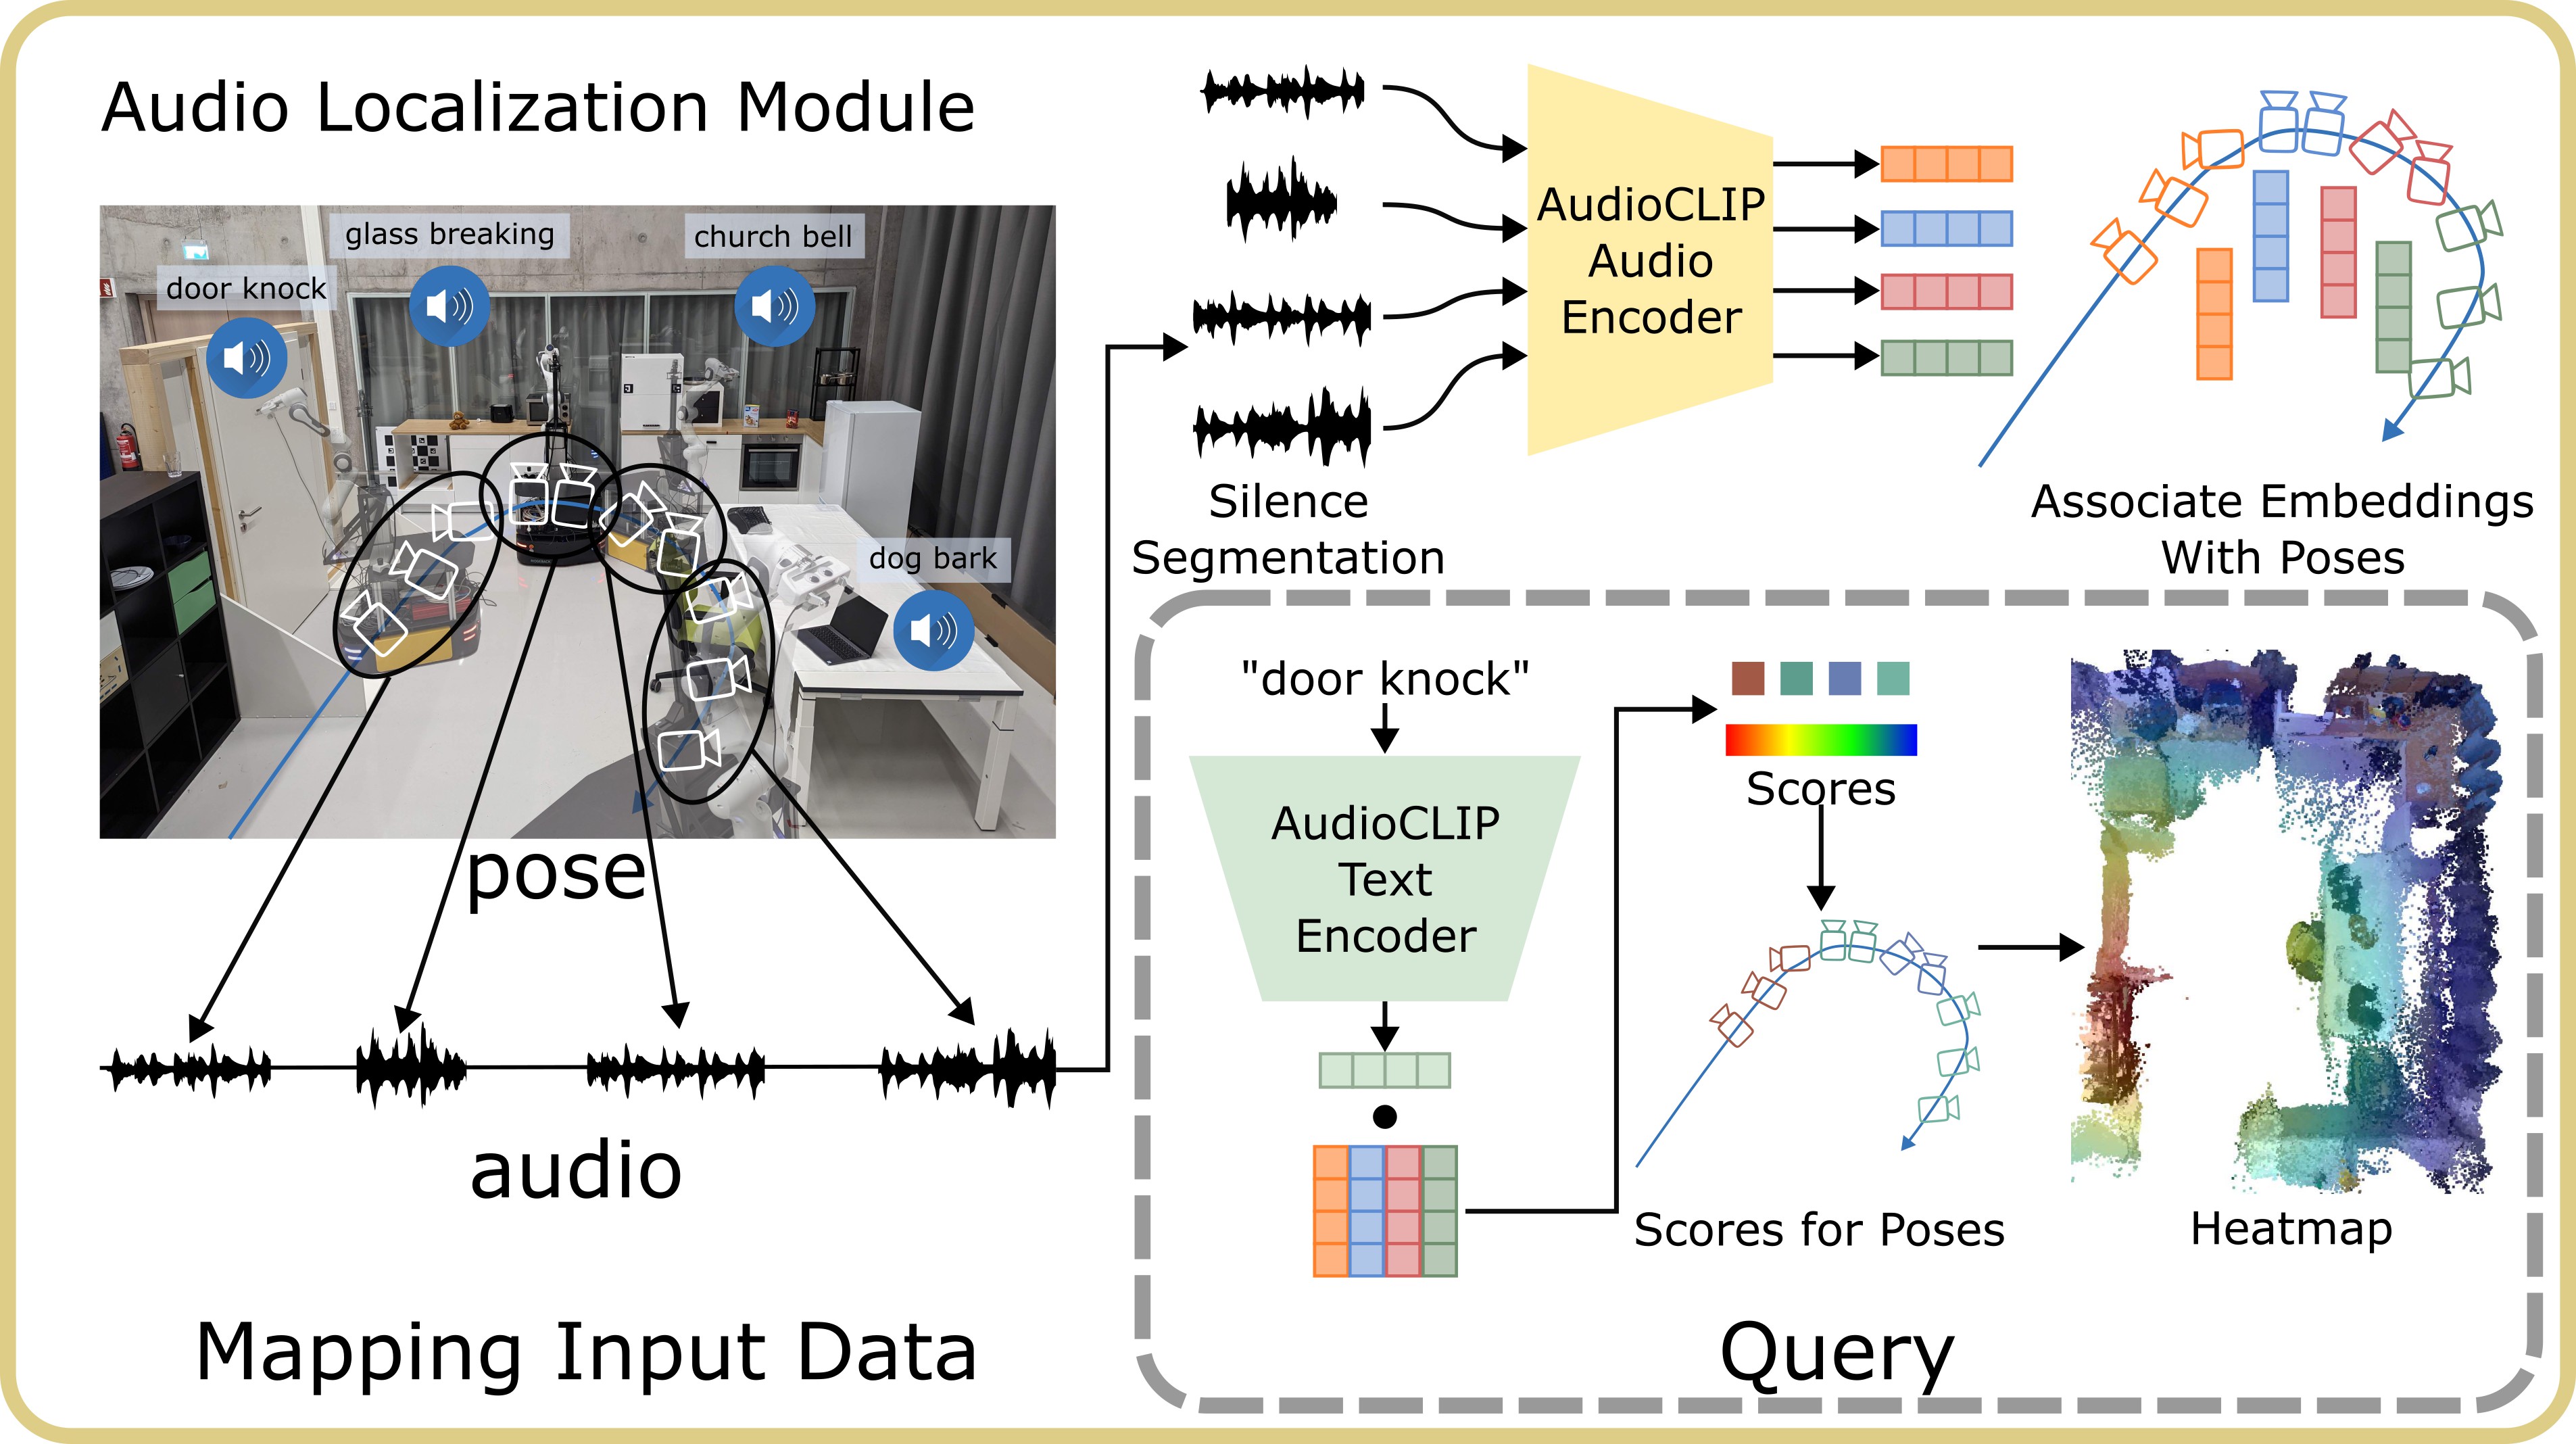
Equations 7–10
| (7) |
| (8) |
| (9) |
| (10) |
3.6 Cross-Modality Reasoning
Cross-modal reasoning multiplies heatmaps elementwise and chooses the strongest resulting location. The primary target uses a sharper decay, while auxiliary concepts use broader fields to select a nearby instance. Reported rates are 0.1 and 0.01 per five-centimeter voxel. This simple product assumes conditional independence and can amplify errors when one module is wrong. Equal-width maps can favor an intermediate location when their support overlaps; they do not guarantee a meaningful midpoint for every configuration.
Equation 11
| (11) |
| APIs | Functions |
|---|---|
| load_image(path) | load an image as an array from the path. |
| move_to(pos) | move to a position on the map. |
| get_major_map(img=None, obj=None, sound=None) | generate a heatmap with high heat decay rate for a specific modality (image, object description, or sound description). |
| get_map(img=None, obj=None, sound=None) | generate a heatmap with low heat decay rate for a specific modality (image, object description, or sound description). |
| get_max_pose_3d(heatmap) | retrieve the coordinate in a 3d voxel heatmap which has the maximal heat value). |
3.7 Multimodal Goal Navigation from Language
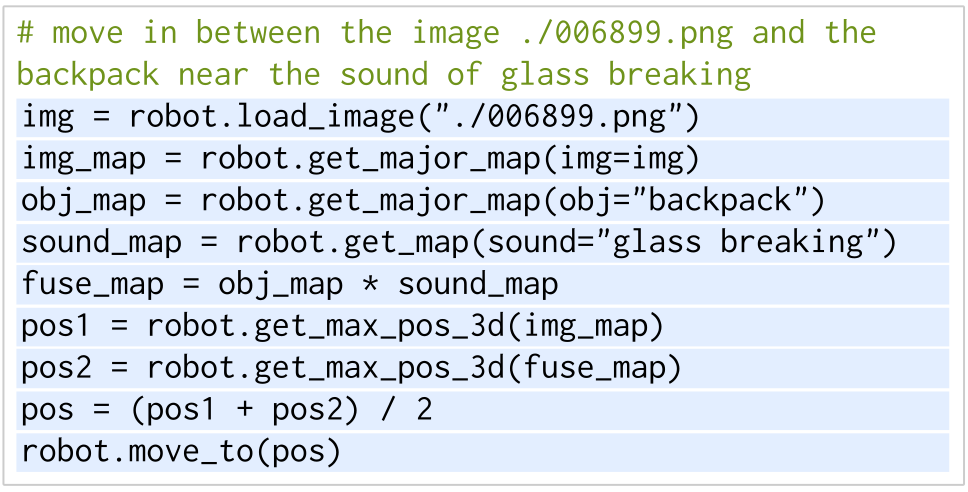
The language model generates code using image loading, sharp or broad heatmap construction, map multiplication, maximum-location retrieval, and movement primitives. Spatial goals can be arithmetic combinations of localized positions. The model used in the reported experiments is text-davinci-003, with the complete context examples preserved in Figure 12 and an output example in Figure 13.
A 3D target is projected to the navigation grid and converted into primitive actions by a planner. The method text lists 0.25-meter forward steps, whereas the multimodal simulation experiment later specifies 0.1-meter steps; those source settings are kept distinct. This is prompted program composition over a fixed tool library rather than end-to-end learning of robot dynamics.
4 Experiments
Evaluation separates spatial-goal navigation, cross-embodiment obstacle maps, multimodal navigation, ambiguous-goal indexing, model substitutions, and two physical robot settings. Individual-goal success, complete-sequence success, localization recall, and path efficiency measure different aspects and should not be interchanged.
4.1 Zero-Shot Spatial Goal Navigation from Language
The spatial-navigation study maps ten Matterport3D scenes using 12,096 RGB-D frames, then evaluates 21 manually specified four-subgoal trajectories in seven scenes. Reaching within one meter counts as success. VLMaps achieves 62% for the first subgoal but only 10% for all four in sequence; the ground-truth semantic-map reference reaches 76% and 29%. The tested learned-feature baselines fail all four-goal sequences.
All map-based methods receive the same code-generation procedure, while LM-Nav keeps its own parsing approach. The result supports better spatial localization in this small benchmark while exposing substantial compounded failures even with perfect semantics.
| Tasks | No. Subgoals in a Row | |||
|---|---|---|---|---|
| 1 | 2 | 3 | 4 | |
| LM-Nav (Shah et al., 2023) | 5 | 5 | 0 | 0 |
| CoW (Gadre et al., 2023) | 33 | 5 | 0 | 0 |
| CLIP Map | 19 | 0 | 0 | 0 |
| VLMaps (ours) | 62 | 33 | 14 | 10 |
| GT Map | 76 | 48 | 33 | 29 |
| Tasks | No. Subgoals in a Row | Indep. | |||||||
|---|---|---|---|---|---|---|---|---|---|
| 1 | 2 | 3 | 4 | Subgoals | |||||
| SR | SPL | SR | SPL | SR | SPL | SR | SPL | SR | |
| LoCoBot (ground map) | 53 | 49.0 | 28 | 17.8 | 14 | 6.7 | 6 | 2.5 | 52.3 |
| Drone (ground map) | 53 | 41.8 | 28 | 15.5 | 14 | 5.3 | 6 | 2.0 | 53.3 |
| Drone (drone map) | 56 | 45.4 | 30 | 16.3 | 17 | 7.0 | 7 | 2.5 | 55.0 |
4.2 Cross-Embodiment Navigation
Ten AI2THOR rooms are mapped from 1,826 frames and evaluated on more than 100 subgoal sequences. Changing the obstacle categories lets a drone plan over furniture that blocks a LoCoBot. For the first subgoal, drone path-weighted success rises from 41.8 with a ground map to 45.4 with its tailored map, with success changing from 53% to 56%. Complete four-goal success remains only 7% for the tailored drone. This tests reuse of one map at a 1.7-meter flight level, with manually chosen obstacle lists.
4.3 Multimodal Navigation Simulation Setup
Multimodal mapping data is manually collected in ten simulated scenes and augmented with randomly inserted ESC-50 validation-fold sounds. The stored frame positions are the audio targets; no acoustic propagation or source triangulation is evaluated. Navigation stops within one meter of a target. Additional datasets pair objects with region labels, nearby images, or repeated sounds to create ambiguity. This protocol evaluates semantic retrieval and spatial association under controlled audio placement.
4.4 Multimodal Goal Navigation
Sound navigation evaluates 200 four-goal sequences. For the 30-category mixture, independent sound-goal success is 77.5%, while completing four goals in a row reaches 33%; these are different quantities. A separate 200-sequence test requests one image goal followed by two object goals: first-goal success is 71.5%, complete three-goal success 25%, and independent-goal success 47.4%. Multimodal querying works, but errors compound over longer sequences.
| Tasks | No. Subgoals in a Row | Independent | |||
|---|---|---|---|---|---|
| 1 | 2 | 3 | 4 | Subgoals | |
| Domestic Sound (10 categories) | 59.5 | 33.0 | 15.5 | 7.0 | 62.5 |
| + Human Sound (20 categories) | 69.5 | 47.0 | 36.5 | 23.0 | 72.38 |
| + Animal Sound (30 categories) | 74.5 | 58.5 | 45.5 | 33.0 | 77.5 |
4.5 Cross-Modal Goal Indexing
Region-object indexing uses 100 tasks; sound-object indexing uses 119. Combining a sparse region map with VLMaps improves half-meter recall from 5.56% to 15.56%, still below the ground-truth-region reference of 37.78%. Object-conditioned AudioCLIP improves half-meter sound recall from 26.05% to 53.78%. Adding image localization improves ambiguous-object half-meter recall from 7.55% to 62.26%.
These exact comparisons explain the headline improvement of roughly 50 percentage points in one ambiguous setting; it is not a uniform 50% improvement for every modality or tolerance. Even improved methods retain nonzero average localization error.
| Method | Recall@1 (%) | Average min. distance (m) | ||||
|---|---|---|---|---|---|---|
| <0.5m | <1m | <1.5m | <2m | |||
|
5.56 | 7.78 | 13.33 | 17.78 | 8.22 | |
|
12.22 | 13.33 | 16.67 | 21.11 | 7.60 | |
|
15.56 | 24.44 | 31.11 | 35.56 | 6.17 | |
|
37.78 | 44.44 | 55.56 | 61.11 | 2.62 | |
| Method | Recall@1 (%) | Average min. distance (m) | |||||
|---|---|---|---|---|---|---|---|
| <0.5m | <1m | <1.5m | <2m | ||||
|
8.40 | 10.08 | 10.92 | 14.29 | 8.52 | ||
|
26.05 | 35.29 | 36.97 | 42.01 | 5.04 | ||
|
24.37 | 30.25 | 33.61 | 38.66 | 6.27 | ||
|
53.78 | 65.55 | 67.23 | 70.59 | 2.74 | ||
| Method | Recall@1 (%) | Average min. distance (m) | |||||
|---|---|---|---|---|---|---|---|
| <0.5m | <1m | <1.5m | <2m | ||||
|
7.55 | 9.43 | 11.32 | 11.94 | 11.22 | ||
|
62.26 | 66.67 | 70.44 | 72.32 | 3.11 | ||
4.6 Multimodal Ambiguous Goal Navigation
The 119 two-goal sequences require an ambiguous sound target followed by an ambiguous object target. AudioCLIP-based AVLMaps achieves 46.2% sound-goal and 55.5% object-goal success, versus 22.0% and 53.4% for the wav2clip multimodal alternative. Both goals are completed in 28.6% of sequences versus 12.7%. The stated gains of 24.2 and 2.1 are percentage-point differences; the large benefit is concentrated in the audio component.
Related source: AudioCLIP.
| Tasks | No. Subgoals in a Row | Sound | Object | ||
|---|---|---|---|---|---|
| 1 | 2 | Goals | Goals | ||
| VLMaps | - | - | - | 27.1 | |
| AudioCLIP | - | - | 16.9 | - | |
| VLMaps + wav2clip | 22.0 | 12.7 | 22.0 | 53.4 | |
|
46.2 | 28.6 | 46.2 | 55.5 | |
| ALM | VLM | No. Subgoals in a Row | Sound | Object | |||
|---|---|---|---|---|---|---|---|
| 1 | 2 | 3 | 4 | ||||
| AudioCLIP | LSeg | 71.0 | 59.0 | 29.0 | 17.0 | 71.0 | 41.8 |
| CLAP | LSeg | 81.0 | 69.0 | 36.5 | 19.0 | 81.0 | 52.0 |
| CLAP | SAM+CLIP | 80.0 | 68.5 | 29.5 | 12.0 | 80.0 | 40.5 |
| CLAP | OVSeg | 81.0 | 69.0 | 37.0 | 21.0 | 81.0 | 53.5 |
4.7 Scaling Experiment
Replacing AudioCLIP with CLAP while retaining LSeg raises sound-goal success from 71% to 81%, but complete four-goal success rises only from 17% to 19%. With CLAP fixed, OVSeg reaches 21% complete success and SAM+CLIP falls to 12%, so a newer component does not automatically improve the system. The authors attribute the weak visual substitutions to mask quality, masked-image feature behavior, and scene-specific tuning. These experiments test particular module configurations, not a general scaling law.
4.8 Real World Experiment for Mobile Robot
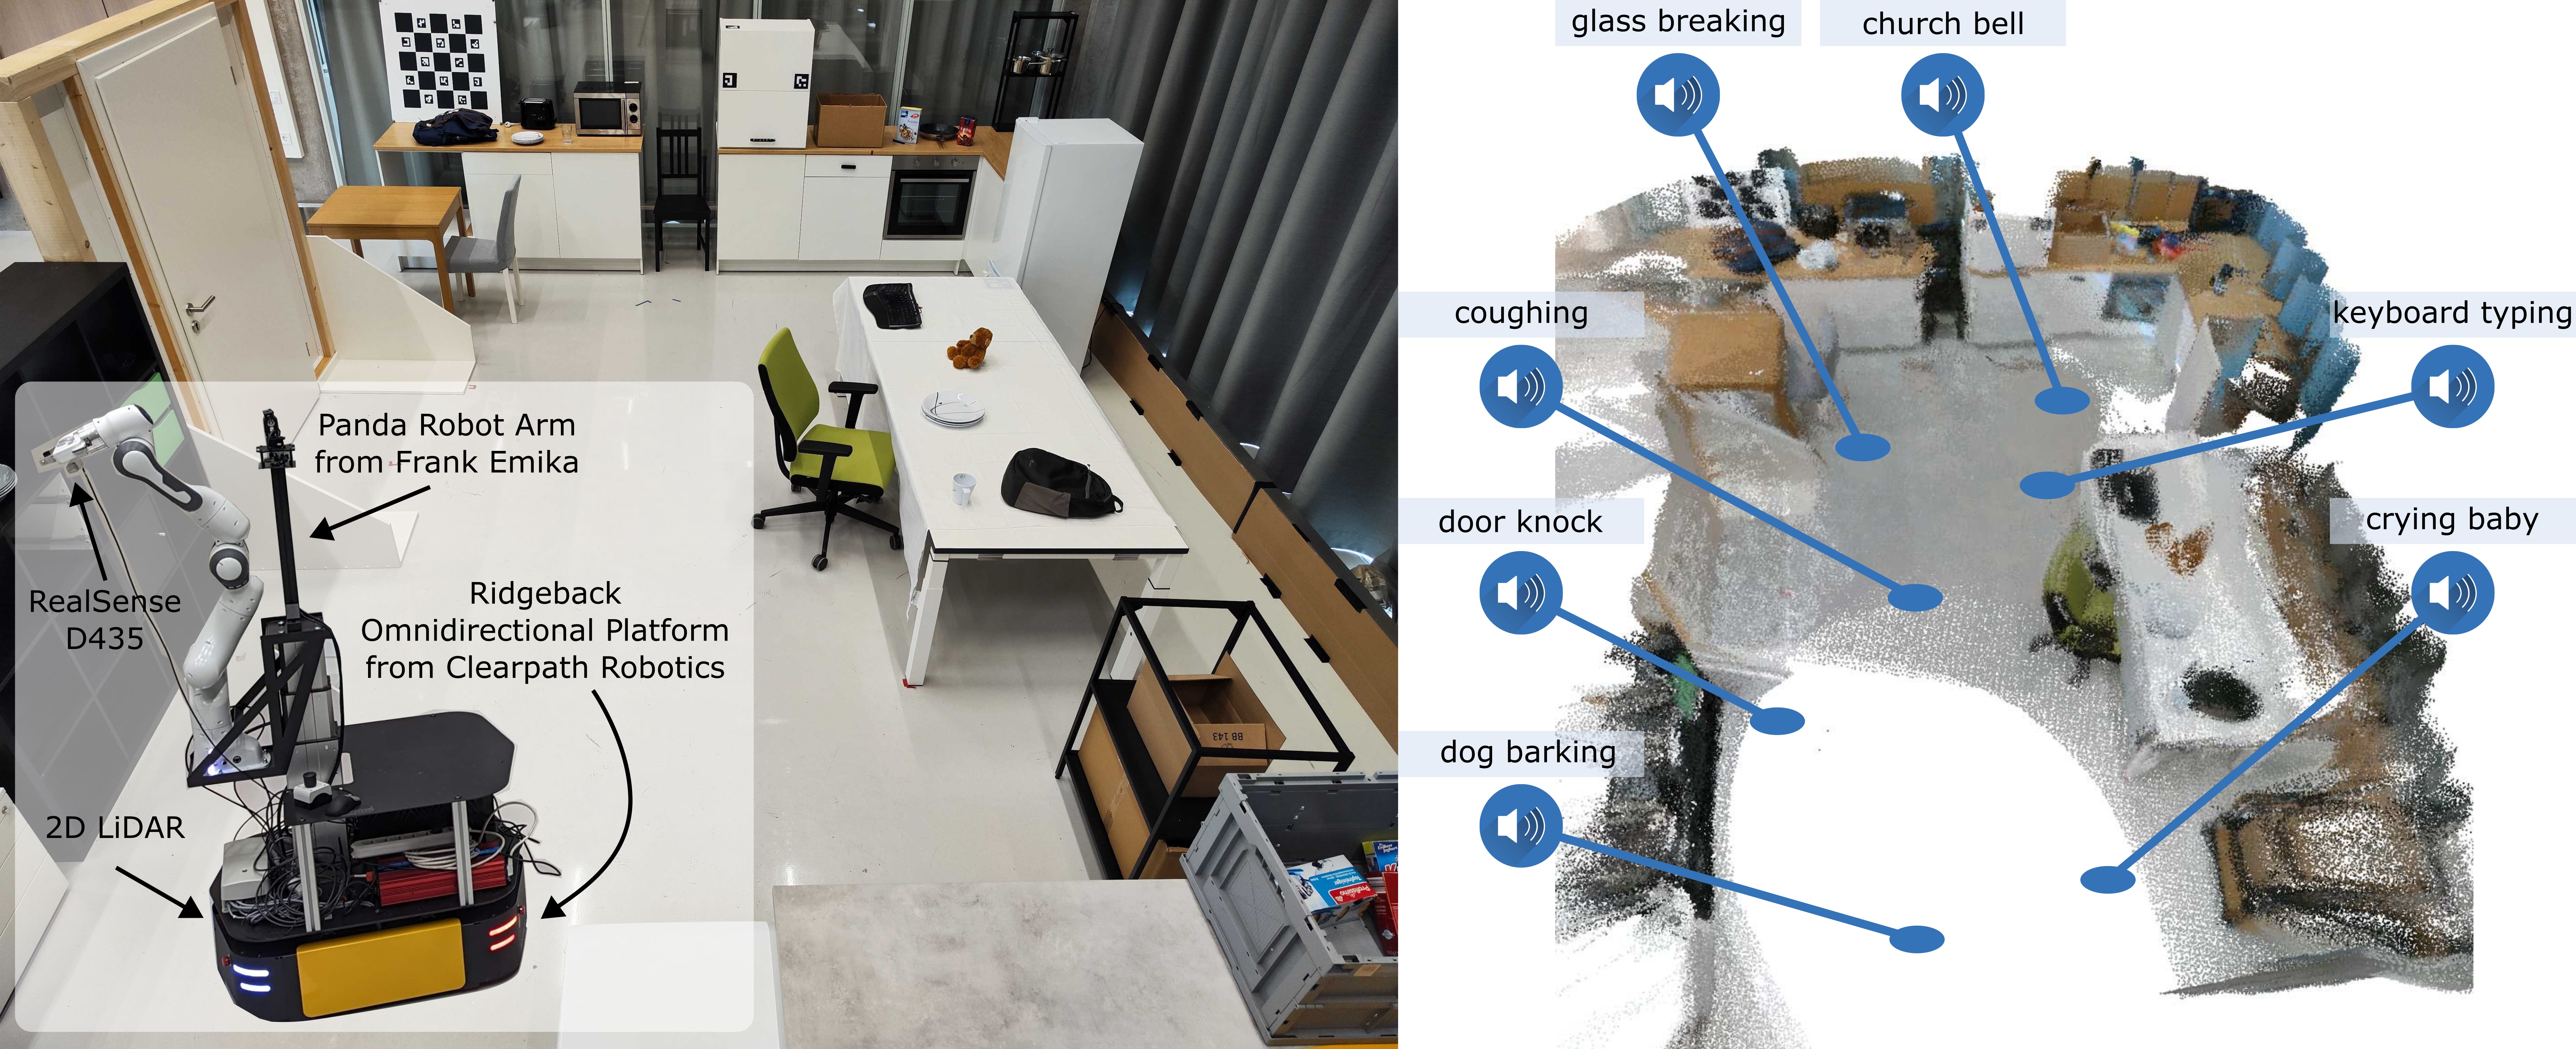
A Ridgeback base with a Panda arm and RGB-D camera supplies physical navigation observations; LiDAR localization and arm kinematics provide poses. Audio categories are inserted into the mapping recording and mixed with measured background noise. Attempted live loudspeaker recording was largely masked by robot vibration, so the reported experiment is not fully live acoustic-source navigation.
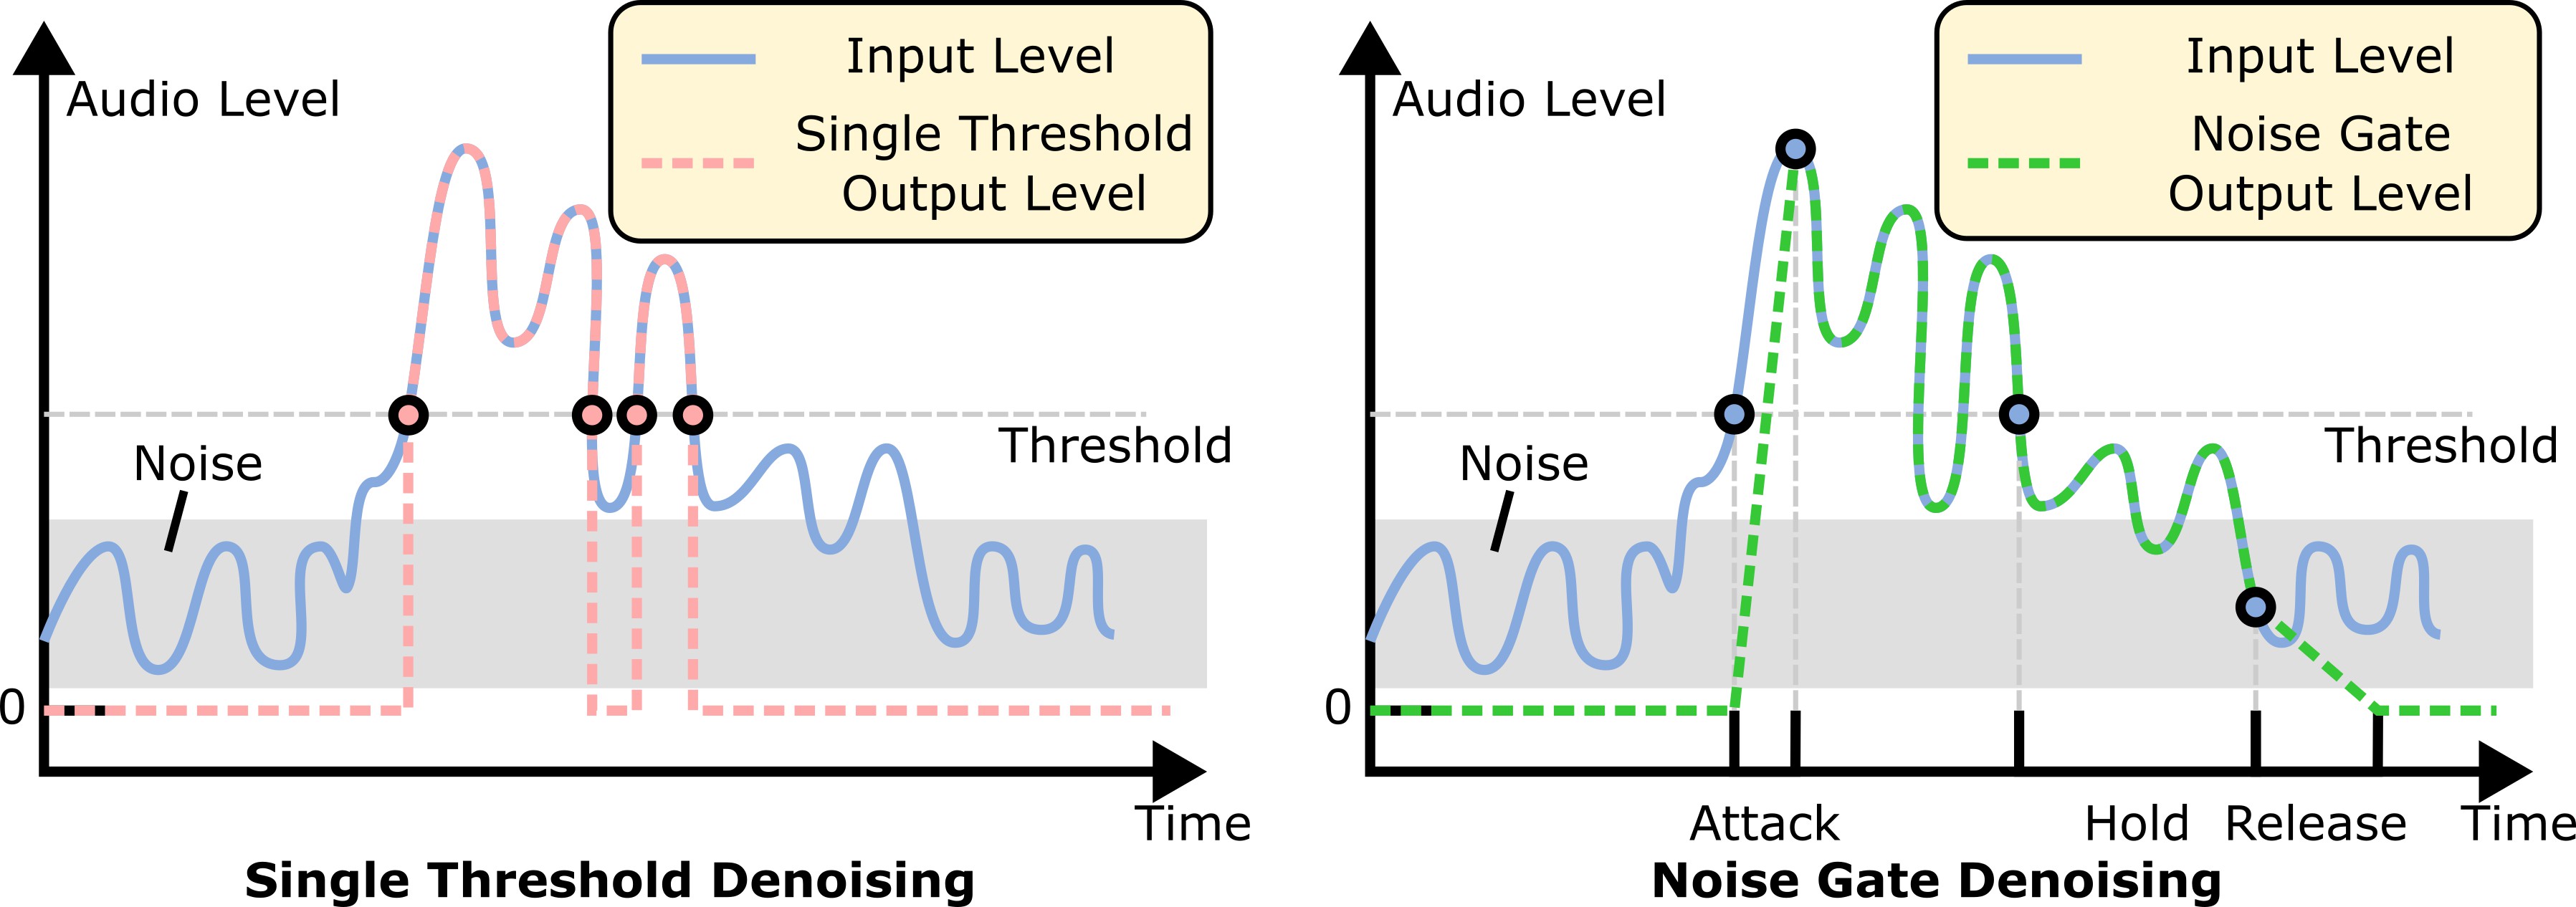
A noise gate uses a −10 dB threshold, 250 ms attack, 1000 ms hold, and 170 ms release, followed by silence segmentation. Offline maps and ROS planning yield 10 successes in 20 multimodal tasks and six in ten spatial tasks. Object confusions and ambiguous audio scores remain failure modes. These small physical tests demonstrate integrated navigation under the stated audio construction rather than general noise-robust hearing.
4.9 Real World Experiment for Table-Top Goal Reaching
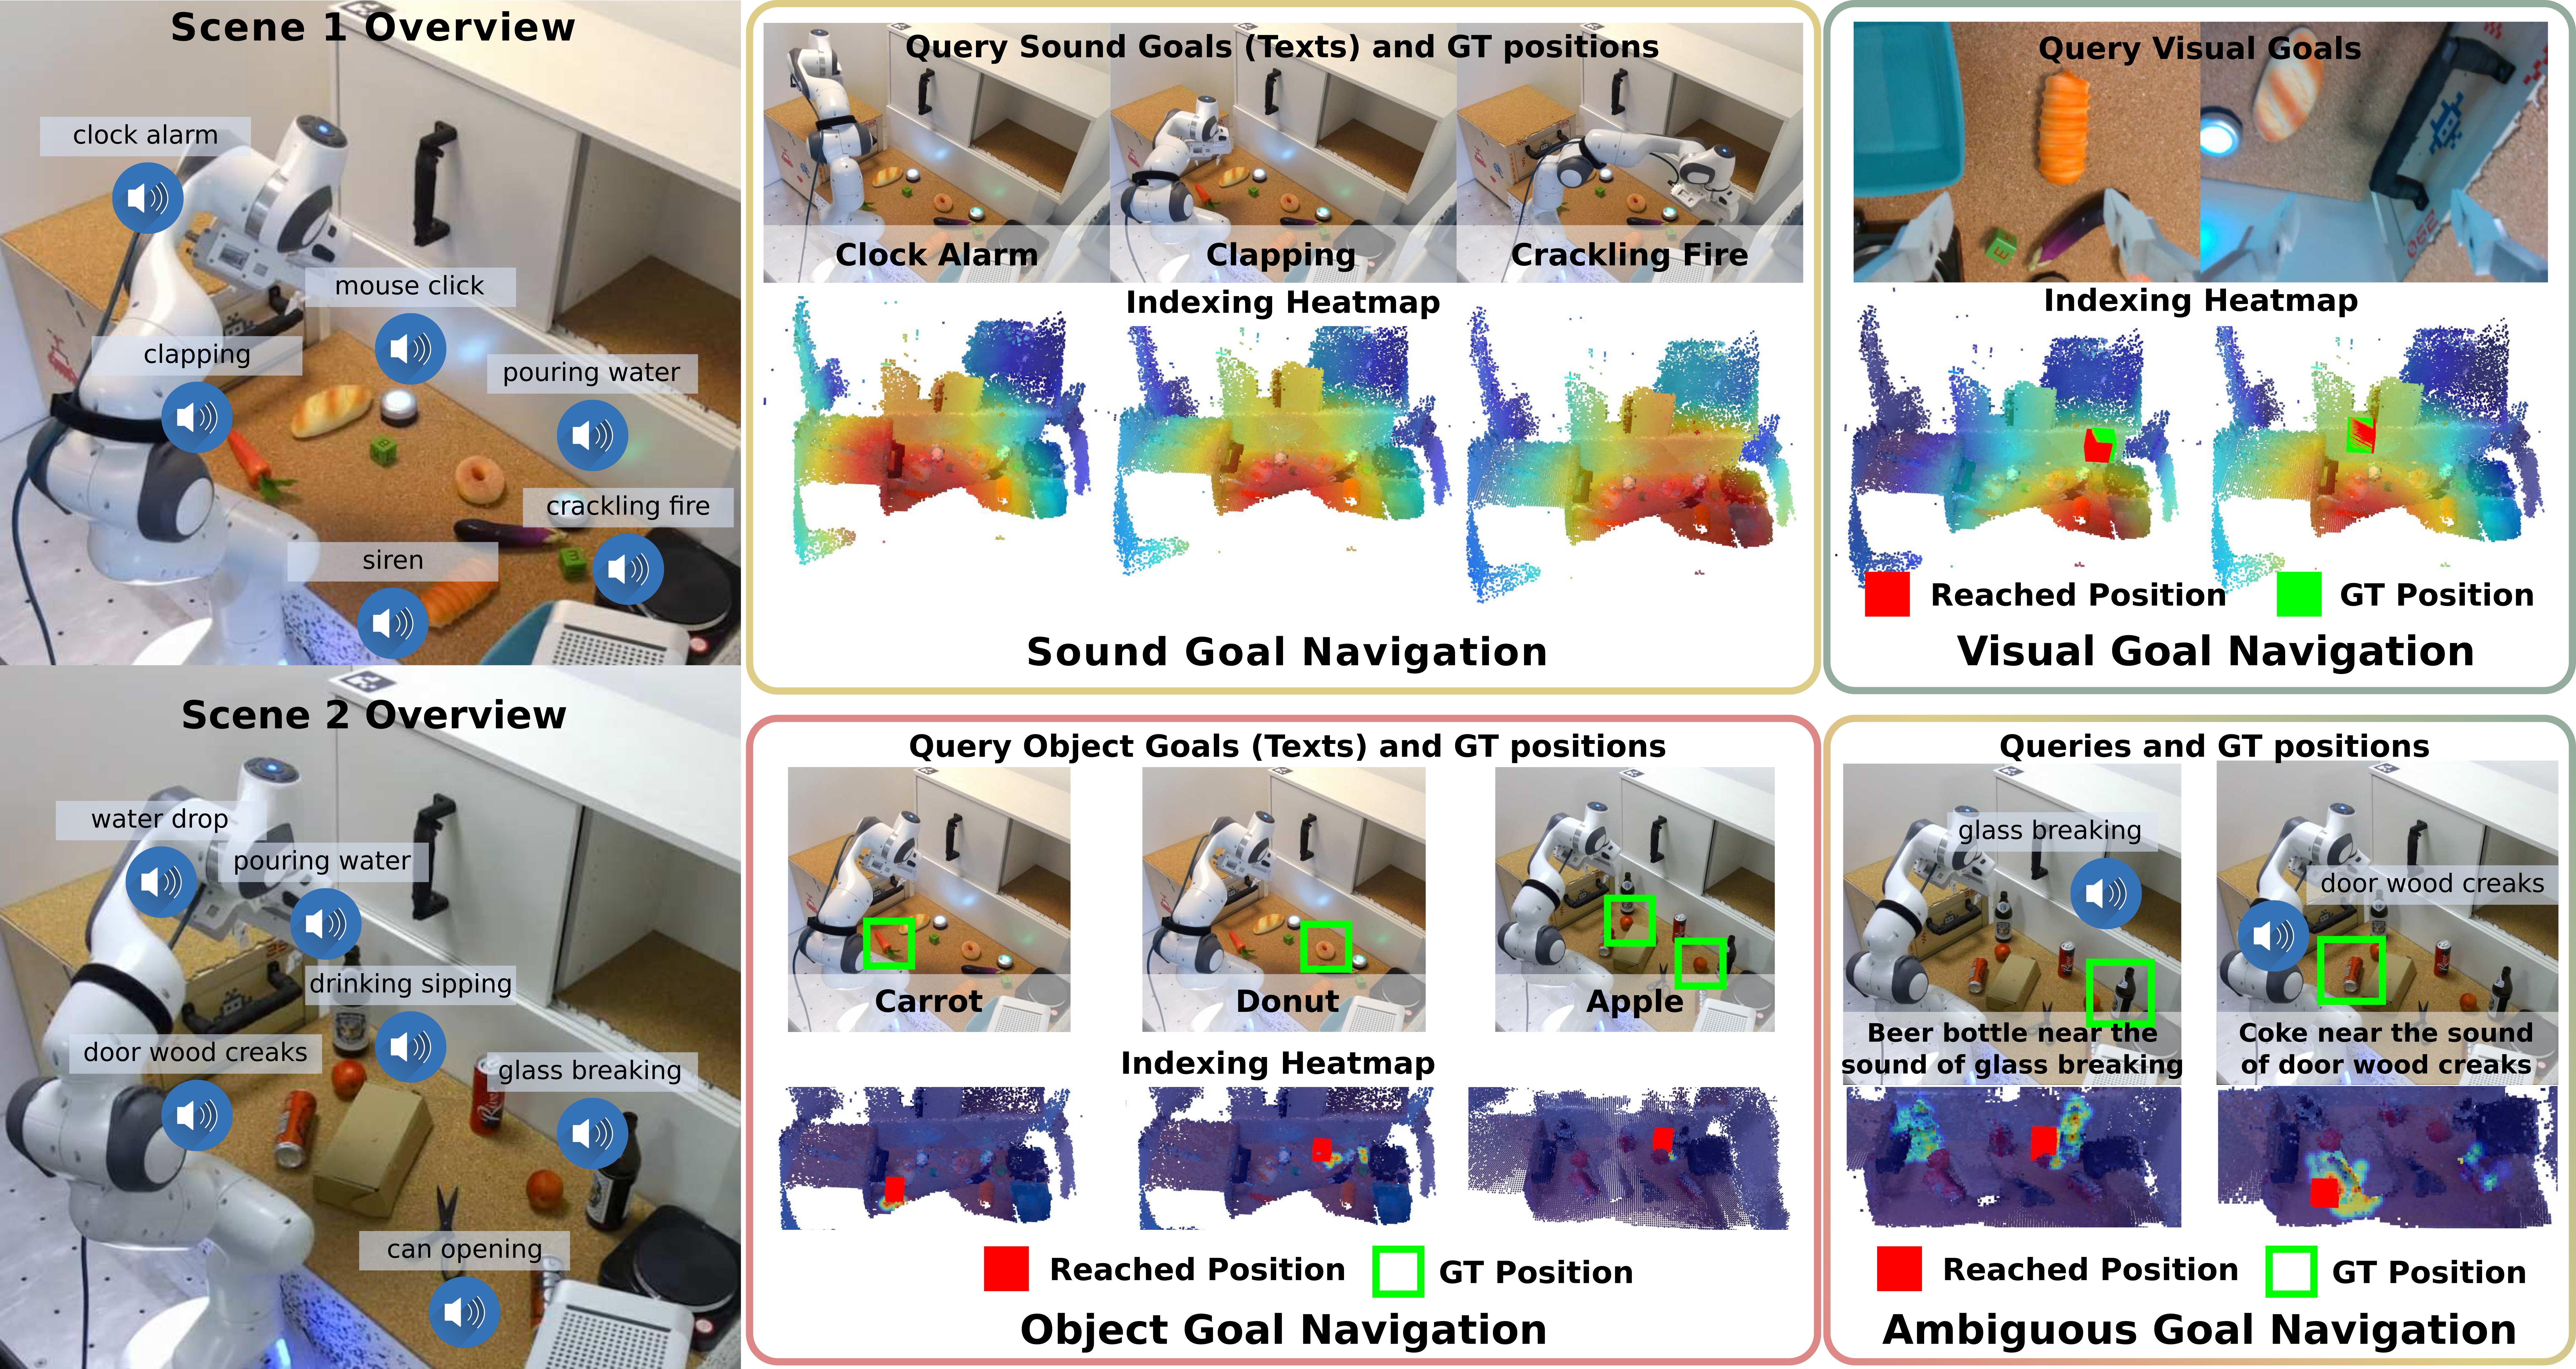
A fixed Panda arm maps two tabletop scenes using calibrated wrist RGB-D observations and inserted ESC-50 audio. CLAP and OVSeg provide audio and object features; the image-localization module is unchanged. Success means ending within 10 cm of the target, not grasping or manipulating the object.
The arm succeeds on all 20 image goals and 12 sound goals, nine of 13 object goals, and nine of ten ambiguous multimodal goals. The experiment demonstrates more precise goal reaching and map reuse across embodiments, with limited scenes and artificially associated sound locations.
5 Limitations and Discussions
The map remembers past observations and does not react reliably to new, disappearing, or moving sounds. Monaural audio is attached to the listener’s pose, so the representation lacks acoustic source localization. Moving objects during mapping leave geometric and semantic artifacts, and later object relocation makes the stored map stale; neither short-term nor long-term dynamics is handled by the current system.
Adding another modality would require its own feature storage and retrieval module, sharp and broad heatmap APIs, and prompting examples. Odor, temperature, magnetic fields, and other inputs are proposed extensions rather than demonstrated capabilities. Integrating transient sound response and map updates remains future work.
6 Conclusion
The framework shows how pretrained semantic features, explicit geometry, and prompted API composition can support spatial and multimodal navigation. Its strongest evidence is improved ambiguous-goal retrieval and reusable maps; its constraints are prior exploration, module errors, coarse audio localization, dynamic scenes, and declining complete-sequence success. The tabletop results add target reaching, while broader manipulation remains outside the demonstrated task.